As we all know, sometimes the right choice can avoid the waste of time, getting twice the result with half the effort. Especially for AI-200 study materials, only by finding the right ones can you reduce the pressure and help yourself to succeed. If you haven't found the right materials yet, please don't worry. Maybe our AI-200 Study Materials can give you a leg up which is our company's flagship product designed for the AI-200 exam.
| Section | Objectives |
|---|---|
| Topic 1: Implement Azure AI solutions | - Implement computer vision solutions - Implement natural language processing solutions - Implement knowledge mining with Azure AI Search - Implement generative AI solutions using Azure OpenAI |
| Topic 2: Implement and monitor AI workloads | - Deploy AI models and services - Monitor performance and troubleshoot issues |
| Topic 3: Plan and manage Azure AI solutions | - Select appropriate Azure AI services - Monitor and optimize AI solutions - Plan security and compliance requirements |
>> Valid AI-200 Cram Materials <<
Our loyal customers give our AI-200 exam materials strong support. So we are deeply moved by their persistence and trust. Your support and praises of our AI-200 study guide are our great motivation to move forward. You can find their real comments in the comments sections. There must be good suggestions for you on the AI-200 learning quiz as well. And we will try our best to satisfy our customers with better quatily and services.
NEW QUESTION # 38
A semantic search application queries Azure Database for PostgreSQL and stores document embeddings and metadata in a table with the following columns:
* embedding (pgvector)
* department
* created_at
The application must return the top five most similar documents for a given query embedding only from the finance department. You need to implement semantic retrieval with metadata filtering.
Which query components should you select? To answer, move the appropriate query components to the correct requirements. You may use each query component once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.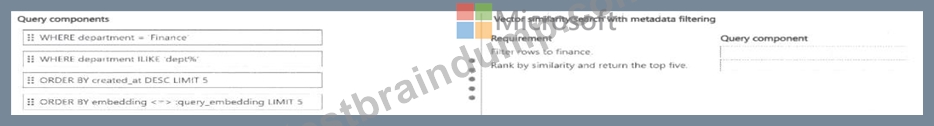
Answer:
Explanation: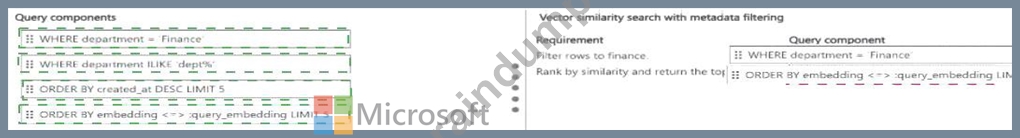
Explanation: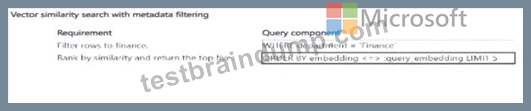
Verified answer: Filter: `WHERE department = ' finance ' `. Rank/top five: `ORDER BY embedding < = > query_embedding LIMIT 5`.
Detailed Explanation: The metadata predicate must restrict the candidate rows to the Finance department, so the `WHERE department = ' finance ' ` component supplies the required filter. The pgvector cosine-distance operator ` < = > ` orders rows by vector distance to the supplied query embedding, and `LIMIT 5` keeps only the five nearest matches. Ordering by creation date would rank recency rather than semantic similarity, and a wildcard department filter would not satisfy the Finance-only requirement.
Study Guide Alignment: AI data-management workloads: Cosmos DB, PostgreSQL, caching, vector storage, vector retrieval, consistency, and connection optimization.
Official Microsoft Learn References: AI-200 Study Guide | Vector similarity search with Azure PostgreSQL
NEW QUESTION # 39
Drag and Drop Question
You are investigating high latency in an AI search application that processes millions of requests daily. Telemetry is stored in Azure Monitor Logs.
You must create a KQL query that correlates information from the AppRequests table and the AppDependencies table. The query must meet the following requirements:
- Include only data from the last 24 hours.
- Filter for failed requests only.
- Calculate the average duration of dependencies, grouped by operation.
The query must be optimized for performance by minimizing the initial data scan.
You need to create the query.
Which five actions should you perform in sequence? To answer, move all actions from the list of actions to the answer area and arrange them in the correct order.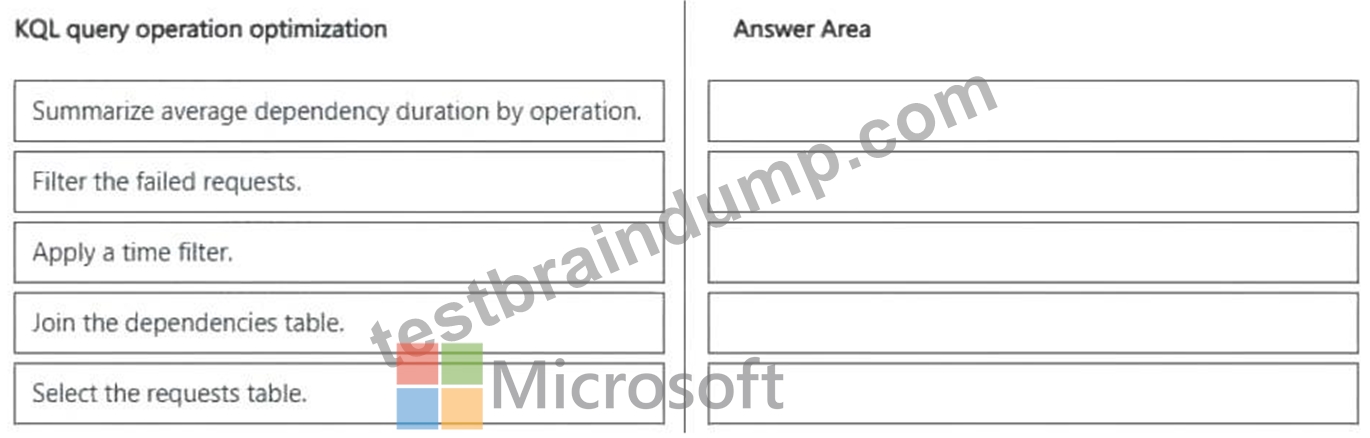
Answer:
Explanation: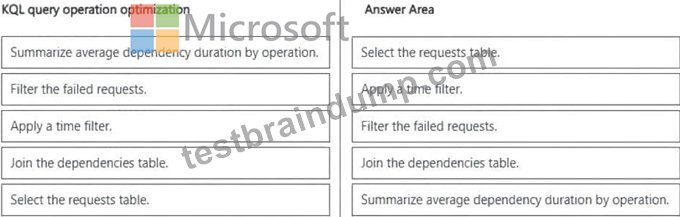
Explanation:
Step 1: Select the requests table
Starts the query stream with the primary base table.
Step 2: Apply a time filter
Such as (where timestamp >= ago(1d))
Restricts the dataset to the last 24 hours immediately to optimize performance by reducing the scan size.
Step 3: Filter the failed requests
where success == false or resultCode checks
Narrows down rows to only failures before performing resource-heavy operations.
Step 4: Join the dependencies table
(join AppDependencies): Correlates the filtered request subset with dependency data using common tracking identifiers.
Step 5: Summarize average dependency duration by operation (summarize avg(duration) by operation) Computes the final aggregated metrics grouped by the operation name.
Reference:
https://learn.microsoft.com/en-us/azure/azure-monitor/logs/get-started-queries
NEW QUESTION # 40
You are configuring an Azure-hosted AI application that uses Azure App Configuration to manage its runtime settings.
The application must provide the following functionality:
- Support percentage-based, targeted rollouts.
- Maximize token limits per request.
- Store a key that is retrieved securely at runtime.
- Reference a list of supported deployment regions.
You need to configure the App Configuration features for the app.
Which features should you configure? To answer, move the appropriate App Configuration features to the correct configuration items. You may use each App Configuration features once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.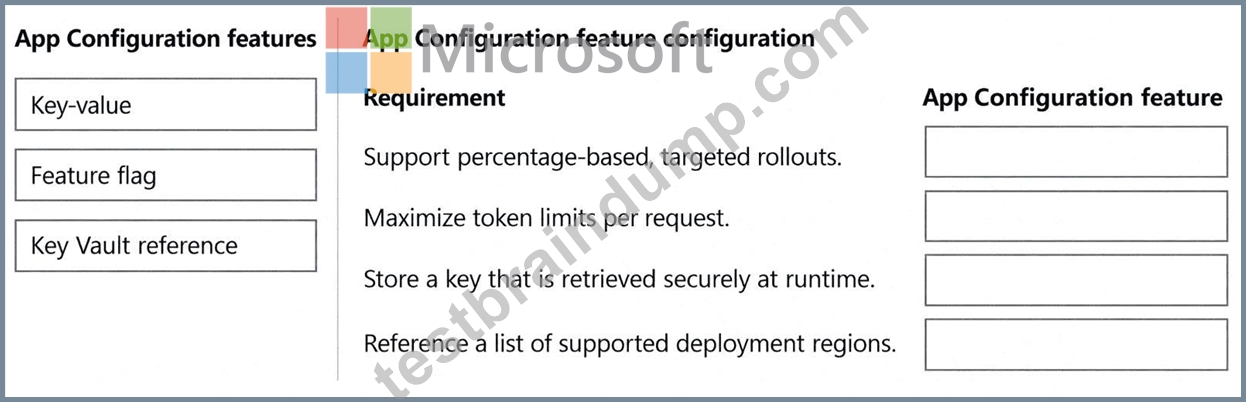
Answer:
Explanation: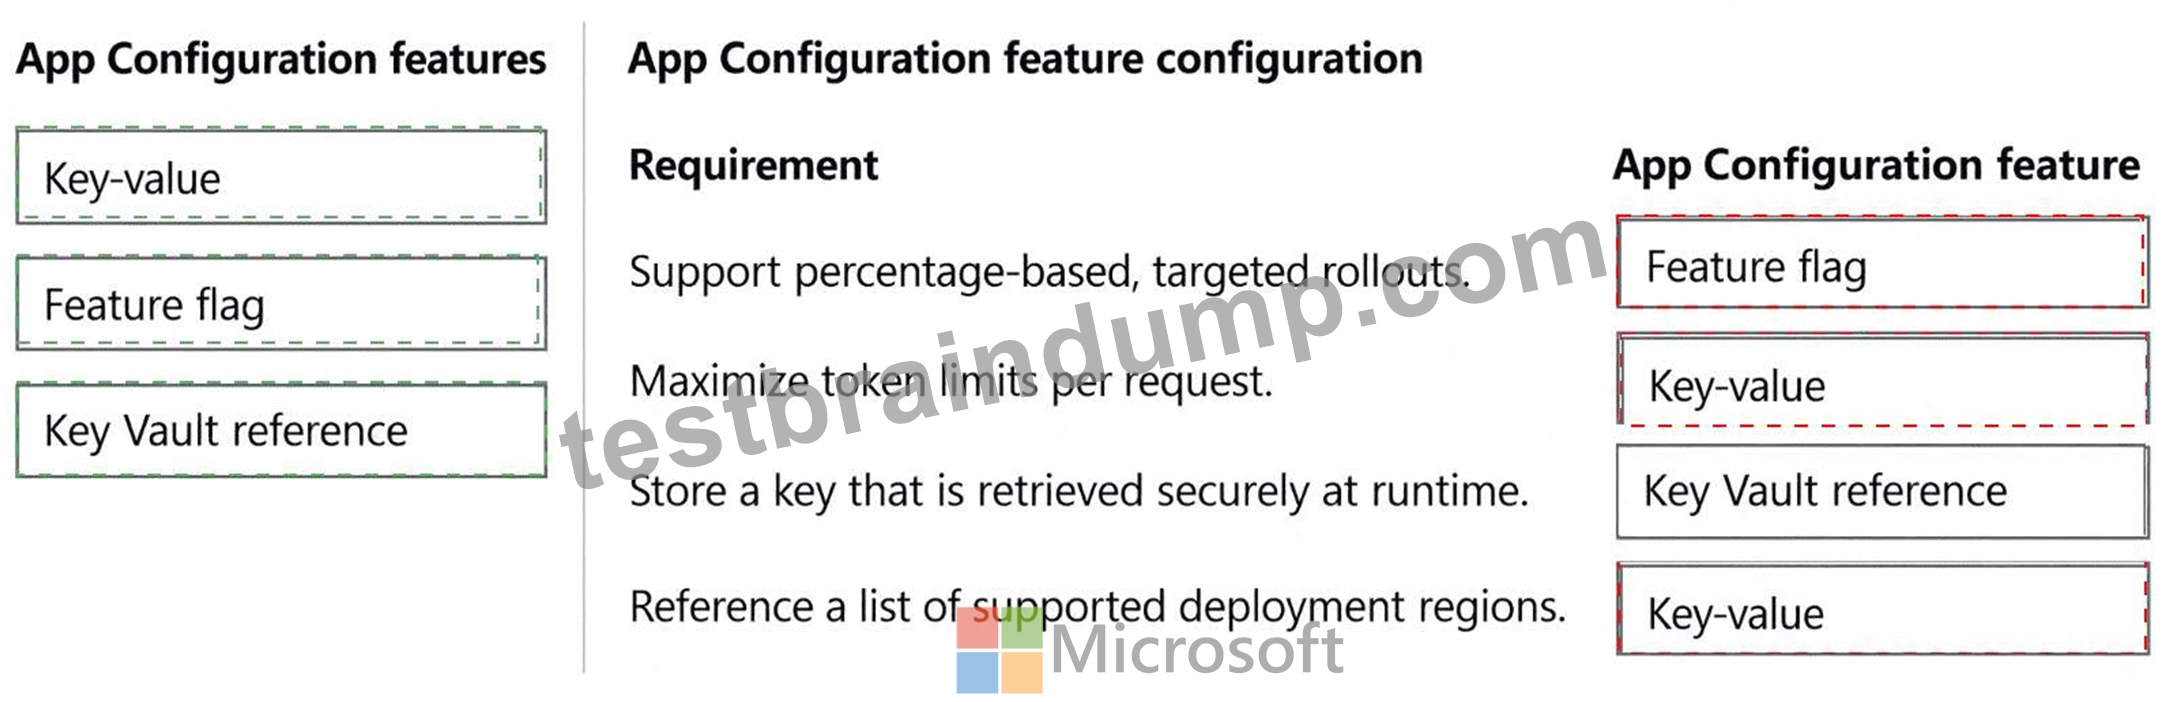
Explanation:
* Support percentage-based, targeted rollouts: Feature flag
* Maximize token limits per request: Key-value
* Store a key that is retrieved securely at runtime: Key Vault reference
* Reference a list of supported deployment regions: Key-value
Azure App Configuration provides three distinct mechanisms for these scenarios. A Feature flag is the correct choice for percentage-based and targeted rollouts. Feature Management supports conditional activation based on filters such as percentage allocation, users, groups, and other targeting criteria, making it appropriate for gradual deployment and controlled experimentation.
A Key-value is the correct mechanism for ordinary runtime configuration data such as a model token limit or a list of supported deployment regions. These values are application settings rather than secrets or feature- state controls. The application can retrieve and refresh them dynamically without redeployment. A token-limit setting such as MaxTokensPerRequest and a region list such as SupportedRegions fit naturally into App Configuration key-value entries.
For sensitive data, use a Key Vault reference . App Configuration stores only the reference to the Azure Key Vault secret rather than the secret value itself. At runtime, the application resolves the secret securely, typically by using a managed identity. This avoids embedding credentials or sensitive keys in configuration values.
Therefore, the correct mapping is Feature flag # Key-value # Key Vault reference # Key-value .
Study Guide references: Azure App Configuration # Feature Management; key-values; Key Vault references; dynamic application configuration.
NEW QUESTION # 41
You optimize an AI inference API that uses Redis caching.
You must reduce the risk of serving outdated data while minimizing cache management overhead. You need to implement the caching strategy that satisfies the requirements. What should you do?
Answer: D
Explanation:
Detailed Explanation: If the priority is to minimize stale results, source-driven invalidation is the direct control: when the underlying record changes, delete the corresponding cache entry so the next request repopulates it from current data. Sliding expiration can keep a frequently accessed stale item alive, disabling expiration is worse, and an allkeys-LRU policy evicts according to memory pressure rather than data freshness. Invalidation therefore best addresses correctness without requiring constant cache-wide maintenance.
Study Guide Alignment: AI data-management workloads: Cosmos DB, PostgreSQL, caching, vector storage, vector retrieval, consistency, and connection optimization.
Official Microsoft Learn References: AI-200 Study Guide | Azure Managed Redis documentation
NEW QUESTION # 42
You are provisioning and configuring a Service Bus processor for AI batch jobs.
The processor must connect to an existing queue, register handlers for message and error processing, and then begin receiving messages.
You need to provision and configure the Service Bus processor for message and error handling.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.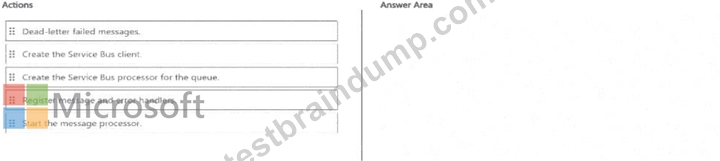
Answer:
Explanation: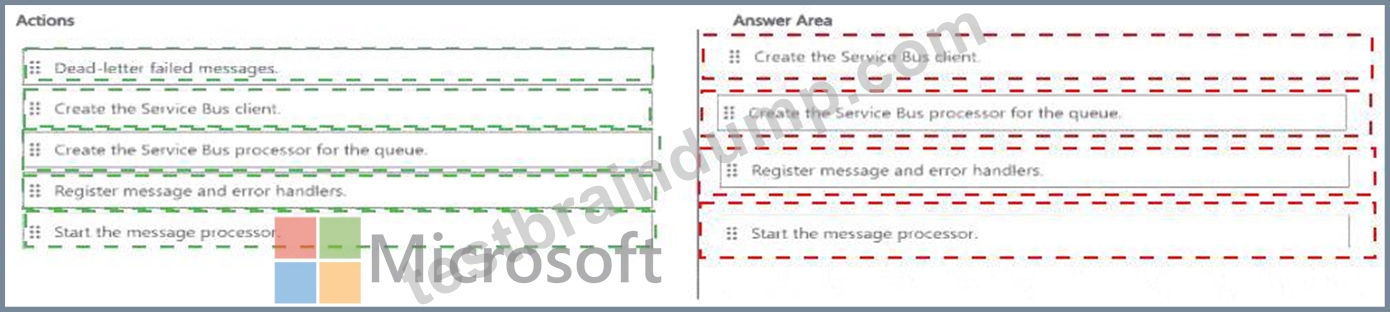
Explanation: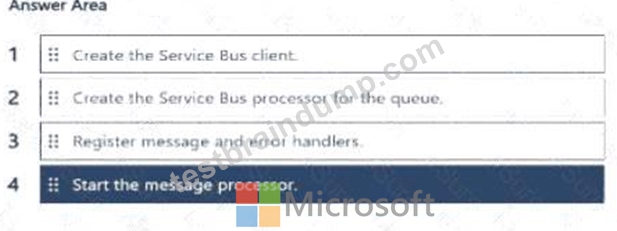
Verified Answer: 1) Create the Service Bus client; 2) create the queue processor/receiver; 3) register message and error handlers; 4) start the message processor.
Detailed Explanation: The processor depends on a namespace client/connection, so the client is created first.
Next, the queue-specific processor or receiver is created from that client. Message and error callbacks must be registered before processing starts so incoming messages and failures have defined handlers. Starting the processor is therefore the final step. Dead-lettering failed messages is an optional application settlement decision and is not a prerequisite for constructing and starting the processor.
Study Guide Alignment: Azure service integration: Service Bus, Event Grid, Azure Functions triggers
/bindings, and event-driven processing.
Official Microsoft Learn References: AI-200 Study Guide | Service Bus message transfers, locks, and settlement
NEW QUESTION # 43
......
TestBraindump deeply believe that our latest AI-200 exam torrent will be very useful for you to strength your ability, pass your AI-200 exam and get your certification. Our AI-200 study materials with high quality and high pass rate in order to help you get out of your harassment. If you do not have access to internet most of the time, if you need to go somewhere is in an offline state but you want to learn for your AI-200 Exam. Our website will help you solve your problem with the help of our excellent AI-200 exam questions.
Download AI-200 Free Dumps: https://www.testbraindump.com/AI-200-exam-prep.html