Die seit kurzem aktuellsten Databricks Databricks-Certified-Professional-Data-Engineer Prüfungsunterlagen, 100% Garantie für Ihen Erfolg in der Databricks Certified Professional Data Engineer Exam Prüfungen!

P.S. Kostenlose 2026 Databricks Databricks-Certified-Professional-Data-Engineer Prüfungsfragen sind auf Google Drive freigegeben von Zertpruefung verfügbar: https://drive.google.com/open?id=1eB0HQIqg_7xCYEGBMOFC0_en-dGrlk3R
Die Schulungen für die Vorbereitung der Databricks Databricks-Certified-Professional-Data-Engineer (Databricks Certified Professional Data Engineer Exam) Zertifizierungsprüfung beinhalten die Simulationsprüfungen sowie die Prüfungsfragen und Antworten zur Databricks Databricks-Certified-Professional-Data-Engineer Zertifizierungsprüfung. Im Internet haben Sie vielleicht auch einige ähnliche Ausbildungswebsites gesehen. Nach dem Vergleich würden Sie aber finden, dass die Schulungen zur Databricks Databricks-Certified-Professional-Data-Engineer Zertifizierungsprüfung von Zertpruefung eher zielgerichtet sind. Sie sind nicht nur von guter Qualität, sondern sind auch die umfassendeste.
Databricks Databricks-Certified-Professional-Data-Engineer Exam Overview:
| Certification Vendor: | Databricks |
|---|
| Exam Name: | Databricks Certified Professional Data Engineer Exam |
|---|
| Exam Number: | Databricks-Certified-Professional-Data-Engineer |
|---|
| Exam Format: | Multiple Choice, Multiple Select |
|---|
| Certificate Validity Period: | 2 years |
|---|
| Available Languages: | English |
|---|
| Exam Duration: | 90 minutes |
|---|
| Related Certifications: | Databricks Certified Data Analyst Associate
Databricks Certified Associate Developer |
|---|
| Passing Score: | 70% |
|---|
| Exam Price: | $200 USD |
|---|
| Real Exam Qty: | 60 |
|---|
| Sample Questions: | Databricks Databricks-Certified-Professional-Data-Engineer Sample Questions |
|---|
| Exam Way: | Online proctored exam (Pearson VUE) |
|---|
| Pre Condition: | Recommended: 6+ months of hands-on experience with Databricks and data engineering concepts; familiarity with Python or Scala and SQL is strongly recommended |
|---|
| Official Syllabus URL: | https://www.databricks.com/learn/certification/professional-data-engineer |
|---|
>> Databricks-Certified-Professional-Data-Engineer Examengine <<
Databricks-Certified-Professional-Data-Engineer Prüfungsfragen Prüfungsvorbereitungen, Databricks-Certified-Professional-Data-Engineer Fragen und Antworten, Databricks Certified Professional Data Engineer Exam
Als der professionelle Lieferant der IT-Zertifizierungsunterlagen, bieten wir Zertpruefung immer die besten Unterlagen für Kandidaten und helfen vielen Leuten, die Databricks Databricks-Certified-Professional-Data-Engineer Prüfung zu bestehen. Mit denen Databricks Databricks-Certified-Professional-Data-Engineer Dumps von Zertpruefung können Sie mehr selbstbewusster werden. Bei guter Nutzung der Dumps können Sie in sehr kürzer Zeit, die Databricks Databricks-Certified-Professional-Data-Engineer Prüfung zu bestehen. Finden Sie es unglaublich? Aber es ist wirklich. Wenn Sie diese Unterlagensfragen von Zertpruefung benutzen, können Sie das Wunder sehen.
Der Databricks Certified Professional Data Engineer ist eine Prüfung, die für Fachleute konzipiert wurde, die ihre Expertise im Aufbau und der Verwaltung von Big-Data-Pipelines mit Databricks demonstrieren möchten. Databricks ist eine einheitliche Analyseplattform, die eine gemeinsame Umgebung für die Verarbeitung von Daten im großen Maßstab bietet. Die Prüfung zum Databricks Certified Professional Data Engineer validiert die Fähigkeit des Kandidaten, große Datenverarbeitungslösungen mit Databricks zu entwerfen, zu entwickeln und bereitzustellen.
Die Databricks Certified Professional Data Engineer Prüfung besteht aus Multiple-Choice-Fragen und wird online durchgeführt. Die Prüfung soll die Kompetenz des Kandidaten in verschiedenen Bereichen wie Spark-Architektur, Spark-Programmierung, Datenverarbeitung, Datenanalyse und Datenmodellierung messen. Die Prüfung testet auch die Fähigkeit des Kandidaten, die Spark-Leistung zu optimieren und Spark-Anwendungen zu debuggen. Es wird empfohlen, dass Personen, die diese Prüfung ablegen möchten, mindestens zwei Jahre praktische Erfahrung in Big-Data-Technologien und Apache Spark haben.
Databricks Certified Professional Data Engineer Exam Databricks-Certified-Professional-Data-Engineer Prüfungsfragen mit Lösungen (Q89-Q94):
89. Frage
How are Delt tables stored?
- A. A Directory where parquet data files are stored, all of the meta data is stored in memory
- B. A Directory where parquet data files are stored, all of the metadata is stored in parquet files
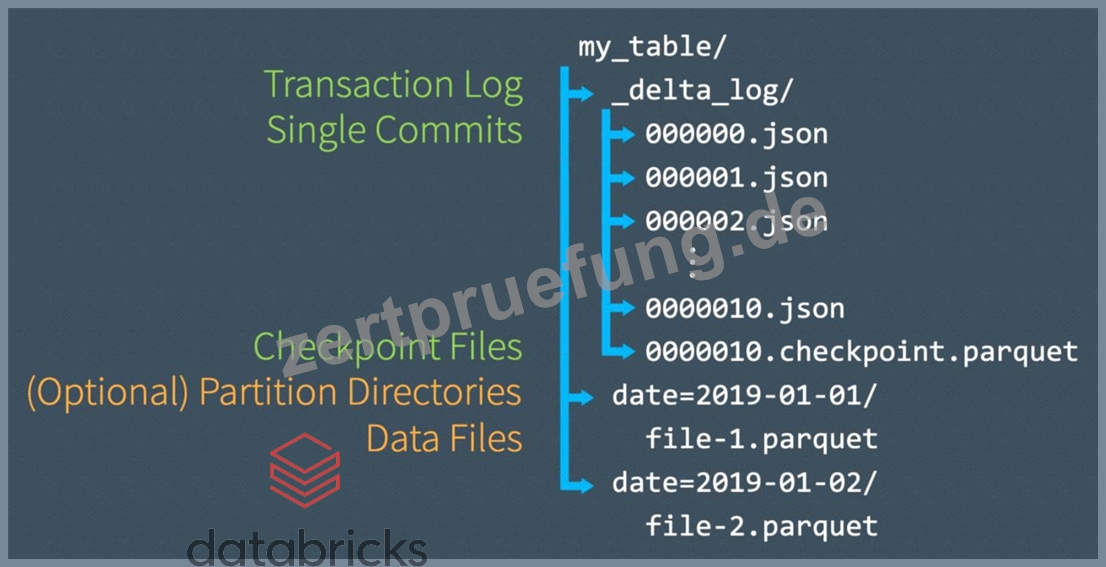
- C. A Directory where parquet data files are stored, a sub directory _delta_log where meta data, and the transaction log is stored as JSON files.
- D. A Directory where parquet data files are stored in Data plane, a sub directory _delta_log where meta data, history and log is stored in control pane.
- E. Data is stored in Data plane and Metadata and delta log are stored in control pane
Antwort: C
Begründung:
Explanation
The answer is A Directory where parquet data files are stored, a sub directory _delta_log where meta data, and the transaction log is stored as JSON files.
Timeline Description automatically generated
90. Frage
What are the advantages of the Hashing Features?
- A. Less pass through the training data
- B. Requires the less memory
- C. Easily reverse engineer vectors to determine which original feature mapped to a vector location
Antwort: A,B
Begründung:
Explanation
SGD-based classifiers avoid the need to predetermine vector size by simply picking a reasonable size and
shoehorning the training data into vectors of that size. This approach is known as feature hashing. The
shoehorning is done by picking one or more locations by using a hash of the name of the variable for
continuous variables or a hash of the variable name and the category name or word for categorical, text*like, or
word-like data.
This hashed feature approach has the distinct advantage of requiring less memory and one less pass through
the training data, but it can make it much harder to reverse engineer vectors to determine which original
feature mapped to a vector location. This is because multiple features may hash to the same location. With
large vectors or with multiple locations per feature, this isn't a problem for accuracy but it can make it hard to
understand what a classifier is doing.
An additional benefit of feature hashing is that the unknown and unbounded vocabularies typical of word-like
variables aren't a problem.
91. Frage
To reduce storage and compute costs, the data engineering team has been tasked with curating a series of aggregate tables leveraged by business intelligence dashboards, customer-facing applications, production machine learning models, and ad hoc analytical queries.
The data engineering team has been made aware of new requirements from a customer-facing application, which is the only downstream workload they manage entirely. As a result, an aggregate table used by numerous teams across the organization will need to have a number of fields renamed, and additional fields will also be added.
Which of the solutions addresses the situation while minimally interrupting other teams in the organization without increasing the number of tables that need to be managed?
- A. Configure a new table with all the requisite fields and new names and use this as the source for the customer-facing application; create a view that maintains the original data schema and table name by aliasing select fields from the new table.
- B. Add a table comment warning all users that the table schema and field names will be changing on a given date; overwrite the table in place to the specifications of the customer-facing application.
- C. Send all users notice that the schema for the table will be changing; include in the communication the logic necessary to revert the new table schema to match historic queries.
- D. Replace the current table definition with a logical view defined with the query logic currently writing the aggregate table; create a new table to power the customer-facing application.
- E. Create a new table with the required schema and new fields and use Delta Lake's deep clone functionality to sync up changes committed to one table to the corresponding table.
Antwort: A
Begründung:
This is the correct answer because it addresses the situation while minimally interrupting other teams in the organization without increasing the number of tables that need to be managed. The situation is that an aggregate table used by numerous teams across the organization will need to have a number of fields renamed, and additional fields will also be added, due to new requirements from a customer-facing application. By configuring a new table with all the requisite fields and new names and using this as the source for the customer-facing application, the data engineering team can meet the new requirements without affecting other teams that rely on the existing table schema and name. By creating a view that maintains the original data schema and table name by aliasing select fields from the new table, the data engineering team can also avoid duplicating data or creating additional tables that need to be managed. Verified Reference: [Databricks Certified Data Engineer Professional], under "Lakehouse" section; Databricks Documentation, under "CREATE VIEW" section.
92. Frage
Where are Interactive notebook results stored in Databricks product architecture?
- A. JDBC data source
- B. Databricks web application
- C. Data plane
- D. Data and Control plane
- E. Control plane
Antwort: D
Begründung:
Explanation
The answer is Data and Control plane,
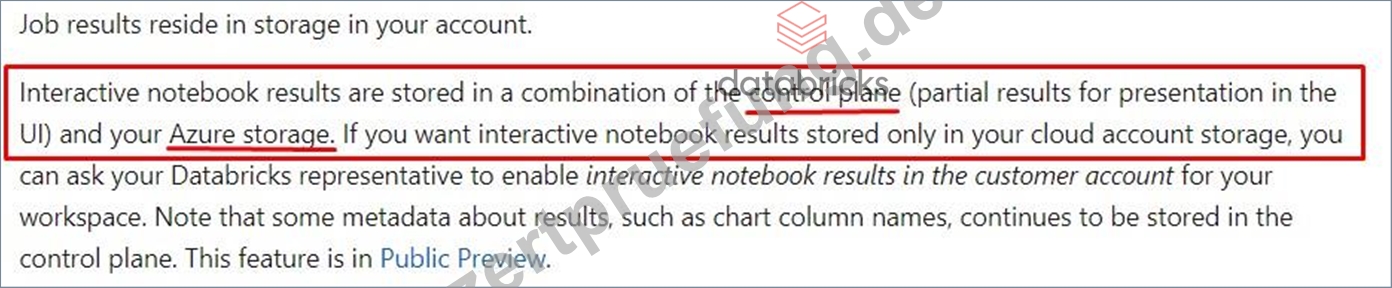
Only Job results are stored in Data Plane(your storage), Interactive notebook results are stored in a combination of the control plane (partial results for presentation in the UI) and customer storage.
https://docs.microsoft.com/en-us/azure/databricks/getting-started/overview#--high-level-architecture Snippet from the above documentation, Graphical user interface, application Description automatically generated
How to change this behavior?
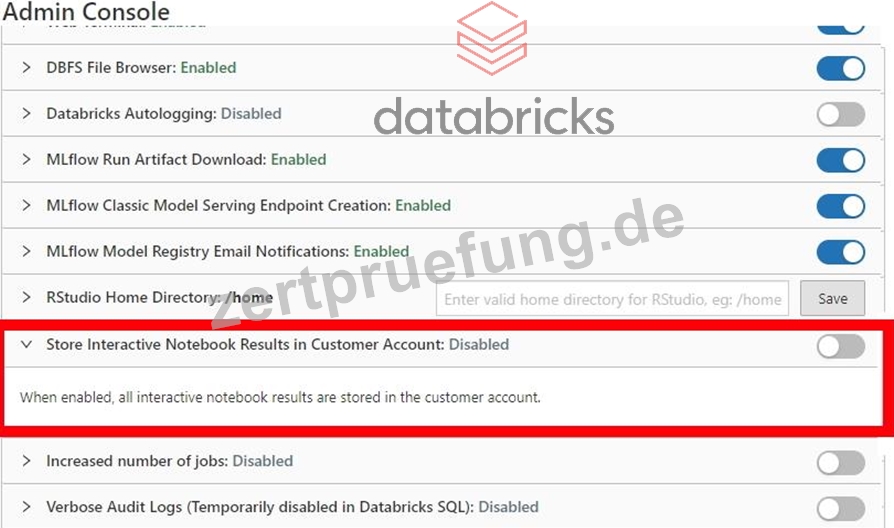
You can change this behavior using Workspace/Admin Console settings for that workspace, once enabled all of the interactive results are stored in the customer account(data plane) except the new notebook visualization feature Databricks has recently introduced, this still stores some metadata in the control pane irrespective of the below settings. please refer to the documentation for more details.
Graphical user interface, text, application, email Description automatically generated
Why is this important to know?
I recently worked on a project where we had to deal with sensitive information of customers and we had a security requirement that all of the data need to be stored in the data plane including notebook results.
93. Frage
An upstream system is emitting change data capture (CDC) logs that are being written to a cloud object storage directory. Each record in the log indicates the change type (insert, update, or delete) and the values for each field after the change. The source table has a primary key identified by the fieldpk_id.
For auditing purposes, the data governance team wishes to maintain a full record of all values that have ever been valid in the source system. For analytical purposes, only the most recent value for each record needs to be recorded. The Databricks job to ingest these records occurs once per hour, but each individual record may have changed multiple times over the course of an hour.
Which solution meets these requirements?
- A. Ingest all log information into a bronze table; use merge into to insert, update, or delete the most recent entry for each pk_id into a silver table to recreate the current table state.
- B. Use Delta Lake's change data feed to automatically process CDC data from an external system, propagating all changes to all dependent tables in the Lakehouse.
- C. Iterate through an ordered set of changes to the table, applying each in turn; rely on Delta Lake's versioning ability to create an audit log.
- D. Use merge into to insert, update, or delete the most recent entry for each pk_id into a bronze table, then propagate all changes throughout the system.
- E. Create a separate history table for each pk_id resolve the current state of the table by running a union all filtering the history tables for the most recent state.
Antwort: A
Begründung:
This is the correct answer because it meets the requirements of maintaining a full record of all values that have ever been valid in the source system and recreating the current table state with only the most recent value for each record. The code ingests all log information into a bronzetable, which preserves the raw CDC data as it is. Then, it uses merge into to perform an upsert operation on a silver table, which means it will insert new records or update or delete existing records based on the change type and the pk_id columns. This way, the silver table will always reflect the current state of the source table, while the bronze table will keep the history of all changes. Verified References: [Databricks Certified Data Engineer Professional], under
"Delta Lake" section; Databricks Documentation, under "Upsert into a table using merge" section.
94. Frage
......
Databricks-Certified-Professional-Data-Engineer Deutsch: https://www.zertpruefung.de/Databricks-Certified-Professional-Data-Engineer_exam.html
- Databricks-Certified-Professional-Data-Engineer Zertifizierungsantworten 🦍 Databricks-Certified-Professional-Data-Engineer Vorbereitung 🤦 Databricks-Certified-Professional-Data-Engineer Prüfung 📗 URL kopieren ➡ www.pass4test.de ️⬅️ Öffnen und suchen Sie ➥ Databricks-Certified-Professional-Data-Engineer 🡄 Kostenloser Download 🙇Databricks-Certified-Professional-Data-Engineer Originale Fragen
- Databricks-Certified-Professional-Data-Engineer aktueller Test, Test VCE-Dumps für Databricks Certified Professional Data Engineer Exam 😎 Suchen Sie auf ➠ www.itzert.com 🠰 nach ➡ Databricks-Certified-Professional-Data-Engineer ️⬅️ und erhalten Sie den kostenlosen Download mühelos 🐪Databricks-Certified-Professional-Data-Engineer PDF
- Databricks-Certified-Professional-Data-Engineer Zertifizierungsantworten 🎾 Databricks-Certified-Professional-Data-Engineer Musterprüfungsfragen 🕛 Databricks-Certified-Professional-Data-Engineer Fragenkatalog 🌄 Suchen Sie auf der Webseite ➽ www.pass4test.de 🢪 nach 【 Databricks-Certified-Professional-Data-Engineer 】 und laden Sie es kostenlos herunter 🧽Databricks-Certified-Professional-Data-Engineer Musterprüfungsfragen
- Databricks-Certified-Professional-Data-Engineer Vorbereitung 👣 Databricks-Certified-Professional-Data-Engineer PDF ⏬ Databricks-Certified-Professional-Data-Engineer Zertifizierungsantworten 🏋 Erhalten Sie den kostenlosen Download von ✔ Databricks-Certified-Professional-Data-Engineer ️✔️ mühelos über ➤ www.itzert.com ⮘ ✏Databricks-Certified-Professional-Data-Engineer Testengine
- Databricks-Certified-Professional-Data-Engineer Fragenkatalog 📤 Databricks-Certified-Professional-Data-Engineer Deutsch Prüfung 🥈 Databricks-Certified-Professional-Data-Engineer Zertifizierungsantworten 🌂 Suchen Sie jetzt auf ➠ www.zertpruefung.ch 🠰 nach ▛ Databricks-Certified-Professional-Data-Engineer ▟ und laden Sie es kostenlos herunter 🤑Databricks-Certified-Professional-Data-Engineer Deutsch Prüfungsfragen
- Databricks-Certified-Professional-Data-Engineer aktueller Test, Test VCE-Dumps für Databricks Certified Professional Data Engineer Exam 🚟 Suchen Sie jetzt auf ⮆ www.itzert.com ⮄ nach ( Databricks-Certified-Professional-Data-Engineer ) um den kostenlosen Download zu erhalten 💖Databricks-Certified-Professional-Data-Engineer Musterprüfungsfragen
- Databricks-Certified-Professional-Data-Engineer Prüfungsinformationen 🌊 Databricks-Certified-Professional-Data-Engineer Fragen Beantworten 😞 Databricks-Certified-Professional-Data-Engineer Testengine 📿 Öffnen Sie die Webseite ▷ www.zertpruefung.ch ◁ und suchen Sie nach kostenloser Download von 《 Databricks-Certified-Professional-Data-Engineer 》 🪐Databricks-Certified-Professional-Data-Engineer Fragenkatalog
- Databricks-Certified-Professional-Data-Engineer Fragenkatalog 🦨 Databricks-Certified-Professional-Data-Engineer Lerntipps 📐 Databricks-Certified-Professional-Data-Engineer Prüfung 👠 Öffnen Sie die Webseite { www.itzert.com } und suchen Sie nach kostenloser Download von ✔ Databricks-Certified-Professional-Data-Engineer ️✔️ 🐳Databricks-Certified-Professional-Data-Engineer Testengine
- Databricks-Certified-Professional-Data-Engineer Musterprüfungsfragen 🎰 Databricks-Certified-Professional-Data-Engineer Zertifizierungsantworten 🤡 Databricks-Certified-Professional-Data-Engineer Fragen Beantworten 😀 Suchen Sie auf ➠ www.itzert.com 🠰 nach kostenlosem Download von ▷ Databricks-Certified-Professional-Data-Engineer ◁ 👒Databricks-Certified-Professional-Data-Engineer Pruefungssimulationen
- Databricks-Certified-Professional-Data-Engineer Dumps und Test Überprüfungen sind die beste Wahl für Ihre Databricks Databricks-Certified-Professional-Data-Engineer Testvorbereitung 🧦 Öffnen Sie die Webseite ➽ www.itzert.com 🢪 und suchen Sie nach kostenloser Download von ➥ Databricks-Certified-Professional-Data-Engineer 🡄 🦜Databricks-Certified-Professional-Data-Engineer Testengine
- Databricks Databricks-Certified-Professional-Data-Engineer Quiz - Databricks-Certified-Professional-Data-Engineer Studienanleitung - Databricks-Certified-Professional-Data-Engineer Trainingsmaterialien 🤦 Suchen Sie auf der Webseite ✔ www.zertpruefung.de ️✔️ nach { Databricks-Certified-Professional-Data-Engineer } und laden Sie es kostenlos herunter 🚠Databricks-Certified-Professional-Data-Engineer Pruefungssimulationen
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
P.S. Kostenlose und neue Databricks-Certified-Professional-Data-Engineer Prüfungsfragen sind auf Google Drive freigegeben von Zertpruefung verfügbar: https://drive.google.com/open?id=1eB0HQIqg_7xCYEGBMOFC0_en-dGrlk3R