Amazon - Unparalleled MLA-C01 Test Pattern
BONUS!!! Download part of PDFVCE MLA-C01 dumps for free: https://drive.google.com/open?id=1FST8BtHLHY22DyZSGkTbXipwX3LslLUS
PDFVCE senior experts have developed exercises and answers about Amazon certification MLA-C01 exam with their knowledge and experience, which have 95% similarity with the real exam. I believe that you will be very confident of our products. If you choose to use PDFVCE's products, PDFVCE can help you 100% pass your first time to attend Amazon Certification MLA-C01 Exam. If you fail the exam, we will give a full refund to you.
| Topic | Details |
|---|
| Topic 1 | - Data Preparation for Machine Learning (ML): This section of the exam measures skills of Forensic Data Analysts and covers collecting, storing, and preparing data for machine learning. It focuses on understanding different data formats, ingestion methods, and AWS tools used to process and transform data. Candidates are expected to clean and engineer features, ensure data integrity, and address biases or compliance issues, which are crucial for preparing high-quality datasets in fraud analysis contexts.
|
| Topic 2 | - Deployment and Orchestration of ML Workflows: This section of the exam measures skills of Forensic Data Analysts and focuses on deploying machine learning models into production environments. It covers choosing the right infrastructure, managing containers, automating scaling, and orchestrating workflows through CI
- CD pipelines. Candidates must be able to build and script environments that support consistent deployment and efficient retraining cycles in real-world fraud detection systems.
|
| Topic 3 | - ML Model Development: This section of the exam measures skills of Fraud Examiners and covers choosing and training machine learning models to solve business problems such as fraud detection. It includes selecting algorithms, using built-in or custom models, tuning parameters, and evaluating performance with standard metrics. The domain emphasizes refining models to avoid overfitting and maintaining version control to support ongoing investigations and audit trails.
|
| Topic 4 | - ML Solution Monitoring, Maintenance, and Security: This section of the exam measures skills of Fraud Examiners and assesses the ability to monitor machine learning models, manage infrastructure costs, and apply security best practices. It includes setting up model performance tracking, detecting drift, and using AWS tools for logging and alerts. Candidates are also tested on configuring access controls, auditing environments, and maintaining compliance in sensitive data environments like financial fraud detection.
|
>> MLA-C01 Test Pattern <<
Top MLA-C01 Exam Dumps & Exam MLA-C01 Simulator Fee
PDFVCE provides exam dumps designed by experts to ensure that the candidates' success. This means that there is no need to worry about your results since everything MLA-C01 exam dumps are verified and updated by professionals. Amazon MLA-C01 Exam are made to be a model of actual exam dumps. Therefore, it can help users to feel in a real exam such as a real exam. This will improve your confidence and lessen stress to be able to pass the actual tests.
Amazon AWS Certified Machine Learning Engineer - Associate Sample Questions (Q152-Q157):
NEW QUESTION # 152
Hotspot Question
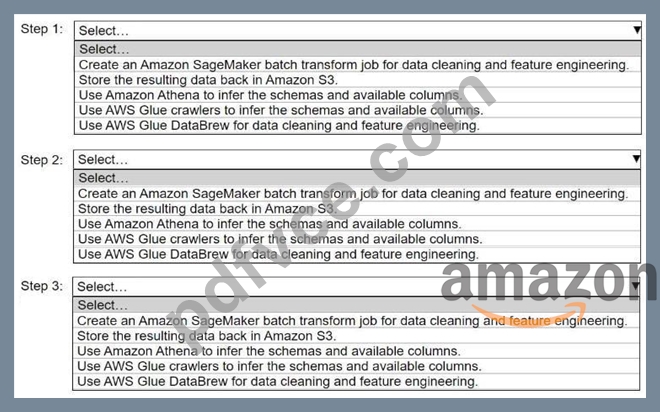
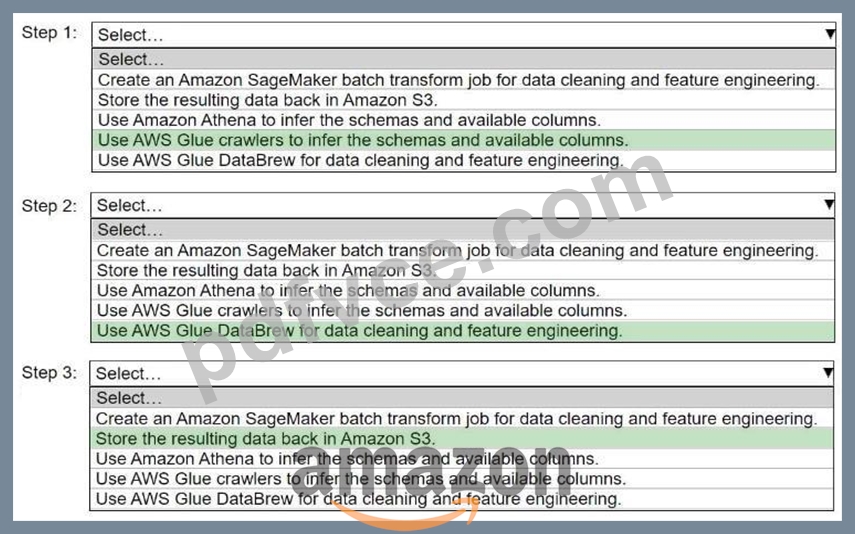
A company stores historical data in .csv files in Amazon S3. Only some of the rows and columns in the .csv files are populated. The columns are not labeled. An ML engineer needs to prepare and store the data so that the company can use the data to train ML models.
Select and order the correct steps from the following list to perform this task. Each step should be selected one time or not at all. (Select and order three.)
- Create an Amazon SageMaker batch transform job for data cleaning and
feature engineering.
- Store the resulting data back in Amazon S3.
- Use Amazon Athena to infer the schemas and available columns.
- Use AWS Glue crawlers to infer the schemas and available columns.
- Use AWS Glue DataBrew for data cleaning and feature engineering.
Answer:
Explanation:
NEW QUESTION # 153
An ML engineer normalized training data by using min-max normalization in AWS Glue DataBrew. The ML engineer must normalize production inference data in the same way before passing the data to the model.
Which solution will meet this requirement?
- A. Apply statistics from a well-known dataset to normalize the production samples.
- B. Calculate new min-max statistics from a batch of production samples and use them to normalize all production samples.
- C. Calculate new min-max statistics from each production sample and use them to normalize all production samples.
- D. Keep the min-max normalization statistics from the training set and use them to normalize the production samples.
Answer: D
Explanation:
AWS ML best practices state that data preprocessing applied during training must be applied identically during inference. For min-max normalization, this requires reusing the minimum and maximum values calculated from the training dataset.
If production data is normalized using different statistics, the feature distributions will differ from what the model learned, leading to degraded prediction accuracy. AWS documentation explicitly warns against recomputing normalization parameters on inference data.
Options A, C, and D introduce data leakage or inconsistent feature scaling. Option B ensures consistency between training and inference pipelines and preserves model integrity.
Therefore, Option B is the correct and AWS-aligned solution.
NEW QUESTION # 154
A company is interested in building a fraud detection model. Currently, the data scientist does not have a sufficient amount of information due to the low number of fraud cases.
Which method is MOST likely to detect the GREATEST number of valid fraud cases?
- A. Oversampling using bootstrapping
- B. Oversampling using SMOTE
- C. Class weight adjustment
- D. Undersampling
Answer: B
Explanation:
With datasets that are not fully populated, the Synthetic Minority Over-sampling Technique (SMOTE. adds new information by adding synthetic data points to the minority class. This technique would be the most effective in this scenario.
NEW QUESTION # 155
An ML engineer is using AWS CodeDeploy to deploy new container versions for inference on Amazon ECS.
The deployment must shift 10% of traffic initially, and the remaining 90% must shift within 10-15 minutes.
Which deployment configuration meets these requirements?
- A. CodeDeployDefault.ECSCanary10Percent15Minutes
- B. CodeDeployDefault.LambdaCanary10Percent15Minutes
- C. CodeDeployDefault.ECSAllAtOnce
- D. CodeDeployDefault.LambdaLinear10PercentEvery10Minutes
Answer: A
Explanation:
AWS CodeDeploy provides predefined deployment configurations for ECS that support canary and linear traffic shifting. The ECSCanary10Percent15Minutes configuration shifts 10% of traffic initially, waits 15 minutes, and then shifts the remaining traffic.
This matches the exact requirement: a 10% initial shift followed by the remaining 90% within the specified time window.
Lambda deployment configurations are not applicable to ECS. ECSAllAtOnce does not perform gradual traffic shifting.
AWS documentation explicitly defines ECSCanary10Percent15Minutes for controlled, low-risk ECS deployments.
Therefore, Option C is the correct and AWS-verified answer.
NEW QUESTION # 156
A healthcare analytics company wants to segment patients into groups that have similar risk factors to develop personalized treatment plans. The company has a dataset that includes patient health records, medication history, and lifestyle changes. The company must identify the appropriate algorithm to determine the number of groups by using hyperparameters.
Which solution will meet these requirements?
- A. Use the Amazon SageMaker k-means clustering algorithm. Set k to specify the number of clusters.
- B. Use the Amazon SageMaker AI Random Cut Forest (RCF) algorithm. Set a contamination hyperparameter for risk anomaly detection.
- C. Use the Amazon SageMaker AI DeepAR algorithm. Set epochs to determine the number of training iterations for risk groups.
- D. Use the Amazon SageMaker AI XGBoost algorithm. Set max_depth to control tree complexity for risk groups.
Answer: A
Explanation:
The problem described is a patient segmentation use case, which is a classic example of unsupervised learning. The objective is to group patients with similar characteristics without predefined labels. AWS documentation clearly states that Amazon SageMaker k-means is designed specifically for clustering and segmentation tasks.
The SageMaker k-means algorithm groups data points into clusters based on feature similarity and requires the user to define the number of clusters using the k hyperparameter. This directly satisfies the requirement to
"determine the number of groups by using hyperparameters." AWS recommends k-means for applications such as customer segmentation, risk grouping, and pattern discovery in healthcare data.
Option A (XGBoost) is a supervised learning algorithm used for classification and regression. The max_depth hyperparameter controls tree complexity, not the number of groups, making it unsuitable for this task.
Option C (DeepAR) is a time-series forecasting algorithm optimized for predicting future values, not clustering patients.
Option D (Random Cut Forest) is an anomaly detection algorithm. While useful for identifying outliers or unusual patient behavior, it does not perform clustering or group segmentation.
AWS SageMaker documentation explicitly identifies k-means as the correct choice when the goal is to partition data into a predefined number of clusters using a tunable hyperparameter.
Therefore, Option B is the correct and AWS-verified answer.
NEW QUESTION # 157
......
When they will be giving their final examination to get Amazon MLA-C01 certification they don't struggle much and do it easily. The results of the customizable MLA-C01 exam dumps can then be used to identify areas of strength and weakness and to create a personalized study plan that focuses on improving in the areas that need the most work. Taking MLA-C01 Practice Tests regularly could help individuals build their confidence, reduce test anxiety, and improve their overall performance.
Top MLA-C01 Exam Dumps: https://www.pdfvce.com/Amazon/MLA-C01-exam-pdf-dumps.html
- New MLA-C01 Test Voucher 🐗 MLA-C01 Latest Test Cost 💡 Associate MLA-C01 Level Exam 📞 Search for 【 MLA-C01 】 and obtain a free download on ▛ www.exam4labs.com ▟ ✔New MLA-C01 Test Voucher
- Valid MLA-C01 Test Pass4sure 🐬 MLA-C01 Latest Study Guide 🎶 MLA-C01 Exam Dumps.zip 😧 Download ✔ MLA-C01 ️✔️ for free by simply searching on { www.pdfvce.com } 📬Reliable MLA-C01 Test Preparation
- Amazon MLA-C01 Realistic Test Pattern Pass Guaranteed Quiz 🟠 Download ⇛ MLA-C01 ⇚ for free by simply searching on ➥ www.examdiscuss.com 🡄 🍲MLA-C01 Valid Exam Book
- MLA-C01 – 100% Free Test Pattern | Efficient Top AWS Certified Machine Learning Engineer - Associate Exam Dumps 🍓 Copy URL 「 www.pdfvce.com 」 open and search for 「 MLA-C01 」 to download for free 🙂MLA-C01 Latest Guide Files
- Latest MLA-C01 Dumps Book 🧀 Exam Dumps MLA-C01 Provider 🧲 MLA-C01 Valid Exam Book 🧙 Search for ⮆ MLA-C01 ⮄ and obtain a free download on ⏩ www.testkingpass.com ⏪ 🤜Exam MLA-C01 Format
- Latest MLA-C01 Exam Price 🦉 Exam MLA-C01 Format 🔴 MLA-C01 Sure Pass 🍚 Download ➤ MLA-C01 ⮘ for free by simply searching on ⮆ www.pdfvce.com ⮄ ‼Reliable MLA-C01 Test Preparation
- Amazon MLA-C01 Questions - Latest Preparation Material [2026] 📎 Easily obtain ⇛ MLA-C01 ⇚ for free download through ➠ www.torrentvce.com 🠰 🐶Reliable MLA-C01 Study Materials
- 2026 Amazon MLA-C01: AWS Certified Machine Learning Engineer - Associate Test Pattern 🪑 Search for 《 MLA-C01 》 and download it for free on ▷ www.pdfvce.com ◁ website 🦲MLA-C01 Latest Guide Files
- What are the Benefits of Preparing with www.pass4test.com Amazon MLA-C01 Exam Questions? 🥱 Open website ⮆ www.pass4test.com ⮄ and search for ( MLA-C01 ) for free download 🍡Exam MLA-C01 Format
- Learn Time Management Skill With Amazon MLA-C01 Practice Tests 🏈 Immediately open ⇛ www.pdfvce.com ⇚ and search for ➽ MLA-C01 🢪 to obtain a free download 🦁Reliable MLA-C01 Test Preparation
- MLA-C01 valid study material | MLA-C01 valid dumps 🚚 Open website “ www.validtorrent.com ” and search for ▛ MLA-C01 ▟ for free download 🦊MLA-C01 Latest Study Guide
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
P.S. Free & New MLA-C01 dumps are available on Google Drive shared by PDFVCE: https://drive.google.com/open?id=1FST8BtHLHY22DyZSGkTbXipwX3LslLUS