Certified-Data-Engineer-Professional시험대비덤프최신자료 & Certified-Data-Engineer-Professional인증시험덤프문제

Fast2test는 여러분이 Databricks인증Certified-Data-Engineer-Professional시험 패스와 추후사업에 모두 도움이 되겠습니다.Fast2test제품을 선택함으로 여러분은 시간과 돈을 절약하는 일석이조의 득을 얻을수 있습니다. Databricks인증Certified-Data-Engineer-Professional 인증시험패스는 아주 어렵습니다. 자기에 맞는 현명한 학습자료 선택은 성공의 지름길을 내딛는 첫발입니다. 퍼펙트한 자료만이Databricks인증Certified-Data-Engineer-Professional시험에서 성공할수 있습니다. Fast2test시험문제와 답이야 말로 퍼펙트한 자료이죠. Fast2test Databricks인증Certified-Data-Engineer-Professional인증시험자료는 100% 패스보장을 드립니다
Databricks Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Objectives |
|---|
| Topic 1: Debugging and Deploying | - Debugging and Troubleshooting
- 1. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- 2. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- 3. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- Deploying CI/CD
- 1. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
|
| Topic 2: Data Modeling | - Design and optimize data models
- 1. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 2. Design dimensional models for analytical workloads with efficient querying and aggregation
- 3. Design and implement scalable data models using Delta Lake to manage large datasets
- 4. Simplify data layout decisions and optimize query performance using liquid clustering
|
| Topic 3: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
- 2. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
|
| Topic 4: Data Sharing and Federation | - Share and federate data
- 1. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
- 2. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 3. Configure Lakehouse Federation with appropriate governance across supported source systems
|
| Topic 5: Developing Code for Data Processing using Python and SQL | - Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 2. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 3. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 4. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 5. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 6. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 7. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 8. Create pipeline components using control flow operators such as if/else and foreach
- Using Python and Tools for Development
- 1. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 2. Develop User-Defined Functions using Pandas/Python UDF
- 3. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
|
| Topic 6: Data Governance | - Govern enterprise data
- 1. Create and add descriptions and metadata to enterprise data to improve discoverability
- 2. Demonstrate understanding of the Unity Catalog permission inheritance model
|
| Topic 7: Ensuring Data Security and Compliance | - Ensuring Compliance
- 1. Implement compliant batch and streaming pipelines that detect and mask PII
- 2. Develop data purging solutions that comply with data retention policies
- Applying Data Security Mechanisms
- 1. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- 2. Use row filters and column masks to protect sensitive table data
- 3. Use ACLs to secure workspace objects and enforce the principle of least privilege
|
| Topic 8: Monitoring and Alerting | - Alerting
- 1. Use SQL Alerts to monitor data quality
- 2. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- Monitoring
- 1. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 2. Use Query Profile and Spark UI to monitor workloads
- 3. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 4. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
|
| Topic 9: Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
- 2. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
|
| Topic 10: Cost & Performance Optimization | - Optimize cost and performance
- 1. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 2. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 3. Apply Change Data Feed to address streaming table limitations and improve latency
- 4. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 5. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
|
>> Certified-Data-Engineer-Professional시험대비 덤프 최신자료 <<
최신 Certified-Data-Engineer-Professional시험대비 덤프 최신자료 인증시험 공부자료
Databricks Certified-Data-Engineer-Professional인증시험은 전문적인 관련지식을 테스트하는 인증시험입니다. Fast2test는 여러분이Databricks Certified-Data-Engineer-Professional인증시험을 통과할 수 잇도록 도와주는 사이트입니다. 많은 분들이 많은 시간과 돈을 들여 혹은 여러 학원 등을 다니면서Databricks Certified-Data-Engineer-Professional인증시험패스에 노력을 다합니다. 하지만 우리Fast2test에서는 20시간 좌우만 투자하면 무조건Databricks Certified-Data-Engineer-Professional시험을 패스할 수 있도록 도와드립니다.
최신 Databricks Certification Certified-Data-Engineer-Professional 무료샘플문제 (Q19-Q24):
질문 # 19
A data team's Structured Streaming job is configured to calculate running aggregates for item sales to update a downstream marketing dashboard. The marketing team has introduced a new field to track the number of times this promotion code is used for each item. A junior data engineer suggests updating the existing query as follows: Note that proposed changes are in bold.
Original query:
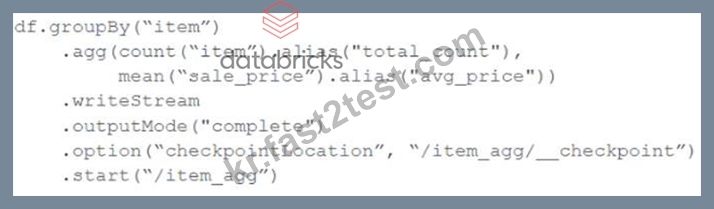
Proposed query:
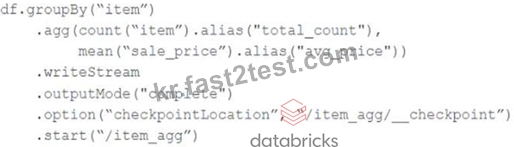
Which step must also be completed to put the proposed query into production?
- A. Register the data in the "/item_agg" directory to the Hive metastore
- B. Increase the shuffle partitions to account for additional aggregates
- C. Run REFRESH TABLE delta, /item_agg'
- D. Specify a new checkpointlocation
- E. Remove .option (mergeSchema', true') from the streaming write
정답:D
설명:
When introducing a new aggregation or a change in the logic of a Structured Streaming query, it is generally necessary to specify a new checkpoint location. This is because the checkpoint directory contains metadata about the offsets and the state of the aggregations of a streaming query. If the logic of the query changes, such as including a new aggregation field, the state information saved in the current checkpoint would not be compatible with the new logic, potentially leading to incorrect results or failures. Therefore, to accommodate the new field and ensure the streaming job has the correct starting point and state information for aggregations, a new checkpoint location should be specified.
질문 # 20
A data engineer is using Lakeflow Declarative Pipeline to propagate row deletions from a source bronze table (user_bronze) to a target silver table (user_silver). The engineer wants deletions in user_bronze to automatically delete corresponding rows in user_silver during pipeline execution.
Which configuration ensures deletions in the bronze table are propagated to the silver table?
- A. Use apply_changes without CDF and filter rows where _soft_deleted is true.
- B. Configure VACUUM on user_bronze to delete files, then rebuild user_silver from scratch.
- C. Enable CDF on user_silver, read its transaction log, and use MERGE to sync deletions.
- D. Enable Change Data Feed (CDF) on user_bronze, read its CDF stream, and use apply_changes() with apply_as_deletes=True for user_silver.
정답:D
설명:
According to Databricks documentation, Change Data Feed (CDF) allows pipelines to read incremental data changes, including inserts, updates, and deletes, from a Delta table. When deletions occur in the source table, reading the CDF stream ensures downstream consumers receive the deletion records. The Lakeflow Declarative Pipelines API provides the apply_changes() function (or auto-CDC pipelines) with the apply_as_deletes parameter to correctly apply those deletions to the target table. This enables automatic synchronization between bronze and silver layers. Options A and D either require manual handling or complete rebuilds, and C incorrectly applies CDF to the target rather than the source. Therefore, enabling CDF on the bronze table and using apply_as_deletes=True is the correct, Databricks-supported configuration.
질문 # 21
A Delta Lake table was created with the below query:
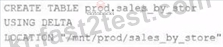
Realizing that the original query had a typographical error, the below code was executed:
ALTER TABLE prod.sales_by_stor RENAME TO prod.sales_by_store
Which result will occur after running the second command?
- A. The table reference in the metastore is updated and no data is changed.
- B. The table name change is recorded in the Delta transaction log.
- C. The table reference in the metastore is updated and all data files are moved.
- D. A new Delta transaction log Is created for the renamed table.
- E. All related files and metadata are dropped and recreated in a single ACID transaction.
정답:A
설명:
The query uses the CREATE TABLE USING DELTA syntax to create a Delta Lake table from an existing Parquet file stored in DBFS. The query also uses the LOCATION keyword to specify the path to the Parquet file as /mnt/finance_eda_bucket/tx_sales.parquet. By using the LOCATION keyword, the query creates an external table, which is a table that is stored outside of the default warehouse directory and whose metadata is not managed by Databricks. An external table can be created from an existing directory in a cloud storage system, such as DBFS or S3, that contains data files in a supported format, such as Parquet or CSV.
The result that will occur after running the second command is that the table reference in the metastore is updated and no data is changed. The metastore is a service that stores metadata about tables, such as their schema, location, properties, and partitions. The metastore allows users to access tables using SQL commands or Spark APIs without knowing their physical location or format. When renaming an external table using the ALTER TABLE RENAME TO command, only the table reference in the metastore is updated with the new name; no data files or directories are moved or changed in the storage system. The table will still point to the same location and use the same format as before. However, if renaming a managed table, which is a table whose metadata and data are both managed by Databricks, both the table reference in the metastore and the data files in the default warehouse directory are moved and renamed accordingly.
질문 # 22
A data engineer is creating a daily reporting job. There are two reporting notebooks--one for weekdays and one for weekends. An "if/else condition" task is configured as
{{job.start_time.is_weekday}} == true to route the job to either the weekday or weekend notebook tasks. The same job would be used across multiple time zones. Which action should a senior data engineer take upon reviewing the job to merge or reject the pull request?
- A. Reject, as they should use {{job.trigger_time.is_weekday}} instead.
- B. Merge, as the job configuration looks good.
- C. Reject, as the {{job.start_time.is_weekday}} is for the UTC timezone.
- D. Reject, as the {{job.start_time.is_weekday}} is not a valid value reference.
정답:C
설명:
Databricks parameter templates like {{job.start_time.is_weekday}} evaluate in UTC time by default, not in local workspace or regional time zones. Therefore, when jobs are configured to run across different time zones, relying on is_weekday using UTC may cause scheduling and task routing mismatches (for example, triggering the weekday notebook in one region while it's still the weekend locally).
Databricks recommends adjusting conditional logic or pipeline parameters explicitly to handle time zone conversions if business requirements depend on local times. Because the engineer's configuration does not account for this behavior, a senior data engineer should reject the pull request and suggest time-zone-aware logic before merging.
질문 # 23
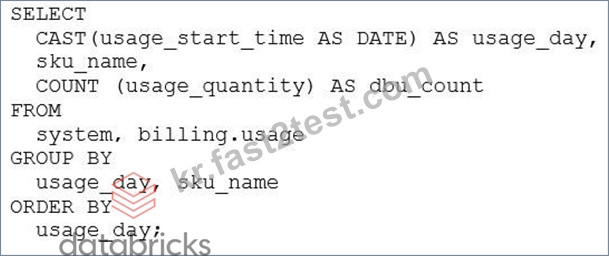
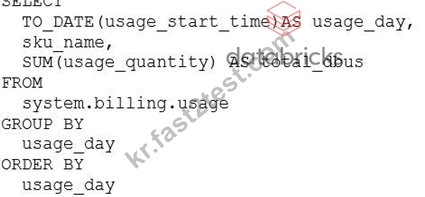
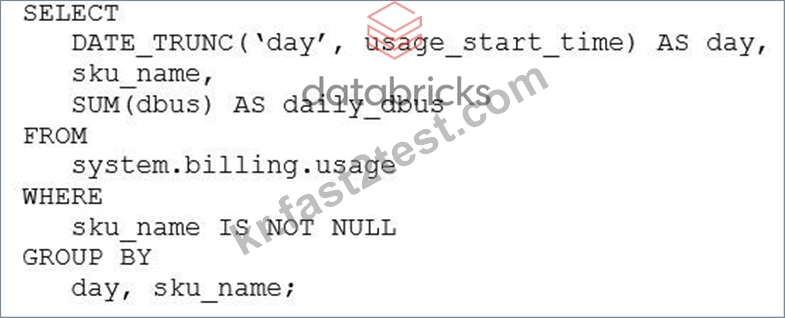
A platform engineer needs to report the resource consumption, categorized by SKU tier, across all workspaces. The engineer decides to use the system.billing.usage system table to create a query. Which SQL query will accurately return the daily usage by product?
정답:A
설명:
This query correctly aggregates usage at a daily granularity by truncating the usage start timestamp to the day and summing the usage quantity, which represents DBUs. Grouping by both the derived daily value and the SKU name ensures usage is accurately categorized by product tier across all workspaces.
질문 # 24
......
Databricks인증Certified-Data-Engineer-Professional시험을 패스하여 자격증을 취득한다면 여러분의 미래에 많은 도움이 될 것입니다.Databricks인증Certified-Data-Engineer-Professional시험자격증은 it업계에서도 아주 인지도가 높고 또한 알아주는 시험이며 자격증 하나로도 취직은 문제없다고 볼만큼 가치가 있는 자격증이죠.Databricks인증Certified-Data-Engineer-Professional시험은 여러분이 it지식테스트시험입니다.
Certified-Data-Engineer-Professional인증시험 덤프문제: https://kr.fast2test.com/Certified-Data-Engineer-Professional-premium-file.html
- Certified-Data-Engineer-Professional시험대비 덤프 최신자료 100% 유효한 덤프공부자료 🔕 ⮆ www.dumptop.com ⮄의 무료 다운로드{ Certified-Data-Engineer-Professional }페이지가 지금 열립니다Certified-Data-Engineer-Professional인증덤프공부
- 시험대비 Certified-Data-Engineer-Professional시험대비 덤프 최신자료 최신버전 덤프샘플문제 다운로드 🟨 { www.itdumpskr.com }의 무료 다운로드▛ Certified-Data-Engineer-Professional ▟페이지가 지금 열립니다Certified-Data-Engineer-Professional최신덤프
- 높은 적중율을 자랑하는 Certified-Data-Engineer-Professional시험대비 덤프 최신자료 덤프로 Databricks Certified Data Engineer Professional 시험도전 🍂 [ kr.fast2test.com ]에서 검색만 하면▷ Certified-Data-Engineer-Professional ◁를 무료로 다운로드할 수 있습니다Certified-Data-Engineer-Professional퍼펙트 최신 덤프공부자료
- Certified-Data-Engineer-Professional인증덤프공부 🛵 Certified-Data-Engineer-Professional퍼펙트 공부 ⬛ Certified-Data-Engineer-Professional자격증공부 🐟 ( www.itdumpskr.com )을(를) 열고⮆ Certified-Data-Engineer-Professional ⮄를 입력하고 무료 다운로드를 받으십시오Certified-Data-Engineer-Professional시험패스 인증덤프
- Certified-Data-Engineer-Professional시험대비 덤프 최신자료 시험준비에 가장 좋은 덤프로 시험에 도전 📌 검색만 하면✔ www.itdumpskr.com ️✔️에서「 Certified-Data-Engineer-Professional 」무료 다운로드Certified-Data-Engineer-Professional높은 통과율 덤프문제
- Certified-Data-Engineer-Professional적중율 높은 시험덤프자료 💚 Certified-Data-Engineer-Professional퍼펙트 덤프공부자료 🖍 Certified-Data-Engineer-Professional높은 통과율 덤프샘플문제 🕝 [ www.itdumpskr.com ]에서⇛ Certified-Data-Engineer-Professional ⇚를 검색하고 무료로 다운로드하세요Certified-Data-Engineer-Professional퍼펙트 최신 덤프공부자료
- Certified-Data-Engineer-Professional시험대비 덤프 최신자료 시험준비에 가장 좋은 덤프로 시험에 도전 🦅 무료 다운로드를 위해▷ Certified-Data-Engineer-Professional ◁를 검색하려면「 www.koreadumps.com 」을(를) 입력하십시오Certified-Data-Engineer-Professional시험패스 가능 공부자료
- Certified-Data-Engineer-Professional덤프문제 🌘 Certified-Data-Engineer-Professional최신덤프 📼 Certified-Data-Engineer-Professional인증덤프공부 🎉 ⮆ www.itdumpskr.com ⮄웹사이트에서{ Certified-Data-Engineer-Professional }를 열고 검색하여 무료 다운로드Certified-Data-Engineer-Professional시험패스 가능 공부자료
- Certified-Data-Engineer-Professional완벽한 덤프자료 🚏 Certified-Data-Engineer-Professional유효한 최신덤프공부 🪐 Certified-Data-Engineer-Professional인증덤프공부 🦆 무료로 다운로드하려면➥ www.exampassdump.com 🡄로 이동하여➤ Certified-Data-Engineer-Professional ⮘를 검색하십시오Certified-Data-Engineer-Professional적중율 높은 시험덤프자료
- Certified-Data-Engineer-Professional퍼펙트 덤프공부자료 🤐 Certified-Data-Engineer-Professional자격증공부 🥫 Certified-Data-Engineer-Professional유효한 최신덤프공부 ⛅ { www.itdumpskr.com }웹사이트에서[ Certified-Data-Engineer-Professional ]를 열고 검색하여 무료 다운로드Certified-Data-Engineer-Professional최신버전 시험덤프
- Certified-Data-Engineer-Professional높은 통과율 덤프샘플문제 🍐 Certified-Data-Engineer-Professional인증시험자료 🚒 Certified-Data-Engineer-Professional최신덤프 😅 【 www.pass4test.net 】의 무료 다운로드▷ Certified-Data-Engineer-Professional ◁페이지가 지금 열립니다Certified-Data-Engineer-Professional적중율 높은 시험덤프자료
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes