BTW, DOWNLOAD part of Pass4guide DP-100 dumps from Cloud Storage: https://drive.google.com/open?id=1qI1A9XlhKyTezdy1voLcg45GxpmGPwyi
Each format has a pool of Designing and Implementing a Data Science Solution on Azure (DP-100) actual questions which have been compiled under the guidance of thousands of professionals worldwide. Questions in this product will appear in the Microsoft DP-100 final test. Hence, memorizing them will help you get prepared for the DP-100 examination in a short time. The product of Pass4guide comes in PDF, desktop practice exam software, and DP-100 web-based practice test. To give you a complete understanding of these formats, we have discussed their features below.
Candidates with permission to take DP-100 Exam are those aspiring to become Azure data scientists and have formed huge knowledge in both data science and machine learning workloads based on Azure.
>> DP-100 Examcollection Vce <<
Have you been many years at your position but haven't got a promotion? Or are you a new comer in your company and eager to make yourself outstanding? Our DP-100 exam materials can help you. After a few days' studying and practicing with our DP-100 products you will easily pass the examination. God helps those who help themselves. If you choose our DP-100 Study Materials, you will find God just by your side. The only thing you have to do is just to make your choice and study. Isn't it very easy? So know more about our DP-100 study guide right now!
The DP-100 exam includes various topics related to data science, such as data exploration, data preparation, data modeling, machine learning, and data visualization. DP-100 exam also tests the candidate's knowledge of Azure services that are used for data solutions, such as Azure Machine Learning, Azure Data Factory, Azure Stream Analytics, and Azure Databricks. DP-100 Exam Format includes multiple-choice questions, case studies, and practical exercises.
NEW QUESTION # 110
You create a training pipeline by using the Azure Machine Learning designer. You need to load data into a machine learning pipeline by using the Import Data component. Which two data sources could you use? Each correct answer presents a complete solution.
NOTE: Each correct selection is worth one point
Answer: D,E
NEW QUESTION # 111
You manage an Azure Machine Learning workspace by using the Python SDK v2.
You must create a compute cluster in the workspace. The compute cluster must run workloads and properly handle interruptions. You start by calculating the maximum amount of compute resources required by the workloads and size the cluster to match the calculations.
The cluster definition includes the following properties and values:
* name="mlcluster1''
* size="STANDARD.DS3.v2"
* min_instances=1
* maxjnstances=4
* tier="dedicated"
The cost of the compute resources must be minimized when a workload is active Of idle. Cluster property changes must not affect the maximum amount of compute resources available to the workloads run on the cluster.
You need to modify the cluster properties to minimize the cost of compute resources.
Which properties should you modify? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation: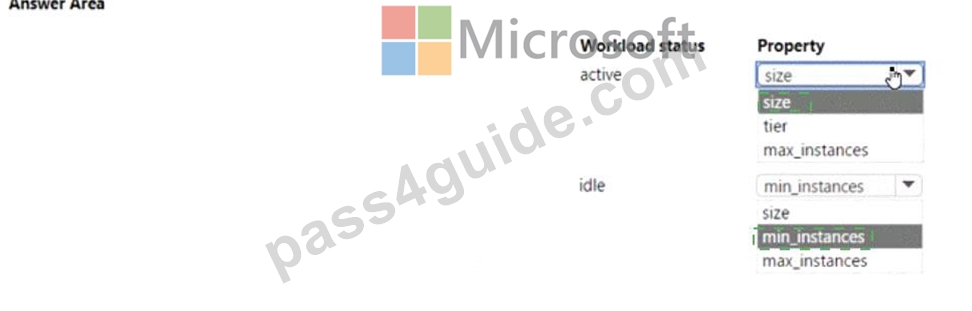
Explanation: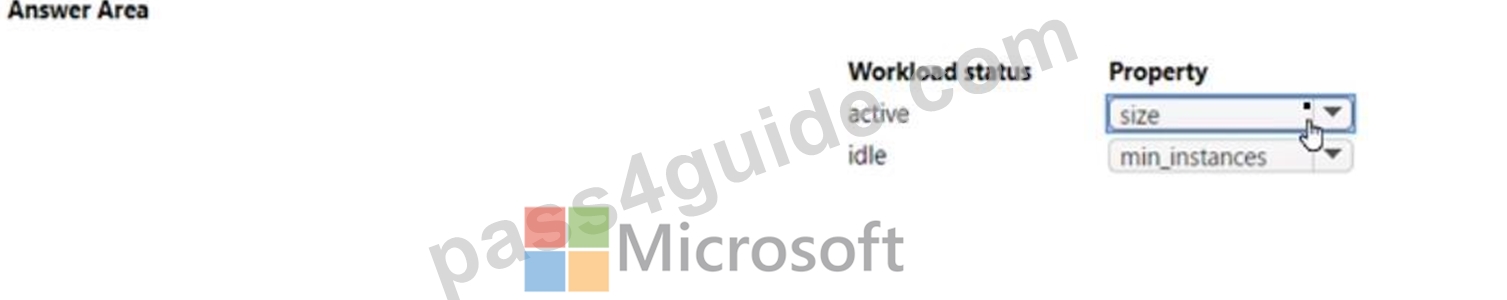
NEW QUESTION # 112
You need to select an environment that will meet the business and data requirements.
Which environment should you use?
Answer: C
NEW QUESTION # 113
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a Python script named train.py in a local folder named scripts. The script trains a regression model by using scikit-learn. The script includes code to load a training data file which is also located in the scripts folder.
You must run the script as an Azure ML experiment on a compute cluster named aml-compute.
You need to configure the run to ensure that the environment includes the required packages for model training. You have instantiated a variable named aml-compute that references the target compute cluster.
Solution: Run the following code: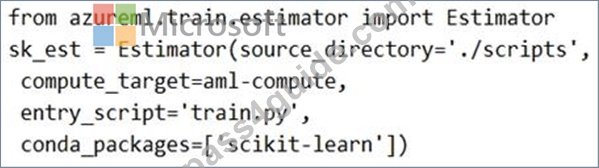
Does the solution meet the goal?
Answer: A
Explanation:
The scikit-learn estimator provides a simple way of launching a scikit-learn training job on a compute target. It is implemented through the SKLearn class, which can be used to support single-node CPU training.
Example:
from azureml.train.sklearn import SKLearn
}
estimator = SKLearn(source_directory=project_folder,
compute_target=compute_target,
entry_script='train_iris.py'
)
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-train-scikit-learn
NEW QUESTION # 114
Drag and Drop Question
You are producing a multiple linear regression model in Azure Machine Learning Studio.
Several independent variables are highly correlated.
You need to select appropriate methods for conducting effective feature engineering on all the data.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.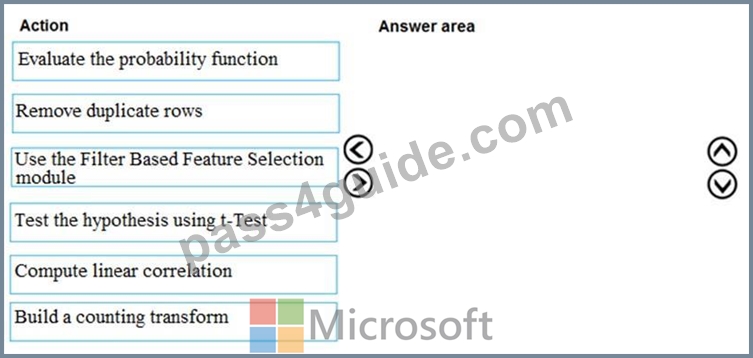
Answer:
Explanation: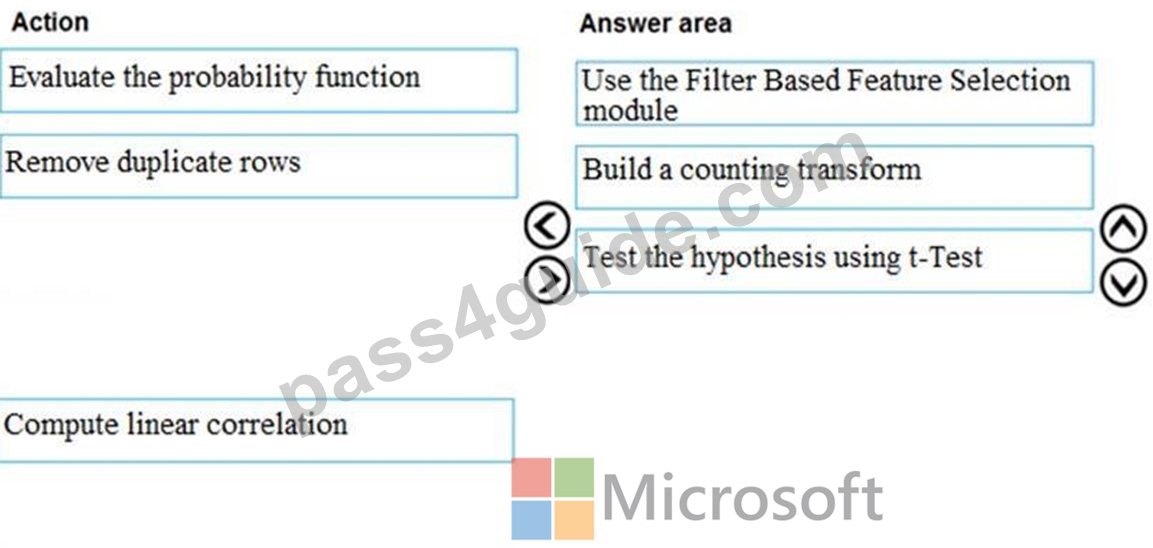
Explanation:
Step 1: Use the Filter Based Feature Selection module
Filter Based Feature Selection identifies the features in a dataset with the greatest predictive power. The module outputs a dataset that contains the best feature columns, as ranked by predictive power. It also outputs the names of the features and their scores from the selected metric.
Step 2: Build a counting transform
A counting transform creates a transformation that turns count tables into features, so that you can apply the transformation to multiple datasets.
Step 3: Test the hypothesis using t-Test
References:
https://docs.microsoft.com/bs-latn-ba/azure/machine-learning/studio-module-reference/filter- based-feature-selection
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/build-counting- transform
NEW QUESTION # 115
......
Valid DP-100 Exam Camp: https://www.pass4guide.com/DP-100-exam-guide-torrent.html
2026 Latest Pass4guide DP-100 PDF Dumps and DP-100 Exam Engine Free Share: https://drive.google.com/open?id=1qI1A9XlhKyTezdy1voLcg45GxpmGPwyi