To ensure that the DP-800 dumps PDF format remains up to date, the Microsoft DP-800 questions in it are regularly revised to reflect any modifications to the DP-800 exam content. This commitment to staying current and aligned with the DP-800 Exam Topics ensures that candidates receive the Developing AI-Enabled Database Solutions (DP-800) updated questions.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
With rigorous analysis and summary of DP-800 exam, we have made the learning content easy to grasp and simplified some parts that beyond candidates' understanding. In addition, we add diagrams and examples to display an explanation in order to make the interface more intuitive. Our DP-800 exam questions will ease your pressure of learning, using less Q&A to convey more important information, thus giving you the top-notch using experience if you study with our DP-800 Training Materials. And with the high pass rate of 99% to 100%, the DP-800 exam will be a piece of cake for you.
NEW QUESTION # 13
You have an Azure SQL database that contains the following tables and columns.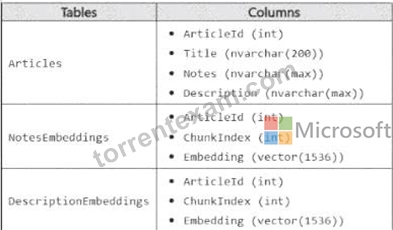
Embeddings in the NotesEnbeddings and DescriptionEabeddings tables have been generated from values in the Description and notes columns of the Articles table by using different chunk sizes.
You need to perform approximate nearest neighbor (ANN) queries across both embedding tables. The solution must minimize the impact of using different chunk sizes.
What should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.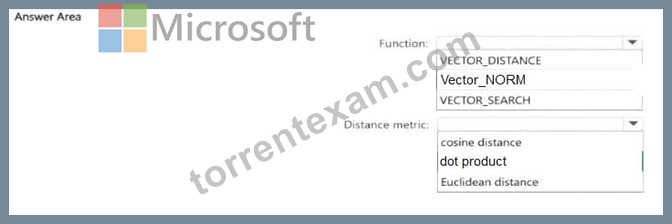
Answer:
Explanation: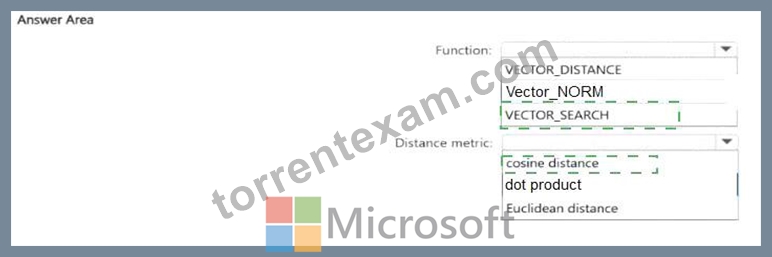
Explanation: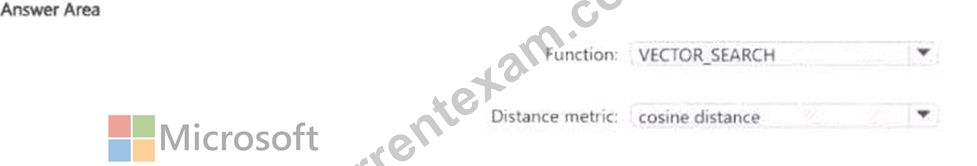
The correct function is VECTOR_SEARCH because the requirement is to perform approximate nearest neighbor (ANN) queries. Microsoft's SQL documentation states that VECTOR_SEARCH is the function used for vector similarity search, and that an ANN index is used only with VECTOR_SEARCH when a compatible vector index exists on the target column. By contrast, VECTOR_DISTANCE calculates an exact distance and does not use a vector index for ANN retrieval.
The correct distance metric is cosine distance. Microsoft documents that VECTOR_SEARCH supports cosine, dot, and euclidean metrics, and Microsoft guidance specifically notes that cosine similarity is commonly used for text embeddings. It also states that retrieval of the most similar texts to a given text typically functions better with cosine similarity, and that Azure OpenAI embeddings rely on cosine similarity to compute similarity between a query and documents. Since both NotesEmbeddings and DescriptionEmbeddings are text-derived embeddings and the goal is to minimize the impact of different chunk sizes, cosine is the best choice because it compares direction/angle rather than being as sensitive to vector magnitude as Euclidean distance.
NEW QUESTION # 14
You have a GitHub Enterprise subscription.
Your team is developing an Azure SQL dataset solution from a locally cloned GitHub repository by using Microsoft Visual Studio Code and GitHub Copilot Chat.
A mix of GitHub Copilot instructions is configured at different levels, including organization-wide, repository- wide, agent-specific, and personal.
Based on the GitHub Copilot instruction precedence rules, which instructions will take precedence over the others?
Answer: D
NEW QUESTION # 15
You have an Azure SQL database that contains a table named stores, stores contains a column named description and a vector column named embedding.
You need to implement a hybrid search query that meets the following requirements:
* Uses full-text search on description for the keyword portion
* Returns the top 20 results based on a combined score that uses a weighted formula of 60% vector distance and 40% full-text rank How should you configure the query components? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.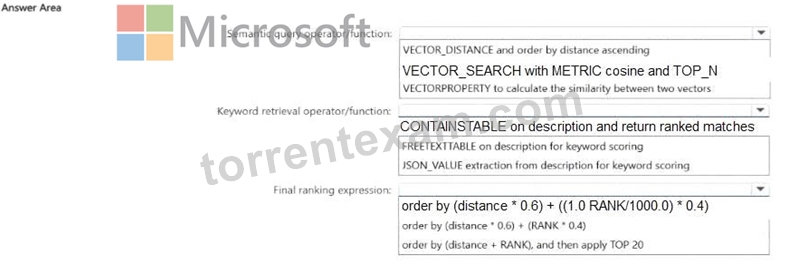
Answer:
Explanation: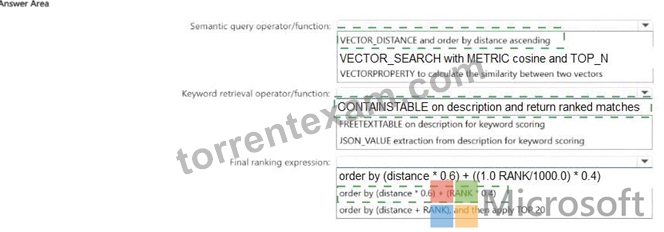
Explanation: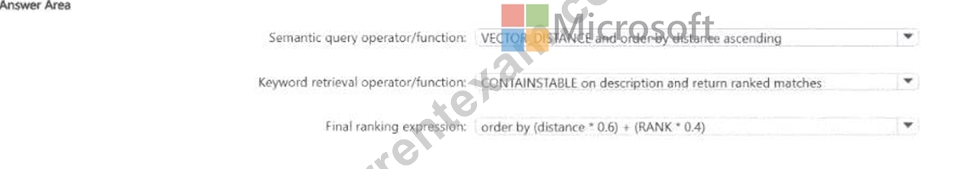
For the vector portion, the correct choice is VECTOR_DISTANCE and order by distance ascending . The requirement is to build a combined weighted formula using the actual vector distance. Microsoft documents that VECTOR_DISTANCE returns the exact distance between two vectors. Since lower distance means greater similarity, ascending distance is the right direction for ranking. VECTOR_SEARCH is for ANN retrieval, but this hotspot specifically asks for a weighted formula based on distance , so VECTOR_DISTANCE is the appropriate operator.
For the keyword portion, the correct choice is CONTAINSTABLE on description and return ranked matches . Microsoft documents that CONTAINSTABLE returns a RANK column from 0 through 1000 , which is exactly what is needed for weighted scoring in a hybrid formula.
For the final ranking expression, the best choice is order by (distance * 0.6) + ((1.0 - RANK/1000.0) * 0.4) .
This works because vector distance is a lower-is-better metric, while full-text RANK is a higher-is-better metric. Dividing RANK by 1000 normalizes it to the documented range, and subtracting from 1.0 converts it into a lower-is-better term so both components can be combined consistently in one ascending score. This final step is a sound inference based on Microsoft's documented distance semantics and full-text rank range.
NEW QUESTION # 16
You have an Azure SQL database that contains a table named Rooms. Rooms was created by using the following transact-SQL statement.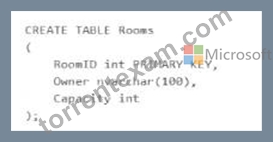
You discover that some records in the Rooms table contain NULL values for the Owner field. You need to ensure that all future records have a value for the Owner field. What should you add?
Answer: A
Explanation:
The table definition allows Owner to be nullable because it was created as Owner nvarchar(100) without NOT NULL. Since the question asks what to add so that future rows must have a value, a check constraint such as CHECK (Owner IS NOT NULL) is the appropriate choice. Microsoft documents that check constraints validate future INSERT and UPDATE operations against the constraint condition.
The other options do not solve the requirement:
* A foreign key enforces referential integrity, not non-null entry by itself.
* A nonclustered index does not require values to be present.
* A unique constraint prevents duplicate values but still does not serve as the right mechanism here for enforcing presence across future writes. Microsoft's constraint documentation also notes that primary- key columns are implicitly NOT NULL, which helps distinguish nullability enforcement from other constraint types.
NEW QUESTION # 17
Case Study 2 - Fabrikam
Existing Environment
Azure Environment
Fabrikam has a single Azure subscription in the East US 2 Azure region. The subscription contains an Azure SQL database named DB1. DB1 contains the following tables:
* Patients
* Employees
* Procedures
* Transactions
* UsefulPrompts
* ProcedureDocuments
You store a column master key as a secret in Azure Key Vault.
You have an on-premises application named TransactionProcessing that uses a hard-coded username and password in a connection string to access DB1.
Problem Statements
Users report that after executing a long-running stored procedure named sp_UpdateProcedureForPatient, updates to the underlying data are sometimes inconsistent.
Requirements
Planned Changes
Fabrikam plans to manage all changes to Azure SQL Database objects by using source control in GitHub. Every pull request submitted to production will be validated before it can be merged.
Deployments must use the Release configuration.
Security Requirements
Fabrikam identifies the following security requirements:
* The TransactionProcessing application must use a passwordless connection to DB1.
* The Employees table contains two columns named TaxID and Salary that must be encrypted at rest.
* Auditors must have a tamper-evident history of transactions with cryptographic proof of changes to the employee data.
Database Performance Requirements
Records accessed by using sp_UpdateProcedureForPatient must NOT be changed by other transactions while the stored procedure runs.
AI Search, Embeddings, and Vector Indexing
Fabrikam identifies the following AI-related requirements:
* Queries to the ProcedureDocuments table must use Reciprocal Rank Fusion (RRF).
* Users must be able to query the data in DB1 by using prompts in Copilot in Microsoft Fabric.
* The UsefulPrompts table will store prompts that doctors can use to help diagnose patient illness by connecting to an Azure OpenAI endpoint.
Development Requirements
Fabrikam identifies the following development requirements:
* Provide the functionality to retrieve all the transactions of a given patient between two dates, showing a running total.
* Expose a Data API builder (DAB) configuration file to enable Azure services to perform the following operations over a REST API:
- Read data from the procedures table without authentication.
- Read and insert data into the Transactions table once authenticated.
- Execute the sp_UpdateProcedurePatient stored procedure.
* Provide the functionality to retrieve a list of the names of patients who underwent medical procedures during the last 30 days.
* Information for each medical procedure will be stored in a table. The table will be used with a large language model (LLM) for user querying and will have the following structure.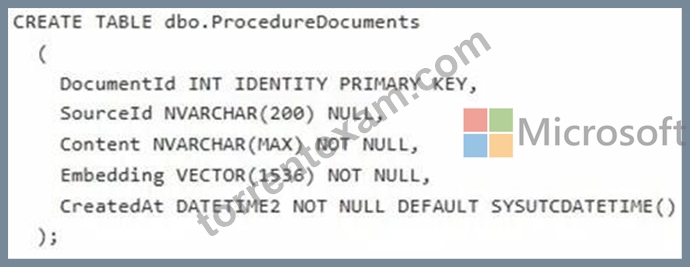
DAB
You create a DAB configuration file that meets the development requirements for DB1 and includes the following entities.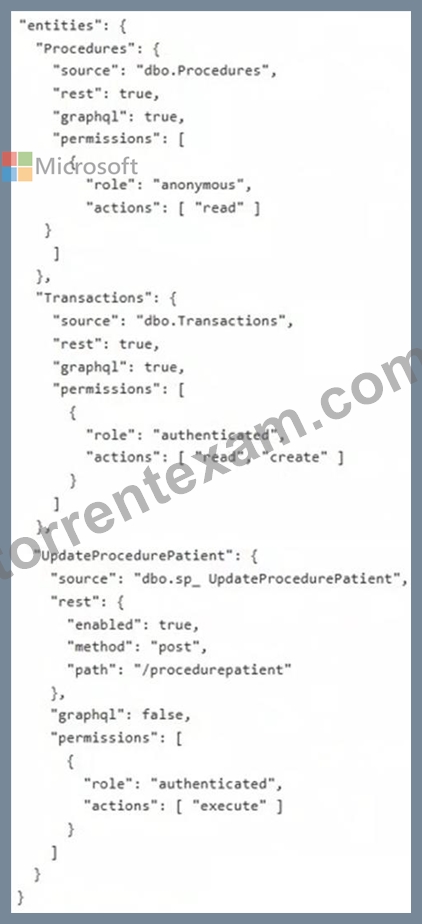
You implement ProcedureDocuments to support the planned changes.
When users consume data through the Retrieval Augmented Generation (RAG) pattern, they experience data retrieval delays.
You need to improve the data retrieval performance and reduce the number of tokens per retrieval.
What should you implement?
Answer: A
Explanation:
Scenario: Fabrikam identifies the following AI-related requirements: Queries to the ProcedureDocuments table must use Reciprocal Rank Fusion (RRF).
To remedy data retrieval delays in a Retrieval Augmented Generation (RAG) pattern using Reciprocal Rank Fusion (RRF) on an Azure SQL Database table, you should use embeddings.
In a RAG architecture, retrieval delays often stem from inefficient or computationally heavy search processes. While RRF is excellent for merging results from multiple sources (like combining keyword and vector searches), the core of the speed problem typically lies in how the initial data is indexed and retrieved.
Role of Embeddings
Vector Search Acceleration: Embeddings convert text into high-dimensional vectors. Azure SQL Database can perform similarity searches on these vectors much faster than complex semantic text matching.
Hybrid Search Synergy: RRF is most effective when it fuses results from a keyword search (fast) and a vector search (powered by embeddings). Using embeddings ensures that the "semantic" side of the retrieval is streamlined.
Pre-computation: Since embeddings are generated once during ingestion, the retrieval phase only requires a distance calculation (e.g., Cosine Similarity), which is significantly faster than real- time natural language parsing during each query.
Reference:
https://pratikbarjatya.medium.com/unlocking-the-power-of-language-with-retrieval-augmented- generation-rag-14123cc275e6
NEW QUESTION # 18
......
Our DP-800 practice materials not only apply to students, but also apply to office workers; not only apply to veterans in the workplace, but also apply to newly recruited newcomers. Our DP-800 study materials use a very simple and understandable language, to ensure that all people can learn and understand. Our DP-800 real test also allows you to avoid the boring of textbook reading, but let you master all the important knowledge in the process of doing exercises. And the high pass rate of our DP-800 exam questions is more than 98%. Why not have a try on our DP-800 study guide?
New DP-800 Test Cost: https://www.torrentexam.com/DP-800-exam-latest-torrent.html