P.S. Free 2026 Microsoft DP-800 dumps are available on Google Drive shared by Prep4pass: https://drive.google.com/open?id=1ofQU_l-uiRpx3qk4240YiUZbA3T0N44I
On the one hand, DP-800 test torrent is revised and updated according to the changes in the syllabus and the latest developments in theory and practice. On the other hand, a simple, easy-to-understand language of DP-800 test answers frees any learner from any learning difficulties - whether you are a student or a staff member. These two characteristics determine that almost all of the candidates who use DP-800 Guide Torrent can pass the test at one time. This is not self-determination. According to statistics, by far, our DP-800 guide torrent has achieved a high pass rate of 98% to 99%, which exceeds all others to a considerable extent. At the same time, there are specialized staffs to check whether the DP-800 test torrent is updated every day.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
Prep4pass has hired professionals to supervise the quality of the DP-800 PDF prep material. Laptops, tablets, and smartphones support the Microsoft DP-800 test questions PDF file. If any taker of the Microsoft DP-800 test prepares thoroughly with our exam product he will crack the exam of the credential on the first attempt.
NEW QUESTION # 29
You have an Azure SQL database that supports an AI-enabled product catalog API. The database contains a table named Sales.Orders. Sales.Orders contains 20 million rows and has a nonclustered index on a column named CreateDate.
The API passes a date parameter named @OrderDate.
You have a stored procedure named get_latest_day_orders that filters by running the following query.
WHERE CAST(CreateDate AS date) = @0rderDate.
A review of the query execution reveals that the query causes an index scan.
You need to modify the predicate to ensure that Microsoft SQL Server can use an index seek on CreateDate for a single day.
Which WHERE clause should you use?
Answer: B
Explanation:
To achieve an Index Seek on your CreateDate column, you must remove the CAST function from the column side of the equation. Wrapping a column in a function makes the expression non- SARGable (Searchable Argument), forcing SQL Server to scan the entire index rather than jumping to a specific range.
The Recommended WHERE Clause
To capture all rows for a single day while remaining SARGable, use a range comparison:
WHERE CreateDate >= @OrderDate
AND CreateDate < DATEADD(day, 1, @OrderDate)
Why This Works
Eliminates Functions on Columns: By keeping CreateDate "naked," the query optimizer can use the nonclustered index to find the exact starting point.
Handles Time Components: Since CreatedDate likely contains time data (DATETIME or DATETIME2), this logic captures everything from 00:00:00.000 up to (but not including) midnight of the following day.
Single Day Precision: It creates a "half-open" interval that is the standard best practice for date filtering in SQL Server.
Reference:
https://medium.com/@c.charalambos1998/how-to-design-indexes-in-sql-server-for-faster-query- performance-4a2279a9b512
NEW QUESTION # 30
Case Study 1 - Contoso
Existing Environment
Azure Environment
Contoso has an Azure subscription in North Europe that contains the corporate infrastructure.
The current infrastructure contains a Microsoft SQL Server 2017 database. The database contains the following tables.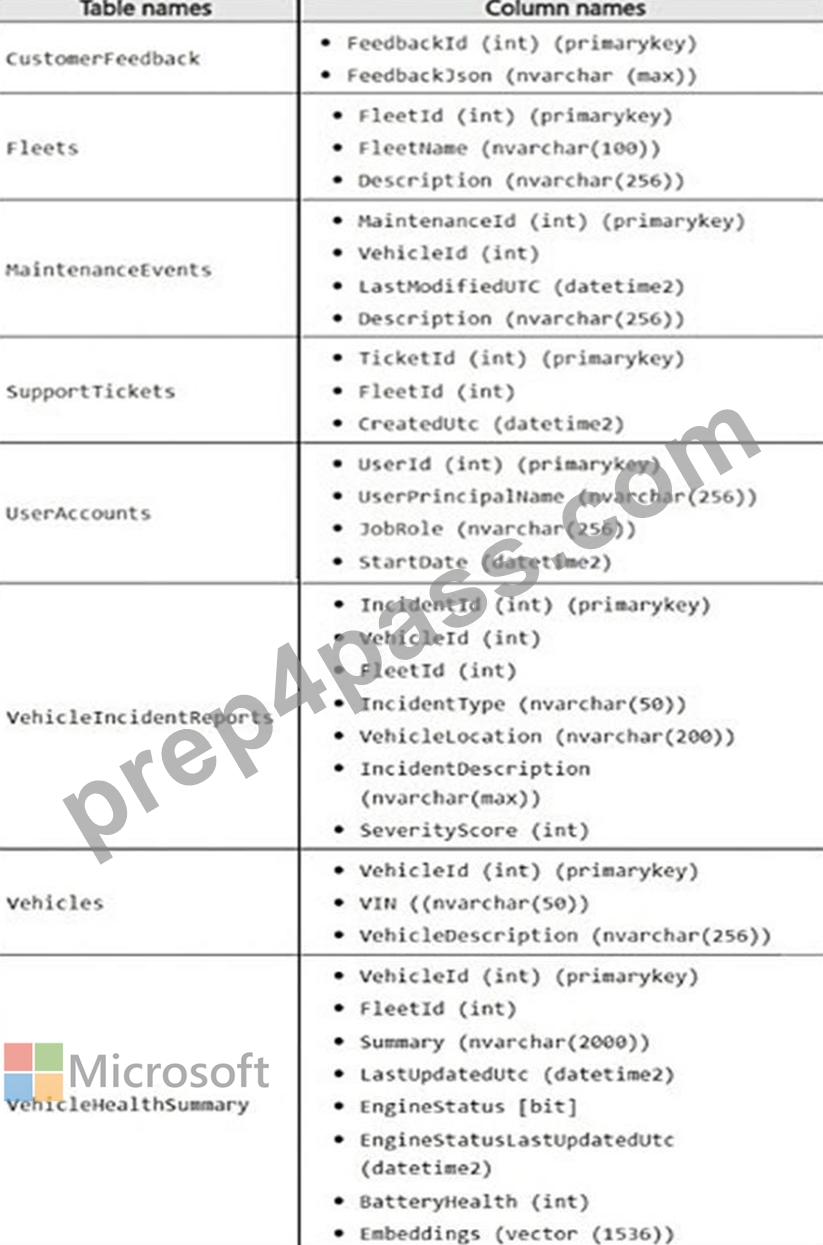
The FeedbackJsoncolumn has a full-text index and stores JSON documents in the following format.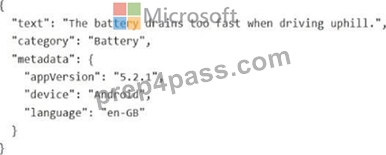
The support staff at Contoso never has the UNMASKpermission.
Problem Statements
Contoso is deploying a new Azure SQL database that will become the authoritative data store for the following:
* AI workloads
* Vector search
* Modernized API access
* Retrieval Augmented Generation (RAG) pipelines
Sometimes the ingestion pipeline fails due to malformed JSON and duplicate payloads.
The engineers at Contoso report that the following dashboard query runs slowly.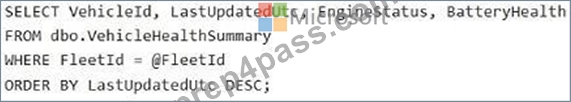
You review the execution plan and discover that the plan shows a clustered index scan.
VehicleIncidentReportsoften contains details about the weather, traffic conditions, and location. Analysts report that it is difficult to find similar incidents based on these details.
Requirements
Planned Changes
Contoso wants to modernize Fleet Intelligence Platform to support AI-powered semantic search over incident reports.
Security Requirements
Contoso identifies the following security requirements:
* Restrict the support staff from viewing Personally Identifiable Information (PII) data, which is full email addresses and phone numbers.
* Enforce row-level filtering so that analysts see only incidents for the fleets to which they are assigned. The analysts can be assigned to multiple fleets.
Database Performance and Requirements
Contoso identifies the following telemetry requirements:
* Telemetry data must be stored in a partitioned table.
* Telemetry data must provide predictable performance for ingestion and retention operations.
* latitude, longitude, and accuracyJSON properties must be filtered by using an index seek.
Contoso identifies the following maintenance data requirements:
* Ensure that any changes to a row in the MaintenanceEventstable updates the corresponding value in the LastModifiedUtccolumn to the time of the change.
* Avoid recursive updates.
AI Search, Embeddings, and Vector Indexing
Contoso plans to implement semantic search over incident data to meet the following requirements:
* Embeddings must be stored in dedicated Azure SQL Database tables.
* Embeddings must be generated from rich natural language fields.
* Chunking must preserve semantic coherence.
* Hybrid search must combine the following:
- Vector similarity
- Keyword filtering or boosting
Development Requirements
The development team at Contoso will use Microsoft Visual Studio Code and GitHub Copilot and will retrieve live metadata from the databases.
Contoso identifies the following requirements for querying data in the FeedbackJsoncolumn of the CustomerFeedbacktable:
* Extract the customer feedback text from the JSON document.
* Filter rows where the JSON text contains a keyword.
* Calculate a fuzzy similarity score between the feedback text and a known issue description.
* Order the results by similarity score, with the highest score first.
You need to recommend a solution to resolve the slow dashboard query issue. What should you recommend?
Answer: C
Explanation:
Scenario:
The engineers at Contoso report that the following dashboard query runs slowly.
You review the execution plan and discover that the plan shows a clustered index scan.
To optimize this query, you should create a covering nonclustered index that handles both the filtering (WHERE) and the sorting (ORDER BY) requirements while including the remaining columns to avoid expensive lookups.
Recommended Index Strategy
Creating an index with FleetID as the first key column and LastUpdateUtc as the second key column will allow SQL Server to perform an Index Seek to find the specific fleet and then retrieve those rows in the pre-sorted order required by your ORDER BY clause.
T-SQL Implementation:
CREATE NONCLUSTERED INDEX IX_VehicleHealth_Fleet_Update
ON dbo.VehicleHealthSummary (FleetID, LastUpdateUtc DESC)
INCLUDE (EngineStatus, BatteryHealth);
Use code with caution.
Why this works
Eliminates Clustered Index Scan: The current plan scans the entire table because no index exists that starts with FleetID. This new index allows the engine to jump directly to the relevant rows.
Avoids a Sort Operator: By including LastUpdateUtc DESC in the index key, the data is already physically ordered. SQL Server can read the index and return the results immediately without needing a costly in-memory sort.
Fully Covers the Query: Using the INCLUDE clause for EngineStatus and BatteryHealth ensures all data required by the SELECT statement is present in the index. This prevents "Key Lookups," where the engine would otherwise have to go back to the original table for those specific values.
Reference:
https://www.mssqltips.com/sqlservertip/8192/sql-server-uses-non-clustered-index-rather-than- clustered-index
NEW QUESTION # 31
You have an Azure SQL database That contains a table named dbo.Products, dbo.Products contains three columns named Embedding Category, and Price. The Embedding column is defined as VECTOR(1536).
You use Ai_GENERME_EMBEDOINGS and VECTOR_SEARCH to support semantic search and apply additional filters on two columns named Category and Price.
You plan to change the embedding model from text-embedding-ada-002 to text-embedding-3-smalL Existing rows already contain embeddings in the Embedding column.
You need to implement the model change. Applications must be able to use VECTOR_SEARCH without runtime errors.
What should you do first?
Answer: C
Explanation:
When you change embedding models, the stored vectors should be treated as belonging to a different embedding space unless you intentionally keep the entire corpus consistent. Microsoft's vector guidance notes that when most or all embeddings are replaced with fresh embeddings from a new model, the recommended practice is to reload the new embeddings and, for large-scale replacement scenarios, consider dropping and recreating the vector index afterward so search quality remains predictable.
This question also says applications must continue to use VECTOR_SEARCH without runtime errors .
VECTOR_SEARCH requires compatible vector dimensions, and the vector column already exists. Azure OpenAI documentation shows that text-embedding-ada-002 is fixed at 1536 dimensions and text- embedding-3-small supports up to 1536 dimensions . That means the migration can remain compatible with a VECTOR(1536) column, but the right implementation step is still to re-embed the existing rows so the table does not contain a mixed corpus produced by different models.
The other options are not appropriate:
* B normalization does not solve a model migration problem.
* C converting the vector column to nvarchar(max) would break vector-native search design.
* D a vector index improves performance, but it does not migrate old embeddings to the new model.
NEW QUESTION # 32
You have an Azure Al Search service and an index named hotels that includes a vector Held named DescriptionVector.
You query hotels by using the Search Documents REST API.
You add semantic ranking to the hybrid search query and discover that some queries return fewer results than expected, and captions and answers are missing.
You need to complete the hybrid search request to meet the following requirements:
* Include more documents when ranking.
* Always include captions and answers.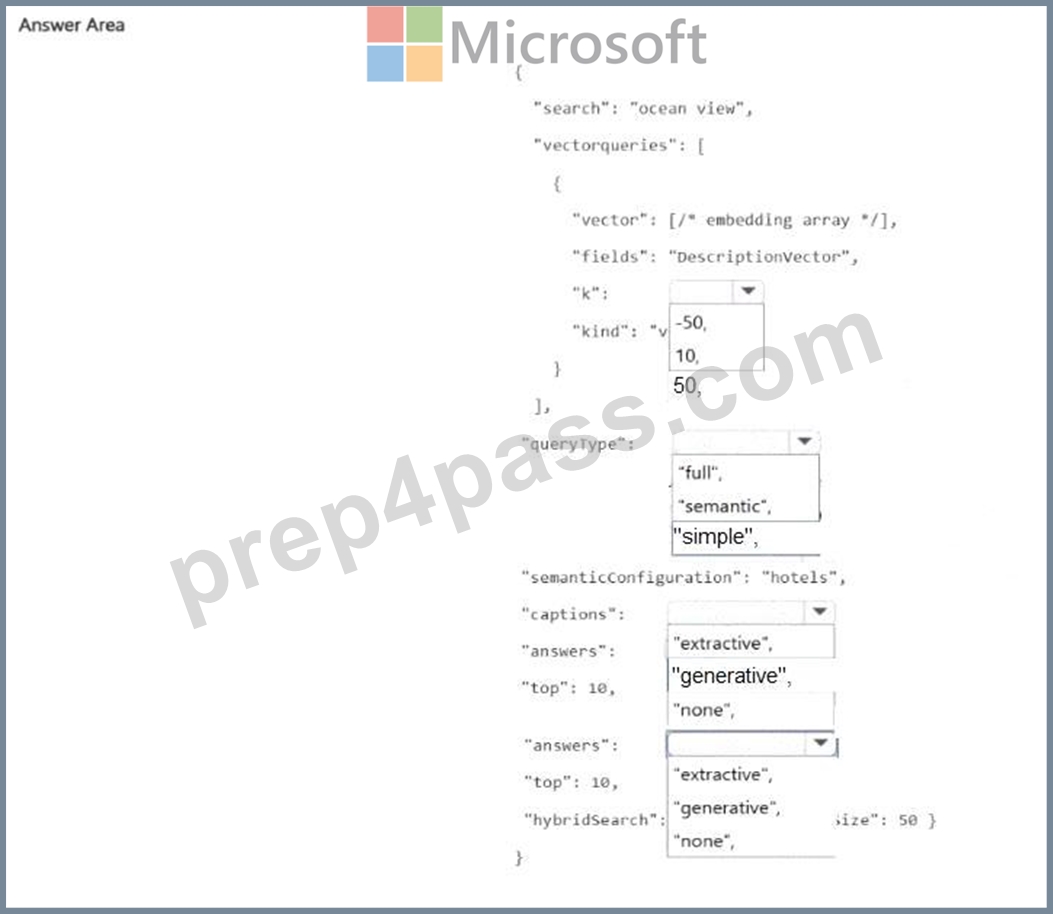
Answer:
Explanation: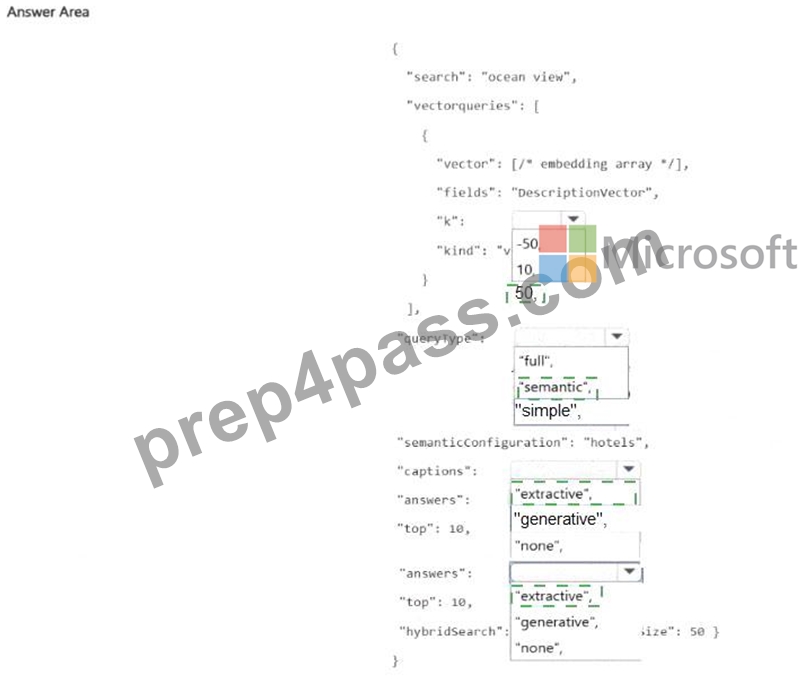
Explanation: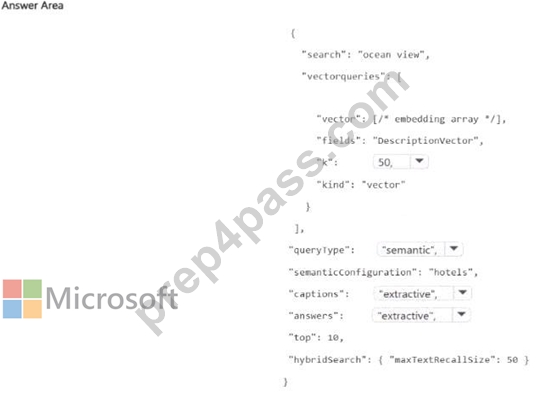
These are the correct selections for a hybrid query that uses semantic ranking in Azure AI Search.
Use k = 50 because Microsoft explicitly recommends that when you combine semantic ranking with vector queries , you should set k to 50 so the semantic ranker has enough candidates to rerank. If you use a smaller value such as 10, semantic ranking can receive too few inputs, which is exactly why some queries return fewer results than expected.
Use queryType = " semantic " because captions and answers are only available on semantic queries.
Microsoft documents that captions is valid only when the query type is semantic, and semantic answers are returned only for semantic queries.
Use captions = " extractive " because semantic captions are extractive passages pulled from the top-ranked documents. Microsoft's REST documentation states that the valid captions option here is extractive and that it defaults to none if not specified.
Use answers = " extractive " because semantic answers in Azure AI Search are extractive, not generated.
Microsoft documents that semantic answers are verbatim passages recognized as answers and the REST API lists extractive as the answer-return option.
NEW QUESTION # 33
You have an Azure SQL database that contains a table named Sales.Orders. Sales.Orders contains the following columns.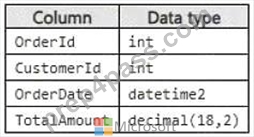
Reporting queries frequently repeat logic to calculate the number of days since an order was placed.
You need to create a scalar user-defined function (UDF) that returns the number of days between an input value of @OrderDate and the current date and time.
How should you complete the Transact-SQL code? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.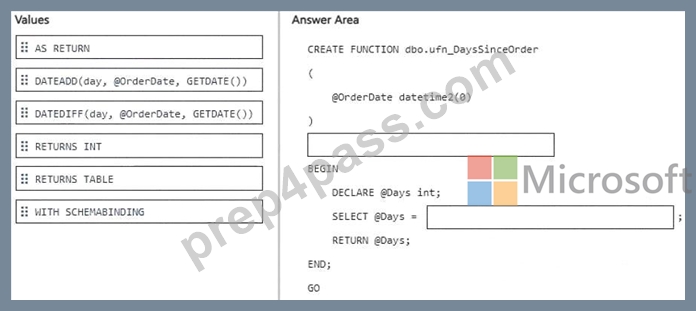
Answer:
Explanation: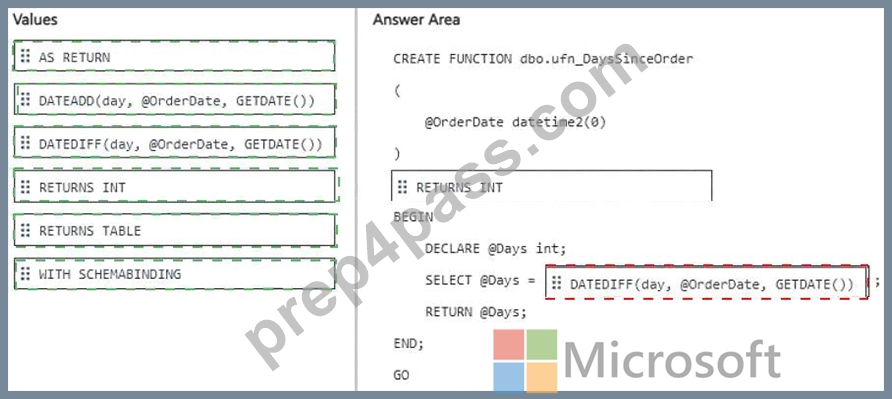
Explanation:
* Function return type # RETURNS INT
* Calculation # DATEDIFF(day, @OrderDate, GETDATE())
Comprehensive and Detailed Explanation with all Developing AI-Enabled Database Solutions documents : = The first correct selection is RETURNS INT because the requirement is to create a scalar UDF that returns a single integer representing the number of days since the order date. Microsoft documents that scalar user- defined functions return a single scalar value, and DATEDIFF returns an int value.
The second correct selection is:
DATEDIFF(day, @OrderDate, GETDATE())
Microsoft defines DATEDIFF(datepart, startdate, enddate) as returning the number of specified datepart boundaries crossed between two dates. Therefore, placing @OrderDate as the start date and GETDATE() as the end date returns the number of elapsed day boundaries from the order date to the current date and time.
GETDATE() is valid inside a Transact-SQL UDF. Microsoft explicitly lists GETDATE among the nondeterministic built-in functions that can be used in T-SQL user-defined functions . Its nondeterministic nature means the result changes over time, but it does not prevent creation of this scalar UDF.
The completed code is:
CREATE FUNCTION dbo.ufn_DaysSinceOrder
(
@OrderDate datetime2(0)
)
RETURNS INT
BEGIN
DECLARE @Days int;
SELECT @Days =
DATEDIFF(day, @OrderDate, GETDATE());
RETURN @Days;
END;
GO
So the drag-and-drop answers are:
* First target: RETURNS INT
* Second target: DATEDIFF(day, @OrderDate, GETDATE())
NEW QUESTION # 34
......
The Developing AI-Enabled Database Solutions (DP-800) exam questions are real, valid, and verified by Microsoft DP-800 certification exam trainers. They work together and put all their efforts to ensure the top standard and relevancy of DP-800 Exam Dumps all the time. So we can say that with Microsoft DP-800 exam questions you will get everything that you need to make the DP-800 exam preparation simple, smart, and successful.
DP-800 Reliable Exam Online: https://www.prep4pass.com/DP-800_exam-braindumps.html
BONUS!!! Download part of Prep4pass DP-800 dumps for free: https://drive.google.com/open?id=1ofQU_l-uiRpx3qk4240YiUZbA3T0N44I