New Databricks-Certified-Data-Engineer-Professional Exam Testking, Databricks-Certified-Data-Engineer-Professional Exam Vce Format

With our study materials, you do not need to have a high IQ, you do not need to spend a lot of time to learn, you only need to follow the method Databricks-Certified-Data-Engineer-Professional real questions provide to you, and then you can easily pass the exam. Our study material is like a tutor helping you learn, but unlike a tutor who make you spend too much money and time on learning. As usual, you just need to spend little time can have a good commend of our study materials, then you can attend to your Databricks-Certified-Data-Engineer-Professional Exam and pass it at your first attempt.
| Section | Weight | Objectives |
|---|
| Topic 1: Databricks Lakehouse Platform | 24% | - Unity Catalog
- Delta Lake
- Lakehouse Architecture
- Data Management
|
| Topic 2: Monitoring and Troubleshooting | 16% | - Performance Optimization
- Troubleshooting
- Monitoring
|
| Topic 3: Data Quality and Governance | 12% | - Data Quality
- Governance
- Data Lineage
|
| Topic 4: Data Processing | 28% | - Spark SQL
- Data Transformation
- Structured Streaming
- ETL Pipelines
|
| Topic 5: Data Modeling and Storage | 20% | - Storage Optimization
- Data Modeling
- File Formats
|
>> New Databricks-Certified-Data-Engineer-Professional Exam Testking <<
100% Pass Newest Databricks-Certified-Data-Engineer-Professional - New Databricks Certified Data Engineer Professional Exam Exam Testking
If you are still study hard to prepare the Databricks Databricks-Certified-Data-Engineer-Professional Exam, you're wrong. Of course, with studying hard, you can pass the exam. But may not be able to achieve the desired effect. Now this is the age of the Internet, there are a lot of shortcut to success. Pass4suresVCE's Databricks Databricks-Certified-Data-Engineer-Professional exam training materials is a good training materials. It is targeted, and guarantee that you can pass the exam. This training matrial is not only have reasonable price, and will save you a lot of time. You can use the rest of your time to do more things. So that you can achieve a multiplier effect.
Databricks Certified Data Engineer Professional Exam Sample Questions (Q108-Q113):
NEW QUESTION # 108
A data team's Structured Streaming job is configured to calculate running aggregates for item sales to update a downstream marketing dashboard. The marketing team has introduced a new field to track the number of times this promotion code is used for each item. A junior data engineer suggests updating the existing query as follows: Note that proposed changes are in bold.
Original query:
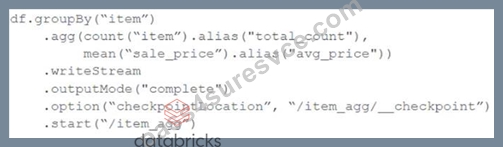
Proposed query:
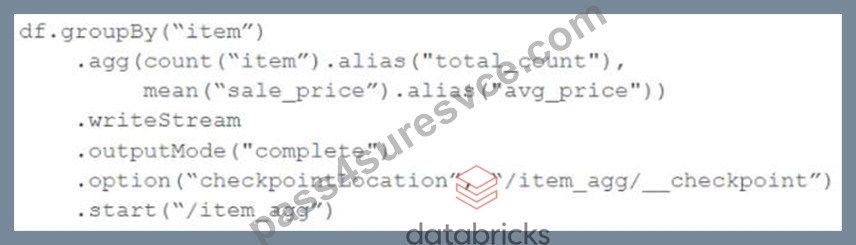
Which step must also be completed to put the proposed query into production?
- A. Run REFRESH TABLE delta, /item_agg'
- B. Specify a new checkpointlocation
- C. Increase the shuffle partitions to account for additional aggregates
- D. Remove .option (mergeSchema', true') from the streaming write
- E. Register the data in the "/item_agg" directory to the Hive metastore
Answer: B
Explanation:
When introducing a new aggregation or a change in the logic of a Structured Streaming query, it is generally necessary to specify a new checkpoint location. This is because the checkpoint directory contains metadata about the offsets and the state of the aggregations of a streaming query. If the logic of the query changes, such as including a new aggregation field, the state information saved in the current checkpoint would not be compatible with the new logic, potentially leading to incorrect results or failures. Therefore, to accommodate the new field and ensure the streaming job has the correct starting point and state information for aggregations, a new checkpoint location should be specified.
NEW QUESTION # 109
A data engineer wants to join a stream of advertisement impressions (when an ad was shown) with another stream of user clicks on advertisements to correlate when impression led to monitizable clicks.

Which solution would improve the performance?
Answer: C
Explanation:
When joining a stream of advertisement impressions with a stream of user clicks, you want to minimize the state that you need to maintain for the join. Option A suggests using a left outer join with the condition that clickTime == impressionTime, which is suitable for correlating events that occur at the exact same time. However, in a real-world scenario, you would likely need some leeway to account for the delay between an impression and a possible click. It's important to design the join condition and the window of time considered to optimize performance while still capturing the relevant user interactions. In this case, having the watermark can help with state management and avoid state growing unbounded by discarding old state data that's unlikely to match with new data.
NEW QUESTION # 110
What is the first line of a Databricks Python notebook when viewed in a text editor?
- A. # Databricks notebook source
- B. // Databricks notebook source
- C. # MAGIC %python
- D. %python
- E. -- Databricks notebook source
Answer: A
Explanation:
https://docs.databricks.com/en/notebooks/notebook-export-import.html#import-a-file-and-convert- it-to-a-notebook
NEW QUESTION # 111
Which of the following technologies can be used to identify key areas of text when parsing Spark Driver log4j output?
- A. pyspsark.ml.feature
- B. Scala Datasets
- C. Regex
- D. Julia
- E. C++
Answer: C
Explanation:
Regex, or regular expressions, are a powerful way of matching patterns in text. They can be used to identify key areas of text when parsing Spark Driver log4j output, such as the log level, the timestamp, the thread name, the class name, the method name, and the message. Regex can be applied in various languages and frameworks, such as Scala, Python, Java, Spark SQL, and Databricks notebooks.
NEW QUESTION # 112
A data engineer is using Auto Loader to read incoming JSON data as it arrives. They have configured Auto Loader to quarantine invalid JSON records but notice that over time, some records are being quarantined even though they are well-formed JSON.
The code snippet is:
df = (spark.readStream
.format("cloudFiles")
.option("cloudFiles.format", "json")
.option("badRecordsPath", "/tmp/somewhere/badRecordsPath")
.schema("a int, b int")
.load("/Volumes/catalog/schema/raw_data/"))
What is the cause of the missing data?
- A. The engineer forgot to set the option "cloudFiles.quarantineMode" = "rescue".
- B. At some point, the upstream data provider switched everything to multi-line JSON.
- C. The badRecordsPath location is accumulating many small files.
- D. The source data is valid JSON but does not conform to the defined schema in some way.
Answer: D
Explanation:
Auto Loader quarantines records that cannot be parsed according to the specified schema, even if the JSON itself is well formed. If incoming records contain additional fields, missing fields, or incompatible data types compared to the declared schema, they are treated as invalid and routed to the bad records path.
NEW QUESTION # 113
......
All contents are masterpieces from experts who imparted essence of the exam into our Databricks-Certified-Data-Engineer-Professional practice materials. So our high quality and high efficiency Databricks-Certified-Data-Engineer-Professional practice materials conciliate wide acceptance around the world. By incubating all useful content Databricks-Certified-Data-Engineer-Professional practice materials get passing rate from former exam candidates of 98 which evince our accuracy rate and proficiency. If your problems are divulging during the review you can pick out the difficult one and focus on those parts.
Databricks-Certified-Data-Engineer-Professional Exam Vce Format: https://www.pass4suresvce.com/Databricks-Certified-Data-Engineer-Professional-pass4sure-vce-dumps.html
- Databricks-Certified-Data-Engineer-Professional Pass4sure 🤙 Databricks-Certified-Data-Engineer-Professional Free Test Questions 😽 Databricks-Certified-Data-Engineer-Professional Test Questions Answers 🛅 Search for ➡ Databricks-Certified-Data-Engineer-Professional ️⬅️ and obtain a free download on ➡ www.verifieddumps.com ️⬅️ 🌭New Guide Databricks-Certified-Data-Engineer-Professional Files
- Free PDF Quiz Databricks - Pass-Sure Databricks-Certified-Data-Engineer-Professional - New Databricks Certified Data Engineer Professional Exam Exam Testking ⏹ Download ☀ Databricks-Certified-Data-Engineer-Professional ️☀️ for free by simply searching on ⏩ www.pdfvce.com ⏪ 🧦Test Databricks-Certified-Data-Engineer-Professional Centres
- Prepare for the Databricks Databricks-Certified-Data-Engineer-Professional Exam on Any Device with www.troytecdumps.com PDF Format 😦 Copy URL ⇛ www.troytecdumps.com ⇚ open and search for ➽ Databricks-Certified-Data-Engineer-Professional 🢪 to download for free 🚝Databricks-Certified-Data-Engineer-Professional Test Questions Answers
- Databricks-Certified-Data-Engineer-Professional valid Pass4sures torrent - Databricks-Certified-Data-Engineer-Professional useful study vce 🧵 Search on ➥ www.pdfvce.com 🡄 for ( Databricks-Certified-Data-Engineer-Professional ) to obtain exam materials for free download 📣Databricks-Certified-Data-Engineer-Professional Valid Examcollection
- Databricks-Certified-Data-Engineer-Professional Valid Dumps 👶 Databricks-Certified-Data-Engineer-Professional Questions 😇 Databricks-Certified-Data-Engineer-Professional Latest Real Exam ⌛ The page for free download of ✔ Databricks-Certified-Data-Engineer-Professional ️✔️ on ▶ www.pdfdumps.com ◀ will open immediately 🏏Exam Databricks-Certified-Data-Engineer-Professional Topics
- Download Free Updated Pdfvce Databricks Databricks-Certified-Data-Engineer-Professional Dumps PDF after Paying Affordable Charges 👙 Enter ➽ www.pdfvce.com 🢪 and search for ▛ Databricks-Certified-Data-Engineer-Professional ▟ to download for free ⏲New Guide Databricks-Certified-Data-Engineer-Professional Files
- Databricks-Certified-Data-Engineer-Professional Questions 🕝 Databricks-Certified-Data-Engineer-Professional Valid Test Dumps 📘 Databricks-Certified-Data-Engineer-Professional Latest Real Exam 🍬 Search for ▛ Databricks-Certified-Data-Engineer-Professional ▟ on 【 www.vce4dumps.com 】 immediately to obtain a free download 🟢Exam Databricks-Certified-Data-Engineer-Professional Topics
- Latest Databricks-Certified-Data-Engineer-Professional Braindumps Files 🏆 Actual Databricks-Certified-Data-Engineer-Professional Test Answers ⚽ Test Databricks-Certified-Data-Engineer-Professional Centres 🍑 The page for free download of ▛ Databricks-Certified-Data-Engineer-Professional ▟ on “ www.pdfvce.com ” will open immediately 🍖Latest Databricks-Certified-Data-Engineer-Professional Braindumps Files
- Download Free Updated www.examcollectionpass.com Databricks Databricks-Certified-Data-Engineer-Professional Dumps PDF after Paying Affordable Charges 🎃 Search for 【 Databricks-Certified-Data-Engineer-Professional 】 and obtain a free download on “ www.examcollectionpass.com ” 🔉Databricks-Certified-Data-Engineer-Professional Free Test Questions
- 2026 Accurate 100% Free Databricks-Certified-Data-Engineer-Professional – 100% Free New Exam Testking | Databricks-Certified-Data-Engineer-Professional Exam Vce Format 📠 Go to website ⇛ www.pdfvce.com ⇚ open and search for ➠ Databricks-Certified-Data-Engineer-Professional 🠰 to download for free 😷Databricks-Certified-Data-Engineer-Professional Free Test Questions
- Databricks-Certified-Data-Engineer-Professional Actual Test Pdf ✒ New Guide Databricks-Certified-Data-Engineer-Professional Files 🐕 Actual Databricks-Certified-Data-Engineer-Professional Test Answers 🦇 Search for ⮆ Databricks-Certified-Data-Engineer-Professional ⮄ and obtain a free download on ⏩ www.examdiscuss.com ⏪ 🔒Databricks-Certified-Data-Engineer-Professional Valid Dumps
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, pastebin.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes



