Databricks Databricks-Certified-Data-Engineer-Professional시험패스가능한인증덤프자료 - Databricks-Certified-Data-Engineer-Professional인기덤프공부

참고: PassTIP에서 Google Drive로 공유하는 무료, 최신 Databricks-Certified-Data-Engineer-Professional 시험 문제집이 있습니다: https://drive.google.com/open?id=1epOk3j4ASxcQ1pyn20FX8OsX28DFirCd
PassTIP덤프를 IT국제인증자격증 시험대비자료중 가장 퍼펙트한 자료로 거듭날수 있도록 최선을 다하고 있습니다. Databricks Databricks-Certified-Data-Engineer-Professional 덤프에는Databricks Databricks-Certified-Data-Engineer-Professional시험문제의 모든 범위와 유형을 포함하고 있어 시험적중율이 높아 구매한 분이 모두 시험을 패스한 인기덤프입니다.만약 시험문제가 변경되어 시험에서 불합격 받으신다면 덤프비용 전액 환불해드리기에 안심하셔도 됩니다.
Databricks Databricks-Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|
| Topic 1: Data Transformation, Cleansing, and Quality | 10% | - Implement schema evolution and management
- Enforce data quality standards
- Apply data cleansing and validation rules
|
| Topic 2: Data Sharing and Federation | 5% | - Implement Lakehouse Federation
- Use Delta Sharing for secure data sharing
- Manage cross-platform data access
|
| Topic 3: Ensuring Data Security and Compliance | 10% | - Secure data at rest and in transit
- Ensure data privacy and compliance
- Implement access control and permissions
|
| Topic 4: Developing Code for Data Processing using Python and SQL | 22% | - Implement complex data processing logic
- Write efficient and maintainable code
- Use Databricks-specific libraries and APIs
|
| Topic 5: Data Governance | 7% | - Use Unity Catalog for governance
- Manage data assets and metadata
- Enforce data policies and standards
|
| Topic 6: Data Modelling | 6% | - Implement dimensional and relational models
- Design Medallion Architecture
- Optimize table design and partitioning
|
| Topic 7: Monitoring and Alerting | 10% | - Set up alerts and notifications
- Monitor pipeline performance and health
- Track data lineage and metrics
|
| Topic 8: Cost & Performance Optimisation | 13% | - Apply cost management best practices
- Improve query and pipeline performance
- Optimize compute and storage resources
|
| Topic 9: Debugging and Deploying | 10% | - Implement CI/CD and DevOps practices
- Deploy using Asset Bundles, CLI, and APIs
- Troubleshoot and debug pipelines
|
| Topic 10: Data Ingestion & Acquisition | 7% | - Ingest data from diverse sources
- Handle incremental and batch data loads
- Use Auto Loader and structured streaming
|
>> Databricks Databricks-Certified-Data-Engineer-Professional시험패스 가능한 인증덤프자료 <<
시험패스에 유효한 Databricks-Certified-Data-Engineer-Professional시험패스 가능한 인증덤프자료 최신버전 덤프데모문제 다운로드
PassTIP는 우수한 IT인증시험 공부가이드를 제공하는 전문 사이트인데 업계에서 높은 인지도를 가지고 있습니다. PassTIP에서는 IT인증시험에 대비한 모든 덤프자료를 제공해드립니다. Databricks인증 Databricks-Certified-Data-Engineer-Professional시험을 준비하고 계시는 분들은PassTIP의Databricks인증 Databricks-Certified-Data-Engineer-Professional덤프로 시험준비를 해보세요. 놀라운 고득점으로 시험패스를 도와드릴것입니다.시험에서 불합격하면 덤프비용 전액환불을 약속드립니다.
최신 Databricks Certification Databricks-Certified-Data-Engineer-Professional 무료샘플문제 (Q144-Q149):
질문 # 144
A data engineer is working in an interactive notebook with many transformations before outputting the result from display(df.collect() ). The notebook includes wide transformations and a cross join.
The data engineer is getting the following error: "The spark driver has stopped unexpectedly and is restarting. Your notebook will be automatically reattached." Which action should the data engineer take?
- A. Look at the compute metrics UI to see if the executors have higher than 90% memory utilization.
- B. Rewrite their code to avoid putting memory pressure on the driver node.
- C. Check into the Spark UI to see how many jobs are assigned to each stage as they are employing fewer executors.
- D. Run the notebook on a single node cluster to keep driver from falling.
정답:B
설명:
Calling df.collect() on a large DataFrame forces all data to be loaded into the driver's memory.
With wide transformations and a cross join, this can easily exceed the driver's capacity, causing it to crash. The data engineer should rewrite the code to avoid collecting large datasets on the driver, using operations like display(df) or writing to storage instead.
질문 # 145
What is the first line of a Databricks Python notebook when viewed in a text editor?
- A. # Databricks notebook source
- B. -- Databricks notebook source
- C. # MAGIC %python
- D. %python
- E. // Databricks notebook source
정답:A
설명:
https://docs.databricks.com/en/notebooks/notebook-export-import.html#import-a-file-and-convert- it-to-a-notebook
질문 # 146
A platform team is creating a standardized template for Databricks Asset Bundles to support CI/CD. The template must specify defaults for artifacts, workspace root paths, and a run identity, while allowing a "dev" target to be the default and override specific paths. How should the team use databricks.yml to satisfy these requirements?
- A. Use deployment, builds, context, identity, and environments; set dev as default environment and override paths under builds.
- B. Use bundle, artifacts, workspace, run_as, and targets at the top level; set one target with default:true and override workspace paths or artifacts under that target.
- C. Use roots, modules, profiles, actor, and targets; where profiles contain workspace and artifacts defaults and actor sets run identity.
- D. Use project, packages, environment, identity, and stages; set dev as default stage and override workspace under environment.
정답:B
설명:
In Databricks Asset Bundles, the databricks.yml file defines all top-level configuration keys, including bundle, artifacts, workspace, run_as, and targets. The targets section defines specific deployment contexts (for example, dev, test, prod). Setting default: true for a target marks it as the default environment. Overrides for workspace paths and artifact configurations can be defined inside each target while keeping defaults at the top level.
질문 # 147
The data architect has mandated that all tables in the Lakehouse should be configured as external (also known as "unmanaged") Delta Lake tables.
Which approach will ensure that this requirement is met?
- A. When configuring an external data warehouse for all table storage, leverage Databricks for all ELT.
- B. When data is saved to a table, make sure that a full file path is specified alongside the Delta format.
- C. When the workspace is being configured, make sure that external cloud object storage has been mounted.
- D. When tables are created, make sure that the EXTERNAL keyword is used in the CREATE TABLE statement.
- E. When a database is being created, make sure that the LOCATION keyword is used.
정답:D
설명:
To create an external or unmanaged Delta Lake table, you need to use the EXTERNAL keyword in the CREATE TABLE statement. This indicates that the table is not managed by the catalog and the data files are not deleted when the table is dropped. You also need to provide a LOCATION clause to specify the path where the data files are stored.
For example:
CREATE EXTERNAL TABLE events ( date DATE, eventId STRING, eventType STRING, data STRING) USING DELTA LOCATION `/mnt/delta/events'; This creates an external Delta Lake table named events that references the data files in the
`/mnt/delta/events' path. If you drop this table, the data files will remain intact and you can recreate the table with the same statement.
질문 # 148
The data engineering team maintains the following code:
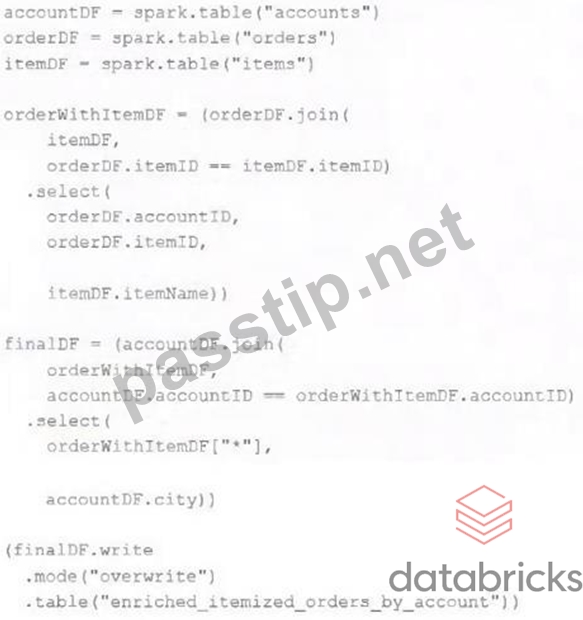
Assuming that this code produces logically correct results and the data in the source tables has been de-duplicated and validated, which statement describes what will occur when this code is executed?
- A. An incremental job will leverage information in the state store to identify unjoined rows in the source tables and write these rows to the enriched_iteinized_orders_by_account table.
- B. No computation will occur until enriched_itemized_orders_by_account is queried; upon query materialization, results will be calculated using the current valid version of data in each of the three tables referenced in the join logic.
- C. An incremental job will detect if new rows have been written to any of the source tables; if new rows are detected, all results will be recalculated and used to overwrite the enriched_itemized_orders_by_account table.
- D. The enriched_itemized_orders_by_account table will be overwritten using the current valid version of data in each of the three tables referenced in the join logic.
- E. A batch job will update the enriched_itemized_orders_by_account table, replacing only those rows that have different values than the current version of the table, using accountID as the primary key.
정답:D
설명:
This is the correct answer because it describes what will occur when this code is executed. The code uses three Delta Lake tables as input sources: accounts, orders, and order_items. These tables are joined together using SQL queries to create a view called new_enriched_itemized_orders_by_account, which contains information about each order item and its associated account details. Then, the code uses write.format("delta").mode("overwrite") to overwrite a target table called enriched_itemized_orders_by_account using the data from the view. This means that every time this code is executed, it will replace all existing data in the target table with new data based on the current valid version of data in each of the three input tables.
질문 # 149
......
Databricks Databricks-Certified-Data-Engineer-Professional 덤프결제에 관하여 불안정하게 생각되신다면 paypal에 대해 알아보시면 믿음이 생길것입니다. 더욱 안전한 지불을 위해 저희 사이트의 모든 덤프는paypal을 통해 지불을 완성하게 되어있습니다. Paypal을 거쳐서 지불하면 저희측에서Databricks Databricks-Certified-Data-Engineer-Professional덤프를 보내드리지 않을시 paypal에 환불신청하실수 있습니다.
Databricks-Certified-Data-Engineer-Professional인기덤프공부: https://www.passtip.net/Databricks-Certified-Data-Engineer-Professional-pass-exam.html
- 시험패스 가능한 Databricks-Certified-Data-Engineer-Professional시험패스 가능한 인증덤프자료 최신버전 문제 🦄 “ www.koreadumps.com ”웹사이트를 열고“ Databricks-Certified-Data-Engineer-Professional ”를 검색하여 무료 다운로드Databricks-Certified-Data-Engineer-Professional적중율 높은 덤프공부
- Databricks-Certified-Data-Engineer-Professional시험문제모음 🤾 Databricks-Certified-Data-Engineer-Professional인기덤프공부 💇 Databricks-Certified-Data-Engineer-Professional최신버전 덤프공부자료 🏔 무료 다운로드를 위해《 Databricks-Certified-Data-Engineer-Professional 》를 검색하려면➥ www.itdumpskr.com 🡄을(를) 입력하십시오Databricks-Certified-Data-Engineer-Professional최신 시험 공부자료
- 100% 합격보장 가능한 Databricks-Certified-Data-Engineer-Professional시험패스 가능한 인증덤프자료 인증공부자료 🍠 무료 다운로드를 위해 지금➤ www.koreadumps.com ⮘에서✔ Databricks-Certified-Data-Engineer-Professional ️✔️검색Databricks-Certified-Data-Engineer-Professional질문과 답
- Databricks-Certified-Data-Engineer-Professional시험대비 공부문제 🌼 Databricks-Certified-Data-Engineer-Professional인기자격증 시험대비 공부자료 🍡 Databricks-Certified-Data-Engineer-Professional시험문제모음 🩱 무료 다운로드를 위해⇛ Databricks-Certified-Data-Engineer-Professional ⇚를 검색하려면▛ www.itdumpskr.com ▟을(를) 입력하십시오Databricks-Certified-Data-Engineer-Professional시험패스 가능한 공부
- Databricks-Certified-Data-Engineer-Professional덤프최신버전 🍤 Databricks-Certified-Data-Engineer-Professional적중율 높은 인증덤프자료 🗳 Databricks-Certified-Data-Engineer-Professional최고덤프 🐞 ☀ www.dumptop.com ️☀️에서▶ Databricks-Certified-Data-Engineer-Professional ◀를 검색하고 무료로 다운로드하세요Databricks-Certified-Data-Engineer-Professional높은 통과율 인기 덤프자료
- 100% 합격보장 가능한 Databricks-Certified-Data-Engineer-Professional시험패스 가능한 인증덤프자료 인증공부자료 🎵 ▛ www.itdumpskr.com ▟에서 검색만 하면▶ Databricks-Certified-Data-Engineer-Professional ◀를 무료로 다운로드할 수 있습니다Databricks-Certified-Data-Engineer-Professional인기덤프공부
- Databricks-Certified-Data-Engineer-Professional시험패스 가능한 인증공부자료 💞 Databricks-Certified-Data-Engineer-Professional최신버전 덤프공부자료 🧃 Databricks-Certified-Data-Engineer-Professional높은 통과율 덤프데모문제 🐋 ⏩ www.pass4test.net ⏪에서 검색만 하면《 Databricks-Certified-Data-Engineer-Professional 》를 무료로 다운로드할 수 있습니다Databricks-Certified-Data-Engineer-Professional적중율 높은 덤프공부
- Databricks-Certified-Data-Engineer-Professional시험패스 가능한 인증덤프자료 퍼펙트한 덤프로 시험패스하여 자격증을 취득하기 🌀 시험 자료를 무료로 다운로드하려면➥ www.itdumpskr.com 🡄을 통해➠ Databricks-Certified-Data-Engineer-Professional 🠰를 검색하십시오Databricks-Certified-Data-Engineer-Professional질문과 답
- 100% 합격보장 가능한 Databricks-Certified-Data-Engineer-Professional시험패스 가능한 인증덤프자료 인증공부자료 ⛳ 시험 자료를 무료로 다운로드하려면➡ kr.fast2test.com ️⬅️을 통해《 Databricks-Certified-Data-Engineer-Professional 》를 검색하십시오Databricks-Certified-Data-Engineer-Professional퍼펙트 공부문제
- Databricks-Certified-Data-Engineer-Professional인기자격증 시험대비 공부자료 👩 Databricks-Certified-Data-Engineer-Professional높은 통과율 인기 덤프자료 🚓 Databricks-Certified-Data-Engineer-Professional시험대비 공부문제 💆 무료로 다운로드하려면⮆ www.itdumpskr.com ⮄로 이동하여▛ Databricks-Certified-Data-Engineer-Professional ▟를 검색하십시오Databricks-Certified-Data-Engineer-Professional높은 통과율 덤프데모문제
- Databricks-Certified-Data-Engineer-Professional시험패스 가능한 인증덤프자료 인증시험정보 🦉 무료 다운로드를 위해 지금[ www.exampassdump.com ]에서➡ Databricks-Certified-Data-Engineer-Professional ️⬅️검색Databricks-Certified-Data-Engineer-Professional퍼펙트 공부문제
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
그 외, PassTIP Databricks-Certified-Data-Engineer-Professional 시험 문제집 일부가 지금은 무료입니다: https://drive.google.com/open?id=1epOk3j4ASxcQ1pyn20FX8OsX28DFirCd