除了Microsoft 的DP-750考試,最近最有人氣的還有Cisco,IBM,HP等的各類考試。但是如果你想取得DP-750的認證資格,Testpdf的DP-750考古題可以實現你的願望。不要因為對考試沒有信心就放棄考試,因為你完全可以通過Testpdf的考試資料來達成自己的目標。取得了DP-750的認證資格以後,你還可以參加其他的IT認證考試。只要有Testpdf的考古題在手,什么考试都不是问题。
| Section | Weight | Objectives |
|---|---|---|
| Configure and manage Azure Databricks environments | 15-20% | - Workspace and compute configuration
|
| Secure and govern data using Unity Catalog | 15-20% | - Data governance fundamentals
|
| Deploy and manage data pipelines and workloads | 30-35% | - Lakehouse architecture operations
|
| Prepare and process data | 30-35% | - Data transformation and modeling
|
如果你想通過Microsoft的DP-750考試認證使自己在當今競爭激烈的IT行業中地位更牢固,在IT行業中的的專業技能更強大,你的需要很強的專業知識和日積月累的努力,而且通過Microsoft的DP-750考試認證也不是簡單的,或許通過Microsoft的DP-750考試認證是你向IT行業推廣自己的時候,但是不一定需要花費大量的時間和精力來學習專業知識,你可以選擇我們Testpdf Microsoft的DP-750考試培訓資料,專門是針對IT相關考試認證研究出來的培訓產品。有了它你就可以毫不費力的通過了這麼困難的Microsoft的DP-750考試認證。
問題 #49
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders.
You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df.filter(df.order_amount.isNotNull())
Does this meet the goal?
答案:A
解題說明:
The correct answer is A - Yes.
df.filter(df.order_amount.isNotNull()) is the correct PySpark pattern for excluding null rows. The isNotNull() method is a Column method that returns True for every row where order_amount has a value and False for rows where it is null. Spark's filter keeps only the rows where the condition evaluates to True, producing a DataFrame with all null order_amount rows removed.
This works correctly because isNotNull() is explicitly null-aware - unlike the != None comparison in Q52, it doesn't rely on Python equality semantics. Under the hood it maps to the SQL expression order_amount IS NOT NULL, which is unambiguous in both SQL and Spark.
Both df.filter(df.order_amount.isNotNull()) and df.dropna(subset=['order_amount']) produce identical results.
The choice between them is stylistic - isNotNull() reads more explicitly as a filter condition, while dropna is more compact when handling multiple columns.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
問題 #50
You have an Azure Databricks workspace named Workspace1 that contains a lakehouse and is enabled for Unity Catalog.
You have a connection to a Microsoft SQL Server database named DB1.
You need to expose the schemas and tables of DB1 to meet the following requirements:
* The schemas and tables can be queried in Databricks.
* The schemas and tables appear alongside other Unity Catalog objects.
* The data is NOT copied into Databricks-managed storage.
Solution: You create a foreign catalog in Catalog Explorer.
Does this meet the goal?
答案:A
解題說明:
The correct answer is A - Yes.
A foreign catalog created through Lakehouse Federation in Catalog Explorer is the correct solution for all three requirements. Here's why it works:
The schemas and tables of DB1 can be queried in Databricks - Lakehouse Federation pushes the query down to the external SQL Server and returns results, so analysts write normal SQL in Databricks.
They appear alongside other Unity Catalog objects - the foreign catalog sits in the same three-tier hierarchy as native catalogs, schemas, and tables, visible in Catalog Explorer alongside all other Unity Catalog assets.
The data is NOT copied into Databricks-managed storage - foreign catalogs query data in place at the source; nothing is replicated or materialised in Databricks storage.
This is exactly the scenario Lakehouse Federation was built for.
Reference: https://learn.microsoft.com/en-us/azure/databricks/query-federation/lakehouse-federation
問題 #51
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job! runs every hour.
Occasionally, the job run takes longer than one hour to complete. Overlapping runs must be prevented to avoid data corruption.
You need to configure the job scheduling behavior.
What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
答案:
解題說明:
Explanation:
Two settings address the overlapping-run problem:
Concurrent Runs policy set to 'Skip' (or 'Allow only one concurrent run'). When a new scheduled trigger fires while the previous run is still in progress, the new run is skipped rather than starting alongside the ongoing one. This prevents two runs from writing to the same tables at the same time - which is the data corruption risk the question highlights.
Cron-based schedule for the hourly trigger. A cron expression defines the regular execution cadence.
Combined with the concurrency setting, the job runs hourly but never overlaps.
An alternative to 'Skip' is 'Wait' (queue the new run), which ensures every scheduled run eventually executes
- but for this scenario where overlapping is the primary concern, skipping the missed run is typically preferable to building up a queue of back-to-back executions.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/configure-jobs#concurrent-runs
問題 #52
You have an Azure Databricks workspace that uses Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that ingests data into a managed Delta table named Table1. Table1 is used for analytics.
New columns are added to the source data, causing pipeline failures during writes to Table1.
You need to prevent the pipeline failures. The solution must ensure that schema changes are detected and handled.
What should you do?
答案:C
解題說明:
You should enable schema evolution to resolve this problem. In Lakeflow Spark Declarative Pipelines (SDP)-formerly known as Delta Live Tables (DLT)-schema evolution automatically updates the schema of your managed Delta tables when new columns are detected in the source data.
Prevents Pipeline Failures: By default, Delta Lake applies strict schema enforcement to prevent bad or mismatched data from corrupting your tables. When the source data layout changes (e.g., column creep), the pipeline will throw a runtime error and fail the write operation.
Automates Ingestion Flexibility: Activating schema evolution allows Delta Lake to automatically adapt by adding the new columns to the target managed table layout dynamically, eliminating manual intervention or explicit ALTER TABLE operations.
Reference:
https://learn.microsoft.com/en-us/azure/databricks/ldp/unity-catalog
問題 #53
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to ingest data from the CSV files stored in an external Azure Data Lake Storage Gen2 container into a managed Delta table. The solution must meet the following requirements:
* Load data incrementally as new files arrive.
* Minimize custom code and operational effort.
How should you complete the SQL statement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
答案:
解題說明: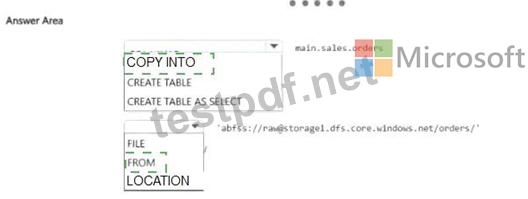
Explanation:
COPY INTO loads files from a cloud-storage location into an existing Delta table. It is retriable and idempotent: Azure Databricks records which source files have already been processed and skips them during subsequent executions. Consequently, the statement can be run repeatedly to load newly arrived CSV files without reloading previously processed files. This provides incremental ingestion with minimal custom tracking code or operational logic. Microsoft Learn The FROM clause specifies the source ADLS Gen2 path containing the CSV files. CREATE TABLE defines a new table but does not incrementally load arriving files into the existing main.sales.orders table. CREATE TABLE AS SELECT creates and populates a new table from a query result and is not the correct recurring file-ingestion operation. FILE and LOCATION are not valid replacements for FROM in the displayed COPY INTO syntax.
Therefore, the statement must begin with COPY INTO and use FROM before the source storage path.
問題 #54
......
如果你還在為 Microsoft的DP-750考試認證而感到煩惱,那麼你就選擇Testpdf培訓資料網站吧, Testpdf Microsoft的DP-750考試培訓資料無庸置疑是最好的培訓資料,選擇它是你最好的選擇,它可以保證你百分百通過考試獲得認證。來吧,你將是未來最棒的IT專家。
DP-750題庫資訊: https://www.testpdf.net/DP-750.html