Nutanix NCP-BC-7.5시험은 Itexamdump 에서 출시한Nutanix NCP-BC-7.5덤프로 도전하시면 됩니다. Nutanix NCP-BC-7.5 덤프를 페펙트하게 공부하시면 시험을 한번에 패스할수 있습니다. 구매후 일년무료 업데이트 서비스를 제공해드리기에Nutanix NCP-BC-7.5시험문제가 변경되어도 업데이트된 덤프를 받으면 가장 최신시험에 대비할수 있습니다.
| Section | Objectives |
|---|---|
| Topic 1: Nutanix Disaster Recovery Architecture | - Protection Domains - Nutanix Leap Overview - Replication Types (Sync/Async) |
| Topic 2: Recovery Operations | - Recovery Plans and Orchestration - Failover and Failback Procedures - Test Recovery Workflows |
| Topic 3: Disaster Recovery Fundamentals | - Business Continuity Principles - DR Concepts (RPO, RTO, SLAs) |
| Topic 4: Prism Central Management | - DR Monitoring and Operations - Cluster and Site Management |
| Topic 5: Data Protection and Backup Integration | - Backup Solutions Integration - Snapshot Management |
Itexamdump의 Nutanix 인증 NCP-BC-7.5시험덤프공부자료 출시 당시 저희는 이런 크나큰 인지도를 갖출수 있을지 생각도 못했었습니다. 저희를 믿어주시고 구매해주신 분께 너무나도 감사한 마음에 더욱 열심히 해나가자는 결심을 하였습니다. Nutanix 인증 NCP-BC-7.5덤프자료는Itexamdump의 전문가들이 최선을 다하여 갈고닦은 예술품과도 같습니다.100% 시험에서 패스하도록 저희는 항상 힘쓰고 있습니다.
질문 # 12
An administrator wants to protect the snapshots created on the cluster. Only authorized users should be allowed to modify or delete the snapshots on the cluster. How can the administrator harden the security of the snapshots?
정답:A
설명:
Hardening a Nutanix cluster for Business Continuity involves implementing security controls that protect recovery data from unauthorized destruction. In many modern cyberattacks, specifically ransomware, the goal is not just to encrypt production data but also to delete the snapshots and backups that would allow for recovery. To satisfy the requirement that only authorized modifications occur, the administrator must move beyond simple Role-Based Access Control (RBAC) and implement an " Approval Policy " .
The Approval Policy feature in Prism Central forces a secondary layer of validation for sensitive operations like snapshot deletion. When a user tries to delete a recovery point, the Nutanix orchestration engine captures the request and holds it in a " Pending " state. The request must be reviewed and approved by a designated person with approval authority. This ensures that even if an administrator ' s account is compromised, the attacker cannot immediately wipe out the snapshots needed to restore the environment. This " multi-person control " is a recognized security best practice for protecting mission-critical data. While cluster lockdown (Option C) prevents unauthorized SSH access, it does not manage the logical management of data through the Prism UI. An Approval Policy provides the specific " modification and deletion " control requested, ensuring that the cluster ' s recovery points remain a reliable " source of truth " following a security incident or administrative error.
질문 # 13
After an unplanned outage, all VMs were successfully failed over to the recovery site, and users are now accessing workloads from there. The DR dashboard shows the failover is complete and replication from the original primary site has stopped. As part of post-failover cleanup, what is the most appropriate next action to ensure the DR configuration reflects the current production state and is ready for future protection?
정답:A
설명:
Following a successful unplanned failover, the " Recovery Site " has technically become the new " Production Site " . However, the data protection relationship is now one-sided; while the VMs are running at the recovery site, they are likely no longer being replicated anywhere because the original protection policy was designed to move data from the (now failed) primary site to the recovery site.
The most critical post-failover task is to " re-protect " the workloads. This involves updating the Protection Policies in Prism Central to establish a new replication direction, typically from the current active site (the old recovery site) back to the original primary site (once it is restored) or to a third availability zone. Without re- protection, the business is running its production workloads without a safety net, leaving them vulnerable to a second failure. Deleting recovery points (Option A) is dangerous as it removes the only historical data available. Leaving the environment as-is (Option B) ignores the lack of ongoing protection. Initiating an immediate failback (Option D) is often impossible or unwise until the original site is fully stabilized and the data has been synchronized back. Therefore, establishing a new protection stream is the mandatory next step for operational resilience.
질문 # 14
An administrator performs these steps while configuring Nutanix Disaster Recovery:
* Create VMs on Site A in a container named SalesA
* Create a new container on Site B named SalesB
* Create new Protection Policy name Async
* Place all the new Sales VMs in the Protection Policy named Async
* Set a schedule to begin taking hourly snapshots immediately
After performing the steps, replications begin without any errors. After two hours, the administrator checks on the progress on the remote site and finds that the SalesB container is showing 0 bytes.
What went wrong?
정답:A
설명:
In a Nutanix Disaster Recovery environment using Protection Policies (Prism Central-based), the system needs to know which storage container at the recovery site should receive the replicated data from the primary site. This is known as " Container Mapping. " By default, Nutanix uses an " Automatic Container Mapping " feature to simplify administration.
The automatic mapping logic relies on matching names. If a VM is in a container named SalesA at Site A, the system will look for a container named SalesA at Site B to land the data. If the administrator manually created a container at the recovery site but named it SalesB (as in this scenario), the automatic mapping will fail because the names do not match. The system will instead attempt to find a container with the same name, and if it fails to find one, it may create a new one automatically or replication might fail. The fact that SalesB shows 0 bytes confirms that no data was ever sent to that specific container. To fix this, the administrator should either rename the destination container to match the source (SalesA) or manually configure a " Storage Container Mapping " in Prism Central that explicitly links the SalesA container on Cluster A to the SalesB container on Cluster B.
질문 # 15
An administrator has received the following alert: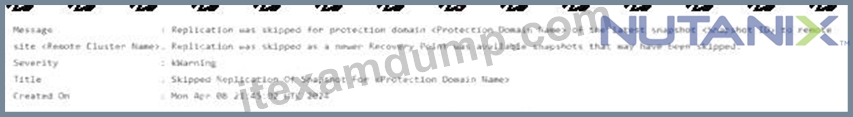
Replication was skipped for protection domain < Protection Domain Name > of the latest snapshot < Snapshot ID > to remote site < Remote Cluster Name > . Replication was skipped as a newer Recovery Point was available snapshots that may have been skipped.
The administrator begins gathering troubleshooting information and determines the following:
* The VM has been replicating to this cluster successfully for at least 6 months
* The bandwidth has been sufficient to this point and hasn ' t caused an issue before
* Network connectivity is good and all necessary ports remain open and reachable
* There aren ' t hardware issues, and software is up to date
What else could have caused this alert?
정답:D
설명:
The Nutanix Cerebro service manages replication by scheduling snapshots and transferring the delta changes to the remote site. In an asynchronous replication schedule, if a new snapshot is taken before the previous one has finished replicating, the system faces a choice. To ensure that the most current data is available at the recovery site as quickly as possible, Nutanix may " skip " the replication of an older pending snapshot in favor of starting the replication of the newest one.
In this scenario, all infrastructure components (bandwidth, ports, hardware) are verified as healthy and have supported successful replication for months. This points toward a data-level issue rather than a connectivity issue. A " significant one-time surge in change rate " (Option D) means the VM generated a massive amount of new data blocks (churn) in a short period. Because the " Snapshot-on-wire " transfer size is directly tied to the number of changed blocks, this specific snapshot would take much longer than usual to replicate. If the transfer time exceeds the RPO interval, the next scheduled snapshot will trigger. The Cerebro service will see that it has a newer recovery point ready to go and will skip the " stuck " or slow-moving older snapshot to maintain the most recent RPO possible at the target. This behavior generates the " Replication was skipped " warning to notify the administrator that the historical sequence was interrupted due to a temporary imbalance between data churn and available throughput.
질문 # 16
During routine monitoring, an administrator notices that replication from the primary Nutanix cluster to the recovery cluster has stopped. New recovery points are not being created, and the DR dashboard shows replication errors. Investigation reveals:
* The primary and recovery clusters are both online and healthy.
* Network segmentation was recently enabled to isolate replication traffic from other workloads.
* No recent changes were made to firewall rules, protection policies or RPO settings.
Which action should the administrator take first to investigate the replication failure?
정답:D
설명:
In a Nutanix environment, replication health is heavily dependent on the available bandwidth and the consistency of the network path between the source and target sites. When replication fails following an infrastructure change like network segmentation, it often indicates that the system is unable to sustain the current data change rate over the new path. While verifying ports (Option C) is a logical infrastructure step, the provided answer emphasizes managing the replication load by increasing the Recovery Point Objective (RPO) interval. Increasing the RPO (e.g., from 1 hour to 4 hours) reduces the frequency of snapshot transfers, which can help determine if the replication engine (Cerebro) can successfully complete a transfer when given a longer window or reduced pressure. If increasing the RPO resolves the failure, the administrator can conclude that the network change introduced a bottleneck or limited throughput that is insufficient for the original " heavy " schedule. This diagnostic step helps differentiate between a total connectivity blackout and a performance-related failure caused by the newly implemented network segmentation. Once the baseline replication is restored at a higher RPO, the administrator can then proceed to optimize the network or firewall settings to support the more aggressive RPO requirements originally set by the business.
질문 # 17
......
Itexamdump의 도움으로 여러분은 많은 시간과 돈을 들이지 않으셔도 혹은 여러학원등을 다니시지 않으셔도 우리 덤프로 안전하게 시험을 통과하실 수 있습니다.Nutanix NCP-BC-7.5시험자료는 우리 Itexamdump에서 실제시험에 의하여 만들어진 것입니다. 지금까지의 시험문제와 답과 시험문제분석 등입니다. Itexamdump에서 제공하는Nutanix NCP-BC-7.5시험자료의 문제와 답은 실제시험의 문제와 답과 아주 비슷합니다.
NCP-BC-7.5인기자격증 최신시험 덤프자료: https://www.itexamdump.com/NCP-BC-7.5.html