2026 Latest VCEEngine Professional-Machine-Learning-Engineer PDF Dumps and Professional-Machine-Learning-Engineer Exam Engine Free Share: https://drive.google.com/open?id=1OH4mZsr5c_lW0PQRcn59gTsiw050p9Lk
To pass the Google Professional-Machine-Learning-Engineer exam on the first try, candidates need Google Professional Machine Learning Engineer updated practice material. Preparing with real Professional-Machine-Learning-Engineer exam questions is one of the finest strategies for cracking the exam in one go. Students who study with Professional-Machine-Learning-Engineer Real Questions are more prepared for the exam, increasing their chances of succeeding. The Professional-Machine-Learning-Engineer exam preparation calls for a strong preparation and precise Google Professional-Machine-Learning-Engineer practice material.
| Certification Vendor: | Google Cloud |
|---|---|
| Exam Name: | Google Cloud Certified - Professional Machine Learning Engineer |
| Exam Number: | Professional-Machine-Learning-Engineer |
| Available Languages: | Japanese, English |
| Certificate Validity Period: | 2 years |
| Exam Format: | Multiple select, Multiple choice |
| Real Exam Qty: | 50-60 |
| Related Certifications: | Google Cloud Certified - Professional Data Engineer |
| Passing Score: | Not publicly disclosed (Pass/Fail) |
| Exam Price: | $200 USD |
| Exam Duration: | 120 minutes |
| Sample Questions: | Google Professional-Machine-Learning-Engineer Sample Questions |
| Exam Way: | Online (proctored) or Test center (Kryterion) |
| Pre Condition: | Recommended 3+ years of industry experience with ML models and 1+ year of experience using Google Cloud. |
| Official Syllabus URL: | https://cloud.google.com/learn/certification/machine-learning-engineer |
>> Printable Google Professional-Machine-Learning-Engineer PDF <<
In order to show you how efficient our Professional-Machine-Learning-Engineer exam dump is, we allow you to download a demo version for free! You will have a chance to peak into the program and then make your final purchase decision. We are absolutely sure that once you see what’s inside, you will buy it immediately without any hesitation! Professional-Machine-Learning-Engineer Exam Dump also provide customer service, in case you have any inquiry or question, our professional Customer Support will be available for you 24/7. 365 days a Year.
The Google Professional-Machine-Learning-Engineer exam covers a wide range of topics, including data preparation, model development, model deployment, and monitoring and maintenance of machine learning solutions. It is designed to test the knowledge and skills required to design, implement, and maintain machine learning solutions using Google Cloud. Professional-Machine-Learning-Engineer Exam is intended for professionals who have a strong background in machine learning, data science, or related fields, and who are looking to demonstrate their expertise to potential employers.
NEW QUESTION # 110
You trained a text classification model. You have the following SignatureDefs:
What is the correct way to write the predict request?
Answer: D
Explanation:
A predict request is a way to send data to a trained model and get predictions in return. A predict request can be written in different formats, such as JSON, protobuf, or gRPC, depending on the service and the platform that are used to host and serve the model. A predict request usually contains the following information:
* The signature name: This is the name of the signature that defines the inputs and outputs of the model.
A signature is a way to specify the expected format, type, and shape of the data that the model can accept and produce. A signature can be specified when exporting or saving the model, or it can be automatically inferred by the service or the platform. A model can have multiple signatures, but only one can be used for each predict request.
* The instances: This is the data that is sent to the model for prediction. The instances can be a single instance or a batch of instances, depending on the size and shape of the data. The instances should match the input specification of the signature, such as the number, name, and type of the input tensors.
For the use case of training a text classification model, the correct way to write the predict request is D. data = json.dumps({"signature_name": "serving_default", "instances": [['a', 'b'], ['c', 'd'] , ['e', 'f']]}) This option involves writing the predict request in JSON format, which is a common and convenient format for sending and receiving data over the web. JSON stands for JavaScript Object Notation, and it is a way to represent data as a collection of name-value pairs or an ordered list of values. JSON can be easily converted to and from Python objects using the json module.
This option also involves using the signature name "serving_default", which is the default signature name that is assigned to the model when it is saved or exported without specifying a custom signature name. The serving_default signature defines the input and output tensors of the model based on the SignatureDef that is shown in the image. According to the SignatureDef, the model expects an input tensor called "text" that has a shape of (-1, 2) and a type of DT_STRING, and produces an output tensor called "softmax" that has a shape of (-1, 2) and a type of DT_FLOAT. The -1 in the shape indicates that the dimension can vary depending on the number of instances, and the 2 indicates that the dimension is fixed at 2. The DT_STRING and DT_FLOAT indicate that the data type is string and float, respectively.
This option also involves sending a batch of three instances to the model for prediction. Each instance is a list of two strings, such as ['a', 'b'], ['c', 'd'] , or ['e', 'f']. These instances match the input specification of the signature, as they have a shape of (3, 2) and a type of string. The model will process these instances and produce a batch of three predictions, each with a softmax output that has a shape of (1, 2) and a type of float.
The softmax output is a probability distribution over the two possible classes that the model can predict, such as positive or negative sentiment.
Therefore, writing the predict request as data = json.dumps({"signature_name": "serving_default",
"instances": [['a', 'b'], ['c', 'd'] , ['e', 'f']]}) is the correct and valid way to send data to the text classification model and get predictions in return.
References:
[json - JSON encoder and decoder]
NEW QUESTION # 111
You trained a text classification model. You have the following SignatureDefs: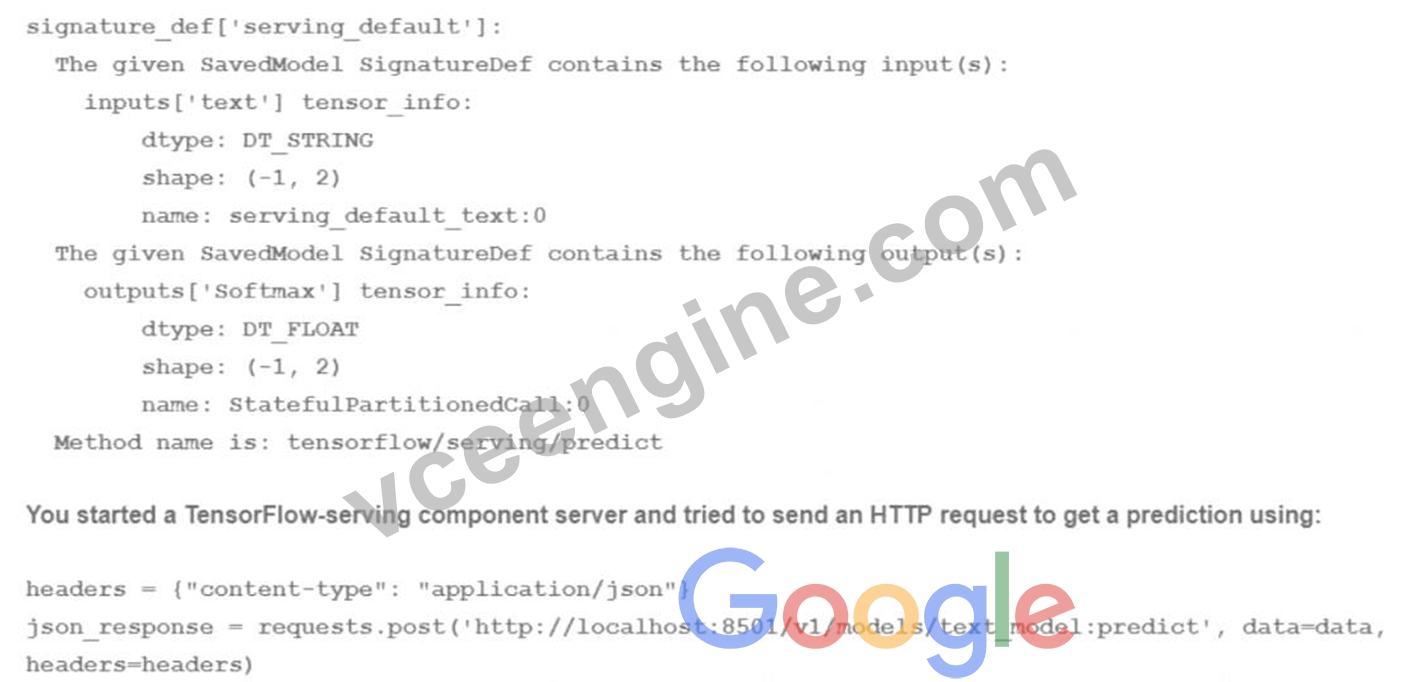
What is the correct way to write the predict request?
Answer: B
Explanation:
A predict request is a way to send data to a trained model and get predictions in return. A predict request can be written in different formats, such as JSON, protobuf, or gRPC, depending on the service and the platform that are used to host and serve the model. A predict request usually contains the following information:
* The signature name: This is the name of the signature that defines the inputs and outputs of the model.
A signature is a way to specify the expected format, type, and shape of the data that the model can accept and produce. A signature can be specified when exporting or saving the model, or it can be automatically inferred by the service or the platform. A model can have multiple signatures, but only one can be used for each predict request.
* The instances: This is the data that is sent to the model for prediction. The instances can be a single instance or a batch of instances, depending on the size and shape of the data. The instances should match the input specification of the signature, such as the number, name, and type of the input tensors.
For the use case of training a text classification model, the correct way to write the predict request is D. data = json.dumps({"signature_name": "serving_default", "instances": [['a', 'b'], ['c', 'd'], ['e', 'f']]}) This option involves writing the predict request in JSON format, which is a common and convenient format for sending and receiving data over the web. JSON stands for JavaScript Object Notation, and it is a way to represent data as a collection of name-value pairs or an ordered list of values. JSON can be easily converted to and from Python objects using the json module.
This option also involves using the signature name "serving_default", which is the default signature name that is assigned to the model when it is saved or exported without specifying a custom signature name. The serving_default signature defines the input and output tensors of the model based on the SignatureDef that is shown in the image. According to the SignatureDef, the model expects an input tensor called "text" that has a shape of (-1, 2) and a type of DT_STRING, and produces an output tensor called "softmax" that has a shape of (-1, 2) and a type of DT_FLOAT. The -1 in the shape indicates that the dimension can vary depending on the number of instances, and the 2 indicates that the dimension is fixed at 2. The DT_STRING and DT_FLOAT indicate that the data type is string and float, respectively.
This option also involves sending a batch of three instances to the model for prediction. Each instance is a list of two strings, such as ['a', 'b'], ['c', 'd'], or ['e', 'f']. These instances match the input specification of the signature, as they have a shape of (3, 2) and a type of string. The model will process these instances and produce a batch of three predictions, each with a softmax output that has a shape of (1, 2) and a type of float.
The softmax output is a probability distribution over the two possible classes that the model can predict, such as positive or negative sentiment.
Therefore, writing the predict request as data = json.dumps({"signature_name": "serving_default",
"instances": [['a', 'b'], ['c', 'd'], ['e', 'f']]}) is the correct and valid way to send data to the text classification model and get predictions in return.
References:
* [json - JSON encoder and decoder]
NEW QUESTION # 112
You are going to train a DNN regression model with Keras APIs using this code:
How many trainable weights does your model have? (The arithmetic below is correct.)
Answer: A
Explanation:
The number of trainable weights in a DNN regression model with Keras APIs can be calculated by multiplying the number of input units by the number of output units for each layer, and adding the number of bias units for each layer. The bias units are usually equal to the number of output units, except for the last layer, which does not have bias units if the activation function is softmax1. In this code, the model has three layers: a dense layer with 256 units and relu activation, a dropout layer with 0.25 rate, and a dense layer with
2 units and softmax activation. The input shape is 500. Therefore, the number of trainable weights is:
* For the first layer: 500 input units * 256 output units + 256 bias units = 128256
* For the second layer: The dropout layer does not have any trainable weights, as it only randomly sets some of the input units to zero to prevent overfitting2.
* For the third layer: 256 input units * 2 output units + 0 bias units = 512 The total number of trainable weights is 128256 + 512 = 161024. Therefore, the correct answer is B.
References:
* How to calculate the number of parameters for a Convolutional Neural Network?
* Dropout (keras.io)
NEW QUESTION # 113
You work for a retail company. You have been asked to develop a model to predict whether a customer will purchase a product on a given day. Your team has processed the company's sales data, and created a table with the following rows:
* Customer_id
* Product_id
* Date
* Days_since_last_purchase (measured in days)
* Average_purchase_frequency (measured in 1/days)
* Purchase (binary class, if customer purchased product on the Date)
You need to interpret your models results for each individual prediction. What should you do?
Answer: B
NEW QUESTION # 114
You work for a public transportation company and need to build a model to estimate delay times for multiple transportation routes. Predictions are served directly to users in an app in real time. Because different seasons and population increases impact the data relevance, you will retrain the model every month. You want to follow Google-recommended best practices. How should you configure the end-to-end architecture of the predictive model?
Answer: D
NEW QUESTION # 115
......
Customizable Professional-Machine-Learning-Engineer Exam Mode: https://www.vceengine.com/Professional-Machine-Learning-Engineer-vce-test-engine.html
What's more, part of that VCEEngine Professional-Machine-Learning-Engineer dumps now are free: https://drive.google.com/open?id=1OH4mZsr5c_lW0PQRcn59gTsiw050p9Lk