BONUS!!! Download part of CertkingdomPDF MLA-C01 dumps for free: https://drive.google.com/open?id=17ze4ybZaFm3jG-2QCv20d6VlD8fd1yxP
The web-based Amazon MLA-C01 Practice Exam is compatible with all operating systems, including Mac, Linux, iOS, Android, and Windows. It is a browser-based AWS Certified Machine Learning Engineer - Associate (MLA-C01) practice exam that works on all major browsers, including Chrome, Firefox, Safari, Internet Explorer, and Opera. This means that you won't have to worry about installing any complicated software or plug-ins.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
>> MLA-C01 Reliable Exam Answers <<
This is much alike our MLA-C01 exam with the only difference of providing services to our desktop users. It is compatible with Windows computers. Candidates find it easy to do self-assessment and they get maximum benefit by practicing AWS Certified Machine Learning Engineer - Associate (MLA-C01) test available only here. The AWS Certified Machine Learning Engineer - Associate (MLA-C01) questions provided here are compiled by over 90,000 competent professionals who handpicked all of these questions for your evaluation and concept-building.
NEW QUESTION # 79
A company wants to use large language models (LLMs) that are supported by Amazon Bedrock to develop a chat interface for the company ' s internal technical documentation. The company stores the documentation as dozens of text files that are several megabytes in total size. The company updates the text files often.
Which solution will meet these requirements MOST cost-effectively?
Answer: C
Explanation:
Option D is correct because Amazon Bedrock Knowledge Bases are designed for applications that need to answer questions using private documents without retraining or repeatedly fine-tuning a foundation model.
AWS documentation states that with Amazon Bedrock Knowledge Bases, you can build applications enriched by context retrieved from a knowledge base, and that this provides an out-of-the-box RAG solution. AWS also explicitly says that adding a knowledge base increases cost-effectiveness by removing the need to continually train your model to use your private data. That matches this use case very closely.
The question also says the documentation consists of text files that are only several megabytes total and are updated often. A retrieval-based approach is more economical and operationally simpler than creating a new model or repeatedly fine-tuning one whenever the documents change. AWS documentation for Bedrock knowledge bases describes adding data sources and running ingestion jobs to process and index the content, which is exactly the pattern needed for frequently updated internal documentation used by a chat interface.
The other options are not as cost-effective. Creating a new LLM is far beyond the need here. Guardrails help control model behavior and policy enforcement, but they do not serve as a document retrieval layer for internal documentation. Fine-tuning a model on frequently changing text files is usually more expensive and less flexible than using retrieval augmentation. For a modest-sized, frequently updated documentation corpus, the AWS-native and most cost-effective solution is to load the files into an Amazon Bedrock knowledge base and use it to provide context at inference time. Therefore, the best verified answer is D.
NEW QUESTION # 80
An ML engineer wants to deploy an Amazon SageMaker AI model for inference. The payload sizes are less than 3 MB. Processing time does not exceed 45 seconds. The traffic patterns will be irregular or unpredictable.
Which inference option will meet these requirements MOST cost-effectively?
Answer: A
Explanation:
Amazon SageMaker Serverless Inference is designed for irregular or unpredictable traffic patterns. It automatically provisions and scales compute resources based on request volume and scales down to zero when idle, making it the most cost-effective option.
Serverless inference supports payloads up to 6 MB and request durations up to 60 seconds, which comfortably meets the stated constraints. Customers are billed only for actual compute usage during inference execution, not for idle capacity.
Asynchronous inference is intended for long-running jobs (up to 1 hour) and large payloads (up to 1 GB).
Real-time inference requires always-on instances, increasing cost during idle periods. Batch transform is designed for offline processing.
Therefore, serverless inference is the optimal choice.
NEW QUESTION # 81
A company has deployed a model to predict the churn rate for its games by using Amazon SageMaker Studio.
After the model is deployed, the company must monitor the model performance for data drift and inspect the report. Select and order the correct steps from the following list to model monitor actions. Select each step one time. (Select and order THREE.) .
Check the analysis results on the SageMaker Studio console. .
Create a Shapley Additive Explanations (SHAP) baseline for the model by using Amazon SageMaker Clarify.
Schedule an hourly model explainability monitor.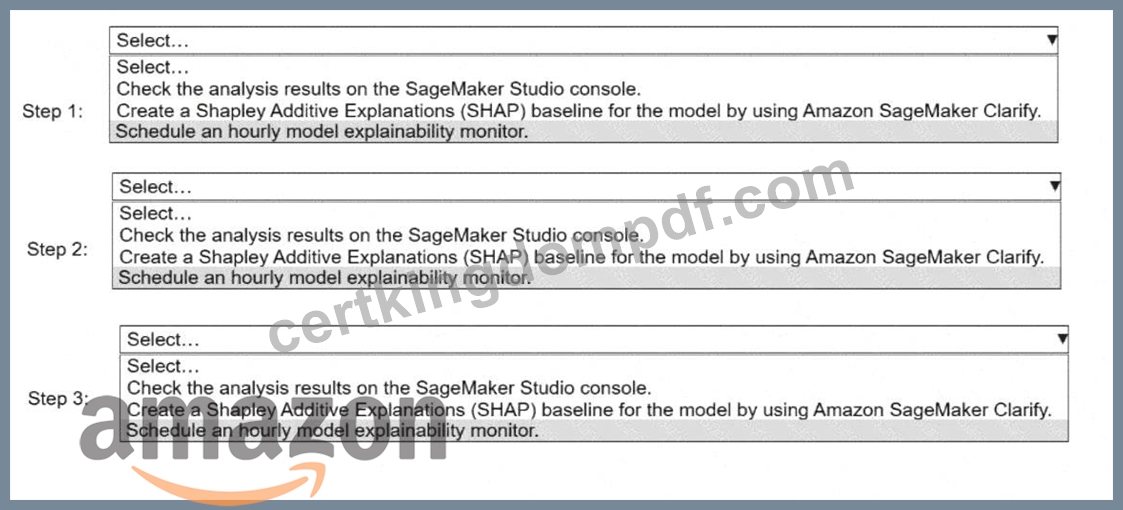
Answer:
Explanation: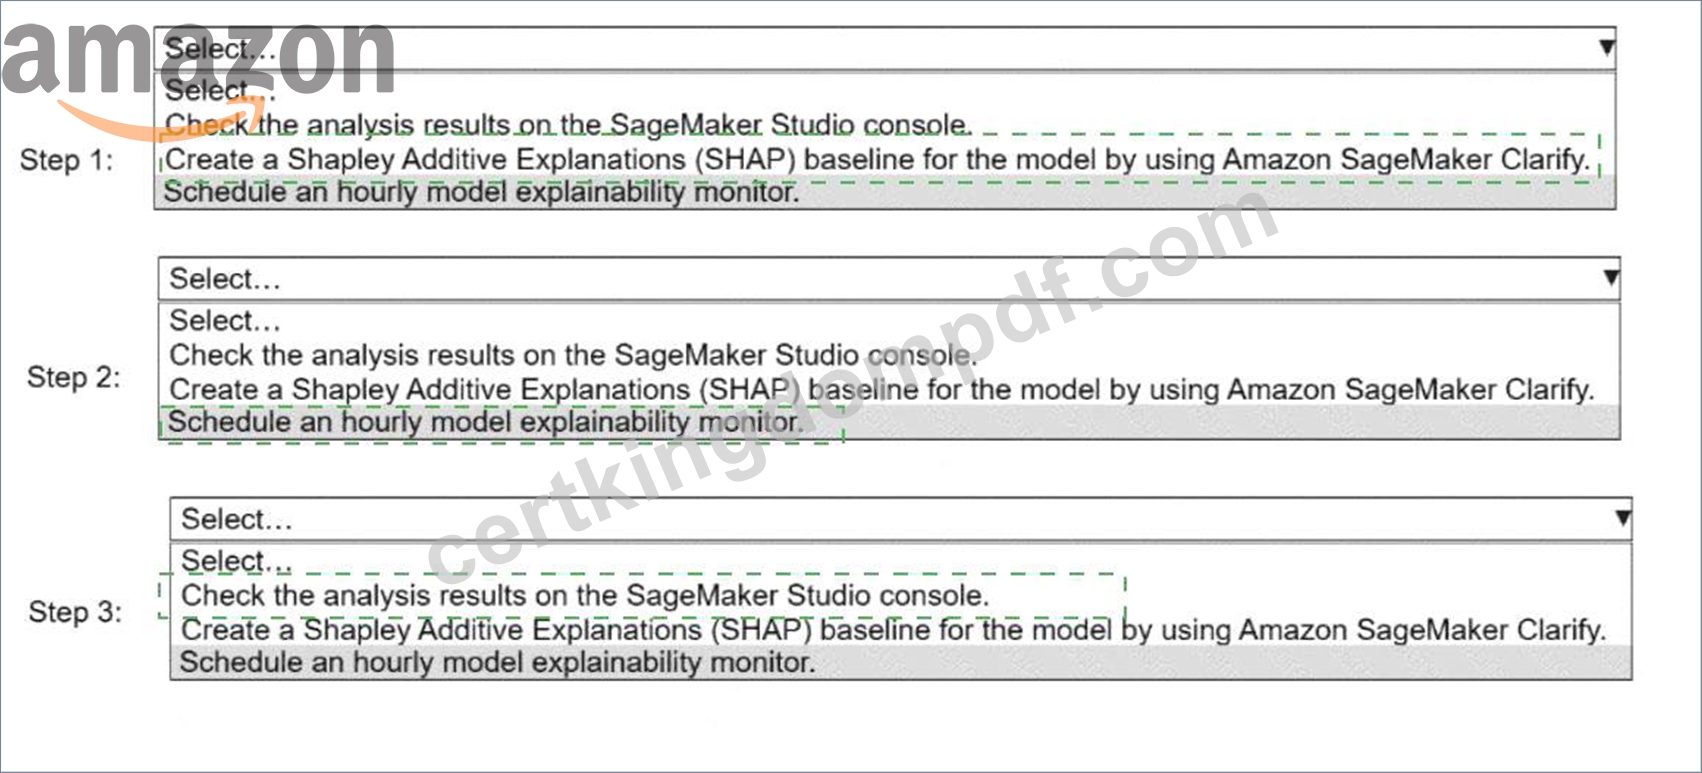
Explanation:
Step 1:
Create a Shapley Additive Explanations (SHAP) baseline for the model by using Amazon SageMaker Clarify.
Step 2:
Schedule an hourly model explainability monitor.
Step 3:
Check the analysis results on the SageMaker Studio console.
When monitoring a deployed model for data drift and explainability, AWS prescribes a specific workflow using SageMaker Clarify and SageMaker Model Monitor:
Create a SHAP baseline (Step 1)Before any monitoring can occur, SageMaker Clarify must establish a baseline explainability configuration. This baseline captures the reference SHAP values for feature importance using training or baseline data. Model Monitor uses this baseline to compare future inferences and detect drift in feature attributions.
Schedule the model explainability monitor (Step 2)After the baseline is created, an explainability monitoring schedule must be configured (hourly in this case). The monitor periodically analyzes inference data, compares it against the SHAP baseline, and generates reports that highlight drift or anomalies in feature contributions.
Inspect results in SageMaker Studio (Step 3)Once monitoring jobs run, SageMaker stores the analysis results in Amazon S3 and surfaces them in the SageMaker Studio console, where engineers can review metrics, violations, and visual reports.
This sequence is mandatory because:
A monitor cannot run without a baseline
Results cannot be reviewed until the monitor executes
NEW QUESTION # 82
A company is developing ML models by using PyTorch and TensorFlow estimators with Amazon SageMaker AI. An ML engineer configures the SageMaker AI estimator and now needs to initiate a training job that uses a training dataset.
Which SageMaker AI SDK method can initiate the training job?
Answer: D
Explanation:
In the Amazon SageMaker Python SDK, the fit() method is used to start a training job after an estimator has been configured. AWS documentation explicitly states that once an estimator (such as PyTorch or TensorFlow) is defined with parameters like instance type, framework version, and hyperparameters, the fit() method is responsible for launching the training process.
The fit() method accepts the training data location (commonly an Amazon S3 URI) and initiates the managed training job on SageMaker infrastructure. SageMaker then provisions the required compute resources, stages the data, executes the training script, and stores model artifacts in Amazon S3.
The create_model() method is used after training to create a SageMaker model object from trained artifacts.
The deploy() method deploys a trained model to an endpoint for inference. The predict() method is used only after deployment to request predictions from an endpoint.
AWS documentation clearly separates these lifecycle steps and identifies fit() as the correct method to initiate training.
Therefore, Option A is the correct and AWS-verified answer.
NEW QUESTION # 83
An ML engineer must choose the appropriate Amazon SageMaker algorithm to solve specific AI problems.
Select the correct SageMaker built-in algorithm from the following list for each use case. Each algorithm should be selected one time.
* Random Cut Forest (RCF) algorithm
* Semantic segmentation algorithm
* Sequence-to-Sequence (seq2seq) algorithm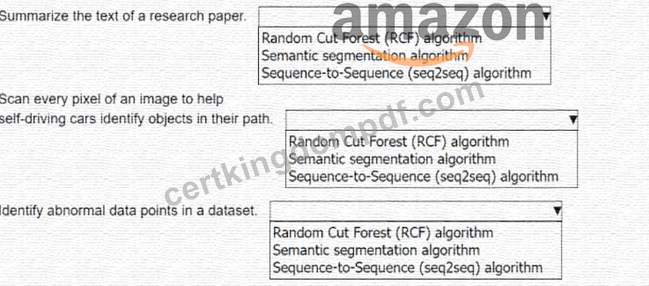
Answer:
Explanation: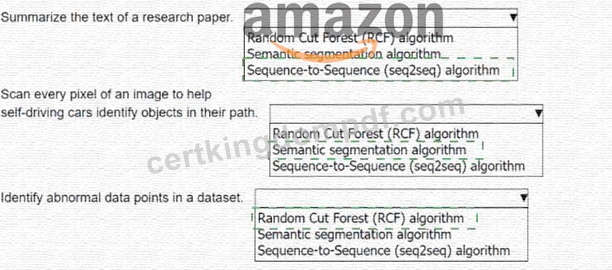
Explanation:
Use case 1:
Summarize the text of a research paper
## Sequence-to-Sequence (seq2seq) algorithm
Why:
Seq2seq models are designed for natural language generation tasks such as text summarization, translation, and paraphrasing. AWS documentation explicitly lists text summarization as a primary use case for the SageMaker seq2seq algorithm.
Use case 2:
Scan every pixel of an image to help self-driving cars identify objects in their path
## Semantic segmentation algorithm
Why:
Semantic segmentation performs pixel-level classification, assigning a class label to every pixel in an image.
This is exactly what is required for applications such as autonomous driving, road scene understanding, and object boundary detection.
Use case 3:
Identify abnormal data points in a dataset
## Random Cut Forest (RCF) algorithm
Why:
Random Cut Forest is an unsupervised anomaly detection algorithm. AWS SageMaker RCF is purpose-built to identify outliers, unusual patterns, and anomalies in numerical datasets, making it ideal for fraud detection, monitoring, and abnormal data point detection.
NEW QUESTION # 84
......
If you want to get through the MLA-C01 practice exam quickly with less time and efforts, our learning materials is definitely your best option. One or two days' preparation and remember the correct MLA-C01 test answers, getting the certification will be simple for our candidates. Free trials of MLA-C01 Exam PDF are available for everyone and great discounts are waiting for you. Join us and realize your dream.
MLA-C01 Complete Exam Dumps: https://www.certkingdompdf.com/MLA-C01-latest-certkingdom-dumps.html
BTW, DOWNLOAD part of CertkingdomPDF MLA-C01 dumps from Cloud Storage: https://drive.google.com/open?id=17ze4ybZaFm3jG-2QCv20d6VlD8fd1yxP