시험패스가능한Certified-Data-Engineer-Professional시험덤프자료덤프샘플문제다운받기

Databricks인증Certified-Data-Engineer-Professional시험을 패스하여 자격증을 취득한다면 여러분의 미래에 많은 도움이 될 것입니다.Databricks인증Certified-Data-Engineer-Professional시험자격증은 it업계에서도 아주 인지도가 높고 또한 알아주는 시험이며 자격증 하나로도 취직은 문제없다고 볼만큼 가치가 있는 자격증이죠.Databricks인증Certified-Data-Engineer-Professional시험은 여러분이 it지식테스트시험입니다.
Databricks Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Objectives |
|---|
| Topic 1: Debugging and Deploying | - Debugging and Troubleshooting
- 1. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- 2. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- 3. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
|
| Topic 2: Ensuring Data Security and Compliance | - Ensuring Compliance
- 1. Implement compliant batch and streaming pipelines that detect and mask PII
- 2. Develop data purging solutions that comply with data retention policies
- Applying Data Security Mechanisms
- 1. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- 2. Use row filters and column masks to protect sensitive table data
- 3. Use ACLs to secure workspace objects and enforce the principle of least privilege
|
| Topic 3: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
- 2. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
|
| Topic 4: Data Modeling | - Design and optimize data models
- 1. Design and implement scalable data models using Delta Lake to manage large datasets
- 2. Design dimensional models for analytical workloads with efficient querying and aggregation
- 3. Simplify data layout decisions and optimize query performance using liquid clustering
- 4. Identify the benefits of liquid clustering over partitioning and Z-Ordering
|
| Topic 5: Data Governance | - Govern enterprise data
- 1. Demonstrate understanding of the Unity Catalog permission inheritance model
- 2. Create and add descriptions and metadata to enterprise data to improve discoverability
|
| Topic 6: Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- 2. Develop User-Defined Functions using Pandas/Python UDF
- 3. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Create pipeline components using control flow operators such as if/else and foreach
- 2. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 3. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 4. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 5. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 6. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 7. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 8. Explain the advantages and disadvantages of streaming tables compared to materialized views
|
| Topic 7: Data Sharing and Federation | - Share and federate data
- 1. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 2. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
- 3. Configure Lakehouse Federation with appropriate governance across supported source systems
|
| Topic 8: Cost & Performance Optimization | - Optimize cost and performance
- 1. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 2. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 3. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 4. Apply Change Data Feed to address streaming table limitations and improve latency
- 5. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
|
| Topic 9: Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
- 2. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
|
| Topic 10: Monitoring and Alerting | - Alerting
- 1. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- 2. Use SQL Alerts to monitor data quality
- Monitoring
- 1. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 2. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 3. Use Query Profile and Spark UI to monitor workloads
- 4. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
|
>> Certified-Data-Engineer-Professional시험덤프자료 <<
최신 Certified-Data-Engineer-Professional시험덤프자료 인기 덤프자료
Itexamdump의Databricks Certified-Data-Engineer-Professional 덤프 구매 후 등록된 사용자가 구매일로부터 일년 이내에Databricks Certified-Data-Engineer-Professional시험에 실패하셨다면 Itexamdump메일에 주문번호와 불합격성적표를 보내오셔서 환불신청하실수 있습니다.구매일자 이전에 발생한 시험불합격은 환불보상의 대상이 아닙니다. 개별 인증사는 불합격성적표를 발급하지 않기에 재시험신청내역을 환불증명으로 제출하시면 됩니다.
최신 Databricks Certification Certified-Data-Engineer-Professional 무료샘플문제 (Q82-Q87):
질문 # 82
A data engineer is optimizing a managed Delta table that suffers from data skew and frequently changing query filter columns. The engineer wants to avoid costly data rewrites when query patterns evolve. The table size is under 1 TB. How should the data engineer meet this requirement?
- A. Use Hive-style partitioning, as it provides efficient data skipping and is easy to change partition columns at any time.
- B. Apply Z-ordering, since it allows flexible reorganization of data layout without rewriting existing files and adapts easily to new filter columns.
- C. Combine partitioning and Z-ordering to maximize flexibility and minimize maintenance as query patterns change.
- D. Enable liquid clustering, as it efficiently handles data skew, allows clustering keys to be changed without rewriting existing data, and adapts to evolving query patterns.
정답:D
설명:
Liquid clustering is designed for managed tables under 1TB with evolving query patterns. It efficiently addresses data skew, continuously optimizes data layout, and allows clustering keys to be changed without requiring full data rewrites, making it well suited for frequently changing filter columns while minimizing maintenance overhead.
질문 # 83
A Spark job is taking longer than expected. Using the Spark UI, a data engineer notes that the Min, Median, and Max Durations for tasks in a particular stage show the minimum and median time to complete a task as roughly the same, but the max duration for a task to be roughly 100 times as long as the minimum.
Which situation is causing increased duration of the overall job?
- A. Skew caused by more data being assigned to a subset of spark-partitions.
- B. Spill resulting from attached volume storage being too small.
- C. Task queueing resulting from improper thread pool assignment.
- D. Network latency due to some cluster nodes being in different regions from the source data
- E. Credential validation errors while pulling data from an external system.
정답:A
설명:
This is the correct answer because skew is a common situation that causes increased duration of the overall job. Skew occurs when some partitions have more data than others, resulting in uneven distribution of work among tasks and executors. Skew can be caused by various factors, such as skewed data distribution, improper partitioning strategy, or join operations with skewed keys. Skew can lead to performance issues such as long-running tasks, wasted resources, or even task failures due to memory or disk spills.
질문 # 84
The data governance team is reviewing user for deleting records for compliance with GDPR. The following logic has been implemented to propagate deleted requests from the user_lookup table to the user aggregate table.
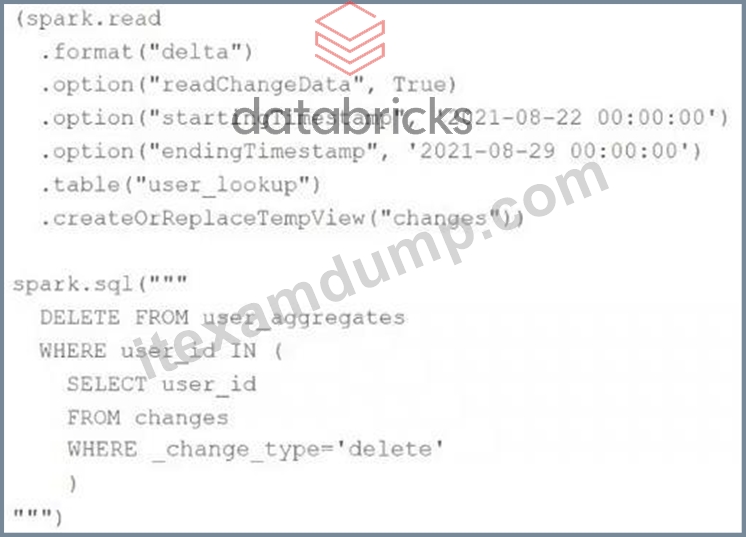
Assuming that user_id is a unique identifying key and that all users have requested deletion have been removed from the user_lookup table, which statement describes whether successfully executing the above logic guarantees that the records to be deleted from the user_aggregates table are no longer accessible and why?
- A. Yes; Delta Lake ACID guarantees provide assurance that the DELETE command successed fully and permanently purged these records.
- B. No; the Delta Lake DELETE command only provides ACID guarantees when combined with the MERGE INTO command
- C. No; the change data feed only tracks inserts and updates not deleted records.
- D. Yes; the change data feed uses foreign keys to ensure delete consistency throughout the Lakehouse.
- E. No; files containing deleted records may still be accessible with time travel until a BACUM command is used to remove invalidated data files.
정답:E
설명:
The DELETE operation in Delta Lake is ACID compliant, which means that once the operation is successful, the records are logically removed from the table. However, the underlying files that contained these records may still exist and be accessible via time travel to older versions of the table. To ensure that these records are physically removed and compliance with GDPR is maintained, a VACUUM command should be used to clean up these data files after a certain retention period. The VACUUM command will remove the files from the storage layer, and after this, the records will no longer be accessible.
질문 # 85
The business intelligence team has a dashboard configured to track various summary metrics for retail stories. This includes total sales for the previous day alongside totals and averages for a variety of time periods. The fields required to populate this dashboard have the following schema:

For Demand forecasting, the Lakehouse contains a validated table of all itemized sales updated incrementally in near real-time. This table named products_per_order, includes the following fields:

Because reporting on long-term sales trends is less volatile, analysts using the new dashboard only require data to be refreshed once daily. Because the dashboard will be queried interactively by many users throughout a normal business day, it should return results quickly and reduce total compute associated with each materialization.
Which solution meets the expectations of the end users while controlling and limiting possible costs?
- A. Use Structure Streaming to configure a live dashboard against the products_per_order table within a Databricks notebook.
- B. Populate the dashboard by configuring a nightly batch job to save the required values as a table overwritten with each update.
- C. Configure a webhook to execute an incremental read against products_per_order each time the dashboard is refreshed.
- D. Define a view against the products_per_order table and define the dashboard against this view.
- E. Use the Delta Cache to persists the products_per_order table in memory to quickly the dashboard with each query.
정답:B
질문 # 86
The data architect has mandated that all tables in the Lakehouse should be configured as external (also known as "unmanaged") Delta Lake tables.
Which approach will ensure that this requirement is met?
- A. When data is saved to a table, make sure that a full file path is specified alongside the Delta format.
- B. When configuring an external data warehouse for all table storage, leverage Databricks for all ELT.
- C. When a database is being created, make sure that the LOCATION keyword is used.
- D. When the workspace is being configured, make sure that external cloud object storage has been mounted.
- E. When tables are created, make sure that the EXTERNAL keyword is used in the CREATE TABLE statement.
정답:E
설명:
To create an external or unmanaged Delta Lake table, you need to use the EXTERNAL keyword in the CREATE TABLE statement. This indicates that the table is not managed by the catalog and the data files are not deleted when the table is dropped. You also need to provide a LOCATION clause to specify the path where the data files are stored.
For example:
CREATE EXTERNAL TABLE events ( date DATE, eventId STRING, eventType STRING, data STRING) USING DELTA LOCATION `/mnt/delta/events'; This creates an external Delta Lake table named events that references the data files in the
`/mnt/delta/events' path. If you drop this table, the data files will remain intact and you can recreate the table with the same statement.
질문 # 87
......
IT업계에 종사하는 분이 점점 많아지고 있는 지금 IT인증자격증은 필수품으로 되었습니다. IT인사들의 부담을 덜어드리기 위해Itexamdump는Databricks인증 Certified-Data-Engineer-Professional인증시험에 대비한 고품질 덤프를 연구제작하였습니다. Databricks인증 Certified-Data-Engineer-Professional시험을 준비하려면 많은 정력을 기울여야 하는데 회사의 야근에 시달리면서 시험공부까지 하려면 스트레스가 이만저만이 아니겠죠. Itexamdump 덤프를 구매하시면 이제 그런 고민은 끝입니다. 덤프에 있는 내용만 공부하시면 IT인증자격증 취득은 한방에 가능합니다.
Certified-Data-Engineer-Professional시험기출문제: https://www.itexamdump.com/Certified-Data-Engineer-Professional.html
- 최신 업데이트된 Certified-Data-Engineer-Professional시험덤프자료 덤프문제 🚪 오픈 웹 사이트▶ www.dumptop.com ◀검색✔ Certified-Data-Engineer-Professional ️✔️무료 다운로드Certified-Data-Engineer-Professional시험유형
- Certified-Data-Engineer-Professional완벽한 공부문제 🔃 Certified-Data-Engineer-Professional최신 인증시험 대비자료 🏮 Certified-Data-Engineer-Professional시험유형 🏨 ⏩ www.itdumpskr.com ⏪웹사이트를 열고▛ Certified-Data-Engineer-Professional ▟를 검색하여 무료 다운로드Certified-Data-Engineer-Professional인증시험자료
- Certified-Data-Engineer-Professional최신버전 덤프공부문제 🔊 Certified-Data-Engineer-Professional퍼펙트 인증덤프자료 👨 Certified-Data-Engineer-Professional자격증공부 🧺 ▛ www.pass4test.net ▟의 무료 다운로드⏩ Certified-Data-Engineer-Professional ⏪페이지가 지금 열립니다Certified-Data-Engineer-Professional퍼펙트 인증덤프자료
- 인기자격증 Certified-Data-Engineer-Professional시험덤프자료 시험대비 공부자료 🎋 검색만 하면▶ www.itdumpskr.com ◀에서☀ Certified-Data-Engineer-Professional ️☀️무료 다운로드Certified-Data-Engineer-Professional자격증공부
- Certified-Data-Engineer-Professional완벽한 공부문제 🆚 Certified-Data-Engineer-Professional시험덤프자료 🆔 Certified-Data-Engineer-Professional최고품질 인증시험 기출문제 🥳 무료 다운로드를 위해 지금“ www.exampassdump.com ”에서「 Certified-Data-Engineer-Professional 」검색Certified-Data-Engineer-Professional높은 통과율 시험자료
- Certified-Data-Engineer-Professional최신버전 시험공부 🦗 Certified-Data-Engineer-Professional시험덤프자료 ⏺ Certified-Data-Engineer-Professional자격증공부 🌰 ➤ www.itdumpskr.com ⮘을(를) 열고【 Certified-Data-Engineer-Professional 】를 입력하고 무료 다운로드를 받으십시오Certified-Data-Engineer-Professional최신 시험기출문제
- 최신 업데이트된 Certified-Data-Engineer-Professional시험덤프자료 덤프문제 🐥 무료로 다운로드하려면⏩ www.itdumpskr.com ⏪로 이동하여( Certified-Data-Engineer-Professional )를 검색하십시오Certified-Data-Engineer-Professional퍼펙트 덤프 최신버전
- Certified-Data-Engineer-Professional최신버전 덤프공부자료 📚 Certified-Data-Engineer-Professional 100%시험패스 덤프문제 💛 Certified-Data-Engineer-Professional최신 인증시험 대비자료 🐏 ⇛ www.itdumpskr.com ⇚에서▶ Certified-Data-Engineer-Professional ◀를 검색하고 무료 다운로드 받기Certified-Data-Engineer-Professional최신 시험기출문제
- Certified-Data-Engineer-Professional최신 덤프데모 📼 Certified-Data-Engineer-Professional퍼펙트 덤프 최신버전 🎇 Certified-Data-Engineer-Professional최신 덤프데모 🔢 “ www.passtip.net ”웹사이트에서➡ Certified-Data-Engineer-Professional ️⬅️를 열고 검색하여 무료 다운로드Certified-Data-Engineer-Professional최고품질 인증시험 기출문제
- 최신 업데이트된 Certified-Data-Engineer-Professional시험덤프자료 덤프문제 🕖 「 www.itdumpskr.com 」에서➥ Certified-Data-Engineer-Professional 🡄를 검색하고 무료 다운로드 받기Certified-Data-Engineer-Professional인증시험자료
- 최신버전 Certified-Data-Engineer-Professional시험덤프자료 완벽한 시험 최신 덤프공부 🦛 검색만 하면➤ www.dumptop.com ⮘에서[ Certified-Data-Engineer-Professional ]무료 다운로드Certified-Data-Engineer-Professional최신 덤프데모
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.longisland.com, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes