Databricks-Certified-Professional-Data-Engineer Exam Braindumps: Databricks Certified Professional Data Engineer Exam & Databricks-Certified-Professional-Data-Engineer Actual Test Questions

Our Databricks-Certified-Professional-Data-Engineer exam torrents enjoy both price and brand advantage at the same time. We understand you not only consider the quality of our Databricks Certified Professional Data Engineer Exam prepare torrents, but price and after-sales services and support, and other factors as well. So our Databricks Certified Professional Data Engineer Exam prepare torrents contain not only the high quality and high accuracy Databricks-Certified-Professional-Data-Engineer Test Braindumps but comprehensive services as well. With the assistance of our Databricks-Certified-Professional-Data-Engineer exam torrents, you will be more distinctive than your fellow workers, because you will learn to make full use of your fragmental time to achieve your goals.
| Section | Weight | Objectives |
|---|
| Data Governance | 7% | - Unity Catalog management
- Data lineage and metadata tracking
- Policy enforcement
|
| Developing Code for Data Processing using Python and SQL | 22% | - Batch and incremental processing logic
- Data transformation and aggregation
- Integration with Databricks APIs and tools
|
| Monitoring and Alerting | 10% | - Pipeline observability and logging
- Setting up alerts and notifications
- Performance and health monitoring
|
| Cost & Performance Optimisation | 13% | - Storage optimization (partitioning, Z-order, indexing)
- Cluster configuration and scaling
- Query optimization and caching
|
| Debugging and Deploying | 10% | - CI/CD and DevOps practices
- Deployment using bundles, CLI, and APIs
- Troubleshooting pipelines and errors
|
| Data Sharing and Federation | 5% | - Unity Catalog data sharing
- Cross-workspace and cross-cloud access
|
| Data Ingestion & Acquisition | 7% | - Connecting to diverse data sources
- Auto Loader and streaming ingestion
- Schema inference and evolution
|
| Data Modelling | 6% | - Delta Lake table design
- Medallion Architecture implementation
- Schema design and management
|
| Ensuring Data Security and Compliance | 10% | - Access control and permissions
- Compliance standards implementation
- Data encryption and masking
|
| Data Transformation, Cleansing, and Quality | 10% | - Standardization and normalization
- Handling missing or inconsistent data
- Data validation and quality checks
|
>> Databricks-Certified-Professional-Data-Engineer Valid Braindumps Book <<
Databricks-Certified-Professional-Data-Engineer Latest Study Guide | Databricks-Certified-Professional-Data-Engineer New Braindumps
Are you an ambitious person and do you want to make your life better right now? If the answer is yes, then you just need to make use of your spare time to finish learning our Databricks-Certified-Professional-Data-Engineer exam materials and we can promise that your decision will change your life. So your normal life will not be disturbed. Please witness your growth after the professional guidance of our Databricks-Certified-Professional-Data-Engineer Study Materials. In short, our Databricks-Certified-Professional-Data-Engineer real exam will bring good luck to your life.
Databricks Certified Professional Data Engineer Exam Sample Questions (Q203-Q208):
NEW QUESTION # 203
Which statement describes Delta Lake Auto Compaction?
- A. Data is queued in a messaging bus instead of committing data directly to memory; all data is committed from the messaging bus in one batch once the job is complete.
- B. Optimized writes use logical partitions instead of directory partitions; because partition boundaries are only represented in metadata, fewer small files are written.
- C. An asynchronous job runs after the write completes to detect if files could be further compacted; if yes, an optimize job is executed toward a default of 1 GB.
- D. Before a Jobs cluster terminates, optimize is executed on all tables modified during the most recent job.
- E. An asynchronous job runs after the write completes to detect if files could be further compacted; if yes, an optimize job is executed toward a default of 128 MB.
Answer: E
Explanation:
Explanation
This is the correct answer because it describes the behavior of Delta Lake Auto Compaction, which is a feature that automatically optimizes the layout of Delta Lake tables by coalescing small files into larger ones. Auto Compaction runs as an asynchronous job after a write to a table has succeeded and checks if files within a partition can be further compacted. If yes, it runs an optimize job with a default target file size of 128 MB.
Auto Compaction only compacts files that have not been compacted previously. Verified References:
[Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Auto Compaction for Delta Lake on Databricks" section.
"Auto compaction occurs after a write to a table has succeeded and runs synchronously on the cluster that has performed the write. Auto compaction only compacts files that haven't been compacted previously."
https://learn.microsoft.com/en-us/azure/databricks/delta/tune-file-size
NEW QUESTION # 204
A Spark job is taking longer than expected. Using the Spark UI, a data engineer notes that the Min, Median, and Max Durations for tasks in a particular stage show the minimum and median time to complete a task as roughly the same, but the max duration for a task to be roughly 100 times as long as the minimum.
Which situation is causing increased duration of the overall job?
- A. Task queueing resulting from improper thread pool assignment.
- B. Spill resulting from attached volume storage being too small.
- C. Network latency due to some cluster nodes being in different regions from the source data
- D. Skew caused by more data being assigned to a subset of spark-partitions.
- E. Credential validation errors while pulling data from an external system.
Answer: D
Explanation:
Explanation
This is the correct answer because skew is a common situation that causes increased duration of the overall job. Skew occurs when some partitions have more data than others, resulting in uneven distribution of work among tasks and executors. Skew can be caused by various factors, such as skewed data distribution, improper partitioning strategy, or join operations with skewed keys. Skew can lead to performance issues such as long-running tasks, wasted resources, or even task failures due to memory or disk spills. Verified References:
[Databricks Certified Data Engineer Professional], under "Performance Tuning" section; Databricks Documentation, under "Skew" section.
NEW QUESTION # 205
Two of the most common data locations on Databricks are the DBFS root storage and external object storage mounted with dbutils.fs.mount().
Which of the following statements is correct?
- A. DBFS is a file system protocol that allows users to interact with files stored in object storage using syntax and guarantees similar to Unix file systems.
- B. By default, both the DBFS root and mounted data sources are only accessible to workspace administrators.
- C. Neither the DBFS root nor mounted storage can be accessed when using %sh in a Databricks notebook.
- D. The DBFS root is the most secure location to store data, because mounted storage volumes must have full public read and write permissions.
- E. The DBFS root stores files in ephemeral block volumes attached to the driver, while mounted directories will always persist saved data to external storage between sessions.
Answer: A
Explanation:
Explanation
DBFS is a file system protocol that allows users to interact with files stored in object storage using syntax and guarantees similar to Unix file systems1. DBFS is not a physical file system, but a layer over the object storage that provides a unified view of data across different data sources1. By default, the DBFS root is accessible to all users in the workspace, and the access to mounted data sources depends on the permissions of the storage account or container2. Mounted storage volumes do not need to have full public read and write permissions, but they do require a valid connection string or access key to be provided when mounting3. Both the DBFS root and mounted storage can be accessed when using %sh in a Databricks notebook, as long as the cluster has FUSE enabled4. The DBFS root does not store files in ephemeral block volumes attached to the driver, but in the object storage associated with the workspace1. Mounted directories will persist saved data to external storage between sessions, unless they are unmounted or deleted3. References: DBFS, Work with files on Azure Databricks, Mounting cloud object storage on Azure Databricks, Access DBFS with FUSE
NEW QUESTION # 206
Which statement describes integration testing?
- A. Validates behavior of individual elements of your application
- B. Requires an automated testing framework
- C. Validates interactions between subsystems of your application
- D. Requires manual intervention
- E. Validates an application use case
Answer: C
Explanation:
Explanation
This is the correct answer because it describes integration testing. Integration testing is a type of testing that validates interactions between subsystems of your application, such as modules, components, or services.
Integration testing ensures that the subsystems work together as expected and produce the correct outputs or results. Integration testing can be done at different levels of granularity, such as component integration testing, system integration testing, or end-to-end testing. Integration testing can help detect errors or bugs that may not be found by unit testing, which only validates behavior of individual elements of your application. Verified References: [Databricks Certified Data Engineer Professional], under "Testing" section; Databricks Documentation, under "Integration testing" section.
NEW QUESTION # 207
The viewupdatesrepresents an incremental batch of all newly ingested data to be inserted or updated in the customerstable.
The following logic is used to process these records.
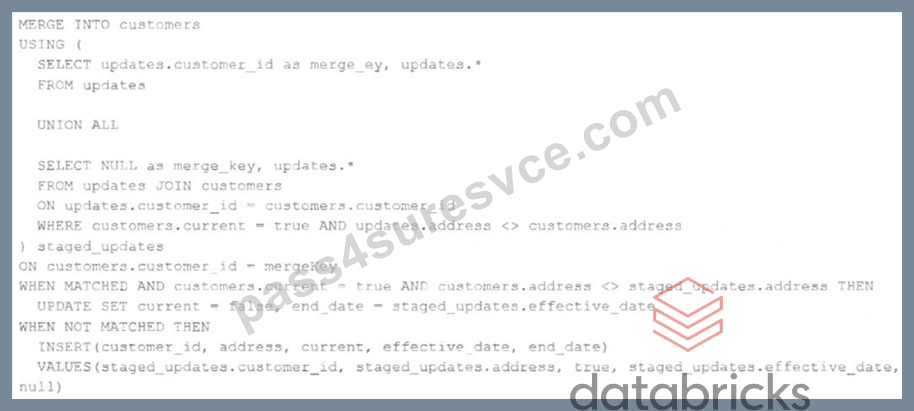
Which statement describes this implementation?
- A. The customers table is implemented as a Type 2 table; old values are overwritten and new customers are appended.
- B. The customers table is implemented as a Type 2 table; old values are maintained but marked as no longer current and new values are inserted.
- C. The customers table is implemented as a Type 1 table; old values are overwritten by new values and no history is maintained.
- D. The customers table is implemented as a Type 0 table; all writes are append only with no changes to existing values.
- E. The customers table is implemented as a Type 3 table; old values are maintained as a new column alongside the current value.
Answer: B
Explanation:
The logic uses the MERGE INTO command to merge new records from the view updates into the table customers. The MERGE INTO command takes two arguments: a target table and a source table or view. The command also specifies a condition to match records between the target and the source, and a set of actions to perform when there is a match or not. In this case,the condition is to match records by customer_id, which is the primary key of the customers table. The actions are to update the existing record in the target with the new values from the source, and set the current_flag to false to indicate that the record is no longer current; and to insert a new record in the target with the new values from the source, and set the current_flag to true to indicate that the record is current. This means that old values are maintained but marked as no longer current and new values are inserted, which is the definition of a Type 2 table. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Merge Into (Delta Lake on Databricks)" section.
NEW QUESTION # 208
......
It is no longer an accident for you to pass Databricks-Certified-Professional-Data-Engineer exam after you have use our Databricks-Certified-Professional-Data-Engineer exam software. You will have thorough training and exercises from our huge question dumps, and master every question from the detailed answer analysis. The exam software with such guarantees will clear your worries about Databricks-Certified-Professional-Data-Engineer Exam.
Databricks-Certified-Professional-Data-Engineer Latest Study Guide: https://www.pass4suresvce.com/Databricks-Certified-Professional-Data-Engineer-pass4sure-vce-dumps.html
- Quiz Databricks - Databricks-Certified-Professional-Data-Engineer - Latest Databricks Certified Professional Data Engineer Exam Valid Braindumps Book 🐧 Search for ⮆ Databricks-Certified-Professional-Data-Engineer ⮄ and download exam materials for free through ▷ www.torrentvce.com ◁ 🍧Reliable Databricks-Certified-Professional-Data-Engineer Study Guide
- Valid Test Databricks-Certified-Professional-Data-Engineer Tips 😝 Databricks-Certified-Professional-Data-Engineer Reliable Braindumps Sheet 🧞 Databricks-Certified-Professional-Data-Engineer Valid Dumps Demo 🩱 Open ➽ www.pdfvce.com 🢪 enter ➽ Databricks-Certified-Professional-Data-Engineer 🢪 and obtain a free download 🚡Databricks-Certified-Professional-Data-Engineer Valid Exam Vce
- Valid Test Databricks-Certified-Professional-Data-Engineer Tips 🗯 Databricks-Certified-Professional-Data-Engineer Valid Exam Vce 🎱 Valid Databricks-Certified-Professional-Data-Engineer Practice Questions 🕑 Search for ▛ Databricks-Certified-Professional-Data-Engineer ▟ and download it for free immediately on ⮆ www.torrentvce.com ⮄ 🌄Databricks-Certified-Professional-Data-Engineer Pass Leader Dumps
- Databricks Certified Professional Data Engineer Exam Latest Exam File - Databricks-Certified-Professional-Data-Engineer free download pdf - Databricks Certified Professional Data Engineer Exam Valid Test Simulator 🧮 Copy URL ( www.pdfvce.com ) open and search for “ Databricks-Certified-Professional-Data-Engineer ” to download for free 🎰Databricks-Certified-Professional-Data-Engineer Pdf Version
- 100% Pass 2026 Newest Databricks Databricks-Certified-Professional-Data-Engineer Valid Braindumps Book 👺 Easily obtain “ Databricks-Certified-Professional-Data-Engineer ” for free download through ⮆ www.vce4dumps.com ⮄ 🏹Databricks-Certified-Professional-Data-Engineer Pdf Version
- Quiz Databricks - Databricks-Certified-Professional-Data-Engineer - Latest Databricks Certified Professional Data Engineer Exam Valid Braindumps Book 📽 Open { www.pdfvce.com } and search for ➠ Databricks-Certified-Professional-Data-Engineer 🠰 to download exam materials for free 🐦Databricks-Certified-Professional-Data-Engineer Reliable Braindumps Sheet
- Reliable Databricks-Certified-Professional-Data-Engineer Test Testking 🦦 Databricks-Certified-Professional-Data-Engineer Test Objectives Pdf 😃 Databricks-Certified-Professional-Data-Engineer Pdf Version 🐔 Search for { Databricks-Certified-Professional-Data-Engineer } and easily obtain a free download on ▶ www.dumpsquestion.com ◀ 🔬Valid Databricks-Certified-Professional-Data-Engineer Test Cram
- Databricks-Certified-Professional-Data-Engineer Reliable Test Sims ☑ Databricks-Certified-Professional-Data-Engineer Valid Dumps Demo 🩸 Test Databricks-Certified-Professional-Data-Engineer Dump 🪂 Search for ▶ Databricks-Certified-Professional-Data-Engineer ◀ and download it for free immediately on ➡ www.pdfvce.com ️⬅️ 🚾Databricks-Certified-Professional-Data-Engineer Test Price
- Test Databricks-Certified-Professional-Data-Engineer Dump 🦀 Databricks-Certified-Professional-Data-Engineer Test Objectives Pdf 🏠 Test Databricks-Certified-Professional-Data-Engineer Dump 🔤 Search for ➤ Databricks-Certified-Professional-Data-Engineer ⮘ and easily obtain a free download on ➡ www.exam4labs.com ️⬅️ 🥎Databricks-Certified-Professional-Data-Engineer Pdf Version
- 100% Pass Quiz 2026 Databricks-Certified-Professional-Data-Engineer: Useful Databricks Certified Professional Data Engineer Exam Valid Braindumps Book 📊 Download ⮆ Databricks-Certified-Professional-Data-Engineer ⮄ for free by simply entering ✔ www.pdfvce.com ️✔️ website 🥵Test Databricks-Certified-Professional-Data-Engineer Dump
- Free PDF Databricks-Certified-Professional-Data-Engineer - Updated Databricks Certified Professional Data Engineer Exam Valid Braindumps Book 🥎 Easily obtain ➡ Databricks-Certified-Professional-Data-Engineer ️⬅️ for free download through [ www.verifieddumps.com ] 😈Latest Real Databricks-Certified-Professional-Data-Engineer Exam
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes