P.S.JPTestKingがGoogle Driveで共有している無料の2026 Databricks Databricks-Certified-Data-Engineer-Associateダンプ:https://drive.google.com/open?id=1SPkJhwHX7ykSjDqyjpBF_OyvlJ_IMtUq
そんなに多くの人はDatabricks Databricks-Certified-Data-Engineer-Associate試験に合格できるのに興味がわきますか。人に引けをとりたくないあなたはDatabricks Databricks-Certified-Data-Engineer-Associate資格認定を取得したいですか。ここで、彼らはDatabricks-Certified-Data-Engineer-Associate試験にうまく合格できる秘訣は我々社の提供する質高いDatabricks Databricks-Certified-Data-Engineer-Associate問題集を利用したことだと教えます。弊社のDatabricks Databricks-Certified-Data-Engineer-Associate問題集を通して復習してから、真実的に自分の能力の向上を感じ、Databricks-Certified-Data-Engineer-Associate資格認定を受け取ります。
GAQM Databricks-Certified-Data-Engineer-Associate(DataBricks Certified Data Engineer Associate)認定試験は、データアブリックプラットフォームとデータエンジニアリングにおけるその役割についての候補者の理解を検証する包括的かつ厳密な試験です。この認定は、DataBricksを使用してデータパイプラインの設計、構築、維持に必要な実用的なスキルと知識の評価に焦点を当てています。
>> Databricks Databricks-Certified-Data-Engineer-Associate試験問題 <<
人々は自分が将来何か成績を作るようにずっと努力しています。IT業界でのあなたも同じでしょう。自分の能力を高めるために、Databricks-Certified-Data-Engineer-Associate試験に参加する必要があります。Databricks-Certified-Data-Engineer-Associate試験に合格したら、あなたがより良く就職し輝かしい未来を持っています。この試験が非常に困難ですが、実は試験を準備するとき、もっと楽になることができます。我々のDatabricks-Certified-Data-Engineer-Associate問題集を入手するのはあなたの進めるべきの第一歩です。
GAQM Databricks-Certified-Data-Engineer-Associate試験は、Databricksを使用したデータパイプラインの設計と構築において、自分の熟練度を証明したいデータエンジニア向けの認定試験です。この試験は、データエンジニアリング、ビッグデータ処理と分析、Databricksを使用したクラウドコンピューティングの知識と技能を評価するように設計されています。
質問 # 268
A data engineer needs to ingest from both streaming and batch sources for a firm that relies on highly accurate data. Occasionally, some of the data picked up by the sensors that provide a streaming input are outside the expected parameters. If this occurs, the data must be dropped, but the stream should not fail. Which feature of Delta Live Tables meets this requirement?
正解:D
解説:
Delta Live Tables Expectations allow defining data quality rules. Records that fail the expectations (such as sensor readings outside valid ranges) can be dropped without stopping the streaming pipeline, ensuring continuous and accurate processing.
質問 # 269
A data engineer wants to delegate day-to-day permission management for the schema main.marketing to the mkt-admins group, without making them workspace admins. They should be able to grant and revoke privileges for other users on objects within that schema.
Which approach aligns with Unity Catalog's ownership and privilege model?
正解:D
解説:
In Unity Catalog, ownership is the primary mechanism for delegating full administrative control of a securable object. The owner of a schema can grant and revoke privileges on that schema and on all objects contained within it (such as tables and views), without needing to be a workspace admin or metastore admin.
Transferring ownership of main.marketing to the mkt-admins group therefore aligns precisely with the requirement to delegate day-to-day permission management at the schema scope. Granting MANAGE at the metastore level (option B) would be overly permissive, enabling global administration across all schemas and objects, which violates the principle of least privilege. Simply granting USE SCHEMA and MODIFY (option C) does not confer the ability to manage grants for other users. Making the group workspace admins (option D) unnecessarily elevates privileges beyond Unity Catalog's data governance model. Unity Catalog documentation emphasizes using ownership transfer to delegate administrative responsibilities at the appropriate scope while maintaining centralized governance in Databricks.
=========
質問 # 270
A data engineer is attempting to drop a Spark SQL table my_table and runs the following command:
DROP TABLE IF EXISTS my_table;
After running this command, the engineer notices that the data files and metadata files have been deleted from the file system.
Which of the following describes why all of these files were deleted?
正解:B
解説:
The reason why all of the data files and metadata files were deleted from the file system after dropping the table is that the table was managed. A managed table is a table that is created and managed by Spark SQL. It stores both the data and the metadata in the default location specified by the spark.sql.warehouse.
dir configuration property. When a managed table is dropped, both the data and the metadata are deleted from the file system.
Option B is not correct, as the size of the table's data does not affect the behavior of dropping the table.
Whether the table's data is smaller or larger than 10 GB, the data files and metadata files will be deleted if the table is managed, and will be preserved if the table is external.
Option C is not correct, for the same reason as option B.
Option D is not correct, as an external table is a table that is created and managed by the user. It stores the data in a user-specified location, and only stores the metadata in the Spark SQL catalog. When an external table is dropped, only the metadata is deleted from the catalog, but the data files are preserved in the file system.
Option E is not correct, as a table must have a location to store the data. If the location is not specified by the user, it will use the default location for managed tables. Therefore, a table without a location is a managed table, and dropping it will delete both the data and the metadata.
Managing Tables
[Databricks Data Engineer Professional Exam Guide]
質問 # 271
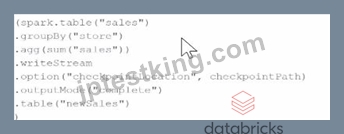
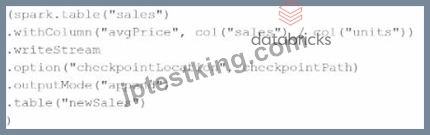
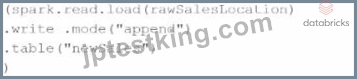
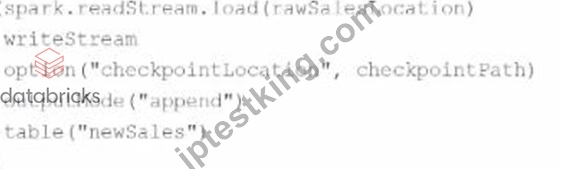
Which query is performing a streaming hop from raw data to a Bronze table?
正解:D
解説:
The query performing a streaming hop from raw data to a Bronze table is identified by using the Spark streaming read capability and then writing to a Bronze table. Let's analyze the options:
Option A: Utilizes .writeStream but performs a complete aggregation which is more characteristic of a roll-up into a summarized table rather than a hop into a Bronze table.
Option B: Also uses .writeStream but calculates an average, which again does not typically represent the raw to Bronze transformation, which usually involves minimal transformations.
Option C: This uses a basic .write with .mode("append") which is not a streaming operation, and hence not suitable for real-time streaming data transformation to a Bronze table.
Option D: It employs spark.readStream.load() to ingest raw data as a stream and then writes it out with .writeStream, which is a typical pattern for streaming data into a Bronze table where raw data is captured in real-time and minimal transformation is applied. This approach aligns with the concept of a Bronze table in a modern data architecture, where raw data is ingested continuously and stored in a more accessible format.
Reference:
Databricks documentation on Structured Streaming: Structured Streaming in Databricks
質問 # 272
A Structured Streaming job is stopped and restarted after a code change. The engineer wants the job to resume from where it left off rather than reprocessing all source data.
Which configuration is required?
正解:C
解説:
The checkpoint location stores stream progress and offset information, allowing the query to resume exactly where it stopped after a restart or failure. Each streaming query must have its own dedicated checkpoint directory; reusing or deleting it causes reprocessing or incorrect results.
質問 # 273
......
Databricks-Certified-Data-Engineer-Associate復習解答例: https://www.jptestking.com/Databricks-Certified-Data-Engineer-Associate-exam.html
さらに、JPTestKing Databricks-Certified-Data-Engineer-Associateダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1SPkJhwHX7ykSjDqyjpBF_OyvlJ_IMtUq