P.S. Free & New DP-750 dumps are available on Google Drive shared by PracticeTorrent: https://drive.google.com/open?id=1W-b8QyjInySOX5AHEBL_hE4YzfM6j2Hw
PracticeTorrent Microsoft DP-750 exam dumps are the best reference materials. PracticeTorrent test questions and answers are the training materials you have been looking for. This is a special IT exam dumps for all candidates. PracticeTorrent pdf real questions and answers will help you prepare well enough for Microsoft DP-750 test in the short period of time and pass your exam successfully. If you don't want to waste a lot of time and efforts on the exam, you had better select PracticeTorrent Microsoft DP-750 Dumps. Using this certification training dumps can let you improve the efficiency of your studying so that it can help you save much more time.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
| Topic 2: Prepare and process data | 30-35% | - Ingest and transform data
|
| Topic 3: Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
| Topic 4: Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
>> Sample DP-750 Questions Pdf <<
The learning material of PracticeTorrent is in three different formats so the students can take full benefit from it and use it anywhere anytime while preparing for Implementing Data Engineering Solutions Using Azure Databricks exam questions. The Implementing Data Engineering Solutions Using Azure Databricks (DP-750) guarantees its customers that they will pass the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) certification exams in a single try if they prepare with our product and if they fail to do it so then they can reclaim their money back according to terms and conditions.
NEW QUESTION # 77
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to recommend a pipeline that ingests files from cloud storage, performs cleansing and enrichment transformations, and writes curated Delta tables for analytics. The solution must minimize development effort and provide built-in monitoring and automatic retries.
What should you include in the recommendation?
Answer: A
Explanation:
The best choice is a Lakeflow Spark Declarative Pipelines (SDP) pipeline.
Low Development Effort: Lakeflow SDP (formerly known as Delta Live Tables or DLT) is a completely declarative ETL framework. You simply define the target schemas and data transformations using standard SQL or Python. Databricks automatically manages the underlying operational complexities, state maintenance, task orchestration, and DAG dependencies for you.
Built-in Quality & Monitoring: It offers out-of-the-box data monitoring capabilities via Expectations, which allow you to specify data cleansing policies (like drop, retain, or fail on bad rows) with zero custom validation code. It also captures complete, automatic end-to-end data lineage and operational stats straight into Unity Catalog.
Built-in Resilience: Infrastructure failure handling and automatic retries are natively managed by the Lakeflow runtime.
Native Storage Ingestion: Using read_files() (Auto Loader) within SDP allows effortless, incremental ingestion of files from cloud object storage directly into curated Delta tables.
Reference:
https://docs.databricks.com/aws/en/ldp/
NEW QUESTION # 78
You have an Azure Databricks workspace.
You need to ingest streaming data from Azure Event Hubs by using Apache Spark Structured Streaming The solution must authenticate to Event Hubs and read the event payload.
How should you complete the PySpark code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.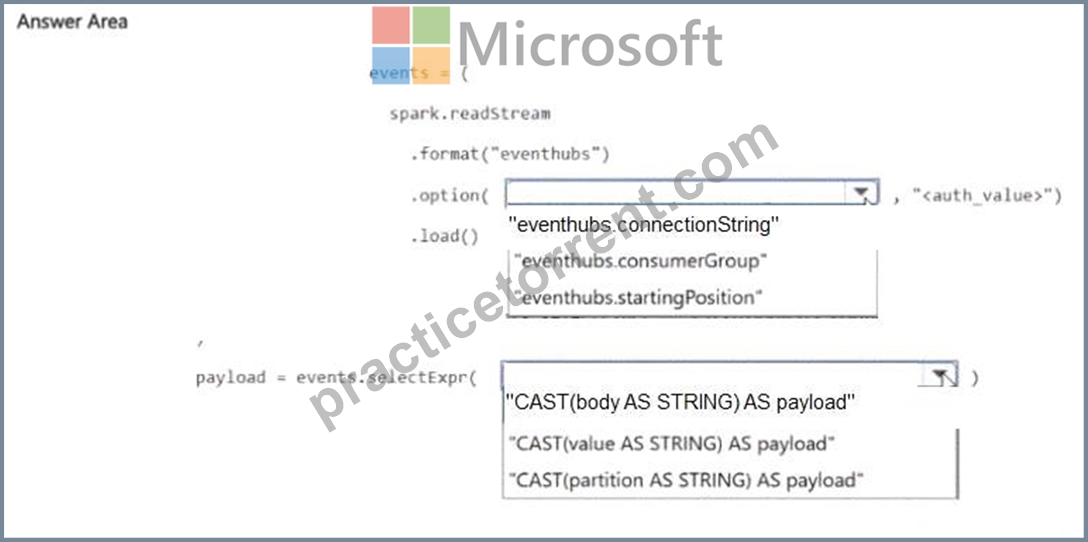
Answer:
Explanation: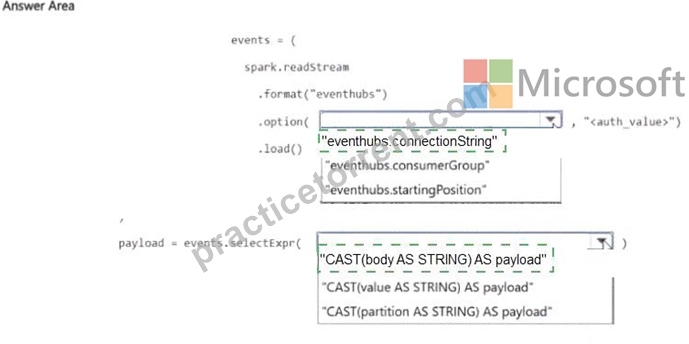
Explanation:
Reading from Azure Event Hubs in Spark Structured Streaming requires three things:
An EventHubsConf object built with the Event Hubs connection string (eventhubs.connectionString). This object is then converted to a map with .toMap before being passed to Spark.
spark.readStream.format('eventhubs').options(**ehConf).load() to create the streaming DataFrame. The
'eventhubs' format is provided by the azure-eventhubs-spark connector library.
A cast('string') on the body column to decode the binary payload. Event Hubs delivers messages with the raw event bytes in a column called body - without the cast, you get binary data rather than the readable JSON or text payload.
This is the standard, documented integration pattern for connecting Azure Databricks to Event Hubs with Structured Streaming, providing the checkpoint-based exactly-once semantics required by the Contoso telemetry pipeline.
Reference: https://learn.microsoft.com/en-us/azure/databricks/connect/storage/events/eventhubs
NEW QUESTION # 79
You have an Azure Databricks workspace.
You have a streaming table named sales_order that is populated by using a Lakeflow Spark Declarative Pipelines (SDP) pipeline.
You need to create a new streaming table named sales_order_by_city that summarizes sales by city and calculates the total sales per city.
How should you complete the SQL statement? To answer, drag the appropriate values to the correct targets.
Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
CREATE OR REFRESH STREAMING TABLE
city
CREATE OR REFRESH STREAMING TABLE defines a streaming table managed by Lakeflow Spark Declarative Pipelines. When the pipeline refreshes, Databricks incrementally processes newly available source data and maintains the resulting table. CREATE OR REPLACE TABLE would create a conventional table and does not provide the required streaming-table semantics. The query selects city AS city and calculates SUM(sales) AS total_sales. Because the aggregation must produce one result for each city, the GROUP BY expression must be city. Neither SUM(sales) nor total_sales belongs in the grouping clause: the former is the aggregate calculation, while the latter is only the alias assigned to its result. This produces continuously maintained city-level sales totals from the sales_order source table.
NEW QUESTION # 80
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Table1. Table1 stores customer data.
You need to implement a data retention solution that meets the following requirements:
Deleted data must be retained for 30 days to support audits.
Deleted data that is older than 30 days must be removed permanently.
The solution must minimize administrative effort.
Which two properties should you configure? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: B,C
Explanation:
The correct answers are B and D. Delta Lake's data retention behaviour is controlled by two distinct properties that work together:
delta.deletedFileRetentionDuration governs how long physically deleted data files are kept before VACUUM can remove them. Setting this to 30 days ensures deleted records remain on storage for the full audit window.
delta.logRetentionDuration controls how long the transaction log is retained. Time-travel queries (SELECT ...
VERSION AS OF or TIMESTAMP AS OF) rely on the log to reconstruct historical table states - without 30 days of log, you can't query 30-day-old snapshots even if the data files are still there.
Both properties need to be set to 30 days to fully honour the requirement. Option A (delta.timeUntilArchived) doesn't exist in Delta Lake. Option C (autoCompact) manages file sizing, not retention. Option E (enableDeletionVectors) speeds up deletes but has no bearing on how long data is kept.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/history#configure-data-retention
NEW QUESTION # 81
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df-fillna(0, subset=['order_amount'])
Does this meet the goal?
Answer: B
Explanation:
The correct answer is B - No.
df.fillna(0, subset=['order_amount']) does not remove null rows. It replaces null values in order_amount with the integer 0, leaving those rows in the DataFrame with 0 as their order_amount value. The row count is unchanged - nulls are imputed, not dropped.
The requirement is to exclude rows where order_amount is null, meaning those rows should not appear in the result at all. fillna is a data imputation function - it fills gaps with default values, which is a different operation entirely from filtering. After fillna, a downstream process would see order_amount = 0 and might treat it as a valid zero-value order rather than recognising it was originally null.
The correct approach is df.dropna(subset=['order_amount']) or df.filter(df.order_amount.isNotNull()), both of which physically remove null rows from the resulting DataFrame.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
NEW QUESTION # 82
......
The striking function of our Implementing Data Engineering Solutions Using Azure Databricks prepare torrent has attracted tens of thousands of exam candidates around the world with regular buyers who trust us by instinct when they have to deal with exams in this area. They are DP-750 exam torrent of versatility for providing not only the essential parts the exam test frequently but the new trendy question points. So our DP-750 Test Braindumps has attracted tens of thousands of regular buyers around the world. The successful endeavor of any kind of exam not only hinges on the effort the exam candidates paid, but the quality of practice materials’ usefulness. We trust you willpower, and we provide the high quality and high-effective DP-750 exam torrent here.
Reliable DP-750 Braindumps Files: https://www.practicetorrent.com/DP-750-practice-exam-torrent.html
BONUS!!! Download part of PracticeTorrent DP-750 dumps for free: https://drive.google.com/open?id=1W-b8QyjInySOX5AHEBL_hE4YzfM6j2Hw