New Certified-Data-Engineer-Professional Test Testking & Certified-Data-Engineer-Professional Learning Engine

What's more, part of that PDFDumps Certified-Data-Engineer-Professional dumps now are free: https://drive.google.com/open?id=12VtarPwAZmc6PV1x69iYhLoSya_4m2Sn
Our Certified-Data-Engineer-Professional exam braindumps are unlike other exam materials that are available on the market. Our Certified-Data-Engineer-Professional study torrent specially proposed different versions to allow you to learn not only on paper, but also to use mobile phones to learn. This greatly improves the students' availability of fragmented time to study our Certified-Data-Engineer-Professional learning guide. You can choose the version of Certified-Data-Engineer-Professional training quiz according to your interests and habits.
| Section | Objectives |
|---|
| Data Sharing and Federation | - Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
- Delta Sharing
- 1. Configure sharing with external platforms using the open sharing protocol
- 2. Configure Databricks-to-Databricks Sharing
- 3. Share live Lakehouse data with external computing platforms
|
| Ensuring Data Security and Compliance | - Data Security
- 1. Apply anonymization and pseudonymization techniques
- 2. Use ACLs to secure workspace objects and enforce least privilege
- 3. Use row filters and column masks for sensitive data
- Compliance
- 1. Develop data purging solutions according to data retention policies
- 2. Implement pipelines that detect and mask personally identifiable information
|
| Data Transformation, Cleansing, and Quality | - Advanced Data Transformation
- 1. Apply window functions, joins, and aggregations to large datasets
- 2. Write efficient Spark SQL and PySpark transformations
- Data Quality
- 1. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
- 2. Develop data quarantining processes for invalid data
|
| Monitoring and Alerting | - Monitoring
- 1. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 2. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- 3. Use system tables for resource, cost, audit, and workload monitoring
- 4. Use Query Profiler and Spark UI to monitor workloads
- Alerting
- 1. Use SQL Alerts for data quality monitoring
- 2. Configure Lakeflow Jobs notifications for job status and performance issues
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
- 2. Ingest data from message buses and cloud storage
- 3. Build append-only pipelines for batch and streaming data using Delta
|
| Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- 2. Manage and troubleshoot third-party library installations and dependencies
- 3. Develop User-Defined Functions using Pandas/Python UDFs
- Building and Testing ETL Pipelines
- 1. Configure environments, dependencies, memory, and retry behavior
- 2. Use APPLY CHANGES APIs for change data capture
- 3. Develop unit and integration tests for data processing code
- 4. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 5. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 6. Compare streaming tables and materialized views
- 7. Use control flow operators in pipeline components
- 8. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
|
| Debugging and Deploying | - Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs
- 2. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- 3. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- Deploying CI/CD
- 1. Integrate Git-based CI/CD workflows using Databricks Git Folders
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
|
| Cost & Performance Optimisation | - Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
- Query Performance
- 1. Use Query Profile to identify performance bottlenecks
- 2. Identify inefficient joins and excessive data shuffling
- Delta Optimization
- 1. Use Change Data Feed to address streaming table limitations and improve latency
- 2. Understand deletion vectors and liquid clustering
- 3. Apply data skipping and file pruning techniques
|
| Data Governance | - Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
- Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
|
| Data Modelling | - Dimensional Modelling
- 1. Design dimensional models for analytical workloads
- Scalable Data Models
- 1. Understand Liquid Clustering versus partitioning and Z-Ordering
- 2. Optimize data layout using Liquid Clustering
- 3. Design and implement scalable data models using Delta Lake
|
>> New Certified-Data-Engineer-Professional Test Testking <<
Certified-Data-Engineer-Professional Study Guide: Databricks Certified Data Engineer Professional & Certified-Data-Engineer-Professional Learning Materials
Are you sometimes nervous about the coming Certified-Data-Engineer-Professional exam and worried that you can't get used to the condition? Never worry, we can offer 3 different versions for you to choose: PDF, Soft and APP versions. You can use the Soft version of our Certified-Data-Engineer-Professional study materials to stimulate the exam to adjust yourself to the atmosphere of the real exam and adjust your speed to answer the questions. The other 2 versions also boost their own strength and applicable method and you could learn our Certified-Data-Engineer-Professional training quiz by choosing the most suitable version to according to your practical situation.
Databricks Certified Data Engineer Professional Sample Questions (Q243-Q248):
NEW QUESTION # 243
A data engineer is creating a daily reporting job. There are two reporting notebooks--one for weekdays and one for weekends. An "if/else condition" task is configured as
{{job.start_time.is_weekday}} == true to route the job to either the weekday or weekend notebook tasks. The same job would be used across multiple time zones. Which action should a senior data engineer take upon reviewing the job to merge or reject the pull request?
- A. Reject, as the {{job.start_time.is_weekday}} is not a valid value reference.
- B. Reject, as they should use {{job.trigger_time.is_weekday}} instead.
- C. Merge, as the job configuration looks good.
- D. Reject, as the {{job.start_time.is_weekday}} is for the UTC timezone.
Answer: D
Explanation:
Databricks parameter templates like {{job.start_time.is_weekday}} evaluate in UTC time by default, not in local workspace or regional time zones. Therefore, when jobs are configured to run across different time zones, relying on is_weekday using UTC may cause scheduling and task routing mismatches (for example, triggering the weekday notebook in one region while it's still the weekend locally).
Databricks recommends adjusting conditional logic or pipeline parameters explicitly to handle time zone conversions if business requirements depend on local times. Because the engineer's configuration does not account for this behavior, a senior data engineer should reject the pull request and suggest time-zone-aware logic before merging.
NEW QUESTION # 244
Review the following error traceback:
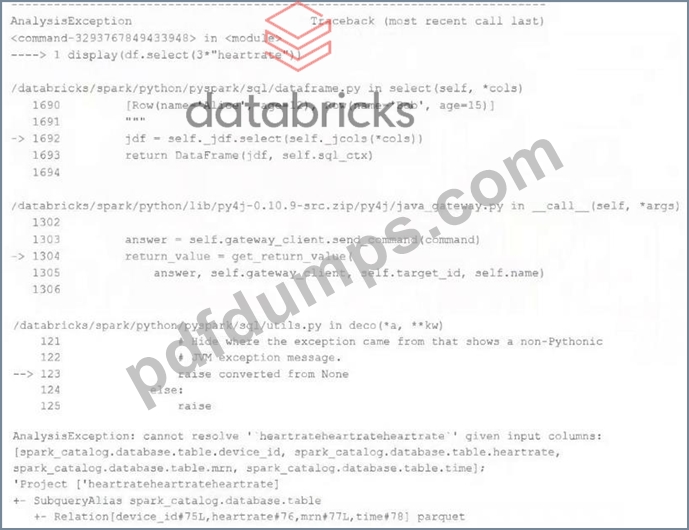
Which statement describes the error being raised?
- A. There is a syntax error because the heartrate column is not correctly identified as a column.
- B. There is no column in the table named heartrateheartrateheartrate
- C. The code executed was PvSoark but was executed in a Scala notebook.
- D. There is a type error because a column object cannot be multiplied.
- E. There is a type error because a DataFrame object cannot be multiplied.
Answer: B
Explanation:
https://sparkbyexamples.com/spark/spark-cannot-resolve-given-input-columns/
NEW QUESTION # 245
A data engineer is configuring a pipeline that will potentially see late-arriving, duplicate records.
In addition to de-duplicating records within the batch, which of the following approaches allows the data engineer to deduplicate data against previously processed records as it is inserted into a Delta table?
- A. VACUUM the Delta table after each batch completes.
- B. Perform a full outer join on a unique key and overwrite existing data.
- C. Set the configuration delta.deduplicate = true.
- D. Rely on Delta Lake schema enforcement to prevent duplicate records.
- E. Perform an insert-only merge with a matching condition on a unique key.
Answer: E
Explanation:
To deduplicate data against previously processed records as it is inserted into a Delta table, you can use the merge operation with an insert-only clause. This allows you to insert new records that do not match any existing records based on a unique key, while ignoring duplicate records that match existing records. For example, you can use the following syntax:
MERGE INTO target_table USING source_table ON target_table.unique_key = source_table.unique_key WHEN NOT MATCHED THEN INSERT * This will insert only the records from the source table that have a unique key that is not present in the target table, and skip the records that have a matching key. This way, you can avoid inserting duplicate records into the Delta table.
NEW QUESTION # 246
A table named user_ltv is being used to create a view that will be used by data analysts on various teams. Users in the workspace are configured into groups, which are used for setting up data access using ACLs.
The user_ltv table has the following schema:
email STRING, age INT, ltv INT
The following view definition is executed:
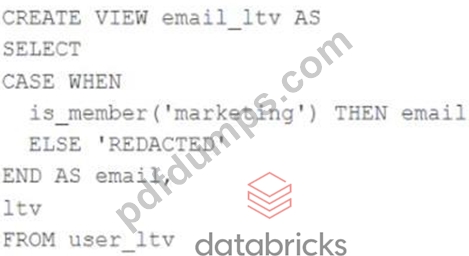
An analyst who is not a member of the marketing group executes the following query:
SELECT * FROM email_ltv
Which statement describes the results returned by this query?
- A. Three columns will be returned, but one column will be named "redacted" and contain only null values.
- B. Only the email and ltv columns will be returned; the email column will contain the string
"REDACTED" in each row. - C. The email, age. and ltv columns will be returned with the values in user ltv.
- D. The email and ltv columns will be returned with the values in user itv.
- E. Only the email and itv columns will be returned; the email column will contain all null values.
Answer: B
Explanation:
The code creates a view called email_ltv that selects the email and ltv columns from a table called user_ltv, which has the following schema: email STRING, age INT, ltv INT. The code also uses the CASE WHEN expression to replace the email values with the string "REDACTED" if the user is not a member of the marketing group. The user who executes the query is not a member of the marketing group, so they will only see the email and ltv columns, and the email column will contain the string "REDACTED" in each row.
NEW QUESTION # 247
A query is taking too long to run. After investigating the Spark UI, the data engineer discovered a significant amount of disk spill. The compute instance being used has a core-to-memory ratio of
1:2. What are the two steps the data engineer should take to minimize spillage? (Choose two.)
- A. Reduce spark.sql.files.maxPartitionBytes.
- B. Choose a compute instance with more network bandwidth.
- C. Choose a compute instance with more disk space.
- D. Choose a compute instance with a higher core-to-memory ratio.
- E. Increase spark.sql.files.maxPartitionBytes.
Answer: A,D
Explanation:
Databricks recommends addressing disk spilling--which occurs when Spark tasks run out of memory--by increasing memory per core and controlling partition size. Selecting an instance type with a higher memory-to-core ratio (A) provides each task with more available RAM, directly reducing the chance of spilling to disk. Additionally, reducing spark.sql.files.maxPartitionBytes (D) creates smaller partitions, preventing any single task from holding too much data in memory.
Increasing partition size (C) or disk capacity (B) does not solve memory bottlenecks, and bandwidth (E) affects network I/O, not spill behavior. Therefore, the correct actions are A and D.
NEW QUESTION # 248
......
After years of hard work, our Certified-Data-Engineer-Professional learning materials can take the leading position in the market. Our highly efficient operating system for learning materials has won the praise of many customers. If you are determined to purchase our Certified-Data-Engineer-Professional learning materials, we can assure you that you can receive an email from our efficient system within 5 to 10 minutes after your payment, which means that you do not need to wait a long time to experience our learning materials. Then you can start learning our Certified-Data-Engineer-Professional Learning Materials in preparation for the exam.
Certified-Data-Engineer-Professional Learning Engine: https://www.pdfdumps.com/Certified-Data-Engineer-Professional-valid-exam.html
- Certified-Data-Engineer-Professional Pdf Files 👇 Latest Certified-Data-Engineer-Professional Dumps Questions 🦦 Certified-Data-Engineer-Professional Latest Dumps Pdf 🏤 Easily obtain free download of ✔ Certified-Data-Engineer-Professional ️✔️ by searching on ▷ www.examcollectionpass.com ◁ 🥔Certified-Data-Engineer-Professional Pdf Files
- Valid Certified-Data-Engineer-Professional Exam Simulator - Certified-Data-Engineer-Professional Test Engine - Certified-Data-Engineer-Professional Study Material 🛰 [ www.pdfvce.com ] is best website to obtain 「 Certified-Data-Engineer-Professional 」 for free download 🦎Latest Certified-Data-Engineer-Professional Test Camp
- Certified-Data-Engineer-Professional Interactive Questions 🐅 Certified-Data-Engineer-Professional Latest Dumps Pdf ⚗ Certified-Data-Engineer-Professional Pdf Files 🤿 Easily obtain ➤ Certified-Data-Engineer-Professional ⮘ for free download through [ www.pdfdumps.com ] 🤹New Braindumps Certified-Data-Engineer-Professional Book
- Famous Certified-Data-Engineer-Professional Training Quiz Bring You the Topping Exam Questions - Pdfvce 🐲 Copy URL ➽ www.pdfvce.com 🢪 open and search for ▶ Certified-Data-Engineer-Professional ◀ to download for free 🖐Study Certified-Data-Engineer-Professional Group
- Exam Certified-Data-Engineer-Professional Details 🐈 Certified-Data-Engineer-Professional Latest Dumps Pdf 😄 New Braindumps Certified-Data-Engineer-Professional Book 🥕 Simply search for “ Certified-Data-Engineer-Professional ” for free download on 【 www.exam4labs.com 】 📞New Certified-Data-Engineer-Professional Test Camp
- Certified-Data-Engineer-Professional Quiz 👖 New Certified-Data-Engineer-Professional Study Notes 🍤 Certified-Data-Engineer-Professional Mock Exam 🚠 Immediately open 【 www.pdfvce.com 】 and search for { Certified-Data-Engineer-Professional } to obtain a free download ⚔New Certified-Data-Engineer-Professional Study Notes
- Precious Databricks Certified Data Engineer Professional Guide Dumps Will be Your Best Choice - www.verifieddumps.com 🤽 Easily obtain free download of ☀ Certified-Data-Engineer-Professional ️☀️ by searching on ⇛ www.verifieddumps.com ⇚ 🛵Certified-Data-Engineer-Professional Cert Guide
- Certified-Data-Engineer-Professional Passing Score Feedback 👌 Latest Certified-Data-Engineer-Professional Dumps Questions 💜 Certified-Data-Engineer-Professional Cert Guide 🐣 Search for ▶ Certified-Data-Engineer-Professional ◀ and download it for free on ✔ www.pdfvce.com ️✔️ website 🐏New Braindumps Certified-Data-Engineer-Professional Book
- Study Certified-Data-Engineer-Professional Group 🪒 Certified-Data-Engineer-Professional Pdf Files 🎅 Certified-Data-Engineer-Professional Pdf Files 🏸 Enter ▶ www.testkingpass.com ◀ and search for ▛ Certified-Data-Engineer-Professional ▟ to download for free 🥌Exam Certified-Data-Engineer-Professional Details
- Latest Certified-Data-Engineer-Professional Test Camp 🍕 Latest Certified-Data-Engineer-Professional Dumps Questions 💲 New Certified-Data-Engineer-Professional Test Camp 🎎 Search for ⇛ Certified-Data-Engineer-Professional ⇚ and easily obtain a free download on ➥ www.pdfvce.com 🡄 🎴Latest Certified-Data-Engineer-Professional Test Camp
- Valid Certified-Data-Engineer-Professional Exam Simulator - Certified-Data-Engineer-Professional Test Engine - Certified-Data-Engineer-Professional Study Material 🏉 Simply search for ➥ Certified-Data-Engineer-Professional 🡄 for free download on ▛ www.vce4dumps.com ▟ 🅱Study Certified-Data-Engineer-Professional Group
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
2026 Latest PDFDumps Certified-Data-Engineer-Professional PDF Dumps and Certified-Data-Engineer-Professional Exam Engine Free Share: https://drive.google.com/open?id=12VtarPwAZmc6PV1x69iYhLoSya_4m2Sn