Microsoft的DP-800考試認證,PDFExamDumps是當前最新Microsoft的DP-800考試認證和考題準備問題提供認證的候選人中的佼佼者,我們資源不斷被修訂和更新,具有緊密的相關性和緊密性,今天你準備Microsoft的DP-800認證,你將要選擇你要開始的訓練,而且要通過你下一次的考題,由於我們大部分考題是每月更新一次,你將得到最好的資源與市場的新鮮品質和可靠性的保證。
| Section | Objectives |
|---|---|
| Integrate AI capabilities with database systems | - Use Azure AI services with database workloads - Implement AI-assisted data processing |
| Develop and manage database solutions | - Ensure security and compliance of data solutions - Optimize performance and scalability |
| Monitor, troubleshoot, and maintain solutions | - Troubleshooting data pipeline issues - Monitoring database health and performance |
| Design and implement data solutions | - Implement data storage and data processing solutions - Design database solutions using Azure data services |
我們PDFExamDumps Microsoft的DP-800考試認證培訓資料可以實現你的夢想,因為它包含了一切需要通過的Microsoft的DP-800考試認證,有了PDFExamDumps,你們將風雨無阻,全身心投入應戰。有了我們PDFExamDumps的提供的高品質高品質的培訓資料,保證你通過考試,給你準備一個光明的未來。
問題 #38
You are creating a table that will store customer profiles.
You have the following Transact-SQL code.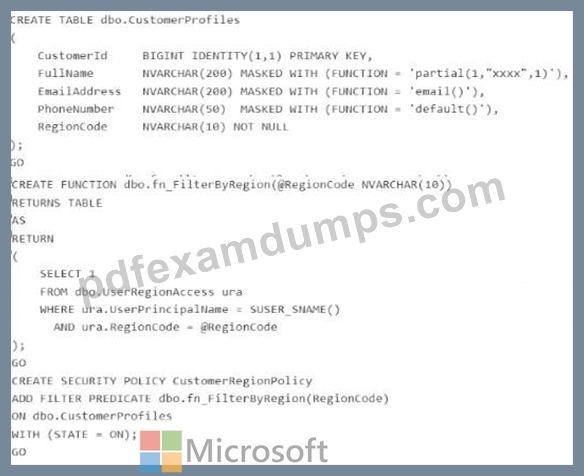
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection Is worth one point.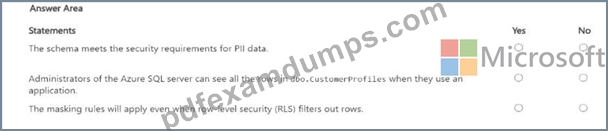
答案:
解題說明: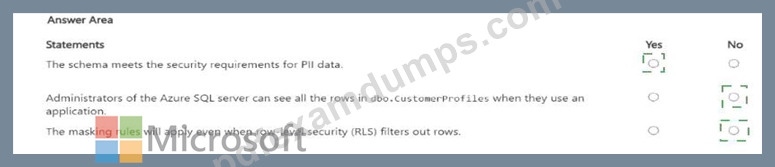
Explanation:
* The schema meets the security requirements for PII data. # Yes
* Administrators of the Azure SQL server can see all the rows in dbo.CustomerProfiles when they use an application. # No
* The masking rules will apply even when row-level security (RLS) filters out rows. # No The first statement is Yes because the design combines two relevant SQL security controls for personally identifiable information: Dynamic Data Masking (DDM) on sensitive columns such as FullName, EmailAddress, and PhoneNumber, and Row-Level Security (RLS) to restrict which rows a user can access based on RegionCode. Microsoft documents that DDM limits sensitive data exposure for nonprivileged users
, while RLS restricts row access according to the user executing the query. Together, these are valid and appropriate controls for protecting PII in Azure SQL Database.
The second statement is No . Administrative users can view unmasked data because administrative roles effectively have CONTROL, which includes UNMASK. However, that does not mean they automatically see all rows through the application query path defined by the RLS policy. The security policy filters rows based on SUSER_SNAME() and matching RegionCode, so row visibility is governed by the predicate unless the policy is altered or bypassed administratively. DDM and RLS solve different problems: DDM affects how returned values are shown, while RLS affects which rows are returned at all.
The third statement is No because masking only applies to data that is actually returned in the query result set.
Microsoft describes DDM as hiding sensitive data in the result set of a query . If RLS filters a row out, that row is not returned, so there is nothing left for masking to act on. In other words, RLS eliminates inaccessible rows first from the user's perspective, and DDM masks sensitive column values only on rows the user is allowed to see.
問題 #39
You need to recommend a solution that will resolve the ingestion pipeline failure issues. Which two actions should you recommend? Each correct answer presents part of the solution. NOTE: Each correct selection is worth one point.
答案:B,E
解題說明:
The two correct actions are D and E because the ingestion failures are caused by malformed JSON and duplicate payloads, and these two controls address those two problems directly. Microsoft's JSON documentation states that SQL Server and Azure SQL support validating JSON with ISJSON, and Microsoft specifically recommends using a CHECK constraint to ensure JSON text stored in a column is properly formatted.
For the duplicate-payload issue, creating a unique index on a hash of the payload is the appropriate design.
Microsoft documents using hashing functions such as HASHBYTES to hash column values, and SQL Server allows a deterministic computed column to be used as a key column in a UNIQUE constraint or unique index.
That makes a persisted hash-based computed column plus a unique index a practical and exam-consistent way to reject duplicate payloads efficiently.
The other options do not solve the stated root causes:
Snapshot isolation addresses concurrency behavior, not malformed JSON or duplicate payload detection.
A trigger to rewrite malformed JSON is not the right integrity control and is brittle.
Foreign key constraints enforce referential integrity, not JSON validity or duplicate-payload prevention
問題 #40
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a SQL database in Microsoft Fabric that contains a table named dbo.Orders.
dbo.Orders has a clustered index, contains three years of data, and is partitioned by a column named OrderDate by month.
You need to remove all the rows for the oldest month. The solution must minimize the impact on other queries that access the data in dbo.Orders.
Solution: Run the following Transact-SQL statement.
DELETE FROM dbo.Orders
WHERE OrderDate < DATEADD(month, -36, SYSUTCDATETIME());
Does this meet the goal?
答案:B
解題說明:
Correct:
* Identify the partition number for the oldest month, and then run the following Transact-SQL statement.
TRUNCATE TABLE dbo.Orders
WITH (PARTITIONS (partition number));
The best Transact-SQL statement to remove all rows for the oldest month while minimizing the impact on other queries is TRUNCATE TABLE with a WITH (PARTITIONS (...)) clause.
Why TRUNCATE TABLE ... WITH (PARTITIONS (...)) is Best
Efficiency: TRUNCATE TABLE is a Data Definition Language (DDL) operation that removes data by deallocating the data pages, which is a metadata operation and is very fast, regardless of the amount of data in the partition.
Minimal Logging: It uses less transaction log space compared to a DELETE statement, which logs each row deletion individually.
Low Impact on Concurrency: It performs a quick, partition-specific operation. A row-by-row DELETE would be a long-running transaction and could cause locking and blocking issues for other queries accessing the table.
Data Integrity: Because the table has a clustered index and is partitioned by the same column (aligned indexes), the TRUNCATE PARTITION operation is a fast, partition-level maintenance operation that targets only that specific data subset.
Incorrect:
* : Identify the partition scheme for the oldest month, and then run the following Transact-SQL statement.
ALTER TABLE dbo.Orders
DROP PARTITION SCHEME (partition_scheme_name);
The DROP PARTITION SCHEME statement removes the partition scheme object from the database but does not remove the data itself or free up the space, and it requires all tables to be moved off the scheme first, which is a complex operation. This does not meet the goal of removing the data efficiently.
* Run the following Transact-SQL statement.
DELETE FROM dbo.Orders
WHERE OrderDate < DATEADD(month, -36, SYSUTCDATETIME());
A standard DELETE statement, even with a WHERE clause that uses the partition column, can be a time-consuming, logged operation that causes locking and blocking on the main table, negatively impacting performance.
Reference:
https://stackoverflow.com/questions/63632963/truncate-partition-vs-drop-partition-performace- wise-which-one-is-efficient-an
問題 #41
You have a GitHub Actions workflow that builds and deploys an Azure SQL database. The schema is stored in a GitHub repository as an SDK-style SQL database project.
Following a code review, you discover that you need to generate a report that shows whether the production schema has diverged from the model in source control.
Which action should you add to the pipeline?
答案:C
解題說明:
Microsoft documents that DriftReport creates an XML report showing changes that have been made to the registered database since it was last registered . That is the action intended to detect whether the production schema has diverged from the expected model baseline in your deployment workflow.
This is different from DeployReport , which shows the changes that would be made by a publish action . In other words:
* DriftReport answers: Has the deployed database drifted from the registered state/model?
* DeployReport answers: What changes would be applied if I published now?
The other options are not the right fit:
* Extract creates a DACPAC from an existing database, not a drift analysis report.
* Script generates a deployment script, not a schema-drift report.
So to generate a report that shows whether production has diverged from the model in source control , add:
SqlPackage.exe /Action:DriftReport
問題 #42
You have an Azure SQL database that contains the following SQL graph tables:
* A NODE table named dbo.Person
* An EDGE table named dbo.Knows
Each row in dbo.Person contains the following columns:
* Personid (int)
* DisplayName (nvarchar(100))
You need to use a HATCH operator and exactly two directed Knows relationships to return the Personid and DisplayName of people that are reachable from the person identified by an input parameter named
@startPersonid.
Which Transact-SQL query should you use?
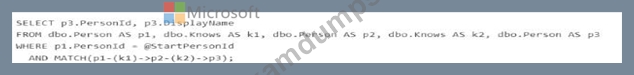
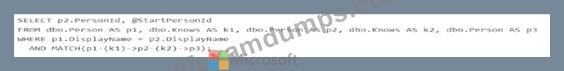
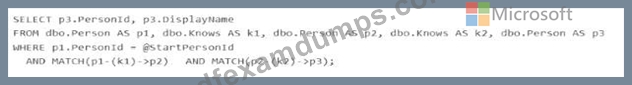
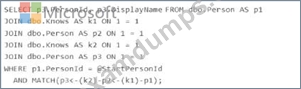
答案:A
解題說明:
The correct query is Option D because it starts from the input person and uses exactly two directed Knows edges in a single MATCH pattern:
MATCH(p1-(k1)- > p2-(k2)- > p3)
Microsoft documents that SQL Graph uses the MATCH predicate in the WHERE clause to express graph traversal patterns over node and edge tables, and directed relationships are written with arrow syntax such as node1-(edge)- > node2.
Why D is correct:
* It anchors the starting node with p1.PersonId = @StartPersonId.
* It traverses two directed hops : p1 - > p2 - > p3.
* It returns p3.PersonId, p3.DisplayName, which are the people reachable in exactly two Knows relationships.
Why the others are wrong:
* A filters on DisplayName = DisplayName, which is unrelated to the required input parameter and does not correctly anchor the start node.
* B reverses the traversal direction in the pattern.
* C uses two separate MATCH predicates instead of the required single two-hop directed pattern. The proper graph pattern syntax supports chaining the hops directly in one MATCH expression.
Topic 1, Contoso Case Study
Existing Environment
Contoso has an Azure subscription in North Europe that contains the corporate infrastructure. The current infrastructure contains a Microsoft SQL Server 2017 database. The database contains the following tables.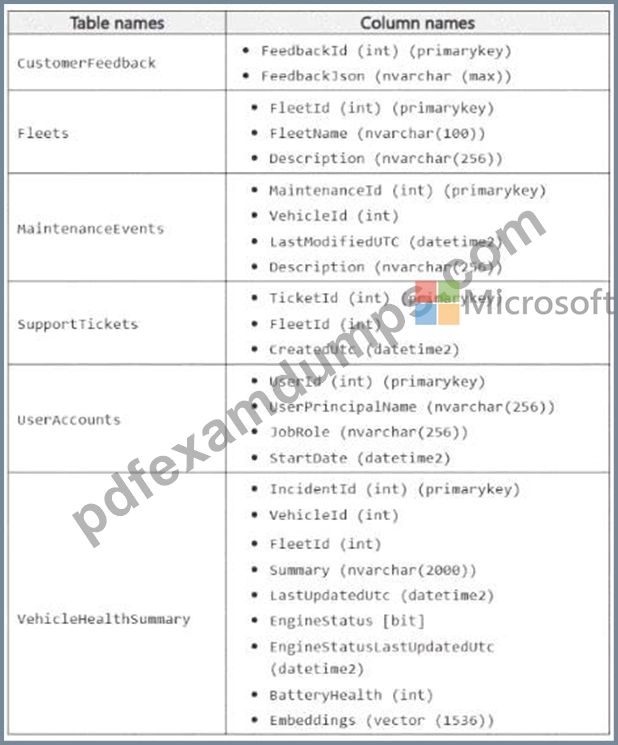
The FeedbackJson column has a full-text index and stores JSON documents in the following format.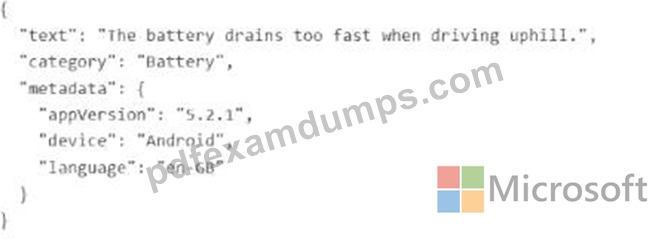
The support staff at Contoso never has the unmask permission.
Requirements
Contoso is deploying a new Azure SQL database that will become the authoritative data store for the following;
* Al workloads
* Vector search
* Modernized API access
* Retrieval Augmented Generation (RAG) pipelines
Sometimes the ingestion pipeline fails due to malformed JSON and duplicate payloads.
The engineers at Contoso report that the following dashboard query runs slowly.
SELECT VehicleTd, Lastupdatedutc, EngineStatus, BatteryHealth FROM dbo.VehicleHealthSumary where fleetld - gFleetld ORDER BV LastUpdatedUtc DESC; You review the execution plan and discover that the plan shows a clustered index scan.
vehicleincidentReports often contains details about the weather, traffic conditions, and location. Analysts report that it is difficult to find similar incidents based on these details.
Planned Changes
Contoso wants to modernize Fleet Intelligence Platform to support Al-powered semantic search over incident reports.
Security Requirements
Contoso identifies the following telemetry requirements:
* Telemetry data must be stored in a partitioned table.
* Telemetry data must provide predictable performance for ingestion and retention operations.
* latitude, longitude, and accuracy JSON properties must be filtered by using an index seek.
Contoso identifies the following maintenance data requirements:
* Ensure that any changes to a row in the MaintenanceEvents table updates the corresponding value in the LastModif reduce column to the time of the change.
* Avoid recursive updates.
AI Search, Embedding's, and Vector indexing
The development learn at Contoso will use Microsoft Visual Studio Code and GitHub Copilot and will retrieve live metadata from the databases. Contoso identifies the following requirements for querying data in the FeedbackJson column of the customer-Feedback table:
* Extract the customer feedback text from the JSON document.
* Filter rows where the JSON text contains a keyword.
* Calculate a fuzzy similarity score between the feedback text and a known issue description.
* Order the results by similarity score, with the highest score first.
問題 #43
......
PDFExamDumps幫助過許多參加IT認定考試的人。也從考生那裏得到了很好的評價。PDFExamDumps的資料的通過率達到100%,這也是經過很多考生驗證過的事實。如果你因為準備Microsoft的DP-800考試而感到很累的話,那麼你千萬不能錯過PDFExamDumps的DP-800資料。因為這是個高效率的準備考試的工具。它可以讓你得到事半功倍的結果。
DP-800認證指南: https://www.pdfexamdumps.com/DP-800_valid-braindumps.html