CCDAK퍼펙트덤프자료 - CCDAK퍼펙트인증공부

그리고 Itexamdump CCDAK 시험 문제집의 전체 버전을 클라우드 저장소에서 다운로드할 수 있습니다: https://drive.google.com/open?id=1545u3GPzRstf-hDzIP0YCkdjWI9BgITj
Itexamdump는 여러분의 요구를 만족시켜드리는 사이트입니다. 많은 분들이 우리사이트의 it인증덤프를 사용함으로 관련it시험을 안전하게 패스를 하였습니다. 이니 우리 Itexamdump사이트의 단골이 되었죠. Itexamdump에서는 최신의Confluent CCDAK자료를 제공하며 여러분의Confluent CCDAK인증시험에 많은 도움이 될 것입니다.
Confluent CCDAK Exam Syllabus Topics:
| Section | Objectives |
|---|
| Topic 1: Kafka Producers and Consumers | - Consumer API
- 1. Rebalancing and offset commits
- 2. Consumer groups
- Producer API
- 1. Reliability and acknowledgments
- 2. Serialization and partitioning strategies
|
| Topic 2: Kafka Streams and Processing | - Kafka Streams API
- 1. Stream processing fundamentals
- 2. Stateful vs stateless processing
- Event processing patterns
- 1. Windowing and aggregation
- 2. Exactly-once semantics
|
| Topic 3: Kafka Ecosystem and Confluent Platform | - ksqlDB and connectors
- 1. Kafka Connect basics
- 2. Stream querying concepts
- Schema Registry
- 1. Avro, Protobuf, JSON Schema usage
|
| Topic 4: Kafka Fundamentals | - Kafka architecture and core concepts
- 1. Replication and fault tolerance
- 2. Brokers, topics, partitions
- Data flow in Kafka
- 1. Producer and consumer model
- 2. Offset management
|
>> CCDAK퍼펙트 덤프자료 <<
CCDAK퍼펙트 덤프자료 - 높은 통과율 Confluent Certified Developer for Apache Kafka Certification Examination퍼펙트 인증공부 덤프로 시험에 패스하여 자격증 취득하기
Itexamdump는 아주 믿을만하고 서비스 또한 만족스러운 사이트입니다. 만약 CCDAK시험실패 시 우리는 100% 덤프비용 전액환불 해드립니다.그리고 시험을 패스하여도 우리는 일 년 동안 무료업뎃을 제공합니다.
최신 Confluent Certified Developer CCDAK 무료샘플문제 (Q37-Q42):
질문 # 37
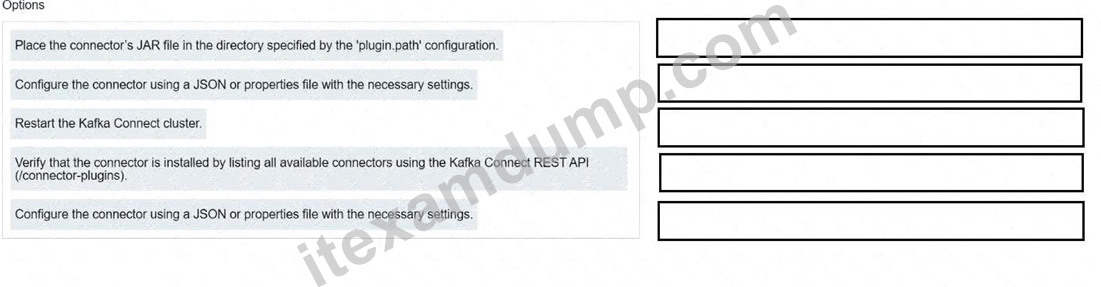
Match each configuration parameter with the correct deployment step in installing a Kafka connector.
정답:
설명:
Explanation:
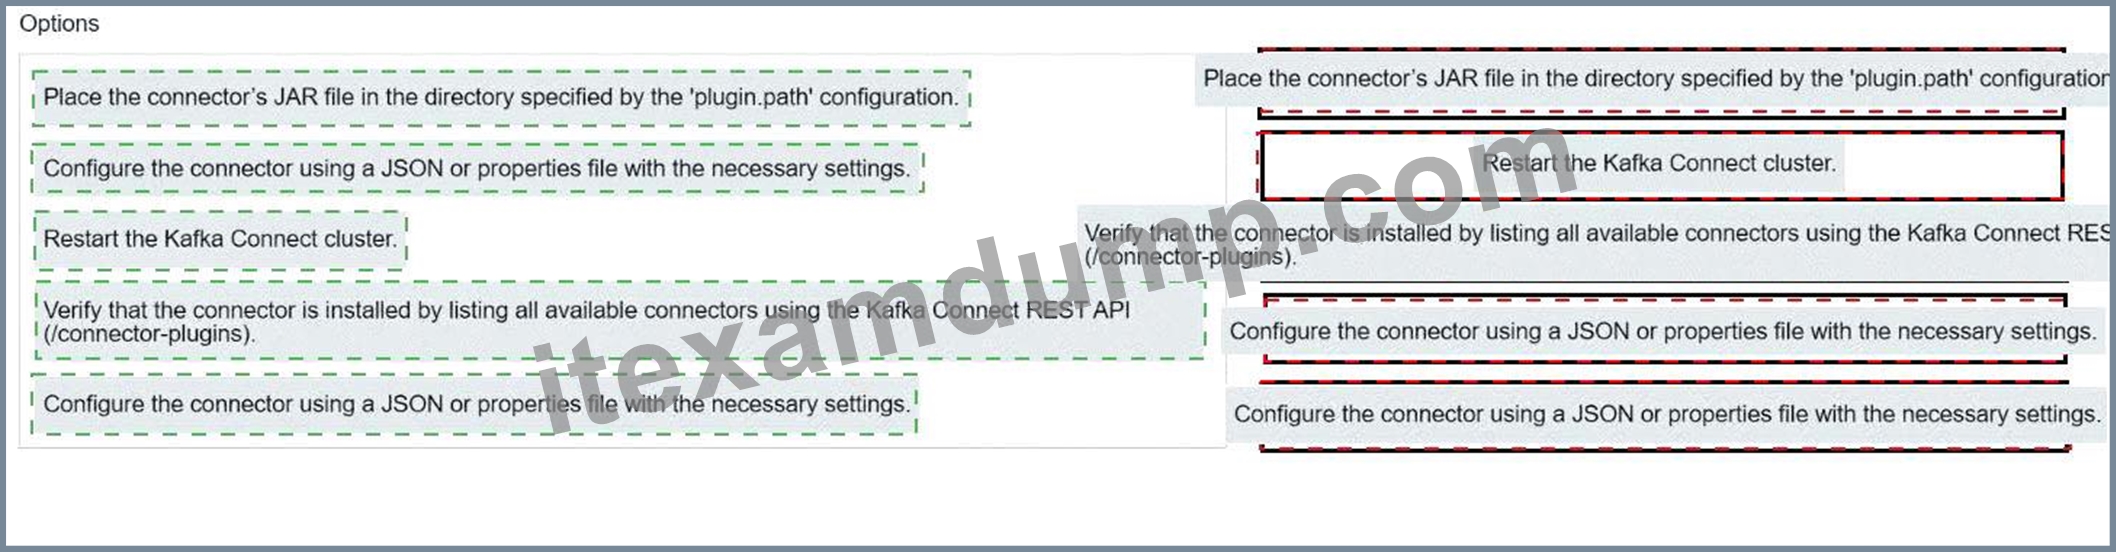
* 1st:Place the connector's JAR file in the directory specified by plugin.path
* 2nd:Restart the Kafka Connect cluster
* 3rd:Verify using REST API (/connector-plugins)
* 4th:Configure the connector
* 5th:(Repeat of 4th, duplicate step)
1st # Place the connector's JAR file in the directory specified by the plugin.path configuration.
2nd # Restart the Kafka Connect cluster.
3rd # Verify that the connector is installed by listing all available connectors using the Kafka Connect REST API (/connector-plugins).
4th # Configure the connector using a JSON or properties file with the necessary settings.
5th # Configure the connector using a JSON or properties file with the necessary settings.
Kafka Connect requires that custom connectors be placed in the directory defined by plugin.path. After restarting the cluster, you can use the REST API to confirm availability and then deploy the connector configuration.
FromKafka Connect Documentation:
"After placing the JAR in the plugin.path, you must restart the Connect cluster to pick it up. Use the
/connector-plugins REST endpoint to verify."
The duplication of configuration is an error in the question options and should occur only once.
Reference:Kafka Connect Plugin Installation Guide
질문 # 38
How will you set the retention for the topic named my-topic to 1 hour?
- A. Set the producer config retention.ms to 3600000
- B. Set the consumer config retention.ms to 3600000
- C. Set the broker config log.retention.ms to 3600000
- D. Set the topic config retention.ms to 3600000
정답:D
설명:
retention.ms can be configured at topic level while creating topic or by altering topic. It shouldn't be set at the broker level (log.retention.ms) as this would impact all the topics in the cluster, not just the one we are interested in
질문 # 39
What are the requirements for a Kafka broker to connect to a Zookeeper ensemble? (select two)
- A. All the brokers must share the same broker.id
- B. Unique values for each broker's broker.id parameter
- C. Unique value for each broker's zookeeper.connect parameter
- D. All the brokers must share the same zookeeper.connect parameter
정답:B,D
설명:
Each broker must have a unique broker id and connect to the same zk ensemble and root zNode
질문 # 40
Suppose you have 6 brokers and you decide to create a topic with 10 partitions and a replication factor of 3. The brokers 0 and 1 are on rack A, the brokers 2 and 3 are on rack B, and the brokers 4 and 5 are on rack C.
If the leader for partition 0 is on broker 4, and the first replica is on broker 2, which broker can host the last replica? (select two)
정답:A,C
설명:
When you create a new topic, partitions replicas are spreads across racks to maintain availability. Hence, the Rack A, which currently does not hold the topic partition, will be selected for the last replica
질문 # 41
You need to configure a sink connector to write records that fail into a dead letter queue topic.
Requirements:
* Topic name: DLQ-Topic
* Headers containing error context must be added to the messagesWhich three configuration parameters are necessary?(Select three.)
- A. errors.tolerance=none
- B. errors.log.enable=true
- C. errors.log.include.messages=true
- D. errors.deadletterqueue.topic.name=DLQ-Topic
- E. errors.deadletterqueue.context.headers.enable=true
- F. errors.tolerance=all
정답:D,E,F
설명:
To send failed records to adead letter queue (DLQ), you must configure:
* errors.tolerance=all: Tells the connector tonot failon errors but handle them (e.g., send to DLQ).
* errors.deadletterqueue.topic.name=DLQ-Topic: Specifies the DLQ topic.
* errors.deadletterqueue.context.headers.enable=true: Includes error context in message headers.
FromKafka Connect Error Handling Docs:
"Kafka Connect supports directing problematic records to a separate topic (DLQ) using errors.* configs.
Headers can include failure metadata."
Options D, E, F are related tologging, not DLQ behavior.
Reference:Kafka Connect Configurations > Error Handling
질문 # 42
......
여러분은 우리. Itexamdump의Confluent CCDAK시험자료 즉 덤프의 문제와 답만 있으시면Confluent CCDAK인증시험을 아주 간단하게 패스하실 수 있습니다.그리고 관련 업계에서 여러분의 지위상승은 자연적 이로 이루어집니다. Itexamdump의 덤프를 장바구니에 넣으세요. 그리고 Itexamdump에서는 무료로 24시간 온라인상담이 있습니다.
CCDAK퍼펙트 인증공부: https://www.itexamdump.com/CCDAK.html
- 시험준비에 가장 좋은 CCDAK퍼펙트 덤프자료 최신버전 덤프 🅱 ⇛ www.itdumpskr.com ⇚을(를) 열고➽ CCDAK 🢪를 검색하여 시험 자료를 무료로 다운로드하십시오CCDAK시험
- CCDAK덤프최신자료 💸 CCDAK최고기출문제 🐂 CCDAK시험 📻 ▷ www.itdumpskr.com ◁을(를) 열고⇛ CCDAK ⇚를 검색하여 시험 자료를 무료로 다운로드하십시오CCDAK최고품질 덤프자료
- 시험준비에 가장 좋은 CCDAK퍼펙트 덤프자료 최신버전 덤프 👩 ⏩ www.dumptop.com ⏪에서[ CCDAK ]를 검색하고 무료 다운로드 받기CCDAK최고품질 덤프자료
- CCDAK퍼펙트 덤프자료 최신 인기 인증 시험덤프자료 📏 무료로 다운로드하려면[ www.itdumpskr.com ]로 이동하여⏩ CCDAK ⏪를 검색하십시오CCDAK시험패스 가능한 공부
- CCDAK덤프최신문제 🍡 CCDAK최신 업데이트 인증덤프자료 ➡️ CCDAK최신 업데이트버전 공부문제 👮 ➽ www.koreadumps.com 🢪에서➽ CCDAK 🢪를 검색하고 무료로 다운로드하세요CCDAK퍼펙트 최신버전 덤프샘플
- CCDAK덤프최신자료 📬 CCDAK완벽한 인증자료 🏸 CCDAK덤프최신문제 🐕 ☀ www.itdumpskr.com ️☀️의 무료 다운로드▛ CCDAK ▟페이지가 지금 열립니다CCDAK참고덤프
- CCDAK최신 덤프문제모음집 🏇 CCDAK적중율 높은 덤프 ⛹ CCDAK최고품질 덤프자료 🟦 무료로 쉽게 다운로드하려면✔ www.koreadumps.com ️✔️에서▛ CCDAK ▟를 검색하세요CCDAK덤프최신자료
- CCDAK퍼펙트 덤프자료 최신 인기 인증 시험덤프자료 🐽 { www.itdumpskr.com }에서 검색만 하면➡ CCDAK ️⬅️를 무료로 다운로드할 수 있습니다CCDAK퍼펙트 최신버전 덤프샘플
- CCDAK완벽한 인증자료 🦽 CCDAK덤프최신자료 🙎 CCDAK참고덤프 ⏰ ⏩ CCDAK ⏪를 무료로 다운로드하려면➥ www.pass4test.net 🡄웹사이트를 입력하세요CCDAK최고품질 덤프자료
- CCDAK시험대비 최신버전 덤프샘플 🧃 CCDAK최고기출문제 🕛 CCDAK시험대비 최신버전 덤프샘플 🤪 무료로 쉽게 다운로드하려면⮆ www.itdumpskr.com ⮄에서✔ CCDAK ️✔️를 검색하세요CCDAK최신 업데이트버전 공부문제
- CCDAK최신 업데이트버전 공부문제 😃 CCDAK덤프최신문제 ⛺ CCDAK덤프최신자료 👊 ✔ www.pass4test.net ️✔️을 통해 쉽게⏩ CCDAK ⏪무료 다운로드 받기CCDAK덤프문제집
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, hashnode.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
그 외, Itexamdump CCDAK 시험 문제집 일부가 지금은 무료입니다: https://drive.google.com/open?id=1545u3GPzRstf-hDzIP0YCkdjWI9BgITj