BONUS!!! Download part of Actual4Labs Professional-Machine-Learning-Engineer dumps for free: https://drive.google.com/open?id=1YCi2JOTZgjOsr4HX3YbhHzBiTtzzFTR_
The Google Professional-Machine-Learning-Engineer exam PDF is the collection of real, valid, and updated Google Professional-Machine-Learning-Engineer practice questions. The Google Professional-Machine-Learning-Engineer PDF dumps file works with all smart devices. You can use the Professional-Machine-Learning-Engineer PDF Questions on your tablet, smartphone, or laptop and start Professional-Machine-Learning-Engineer exam preparation anytime and anywhere.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Scale prototypes into AI models | 18% | - Select appropriate model architectures and frameworks - Design and run experiments - Work with foundation models and generative AI techniques - Optimize model performance and generalization |
| Topic 2: Automate and orchestrate ML pipelines | 18% | - Design end-to-end ML workflows - Implement CI/CD for ML systems - Use Vertex AI Pipelines, TFX, and other orchestration tools - Automate retraining and model updates |
| Topic 3: Train and deploy models | 20% | - Use Vertex AI deployment features and infrastructure - Implement generative AI deployment patterns - Configure training jobs and environments - Deploy models for online, batch, and streaming prediction |
| Topic 4: Monitor and optimize AI solutions | 16% | - Monitor model performance, fairness, and drift - Troubleshoot and maintain production systems - Monitor data quality and pipeline health - Optimize cost, latency, and resource usage |
| Topic 5: Collaborate to manage data and models | 16% | - Manage datasets and features in Vertex AI - Address data privacy, compliance, and governance - Organize and prepare enterprise data
|
| Topic 6: Architect low-code AI solutions | 12% | - Identify use cases for low-code/no-code AI tools - Design solutions using Vertex AI Studio, Model Garden, and Agent Builder - Apply responsible AI principles to low-code designs |
>> Braindumps Professional-Machine-Learning-Engineer Pdf <<
Are you looking for a reliable product for the Professional-Machine-Learning-Engineer exam? If you do, our product will be your best choice. The reference materials of our company are edited by skilled experts and profestionals who are quite famialiar with the latest exam and testing center for yaers, therefore the quality of the practice materials for the Professional-Machine-Learning-Engineer exam is guaranteed. Besides the practice material provide the demo, and you can have a try before you buy it,and the questions and answers online of the practice materials for theProfessional-Machine-Learning-Engineer Exam can also be seen. If you just wan to test yourself, you can can conceal it, after you finish it , yon can seen the answers by canceling the conceal. It's quite convenient and effective.
NEW QUESTION # 245
Your team is working on an NLP research project to predict political affiliation of authors based on articles they have written. You have a large training dataset that is structured like this:
You followed the standard 80%-10%-10% data distribution across the training, testing, and evaluation subsets. How should you distribute the training examples across the train-test-eval subsets while maintaining the 80-10-10 proportion?


Answer: C
Explanation:
The best way to distribute the training examples across the train-test-eval subsets while maintaining the 80-
10-10 proportion is to use option C. This option ensures that each subset contains a balanced and representative sample of the different classes (Democrat and Republican) and the different authors. This way, the model can learn from a diverse and comprehensive set of articles and avoid overfitting or underfitting.
Option C also avoids the problem of data leakage, which occurs when the same author appears in more than one subset, potentially biasing the model and inflating its performance. Therefore, option C is the most suitable technique for this use case.
NEW QUESTION # 246
You are investigating the root cause of a misclassification error made by one of your models. You used Vertex Al Pipelines to tram and deploy the model. The pipeline reads data from BigQuery. creates a copy of the data in Cloud Storage in TFRecord format trains the model in Vertex Al Training on that copy, and deploys the model to a Vertex Al endpoint. You have identified the specific version of that model that misclassified: and you need to recover the data this model was trained on. How should you find that copy of the data ' ?
Answer: C
Explanation:
* Option A is not the best answer because it requires modifying the pipeline to use the Vertex AI Feature Store, which may not be feasible or necessary for recovering the data that the model was trained on. The Vertex AI Feature Store is a service that helps you manage, store, and serve feature values for your machine learning models 1 , but it is not designed for storing the raw data or the TFRecord files.
* Option B is the best answer because it leverages the lineage feature of Vertex AI Metadata , which is a service that helps you track and manage the metadata of your machine learning workflows, such as datasets, models, metrics, and parameters 2 . The lineage feature allows you to view the relationships and dependencies among the artifacts and executions in your pipeline, and trace back the origin and history of any artifact 3 . By using the lineage feature, you can find the model artifact, determine the version of the model, identify the step that creates the data copy, and search in the metadata for its location.
* Option C is not the best answer because it relies on the logging features in the Vertex AI endpoint, which may not be accurate or reliable for finding the data copy. The logging features in the Vertex AI endpoint help you monitor and troubleshoot the onl ine predictions made by your deployed models, but they do not provide information about the training data or the pipeline steps 4 . Moreover, the timestamp of the model deployment may not match the timestamp of the pipeline run, as there may be delays or errors in the deployment process.
* Option D is not the best answer because it requires finding the job ID in Vertex AI Training, which may not be easy or straightforward. Vertex AI Training is a service that helps you train your custom models on Google Cloud, but it does not provide a direct way to link the training job to the model version or the pipeline run. Moreover, searching in the logs of the job may not reveal the location of the data copy, as the logs may only contain information about the training process and the metrics.
:
1 : Introduction to Vertex AI Feature Store | Vertex AI | Google Cloud
2 : Introduction to Vertex AI Metadata | Vertex AI | Google Cloud
3 : View lineage for ML workflows | Vertex AI | Google Cloud
4 : Monitor online predictions | Vertex AI | Google Cloud
[5]: Train custom models | Vertex AI | Google Cloud
NEW QUESTION # 247
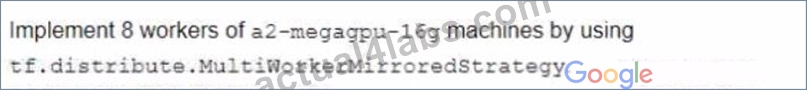
You are pre-training a large language model on Google Cloud. This model includes custom TensorFlow operations in the training loop Model training will use a large batch size, and you expect training to take several weeks You need to configure a training architecture that minimizes both training time and compute costs What should you do?



Answer: D
NEW QUESTION # 248
Your company manages a video sharing website where users can watch and upload videos. You need to create an ML model to predict which newly uploaded videos will be the most popular so that those videos can be prioritized on your company's website. Which result should you use to determine whether the model is successful?
Answer: A
Explanation:
In this scenario, the goal is to create an ML model to predict which newly uploaded videos will be the most popular on a video sharing website. The result that should be used to determine whether the model is successful is the one that best aligns with the business objective and the evaluation metric. Option C is the correct answer because it defines the most popular videos as the ones that have the highest watch time within
30 days of being uploaded, and it sets a high accuracy threshold of 95% for the model prediction.
Option C: The model predicts 95% of the most popular videos measured by watch time within 30 days of being uploaded. This option is the best result for the scenario because it reflects the business objective and the evaluation metric. The business objective is to prioritize the videos that will attract and retain the most viewers on the website. The watch time is a good indicator of the viewer engagement and satisfaction, as it measures how long the viewers watch the videos. The 30-day window is a reasonable time frame to capture the popularity trend of the videos, as it accounts for the initial interest and the viral potential of the videos. The
95% accuracy threshold is a high standard for the model prediction, as it means that the model can correctly identify 95 out of 100 of the most popular videos based on the watch time metric.
Option A: The model predicts videos as popular if the user who uploads them has over 10,000 likes. This option is not a good result for the scenario because it does not reflect the business objective or the evaluation metric. The business objective is to prioritize the videos that will be the most popular on the website, not the users who upload them. The number of likes that a user has is not a good indicator of the popularity of their videos, as it does not measure the viewer engagement or satisfaction with the videos. Moreover, this option does not specify a time frame or an accuracy threshold for the model prediction, making it vague and unreliable.
Option B: The model predicts 97.5% of the most popular clickbait videos measured by number of clicks. This option is not a good result for the scenario because it does not reflect the business objective or the evaluation metric. The business objective is to prioritize the videos that will be the most popular on the website, not the videos that have the most misleading or sensational titles or thumbnails. The number of clicks that a video has is not a good indicator of the popularity of the video, as it does not measure the viewer engagement or satisfaction with the video content. Moreover, this option only focuses on the clickbait videos, which may not represent the majority or the diversity of the videos on the website.
Option D: The Pearson correlation coefficient between the log-transformed number of views after 7 days and
30 days after publication is equal to 0. This option is not a good result for the scenario because it does not reflect the business objective or the evaluation metric. The business objective is to prioritize the videos that will be the most popular on the website, not the videos that have the most consistent or inconsistent number of views over time. The Pearson correlation coefficient is a metric that measures the linear relationship between two variables, not the popularity of the videos. A correlation coefficient of 0 means that there is no linear relationship between the log-transformed number of views after 7 days and 30 days, which does not indicate whether the videos are popular or not. Moreover, this option does not specify a threshold or a target value for the correlation coefficient, making it meaningless and irrelevant.
NEW QUESTION # 249
Your team is building an application for a global bank that will be used by millions of customers.
You built a forecasting model that predicts customers' account balances 3 days in the future.
Your team will use the results in a new feature that will notify users when their account balance is likely to drop below $25. How should you serve your predictions?
Answer: A
Explanation:
Firebase is designed for exactly this sort of scenario. Also, it would not be possible to create millions of pubsub topics due to GCP quotas
https://cloud.google.com/pubsub/quotas#quotas
https://firebase.google.com/docs/cloud-messaging
NEW QUESTION # 250
......
Our company have the higher class operation system than other companies, so we can assure you that you can start to prepare for the Professional-Machine-Learning-Engineer exam with our study materials in the shortest time. In addition, if you decide to buy the Professional-Machine-Learning-Engineer study materials from our company, we can make sure that your benefits will far exceed the costs of you. The rate of return will be very obvious for you. We sincerely reassure all people on the Professional-Machine-Learning-Engineer Study Materials from our company and enjoy the benefits that our study materials bring.
Professional-Machine-Learning-Engineer Reliable Braindumps Pdf: https://www.actual4labs.com/Google/Professional-Machine-Learning-Engineer-actual-exam-dumps.html
BONUS!!! Download part of Actual4Labs Professional-Machine-Learning-Engineer dumps for free: https://drive.google.com/open?id=1YCi2JOTZgjOsr4HX3YbhHzBiTtzzFTR_