BONUS!!! 免費下載VCESoft SPS-C01考試題庫的完整版:https://drive.google.com/open?id=122ibdhEubsmTCilzGB2Y1DojRCKaag5V
在如今時間那麼寶貴的社會裏,我建議您來選擇VCESoft為您提供的短期培訓,你可以花少量的時間和金錢就可以通過您第一次參加的Snowflake SPS-C01 認證考試。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Snowpark Concepts | 15% | - Snowpark architecture and core concepts - Snowpark Sessions and connection management - Snowpark DataFrames and query plans - Stored procedures and conditional logic - Transformations vs. Actions - Client-side vs. Server-side execution |
| Topic 2: Snowpark API for Python | 30% | - Establishing connections and session management - Working with Semi-structured data - DataFrame creation and manipulation - Reading and writing data - User-Defined Functions (UDFs) and Stored Procedures |
| Topic 3: Data Transformations and DataFrame Operations | 35% | - Using built-in functions - Complex data pipelines - Persisting transformed data - Filtering, Aggregating, and Joining DataFrames - Window functions |
| Topic 4: Performance Optimization and Best Practices | 20% | - Minimizing data transfer - Vectorized UDFs - Debugging and explain plans - Caching strategies - Query pushdown and optimization - Warehouse sizing for Snowpark |
VCESoft是一個可以成就很多IT人士的夢想的網站。VCESoft能為參加IT相關認證考試的考生提供他們想要的資料來助幫助他們通過考試。你還在為通過Snowflake SPS-C01認證考試苦惱嗎?你有想過購買Snowflake SPS-C01認證考試相關的課程來輔助你嗎?VCESoft可以為你提供這個便利,VCESoft提供的培訓資料可以有效地幫你通過認證考試。VCESoft提供的練習題幾乎真題是一樣的。有了VCESoft為你提供的精確的Snowflake SPS-C01認證考試的練習題和答案,你可以以高分通過Snowflake SPS-C01認證考試。
問題 #223
You have a Snowpark DataFrame 'product_df and you want to create a view named 'active_products' that only includes products with a 'status' column value equal to 'ACTIVE'. This view should be accessible to all users in the 'PUBLIC' role. Which of the following code snippets correctly creates the view and grants the necessary privileges?





答案:B
解題說明:
Option C correctly creates a persistent view ('createOrReplaceView') and then grants the 'SELECT privilege to the 'PUBLIC' role. A temporary view (option B) is session-scoped and wouldn't be accessible to other users or sessions, even with a grant. Option D does not work as Global temporary views created using Snowpark API is not a supported feature..Option E does not apply the filter condition to the View.
問題 #224
You are developing a Snowpark application that uses a Python UDF to perform geocoding operations. This UDF relies on a third-party geocoding library and a large dataset of geographical data stored in a file named 'geodata.db'. The UDF needs to be operationalized with minimal latency. Which of the following strategies will result in the FASTEST execution of the UDF and optimal resource utilization?
答案:D
解題說明:
Option E is the most efficient strategy. Packaging the library and data file in a ZIP, referencing it with 'imports' , and using a global variable with caching within the UDF minimizes latency by loading the data only once per worker. It also benefits from utilizing the parallel processing capabilities of Snowpark. Using Java UDF's (C) is less efficient, unless it is highly optimized since java conversion can happen and adds overhead . Relying on external geocoding services (D) introduces network latency and is not ideal for performance. While a custom Anaconda channel (B) can simplify dependency management, it does not address the issue of loading the large 'geodata.db' file efficiently. Option A addresses the dependency managment but performance is not addressed.
問題 #225
A Snowpark Python application is experiencing significant performance degradation when processing a large dataset (100GB+) stored in Snowflake. The application performs a complex series of transformations, including window functions and joins with smaller lookup tables. You suspect data skew is contributing to the issue. Which of the following strategies would be MOST effective in mitigating the impact of data skew and improving performance?
答案:E
解題說明:
Salting or pre-partitioning addresses data skew directly by distributing the skewed values more evenly across partitions. Increasing warehouse size (A) might help to some extent but doesn't solve the underlying skew issue. Broadcasting small tables (C) is a good optimization, but it's less effective if the larger dataset is skewed. Disabling query result caching (D) is irrelevant to data skew. Converting to Pandas (E) will likely make performance worse for large datasets due to data transfer overhead and limitations of single-node processing.
問題 #226
You are working with a Snowpark DataFrame 'products_df' that contains product information, including 'product_name', 'category', and 'price'. You need to perform several transformations: 1. Rename the 'product_name' column to 'item_name'. 2. Create a new column 'discounted_price' by applying a 10% discount to the 'price' column. 3. Filter the DataFrame to only include products in the 'Electronics' category where the 'discounted_price' is less than 100. Which of the following code sequences correctly and efficiently performs these transformations in Snowpark?





答案:E
解題說明:
Option D is the most efficient. Option D is correct because it renames the column first, then filters for 'Electronics', creates the 'discounted_price' column, and finally filters based on the discounted price being less than 100, all correctly chained. Other options will not perform transformation correctly or not follow the correct sequence.
問題 #227
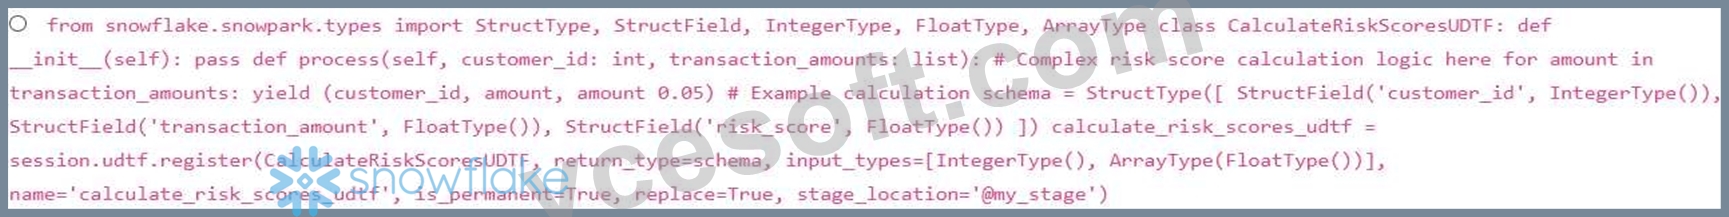
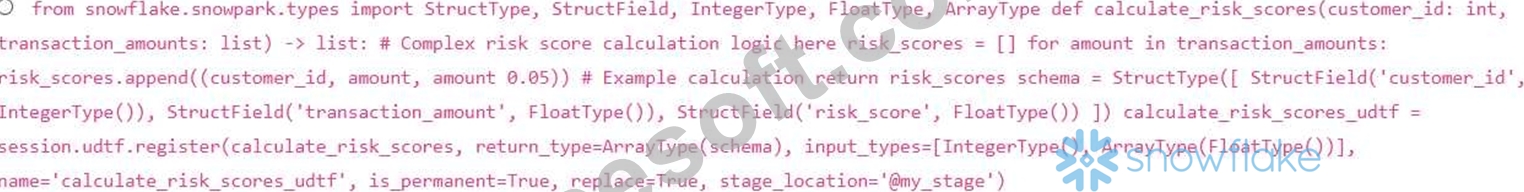
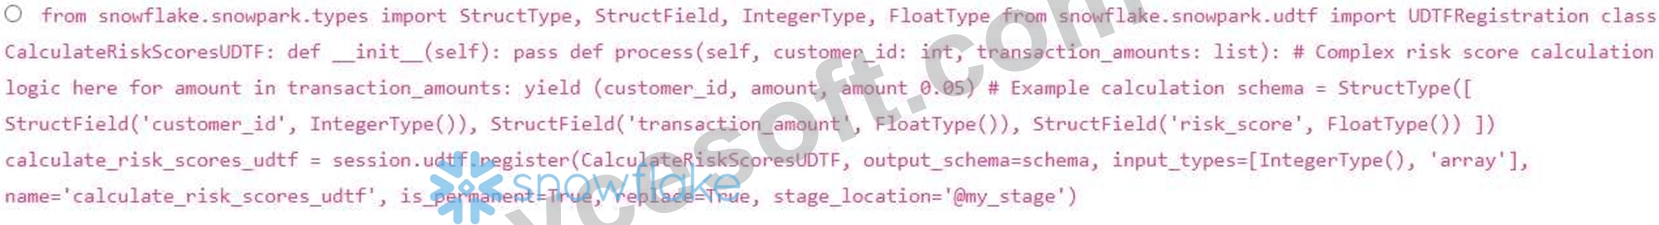
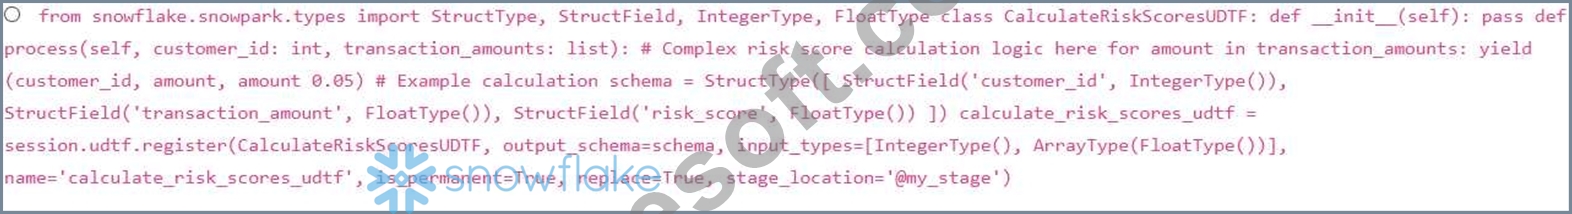
You have developed a Python function that performs complex data transformation on customer data'. You want to operationalize this function as a UDTF in Snowpark to process large datasets efficiently. The function takes a customer ID and a list of transaction amounts as input and returns a table with calculated risk scores for each transaction. Which of the following code snippets correctly defines and registers this UDTF in Snowpark, ensuring proper type handling and scalability?
答案:B
解題說明:
Options B and C correctly defines the UDTF.Option B uses return_type and option C uses output_schema, both work. Option A is incorrect because a UDTF needs to be defined as a class with a 'process' method that yields rows, not as a function that returns a list. Option D uses an incorrect way to specify ArrayType ('array') . The other options are either syntactically incorrect or do not follow the correct UDTF definition pattern.
問題 #228
......
VCESoft為你提供了一個明確而優秀的選擇,為你減少煩惱。想早點成功嗎?早點拿到Snowflake SPS-C01認證考試的證書嗎?快點將VCESoft加入購物車吧。VCESoft會給你很好的指導,能確保你通過考試。使用VCESoft你可以很快獲得你想要的證書。
SPS-C01通過考試: https://www.vcesoft.com/SPS-C01-pdf.html
從Google Drive中免費下載最新的VCESoft SPS-C01 PDF版考試題庫:https://drive.google.com/open?id=122ibdhEubsmTCilzGB2Y1DojRCKaag5V