P.S. Kostenlose 2026 Google Professional-Machine-Learning-Engineer Prüfungsfragen sind auf Google Drive freigegeben von ITZert verfügbar: https://drive.google.com/open?id=1JPUHIqG7526He50CcvhCvvxEfFGcy8KS
Unsere Prüfungsunterlage zu Google Professional-Machine-Learning-Engineer(Google Professional Machine Learning Engineer)enthältet alle echten, originalen und richtigen Fragen und Antworten. Die Abdeckungsrate unserer Unterlage (Fragen und Antworten) zu Google Professional-Machine-Learning-Engineer(Google Professional Machine Learning Engineer)ist normalerweise mehr als 98%.
| Section | Objectives |
|---|---|
| Topic 1: Data preparation and processing | - Data ingestion and pipelines
|
| Topic 2: ML model development | - Evaluation
|
| Topic 3: ML pipeline automation and orchestration | - Pipeline design
|
| Topic 4: Deployment and operations | - Monitoring and maintenance
|
| Topic 5: Designing ML solutions | - ML architecture design
|
>> Professional-Machine-Learning-Engineer Deutsche <<
Eine breite Vielzahl von Google ITZert Professional-Machine-Learning-Engineer Prüfung Fragen und AntwortenLogische ursprünglichen Exponate für ITZert Professional-Machine-Learning-Engineer Google Professional Machine Learning Engineer Prüfungsfragen100% genaue Antworten von Industrie-Experten gelöstFalls erforderlich aktualisiert Google ITZert Professional-Machine-Learning-Engineer Prüfungsfragen ITZert Professional-Machine-Learning-Engineer Fragen und Antworten sind die gleichen wie sie die Real Google Zertifizierungsprüfungen erscheinen. Viele der ITZert Professional-Machine-Learning-Engineer Google Professional Machine Learning Engineer Prüfungsvorbereitung Antworten sind in Vielfache-Wahl-Fragen (MCQs) FormatQualität geprüften Google Professional Machine Learning Engineer Produkte viele Male vor der VeröffentlichungKostenlose Demo der Prüfung ITZert Professional-Machine-Learning-Engineer an ITZert.
177. Frage
You received a training-serving skew alert from a Vertex Al Model Monitoring job running in production.
You retrained the model with more recent training data, and deployed it back to the Vertex Al endpoint but you are still receiving the same alert. What should you do?
Antwort: D
Begründung:
The best option for resolving the training-serving skew alert is to update the model monitoring job to use the more recent training data that was used to retrain the model. This option can help align the baseline distribution of the model monitoring job with the current distribution of the production data, and eliminate the false positive alerts. Model Monitoring is a service that can track and compare the results of multiple machine learning runs. Model Monitoring can monitor the model's prediction input data for feature skew and drift.
Training-serving skew occurs when the feature data distribution in production deviates from the feature data distribution used to train the model. If the original training data is available, you can enable skew detection to monitor your models for training-serving skew. Model Monitoring uses TensorFlow Data Validation (TFDV) to calculate the distributions and distance scores for each feature, and compares them with a baseline distribution. The baseline distribution is the statistical distribution of the feature's values in the training data. If the distance score for a feature exceeds an alerting threshold that you set, Model Monitoring sends you an email alert. However, if you retrain the model with more recent training data, and deploy it back to the Vertex AI endpoint, the baseline distribution of the model monitoring job may become outdated and inconsistent with the current distribution of the production data. This can cause the model monitoring job to generate false positive alerts, even if the model performance is not deteriorated. To avoid this problem, you need to update the model monitoring job to use the more recent training data that was used to retrain the model. This can help the model monitoring job to recalculate the baseline distribution and the distance scores, and compare them with the current distribution of the production data. This can also help the model monitoring job to detect any true positive alerts, such as a sudden change in the production data that causes the model performance to degrade1.
The other options are not as good as option B, for the following reasons:
* Option A: Updating the model monitoring job to use a lower sampling rate would not resolve the training-serving skew alert, and could reduce the accuracy and reliability of the model monitoring job.
The sampling rate is a parameter that determines the percentage of prediction requests that are logged and analyzed by the model monitoring job. Using a lower sampling rate can reduce the storage and computation costs of the model monitoring job, but also the quality and validity of the data. Using a lower sampling rate can introduce sampling bias and noise into the data, and make the model monitoring job miss some important features or patterns of the data. Moreover, using a lower sampling rate would not address the root cause of the training-serving skew alert, which is the mismatch between the baseline distribution and the current distribution of the production data2.
* Option C: Temporarily disabling the alert, and enabling the alert again after a sufficient amount of new production traffic has passed through the Vertex AI endpoint, would not resolve the training-serving skew alert, and could expose the model to potential risks and errors. Disabling the alert would stop the model monitoring job from sending email notifications when the distance score for a feature exceeds the
* alerting threshold, but it would not stop the model monitoring job from calculating and comparing the distributions and distance scores. Therefore, disabling the alert would not address the root cause of the training-serving skew alert, which is the mismatch between the baseline distribution and the current distribution of the production data. Moreover, disabling the alert would prevent the model monitoring job from detecting any true positive alerts, such as a sudden change in the production data that causes the model performance to degrade. This can expose the model to potential risks and errors, and affect the user satisfaction and trust1.
* Option D: Temporarily disabling the alert until the model can be retrained again on newer training data, and retraining the model again after a sufficient amount of new production traffic has passed through the Vertex AI endpoint, would not resolve the training-serving skew alert, and could cause unnecessary costs and efforts. Disabling the alert would stop the model monitoring job from sending email notifications when the distance score for a featureexceeds the alerting threshold, but it would not stop the model monitoring job from calculating and comparing the distributions and distance scores.
Therefore, disabling the alert would not address the root cause of the training-serving skew alert, which is the mismatch between the baseline distribution and the current distribution of the production data.
Moreover, disabling the alert would prevent the model monitoring job from detecting any true positive alerts, such as a sudden change in the production data that causes the model performance to degrade.
This can expose the model to potential risks and errors, and affect the user satisfaction and trust.
Retraining the model again on newer training data would create a new model version, but it would not update the model monitoring job to use the newer training data as the baseline distribution. Therefore, retraining the model again on newer training data would not resolve the training-serving skew alert, and could cause unnecessary costs and efforts1.
References:
* Preparing for Google Cloud Certification: Machine Learning Engineer, Course 3: Production ML Systems, Week 4: Evaluation
* Google Cloud Professional Machine Learning Engineer Exam Guide, Section 3: Scaling ML models in production, 3.3 Monitoring ML models in production
* Official Google Cloud Certified Professional Machine Learning Engineer Study Guide, Chapter 6:
Production ML Systems, Section 6.3: Monitoring ML Models
* Using Model Monitoring
* Understanding the score threshold slider
* Sampling rate
178. Frage
You are training an object detection model using a Cloud TPU v2. Training time is taking longer than expected. Based on this simplified trace obtained with a Cloud TPU profile, what action should you take to decrease training time in a cost-efficient way?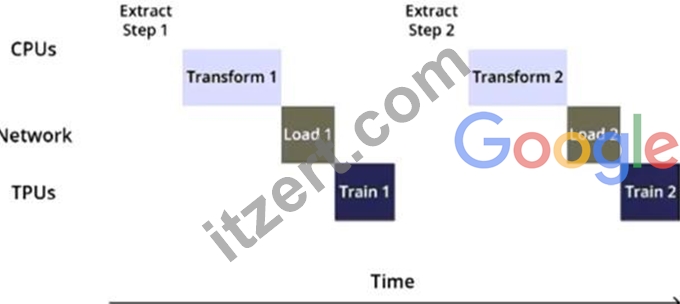
Antwort: C
Begründung:
https://www.tensorflow.org/guide/data_performance
179. Frage
You work for a gaming company that develops massively multiplayer online (MMO) games. You built a TensorFlow model that predicts whether players will make in-app purchases of more than $10 in the next two weeks. The model's predictions will be used to adapt each user's game experience. User data is stored in BigQuery. How should you serve your model while optimizing cost, user experience, and ease of management?
Antwort: B
Begründung:
The best option to serve the model while optimizing cost, user experience, and ease of management is to deploy the model to Vertex AI Prediction, which is a managed service that can scale up or down according to the demand and provide low latency and high availability. Vertex AI Prediction can also handle TensorFlow models natively, without requiring any additional steps or conversions. By using batch prediction, the model can process large volumes of data efficiently and periodically, without affecting the user experience. The data can be read from Cloud Bigtable, which is a scalable and performant NoSQL database that can store user data in a flexible schema. The predictions can then be pushed to Cloud SQL, which is a fully managed relational database that can store the predictions in a structured format and enable easy querying and analysis. This option also simplifies the management of the model and the data, as it leverages the existing Google Cloud services and does not require any additional infrastructure or code.
The other options are not optimal for the following reasons:
A . Importing the model into BigQuery ML is not a good option, as it requires converting the TensorFlow model into a format that BigQuery ML can understand, which can introduce errors and reduce the performance. Moreover, BigQuery ML is not designed for serving real-time predictions, but rather for training and evaluating models using SQL queries. Reading and writing data from BigQuery and Cloud SQL can also incur additional costs and latency, as they are both relational databases that require schema definition and data transformation.
C . Embedding the model in the mobile application is not a good option, as it increases the size and complexity of the application, and requires updating the application every time the model changes. Moreover, it exposes the model to the users, which can pose security and privacy risks, as well as potential misuse or abuse. Additionally, it does not leverage the benefits of the cloud, such as scalability, reliability, and performance.
D . Embedding the model in the streaming Dataflow pipeline is not a good option, as it requires building and maintaining a custom pipeline that can handle the model inference and data processing. This can increase the development and operational costs and complexity, as well as the potential for errors and failures. Moreover, it does not take advantage of the batch prediction feature of Vertex AI Prediction, which can optimize the resource utilization and cost efficiency.
Reference:
Professional ML Engineer Exam Guide
Preparing for Google Cloud Certification: Machine Learning Engineer Professional Certificate Google Cloud launches machine learning engineer certification Vertex AI Prediction documentation Cloud Bigtable documentation Cloud SQL documentation
180. Frage
You work for a gaming company that has millions of customers around the world. All games offer a chat feature that allows players to communicate with each other in real time. Messages can be typed in more than
20 languages and are translated in real time using the Cloud Translation API. You have been asked to build an ML system to moderate the chat in real time while assuring that the performance is uniform across the various languages and without changing the serving infrastructure.
You trained your first model using an in-house word2vec model for embedding the chat messages translated by the Cloud Translation API. However, the model has significant differences in performance across the different languages. How should you improve it?
Antwort: B
Begründung:
The problem with the current approach is that it relies on the Cloud Translation API to translate the chat messages into a common language before embedding them with the in-house word2vec model. This introduces two sources of error: the translation quality and the word2vec quality. The transla tion quality may vary across different languages, depending on the availability of data and the complexity of the grammar and vocabulary. The word2vec quality may also vary depending on the size and diversity of the corpus used to train it. These errors may affect the performance of the classifier that moderates the chat messages, resulting in significant differences across the languages.
A better approach would be to train a classifier using the chat messages in their original language, without relying on the Cloud Translation API or the in-house word2vec model. This way, the classifier can learn the nuances and subtleties of each language, and avoid the errors introduced by the translation and embedding processes. This would also reduce the latency and cost of the moderation system, as it would not need to invoke the Cloud Translation API for every message. To train a classifier using the chat messages in their original language, one could use a multilingual pre-trained model such as mBERT or XLM-R, which can handle multiple languages and domains. Alternatively, one could train a separate classifier for each language, using a monolingual pre-trained model such as BERT or a custom model tailored to the specific language and task.
:
Professional ML Engineer Exam Guide
Preparing for Google Cloud Certification: Machine Learning Engineer Professional Certificate Google Cloud launches machine learning engineer certification
[mBERT: Bidirectional Encoder Representations from Transformers]
[XLM-R: Unsupervised Cross-lingual Representation Learning at Scale]
[BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding]
181. Frage
You have been tasked with deploying prototype code to production. The feature engineering code is in PySpark and runs on Dataproc Serverless. The model training is executed by using a Vertex Al custom training job. The two steps are not connected, and the model training must currently be run manually after the feature engineering step finishes. You need to create a scalable and maintainable production process that runs end-to-end and tracks the connections between steps. What should you do?
Antwort: D
182. Frage
......
Suchen Sie nach die geeignetsten Prüfungsunterlagen der Google Professional-Machine-Learning-Engineer? Sorgen Sie noch um das Ordnen der Unterlagen? ITZert als ein professioneller Lieferant der Software der IT-Zertifizierungsprüfung haben Ihnen die umfassendsten Unterlagen der Google Professional-Machine-Learning-Engineer vorbereitet. Jetzt können Sie Zeit fürs Suchen gespart und direkt auf die Google Professional-Machine-Learning-Engineer Prüfung vorbereiten!
Professional-Machine-Learning-Engineer Pruefungssimulationen: https://www.itzert.com/Professional-Machine-Learning-Engineer_valid-braindumps.html
P.S. Kostenlose und neue Professional-Machine-Learning-Engineer Prüfungsfragen sind auf Google Drive freigegeben von ITZert verfügbar: https://drive.google.com/open?id=1JPUHIqG7526He50CcvhCvvxEfFGcy8KS