SPS-C01 Test Questions Pdf - Updated SPS-C01 Test Cram
BONUS!!! Download part of Itcertkey SPS-C01 dumps for free: https://drive.google.com/open?id=1vg31w6aYhehIT7k2hMmXquQ8rf9f8q1_
Are you still satisfied with your present job? Do you still have the ability to deal with your job well? Do you think whether you have the competitive advantage when you are compared with people working in the same field? If your answer is no,you are a right place now. Because our SPS-C01 Exam Torrent will be your good partner and you will have the chance to change your work which you are not satisfied with, and can enhance your ability by our SPS-C01 guide questions, you will pass the exam and achieve your target.
| Section | Objectives |
|---|
| Topic 1: Performance Optimization and Best Practices | - Efficient Snowpark execution
- 1. Resource utilization tuning
- 2. Pushdown optimization concepts
|
| Topic 2: DataFrame Operations and Data Processing | - Data transformation workflows
- 1. Joins and window functions
- 2. Filtering, selecting, and aggregations
|
| Topic 3: Testing, Debugging, and Deployment | - Production readiness
- 1. Deployment strategies
- 2. Debugging Snowpark applications
|
| Topic 4: Snowpark Fundamentals | - Snowpark architecture and concepts
- 1. Snowflake execution model overview
- 2. Snowpark APIs and supported languages
|
| Topic 5: Data Engineering with Snowpark | - Pipeline development
- 1. Batch processing workflows
- 2. Integration with Snowflake data pipelines
|
| Topic 6: User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
- 1. Stored procedures in Snowpark
- 2. Python UDFs
|
>> SPS-C01 Test Questions Pdf <<
Pass Guaranteed Quiz Latest Snowflake - SPS-C01 - Snowflake Certified SnowPro Specialty - Snowpark Test Questions Pdf
As we all, having a general review of what you have learnt is quite important, it will help you master the knowledge well. SPS-C01 Online test engine has testing history and performance review, and you can have a review through this version. In addition, SPS-C01 Online test engine supports all web browsers and Android and iOS etc. SPS-C01 Exam Materials of us offer you free demo to have a try before buying SPS-C01 training materials, so that you can have a deeper understanding of what you are going to buy. You can receive your downloading link and password within ten minutes, so that you can begin your study right away.
Snowflake Certified SnowPro Specialty - Snowpark Sample Questions (Q272-Q277):
NEW QUESTION # 272
You have a Snowpark DataFrame with columns 'department' , and 'salary'. You want to identify employees in each department whose salary is within the top 20% of salaries for that department. Which of the following approaches, using window functions, is the MOST efficient way to achieve this?
- A. Use window function to rank employees within each department by salary, then calculate the 80th percentile salary using a separate aggregation and join back to the original DataFrame to filter.
- B. Calculate the maximum salary per department, then filter employees whose salary is greater than or equal to 80% of the maximum salary.
- C. Use the 'ntile(5)' window function to divide each department's employees into 5 buckets based on salary, then select employees in the top bucket.
- D. Use the window function to calculate the percentile rank of each employee's salary within their department, then filter for ranks greater than or equal to 0.8.
- E. Calculate the average salary per department, then filter employees whose salary is greater than 80% of the average salary.
Answer: D
Explanation:
Option B is the most efficient. directly calculates the percentile rank, allowing for a simple and efficient filter. Options A and C only consider the average or maximum salary and don't provide a percentile rank. Option D divides into 5 buckets (quintiles), which isn't precise enough for identifying the top 20%. Option E is less efficient as it involves multiple steps: ranking, aggregation, and joining.
NEW QUESTION # 273
A data scientist has developed a Snowpark Python stored procedure named 'model_training'. This procedure utilizes a large machine learning model and requires significant compute resources. The data scientist wants to optimize the cost and performance of running this stored procedure. Which of the following strategies would be the MOST effective for achieving this goal?
- A. Register the stored procedure with the '@sproc' decorator without specifying any warehouse size, letting Snowflake automatically manage the warehouse.
- B. Convert the Python stored procedure to a SQL stored procedure to leverage Snowflake's SQL optimization engine.
- C. Split the stored procedure into multiple smaller procedures and execute them sequentially on a smaller warehouse.
- D. Specify a warehouse size using the 'warehouse' parameter within the '@sproc' decorator and leverage auto-suspend and auto-resume features to minimize costs when the procedure is idle.
- E. Run the stored procedure on a larger Snowflake warehouse to reduce execution time, regardless of potential idle time.
Answer: D
Explanation:
Specifying a warehouse size and using auto-suspend and auto-resume provides a balance between performance and cost. Option A might increase costs due to idle time. Option B relies on Snowflake's default warehouse, which might not be optimal. Option D could increase overall execution time due to overhead. Option E may not be feasible or efficient if the logic is heavily dependent on Python libraries. Therefore, specifically assigning an appropriate warehouse size with auto-suspend/resume is the most effective approach.
NEW QUESTION # 274
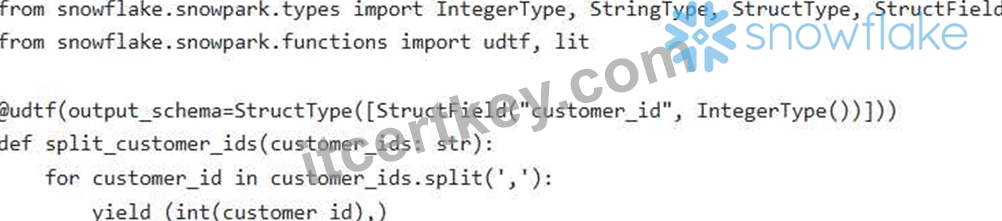
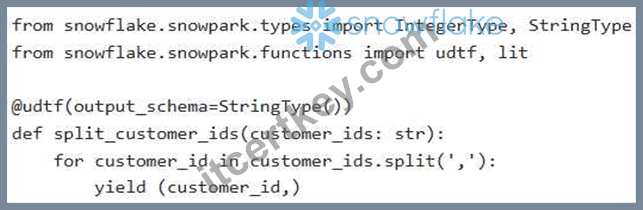
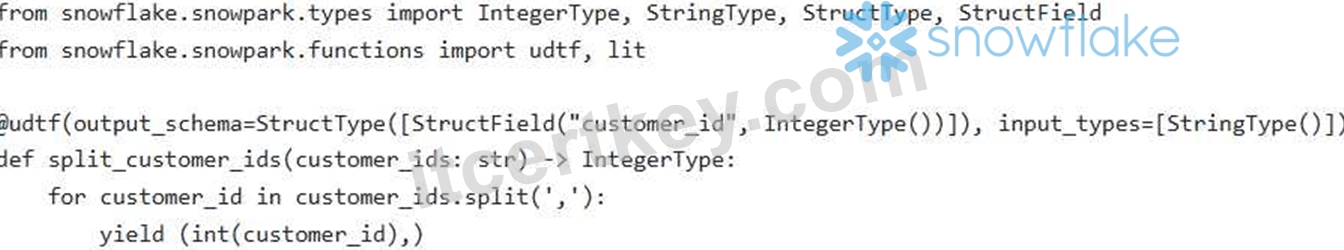
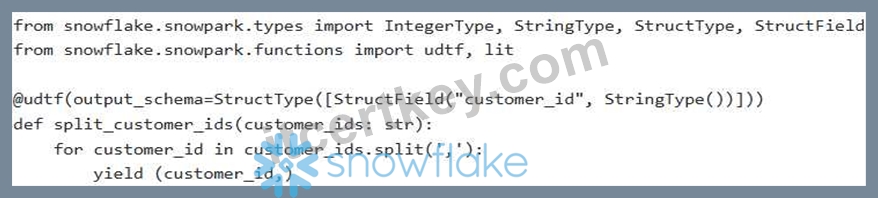
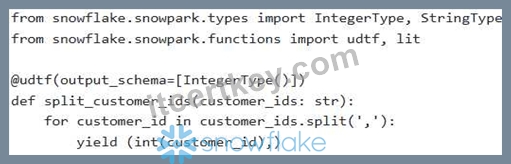
You are tasked with creating a UDTF using Snowpark Python that splits a comma-separated string of customer IDs into individual rows. The input is a string (VARCHAR) and the output should be a table with a single column named 'customer_id' of type INTEGER. Which of the following code snippets CORRECTLY defines and registers the UDTF, ensuring proper data type handling? Assume is a valid Snowpark Session object.
Answer: A
Explanation:
Option B correctly defines the UDTF. It uses 'StructType' and to define the output schema with a column named 'customer_id' of type "Integer Type'. The code also correctly converts the customer ID to an integer before yielding it. Option A defines the output schema as 'StringType' , which is incorrect. Option C does not correctly define a column name. Option D uses 'StringType' for the column, which violates the requirements. Option E adds and a return annotation which are valid, but the structure of the annotation is still not correct for a UDTF.
NEW QUESTION # 275
You are developing a secure UDF in Snowpark Python that needs to access sensitive data stored in an internal stage. The UDF should be accessible to users without granting them direct access to the stage. Which of the following security measures and code snippets are required to achieve this, assuming the stage is already created?
- A. Create a UDF and grant USAGE on the stage to the role that owns the UDF.
- B. Create a secure UDF and use the function to access stage credentials within the UDF's handler function.
- C. Create a secure UDF and use a stored procedure owned by a role with access to the internal stage to retrieve data, passing the data to the UDF as an argument.
- D. Create a secure UDF using the ' VOLATILE keyword, allowing it to access secured data with current user's permissions.
- E. Create an external function and grant access to the API integration that provides the security context.
Answer: B
Explanation:
Secure UDFs are designed to execute with the privileges of the UDF owner, not the caller. allows secure access to stage credentials. Option B is incorrect because granting USAGE on the stage directly grants access to the data in the stage. Option C is a valid approach but unnecessary complex. Option D concerns external functions, not secure UDFs within Snowflake. Option E is incorrect because 'VOLATILE doesn't affect privilege handling.
NEW QUESTION # 276
You're tasked with loading data representing transactions from a legacy system into Snowflake using Snowpark. The legacy system exports the transaction data as a Python list of tuples, where each tuple contains transaction ID (integer), transaction amount (float), and transaction date (string in 'YYYY-MM-DD' format). The scale of data can be very high and need optimized way to load the data'. Your goal is to create a Snowpark DataFrame from this list of tuples, ensuring the date column is correctly interpreted as a Snowflake Date type. Which of the following approaches would be the most efficient and correct, minimizing data conversion overhead and maximizing Snowpark's capabilities?
- A. Create a Snowpark DataFrame directly from the list of tuples using 'session.createDataFrame(data)' , relying on automatic schema inference. Then, use function to cast the date column to a DateType.
- B. Create a Snowpark DataFrame directly from the list of tuples using 'session.createDataFrame(datay , relying on automatic schema inference. No need to explicitly convert to 'DateType' as Snowflake will take care of implicit conversion.
- C. Convert the list of tuples to a Pandas DataFrame, explicitly specifying the column names and data types (including 'pd.datetime64[ns]' for the date column). Then, create a Snowpark DataFrame from the Pandas DataFrame using 'session.createDataFrame(pandas_df)'.
- D. Define a Snowpark schema using 'StructType' and 'StructField' , explicitly setting the data type of the date column to 'DateType'. Then, create the Snowpark DataFrame using 'session.createDataFrame(data,
- E. Create a list of dictionaries from the list of tuples with correct column names, and define a Snowpark schema using 'StructType' and 'StructField', explicitly setting the data type of the date column to 'DateType'. Then, create the Snowpark DataFrame using 'session.createDataFrame(data, schema=schema)'.
Answer: D
Explanation:
Option C is the most efficient and correct way. Correctness : Option C explicitly defines the schema, including the 'DateType' for the transaction date. This ensures that Snowflake correctly interprets the date column without requiring any further casting or conversion. Avoids unnecessary string conversion. Efficiency : By defining the schema upfront, you avoid schema inference during dataframe creation, which can be costly for large datasets. This also avoids the cost of explicit casting after dataframe creation (as in Option A). Maximizing Snowpark Capabilities : Directly using Snowpark API to declare data types takes full advantage of Snowpark capabilities. Option A relies on implicit schema inference, which is not optimal in scenarios with specific data type requirements, and it requires an additional step which can be costly for large data. Option B introduces a dependency on Pandas and involves converting the data to a Pandas DataFrame, then to a Snowpark DataFrame, which creates unnecessary overhead and is not the most efficient approach. Option D, although correct, requires you to create a list of dictionaries, which adds an unneeded step in between and may not be optimized. Option E relies on implicit casting; However, this can lead to failure if date format is wrong.
NEW QUESTION # 277
......
When you are preparing SPS-C01 practice exam, it is necessary to grasp the overall knowledge points of real exam by using the latest SPS-C01 pass guide. Our experts written the accurate SPS-C01 test answers for exam preparation and created the study guideline for our candidates. We promise you will get high passing mark with our valid SPS-C01 Exam Torrent and your money will be back to your account if you failed exam with our study materials.
Updated SPS-C01 Test Cram: https://www.itcertkey.com/SPS-C01_braindumps.html
- Valid SPS-C01 Exam Testking ✨ Reliable SPS-C01 Real Exam 😍 SPS-C01 Valid Vce Dumps 🕡 Search for ▷ SPS-C01 ◁ on 「 www.prepawaypdf.com 」 immediately to obtain a free download ✳Valid SPS-C01 Exam Testking
- SPS-C01 Reliable Test Preparation 😽 SPS-C01 Mock Exams ✨ Verified SPS-C01 Answers 🏍 Simply search for 「 SPS-C01 」 for free download on ☀ www.pdfvce.com ️☀️ 😺SPS-C01 Pass4sure Pass Guide
- SPS-C01 Dumps Collection 💧 Test SPS-C01 Objectives Pdf 🧢 SPS-C01 Pass4sure Pass Guide 😃 Open 「 www.practicevce.com 」 and search for “ SPS-C01 ” to download exam materials for free 🦰Valid SPS-C01 Practice Questions
- SPS-C01 Exam Bootcamp 🌇 Valid SPS-C01 Test Guide 🥻 SPS-C01 Certification 👇 Search for [ SPS-C01 ] on “ www.pdfvce.com ” immediately to obtain a free download 🌄Valid SPS-C01 Exam Testking
- Valid SPS-C01 Exam Testking 🍑 SPS-C01 Reliable Test Preparation 🆒 SPS-C01 Exam Bootcamp 🛀 The page for free download of ⮆ SPS-C01 ⮄ on ✔ www.easy4engine.com ️✔️ will open immediately 🚹SPS-C01 Pass4sure Pass Guide
- SPS-C01 study guide - real SPS-C01 braindumps - latest valid 🔀 Download 《 SPS-C01 》 for free by simply entering ➠ www.pdfvce.com 🠰 website 🕡Valid SPS-C01 Test Online
- High Hit-Rate Snowflake - SPS-C01 - Snowflake Certified SnowPro Specialty - Snowpark Test Questions Pdf 🧑 Easily obtain 《 SPS-C01 》 for free download through 【 www.vce4dumps.com 】 🍾Valid SPS-C01 Practice Questions
- Latest SPS-C01 Exam Questions Vce 🔵 SPS-C01 Mock Exams 🍖 SPS-C01 Questions Answers ☮ Enter 《 www.pdfvce.com 》 and search for ✔ SPS-C01 ️✔️ to download for free 🎲Valid SPS-C01 Exam Testking
- Download the Snowflake SPS-C01 Exam Dumps Now 🔀 Search for ➽ SPS-C01 🢪 and download it for free immediately on ▷ www.validtorrent.com ◁ 🌮SPS-C01 Valid Vce Dumps
- SPS-C01 Reliable Test Preparation 📋 Reliable SPS-C01 Real Exam 🛸 Test SPS-C01 Objectives Pdf 📗 Search for ▷ SPS-C01 ◁ and download it for free on ➡ www.pdfvce.com ️⬅️ website 🟩Latest SPS-C01 Exam Questions Vce
- 100% Pass Quiz 2026 High Hit-Rate Snowflake SPS-C01: Snowflake Certified SnowPro Specialty - Snowpark Test Questions Pdf 🚐 Search for ▶ SPS-C01 ◀ and download it for free on ( www.vceengine.com ) website ✒Valid SPS-C01 Practice Questions
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes
BTW, DOWNLOAD part of Itcertkey SPS-C01 dumps from Cloud Storage: https://drive.google.com/open?id=1vg31w6aYhehIT7k2hMmXquQ8rf9f8q1_