Valid Databricks-Certified-Professional-Data-Engineer Exam Pattern, New Databricks-Certified-Professional-Data-Engineer Test Syllabus
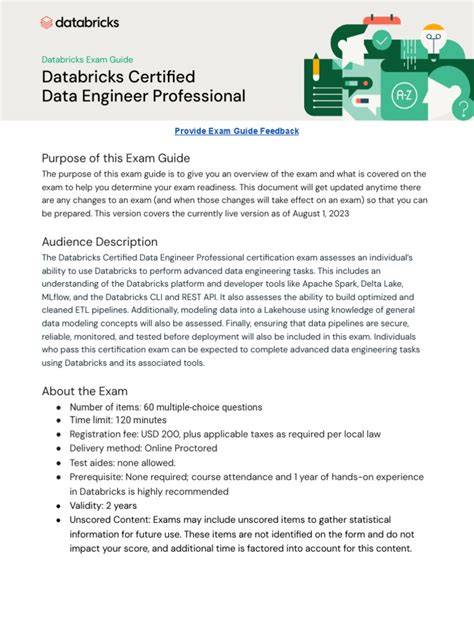
BTW, DOWNLOAD part of It-Tests Databricks-Certified-Professional-Data-Engineer dumps from Cloud Storage: https://drive.google.com/open?id=1Fy5dgTsXyfLAqegXtSFd2sbmPQ6LUF76
With Databricks-Certified-Professional-Data-Engineer exam dumps from It-Tests, we provide guaranteed success rate for the Databricks-Certified-Professional-Data-Engineer. We provide latest and updated question answers for Databricks-Certified-Professional-Data-Engineer exam for preparation. You can prepare for the Databricks-Certified-Professional-Data-Engineer with our test products including Databricks-Certified-Professional-Data-Engineer PDF dumps questions, and test preparation software. You can prepare for the Databricks-Certified-Professional-Data-Engineer through practice kits without facing any problem. You can get the desired score for the Databricks-Certified-Professional-Data-Engineer and join the list of our satisfied customers. The Databricks-Certified-Professional-Data-Engineer test questions and preparation material is prepared by highly skilled certified professionals.
| Section | Weight | Objectives |
|---|
| Topic 1: Data Warehouse and Lakehouse Architecture | 15-20% | - Lakehouse architecture principles
- 1. Bronze, silver, gold data layers
- 2. Data governance fundamentals
- 3. Differences between data lake, data warehouse, and lakehouse
|
| Topic 2: Pipeline Development and Orchestration | 10-15% | - Databricks workflows
- 1. Task dependencies and orchestration
- 2. Monitoring and alerting
- 3. Jobs and job scheduling
|
| Topic 3: Data Ingestion | 15-20% | - Batch ingestion methods
- 1. DBR autoloader
- 2. Integration with external systems
- 3. Spark APIs for ingestion
- Streaming ingestion
- 1. Kafka integration
- 2. Structured streaming fundamentals
|
| Topic 4: Delta Lake | 20-25% | - Delta Lake fundamentals
- 1. Time travel and data versioning
- 2. Optimize and Z-order
- 3. ACID transactions
- Delta Lake operations
- 1. Merge, update, delete operations
- 2. Delta Live Tables
- 3. Schema evolution and enforcement
|
| Topic 5: Data Processing with Spark | 25-30% | - Spark DataFrames and Spark SQL
- 1. Window functions
- 2. DataFrame operations and transformations
- 3. Spark SQL queries and functions
- Python and SQL for data engineering
- 1. Built-in and user-defined functions
- 2. Spark APIs in Python
- 3. Performance optimization techniques
|
>> Valid Databricks-Certified-Professional-Data-Engineer Exam Pattern <<
New Databricks Databricks-Certified-Professional-Data-Engineer Test Syllabus - Exam Databricks-Certified-Professional-Data-Engineer Questions Answers
Databricks-Certified-Professional-Data-Engineer valid study test give you an in-depth understanding of the contents and help you to make out a detail study plan for Databricks-Certified-Professional-Data-Engineer preparation. All the questions are edited according to the analysis of data and summarized from the previous test, which can ensure the high hit rate. You just need take the spare time to study Databricks-Certified-Professional-Data-Engineer Training Material, the effects are obvious. You will get a high score with the help of Databricks Databricks-Certified-Professional-Data-Engineer study pdf.
Databricks Certified Professional Data Engineer Exam Sample Questions (Q182-Q187):
NEW QUESTION # 182
The following table consists of items found in user carts within an e-commerce website.

The following MERGE statement is used to update this table using an updates view, with schema evaluation enabled on this table.

How would the following update be handled?
- A. The update throws an error because changes to existing columns in the target schema are not supported.
- B. The new nested field is added to the target schema, and files underlying existing records are updated to include NULL values for the new field.
- C. The update is moved to separate ''restored'' column because it is missing a column expected in the target schema.
- D. The new restored field is added to the target schema, and dynamically read as NULL for existing unmatched records.
Answer: B
Explanation:
With schema evolution enabled in Databricks Delta tables, when a new field is added to a record through a MERGE operation, Databricks automatically modifies the table schema to include the new field. In existing records where this new field is not present, Databricks will insert NULL values for that field. This ensures that the schema remains consistent across all records in the table, with the new field being present in every record, even if it is NULL for records that did not originally include it.
References:
* Databricks documentation on schema evolution in Delta Lake:
https://docs.databricks.com/delta/delta-batch.html#schema-evolution
NEW QUESTION # 183
Which of the following technologies can be used to identify key areas of text when parsing Spark Driver log4j output?
- A. Scala Datasets
- B. C++
- C. pyspsark.ml.feature
- D. Regex
- E. Julia
Answer: D
Explanation:
Regex, or regular expressions, are a powerful way of matching patterns in text. They can be used to identify key areas of text when parsing Spark Driver log4j output, such as the log level, the timestamp, the thread name, the class name, the method name, and the message. Regex can be applied in various languages and frameworks, such as Scala, Python, Java, Spark SQL, and Databricks notebooks. References:
* https://docs.databricks.com/notebooks/notebooks-use.html#use-regular-expressions
* https://docs.databricks.com/spark/latest/spark-sql/udf-scala.html#using-regular-expressions-in-udfs
* https://docs.databricks.com/spark/latest/sparkr/functions/regexp_extract.html
* https://docs.databricks.com/spark/latest/sparkr/functions/regexp_replace.html
NEW QUESTION # 184
A transactions table has been liquid clustered on the columns product_id, user_id, and event_date.
Which operation lacks support for cluster on write?
- A. CTAS and RTAS statements
- B. spark.write.format('delta').mode('append')
- C. spark.writestream.format('delta').mode('append')
- D. INSERT INTO operations
Answer: C
Explanation:
Delta Lake'sLiquid Clusteringis an advanced feature that improves query performance by dynamically clustering data without requiring costly compaction steps like traditional Z-ordering.
When performing writes to aLiquid Clusteredtable, some write operations automatically maintain clustering, while othersdo not.
Explanation of Each Option:
* (A) spark.writestream.format('delta').mode('append') (Correct Answer)
* Reason:Streaming writes (writestream) donotsupportLiquid Clusteringbecause streaming data arrives in micro-batches.
* Since Liquid Clustering needs efficient global reorganization of files, streaming append operations don't provide sufficient data volume at a time to be effectively clustered.
* Delta Lake documentation states that Liquid Clustering is only supported for batch writes.
* (B) CTAS and RTAS statements
* Reason:CREATE TABLE AS SELECT (CTAS) and REPLACE TABLE AS SELECT (RTAS) are batch operationsand can enforce Liquid Clustering.
* These operations create or replace a table based on a query result, and since they are batch-based, Liquid Clustering applies.
* (C) INSERT INTO operations
* Reason:INSERT INTOis supportedfor Liquid Clustering because it is a batch operation.
* While it may not be as efficient as MERGE or COPY INTO, clustering is applied upon execution.
* (D) spark.write.format('delta').mode('append')
* Reason:Batch append operationsare supportedfor Liquid Clustering.
* Unlike streaming append, batch writes allow the optimizer to re-cluster data efficiently.
Conclusion:
Sincestreaming append operations do not support Liquid Clustering, option(A)is the correct answer.
References:
* Liquid Clustering in Delta Lake - Databricks Documentation
NEW QUESTION # 185
A table is registered with the following code:

Both users and orders are Delta Lake tables. Which statement describes the results of querying recent_orders?
- A. All logic will execute at query time and return the result of joining the valid versions of the source tables at the time the query began.
- B. All logic will execute at query time and return the result of joining the valid versions of the source tables at the time the query finishes.
- C. The versions of each source table will be stored in the table transaction log; query results will be saved to DBFS with each query.
- D. All logic will execute when the table is defined and store the result of joining tables to the DBFS; this stored data will be returned when the table is queried.
- E. Results will be computed and cached when the table is defined; these cached results will incrementally update as new records are inserted into source tables.
Answer: D
NEW QUESTION # 186
The data governance team is reviewing code used for deleting records for compliance with GDPR. They note the following logic is used to delete records from the Delta Lake table named users .

Assuming that user_id is a unique identifying key and that delete_requests contains all users that have requested deletion, which statement describes whether successfully executing the above logic guarantees that the records to be deleted are no longer accessible and why?
- A. No; the Delta cache may return records from previous versions of the table until the cluster is restarted.
- B. Yes; the Delta cache immediately updates to reflect the latest data files recorded to disk.
- C. No; the Delta Lake delete command only provides ACID guarantees when combined with the merge into command.
- D. Yes; Delta Lake ACID guarantees provide assurance that the delete command succeeded fully and permanently purged these records.
- E. No; files containing deleted records may still be accessible with time travel until a vacuum command is used to remove invalidated data files.
Answer: E
Explanation:
The code uses the DELETE FROM command to delete records from the users table that match a condition based on a join with another table called delete_requests, which contains all users that have requested deletion. The DELETE FROM command deletes records from a Delta Lake table by creating a new version of the table that does not contain the deleted records. However, this does not guarantee that the records to be deleted are no longer accessible, because Delta Lake supports time travel, which allows querying previous versions of the table using a timestamp or version number. Therefore, files containing deleted records may still be accessible with time travel until a vacuum command is used to remove invalidated data files from physical storage. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Delete from a table" section; Databricks Documentation, under
"Remove files no longer referenced by a Delta table" section.
NEW QUESTION # 187
......
We have a variety of versions for your reference: PDF & Software & APP version. All those versions are high efficient and accurate with passing rate up to 98 to 100 percent. So our Databricks-Certified-Professional-Data-Engineer Study Guide is efficient, high-quality for you. Such high quality and low price traits of our Databricks-Certified-Professional-Data-Engineer guide materials make exam candidates reassured.
New Databricks-Certified-Professional-Data-Engineer Test Syllabus: https://www.it-tests.com/Databricks-Certified-Professional-Data-Engineer.html
- Databricks-Certified-Professional-Data-Engineer Reliable Test Experience 🧾 Practice Databricks-Certified-Professional-Data-Engineer Exam Fee 😬 Valid Databricks-Certified-Professional-Data-Engineer Test Answers 💹 Simply search for ▛ Databricks-Certified-Professional-Data-Engineer ▟ for free download on 《 www.exam4labs.com 》 ☎Reliable Databricks-Certified-Professional-Data-Engineer Test Topics
- Databricks-Certified-Professional-Data-Engineer Vce Exam 🤖 Databricks-Certified-Professional-Data-Engineer Best Practice 💼 Databricks-Certified-Professional-Data-Engineer Best Practice 🚚 Download 【 Databricks-Certified-Professional-Data-Engineer 】 for free by simply searching on ➠ www.pdfvce.com 🠰 ↙Online Databricks-Certified-Professional-Data-Engineer Training Materials
- Reliable Valid Databricks-Certified-Professional-Data-Engineer Exam Pattern offer you accurate New Test Syllabus | Databricks Certified Professional Data Engineer Exam 🦼 Search for ➤ Databricks-Certified-Professional-Data-Engineer ⮘ on ➤ www.prep4away.com ⮘ immediately to obtain a free download ❇Databricks-Certified-Professional-Data-Engineer Valid Exam Papers
- Databricks-Certified-Professional-Data-Engineer Training Materials are Worthy for You to Buy It - Pdfvce 🏥 Easily obtain free download of ⏩ Databricks-Certified-Professional-Data-Engineer ⏪ by searching on ➡ www.pdfvce.com ️⬅️ 🎾Online Databricks-Certified-Professional-Data-Engineer Training Materials
- Reliable Valid Databricks-Certified-Professional-Data-Engineer Exam Pattern offer you accurate New Test Syllabus | Databricks Certified Professional Data Engineer Exam 🟢 Search for ▛ Databricks-Certified-Professional-Data-Engineer ▟ and easily obtain a free download on “ www.pdfdumps.com ” 💄Practice Databricks-Certified-Professional-Data-Engineer Exam Fee
- Pass Guaranteed 2026 Databricks Databricks-Certified-Professional-Data-Engineer Perfect Valid Exam Pattern 🍆 Simply search for ☀ Databricks-Certified-Professional-Data-Engineer ️☀️ for free download on ☀ www.pdfvce.com ️☀️ 🐝Reliable Databricks-Certified-Professional-Data-Engineer Test Topics
- Databricks-Certified-Professional-Data-Engineer Reliable Real Exam 🧿 Online Databricks-Certified-Professional-Data-Engineer Training Materials 🎍 Practice Databricks-Certified-Professional-Data-Engineer Exam Fee ⛪ The page for free download of “ Databricks-Certified-Professional-Data-Engineer ” on ➥ www.easy4engine.com 🡄 will open immediately 👈Databricks-Certified-Professional-Data-Engineer Exam Answers
- Databricks-Certified-Professional-Data-Engineer Training Materials are Worthy for You to Buy It - Pdfvce 🧄 Search for ( Databricks-Certified-Professional-Data-Engineer ) on 「 www.pdfvce.com 」 immediately to obtain a free download 🍱Databricks-Certified-Professional-Data-Engineer Online Training
- Databricks-Certified-Professional-Data-Engineer Exam Study Guide - Databricks-Certified-Professional-Data-Engineer PDF prep material - Databricks-Certified-Professional-Data-Engineer Exam Training Test 🐕 ➥ www.vce4dumps.com 🡄 is best website to obtain 《 Databricks-Certified-Professional-Data-Engineer 》 for free download 🔴Valid Databricks-Certified-Professional-Data-Engineer Test Answers
- Databricks-Certified-Professional-Data-Engineer Guide 🥽 Answers Databricks-Certified-Professional-Data-Engineer Free 🥺 Databricks-Certified-Professional-Data-Engineer Guide 📋 Search on ▷ www.pdfvce.com ◁ for 《 Databricks-Certified-Professional-Data-Engineer 》 to obtain exam materials for free download 🌞Databricks-Certified-Professional-Data-Engineer Guide
- Reliable Databricks-Certified-Professional-Data-Engineer Dumps 📤 Online Databricks-Certified-Professional-Data-Engineer Training Materials 🚡 Reliable Databricks-Certified-Professional-Data-Engineer Test Topics 🥊 Search for ☀ Databricks-Certified-Professional-Data-Engineer ️☀️ and download it for free on ➥ www.prepawaypdf.com 🡄 website 👪Reliable Databricks-Certified-Professional-Data-Engineer Test Topics
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, aprenderfotografia.online, audiomack.com, jogajog.com.bd, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
What's more, part of that It-Tests Databricks-Certified-Professional-Data-Engineer dumps now are free: https://drive.google.com/open?id=1Fy5dgTsXyfLAqegXtSFd2sbmPQ6LUF76