ExamTorrent provide you with the most authoritative and the fullest Microsoft DP-750 Exam Dumps, thus the hit rate is very high. All questions that may appear in the exam are included in our exam dumps. With the changes of exam outline, we also update our exam dumps at any time. ExamTorrent pdf real questions and answers can prevent you from wasting lots of time and efforts on preparing for the exam and can help you sail through you exam with ease and high efficiency. But even you fail the exam, we assure we will give you FULL REFUND. Opportunities always for those who are well prepared and we wish you not to miss the good opportunities.
| Section | Weight | Objectives |
|---|---|---|
| Prepare and process data | 30–35% | - Optimize and manage data storage
|
| Secure and govern Unity Catalog objects | 15–20% | - Implement data governance and security
|
| Set up and configure an Azure Databricks environment | 15–20% | - Integrate with Azure services
|
| Deploy and maintain data pipelines and workloads | 30–35% | - Build and orchestrate pipelines
|
ExamTorrent is a good website for Microsoft certification DP-750 exams to provide short-term effective training. And ExamTorrent can guarantee your Microsoft certification DP-750 exam to be qualified. If you don't pass the exam, we will take a full refund to you. Before you choose to buy the ExamTorrent products before, you can free download part of the exercises and answers about Microsoft Certification DP-750 Exam as a try, then you will be more confident to choose ExamTorrent's products to prepare your Microsoft certification DP-750 exam.
NEW QUESTION # 45
You have an Azure Databricks workspace named Workspace1 that uses a Git repository. The repository contains a Databricks notebook named Notebook1.
From the main branch, you create a feature branch named Branch1 and commit changes to Notebook1. Another user commits changes to Notebook1 in main.
When you attempt to merge Branch1 into main, the merge fails due to conflicts.
You need to merge Branch1 into the main branch. The solution must ensure that Notebook1 includes all the changes from both the branches.
What should you do?
Answer: C
Explanation:
To resolve the merge conflict and keep all changes from both branches, you must pull the updated main branch into your feature branch, resolve the conflicts manually within Databricks or a local Git tool, and then merge.
Reference:
https://devactivity.com/insights/streamlining-your-git-workflow-resolving-branch-behind-main- issues-in-your-git-repo/
NEW QUESTION # 46
Drag and Drop Question
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a catalog named finance, finance contains two schemas named default and procurement.
You need to create a table named assets in the procurement schema, assets must contain the following columns:
- asset_id
- asset_type
- asset_name
How should you complete the SQL statement? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.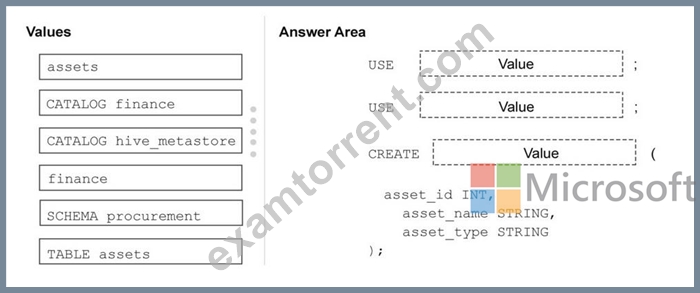
Answer:
Explanation: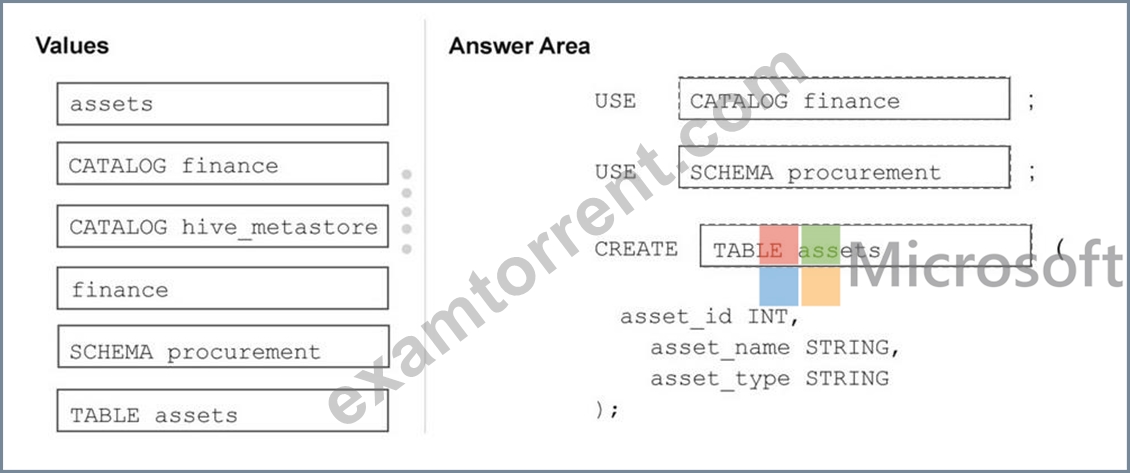
NEW QUESTION # 47
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains two catalogs named Catalog1 and Catalog2.
An external application uses a service principal named SP1 to connect to a SQL warehouse.
You need to ensure that SP1 can query the data in Catalog1 and Catalog2. The solution must follow the principle of least privilege.
Which permissions should you grant to SP1 for the catalogs?
Answer: C
Explanation:
To ensure a service principal can query data in two specific catalogs while maintaining the principle of least privilege, you must assign the following permissions for each catalog:
Unified Catalog Permissions
USE CATALOG on the specific catalog: This is a prerequisite that allows the principal to see the catalog and its child objects.
USE SCHEMA on the schemas containing the data: This allows the principal to interact with the schemas within that catalog.
SELECT on the specific tables or views: This provides the actual read access required to query the data.
Reference:
https://learn.microsoft.com/en-us/purview/data-governance-roles-permissions
NEW QUESTION # 48
You have an Azure Databricks workspace that is enabled for Unity Catalog You plan to ingest data from CSV files stored in Azure Data Lake Storage Gen2. New rows are appended frequently.
You need to implement a data ingestion solution that meets the following requirements:
* New data must be available in near-real time (NRT).
* The data must be stored in managed Delta tables.
* The solution must minimize custom code and maintenance effort.
What should you include in the solution?
Answer: A
Explanation:
The correct answer is A - Auto Loader.
Auto Loader is exactly the right tool for this scenario: new CSV files land in ADLS Gen2, and they need to be ingested into managed Delta tables in near-real time with minimal custom code. Auto Loader uses file-system notifications or incremental directory listing to detect new arrivals, processes only the newly added files (skipping previously ingested ones), and writes results into Delta tables - all with schema inference and evolution support built in.
Option B (scheduled Spark batch jobs) adds latency tied to the schedule interval and requires custom 'what files have I already processed' tracking. Option C (external table referencing CSV files) exposes the raw files for querying but doesn't load data into managed Delta tables - it also can't provide NRT updates as files change. Option D (Azure Data Factory pipeline) introduces external orchestration overhead and is a heavier solution for something Auto Loader handles natively in a few lines of PySpark.
Reference: https://learn.microsoft.com/en-us/azure/databricks/ingestion/auto-loader/
NEW QUESTION # 49
You have an Azure Databricks workspace that uses Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that ingests data into a managed Delta table named Table1. Table1 is used for analytics.
New columns are added to the source data, causing pipeline failures during writes to Table1.
You need to prevent the pipeline failures. The solution must ensure that schema changes are detected and handled.
What should you do?
Answer: B
Explanation:
You should enable schema evolution to resolve this problem. In Lakeflow Spark Declarative Pipelines (SDP)-formerly known as Delta Live Tables (DLT)-schema evolution automatically updates the schema of your managed Delta tables when new columns are detected in the source data.
Prevents Pipeline Failures: By default, Delta Lake applies strict schema enforcement to prevent bad or mismatched data from corrupting your tables. When the source data layout changes (e.g., column creep), the pipeline will throw a runtime error and fail the write operation.
Automates Ingestion Flexibility: Activating schema evolution allows Delta Lake to automatically adapt by adding the new columns to the target managed table layout dynamically, eliminating manual intervention or explicit ALTER TABLE operations.
Reference:
https://learn.microsoft.com/en-us/azure/databricks/ldp/unity-catalog
NEW QUESTION # 50
......
Many students often start to study as the exam is approaching. Time is very valuable to these students, and for them, one extra hour of study may mean 3 points more on the test score. If you are one of these students, then Implementing Data Engineering Solutions Using Azure Databricks exam tests are your best choice. Because students often purchase materials from the Internet, there is a problem that they need transport time, especially for those students who live in remote areas. When the materials arrive, they may just have a little time to read them before the exam. However, with DP-750 Exam Questions, you will never encounter such problems, because our materials are distributed to customers through emails.
Reliable DP-750 Test Materials: https://www.examtorrent.com/DP-750-valid-vce-dumps.html