認定するSnowflake SPS-C01|完璧なSPS-C01試験関連情報試験|試験の準備方法Snowflake Certified SnowPro Specialty - Snowparkテスト難易度

P.S. JPNTestがGoogle Driveで共有している無料かつ新しいSPS-C01ダンプ:https://drive.google.com/open?id=11NX8jn0-MeEi5aFs1KAzdR87JD4DmTYN
SPS-C01試験参考書を購入すると、完璧なアフターサービスと高品質なを楽しむことができます。だから、あなたは私たちのSPS-C01試験参考書から、驚きを得ることができると信じています。また、あなたがSPS-C01試験参考書の費用を支払う前にサービスを楽しむことができるだけでなく、購入後1年間無料でSPS-C01試験参考書の更新版を楽しむこともできます。
Snowflake SPS-C01 Exam Syllabus Topics:
| Section | Objectives |
|---|
| Topic 1: DataFrame Operations and Data Processing | - Data transformation workflows
- 1. Filtering, selecting, and aggregations
- 2. Joins and window functions
|
| Topic 2: Performance Optimization and Best Practices | - Efficient Snowpark execution
- 1. Pushdown optimization concepts
- 2. Resource utilization tuning
|
| Topic 3: Snowpark Fundamentals | - Snowpark architecture and concepts
- 1. Snowpark APIs and supported languages
- 2. Snowflake execution model overview
|
| Topic 4: Testing, Debugging, and Deployment | - Production readiness
- 1. Debugging Snowpark applications
- 2. Deployment strategies
|
| Topic 5: Data Engineering with Snowpark | - Pipeline development
- 1. Integration with Snowflake data pipelines
- 2. Batch processing workflows
|
| Topic 6: User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
- 1. Stored procedures in Snowpark
- 2. Python UDFs
|
>> SPS-C01試験関連情報 <<
認定するSnowflake SPS-C01試験関連情報 & 合格スムーズSPS-C01テスト難易度 | ユニークなSPS-C01復習テキスト
逆境は人をテストすることができます。困難に直面するとき、勇敢な人だけはのんびりできます。あなたは勇敢な人ですか。もしIT認証の準備をしなかったら、あなたはのんびりできますか。もちろんです。 JPNTestのSnowflakeのSPS-C01試験トレーニング資料を持っていますから、どんなに難しい試験でも成功することができます。
Snowflake Certified SnowPro Specialty - Snowpark 認定 SPS-C01 試験問題 (Q133-Q138):
質問 # 133
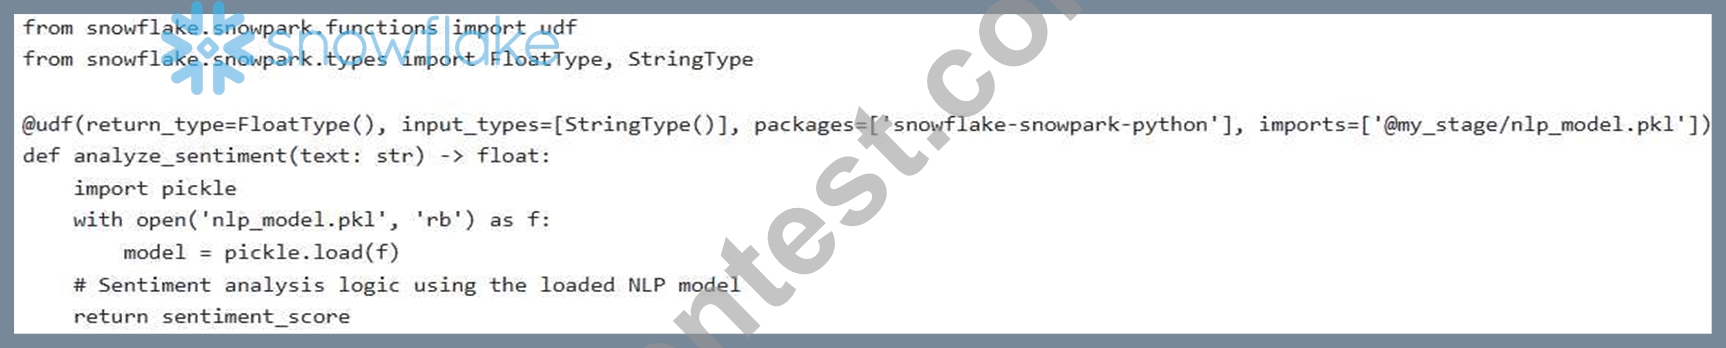
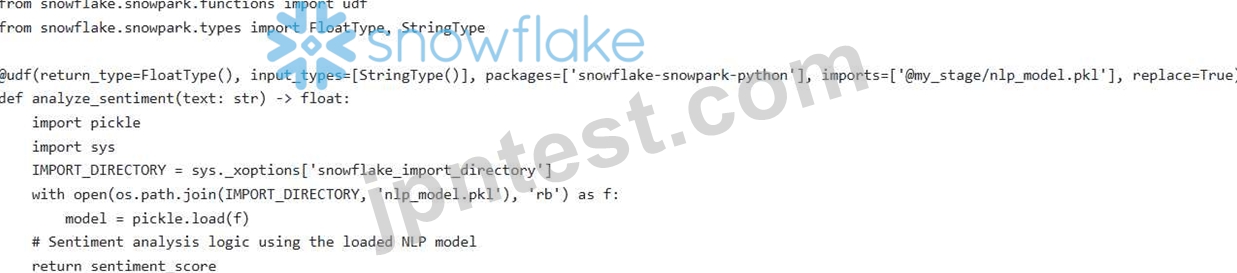
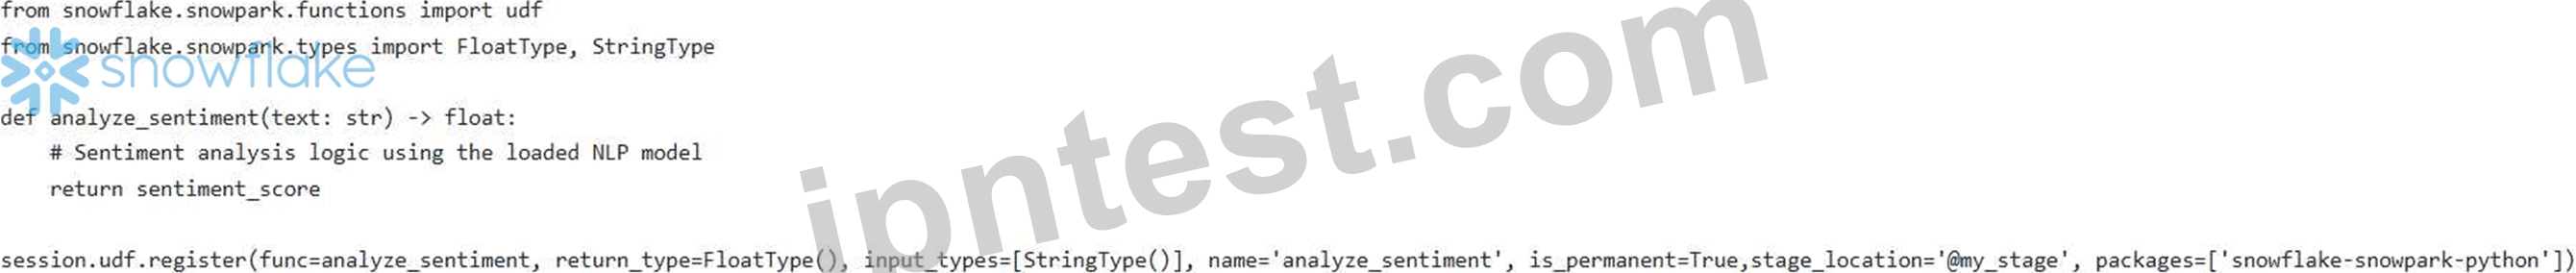
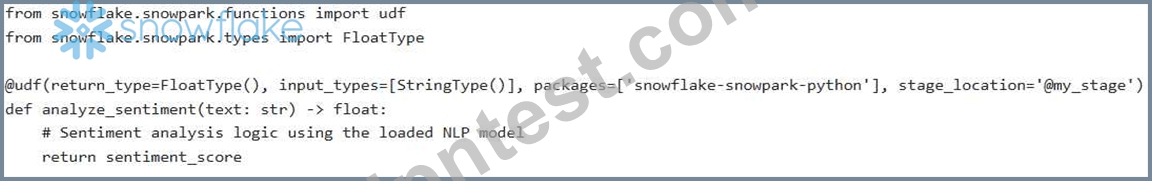
You are developing a Snowpark application to process customer sentiment from text reviews. You have a Python function, , that utilizes a pre-trained NLP model loaded from a file on a Snowflake stage named This function returns a sentiment score (float) between -1 and 1. You need to register this function as a UDF so that it can be used within Snowpark DataFrames. Which of the following code snippets correctly registers the UDF, ensuring the NLP model is available to the function during execution?
正解:B
解説:
Option E correctly uses the '@udf decorator with the 'imports' parameter to specify the location of the pickled model on the stage. It also uses to correctly construct the path to the imported file within the UDF's execution environment. Replace=True prevents errors if the UDF already exists. Options A, C and D don't correctly handle importing the NLP model. Option B has a security issue of loading file without validating the Path.
質問 # 134
You have a Snowpark DataFrame containing data to be loaded into a Snowflake table You want to use the 'merge' operation to update existing records and insert new records. The has a column (BOOLEAN) that indicates whether a record should be updated (TRUE) or inserted (FALSE) if it doesn't already exist. Which of the following SQL expressions correctly implement this logic within the 'merge' operation's 'WHEN MATCHED' and 'WHEN NOT MATCHED' clauses?
- A. WHEN MATCHED THEN UPDATE SET target_table.columnl = staging_df.columnl WHEN NOT MATCHED THEN INSERT (columni) VALUES (staging_df.columnl )
- B. WHEN MATCHED AND = TRUE THEN UPDATE SET target_table.columnl = staging_df.columnl WHEN NOT MATCHED AND = FALSE THEN INSERT (columni) VALUES (staging_df.columnl)
- C. WHEN MATCHED AND THEN UPDATE SET columni = staging_df.columnl WHEN NOT MATCHED AND NOT THEN INSERT (columni) VALUES (staging_df.columnl)
- D. WHEN MATCHED THEN UPDATE SET columni = staging_df.columnl WHEN NOT MATCHED THEN INSERT (columni) VALUES (staging_df.columnl)
- E. WHEN MATCHED AND = TRUE THEN UPDATE SET columni = staging_df.columnl WHEN NOT MATCHED AND = FALSE THEN INSERT (columni) VALUES (staging_df.columnl)
正解:C
解説:
The correct SQL expression utilizes the column within the 'WHEN MATCHED and 'WHEN NOT MATCHED clauses to conditionally determine whether to update or insert a record. Option E correctly checks the for 'TRUE in the 'WHEN MATCHED' clause and 'FALSE' in the 'WHEN NOT MATCHED clause to conditionally trigger the 'UPDATE' and 'INSERT operations, respectively. It uses Boolean algebra directly for concise condition checking. When the update_flag is True the update is executed, when false it is inserted. This implementation allows for a single 'merge' statement to handle both update and insert operations based on a flag within the staging data.
質問 # 135
You are working with a Snowpark DataFrame containing employee data, including columns 'employee_id', 'first_name', 'last_name', 'salary', and 'department'. You need to perform the following transformations: 1. Concatenate 'first_name' and into a new column called separating them with a space. 2. Increase each employee's salary by a percentage based on their 'department'. Department 'Sales' gets a 10% raise, 'Marketing' gets a 15% raise, and all other departments get a 5% raise. 3. Create a new column reflecting this raise. Which of the following Snowpark code snippets achieves these transformations correctly and efficiently? (Select all that apply)
正解:B、D
解説:
Options A and C are correct. Option A uses 'concat for string concatenation and 'when' for conditional salary calculation, which is a standard and efficient approach in Snowpark. Option C uses a Snowflake expression to achieve the same conditional salary calculation, which can be more concise for complex conditions and may leverage Snowflake's optimization. Option B is incorrect, because the '+' string concatenation will not work; string concatenation in Snowpark should happen using the 'concat' function. Option D is less efficient because it uses a Python UDF, which involves serialization/deserialization overhead. Option E will not work because of syntax 'select(' 'Y does not exist, therefore the user will need to specify all the columns. Also, there is a column called ' ' which will break the processing.
質問 # 136
You are working with Snowpark to create a DataFrame from a Python dictionary where keys represent column names and values are lists representing column data'. However, the dictionary contains lists of varying lengths for different columns. You need to create a DataFrame from the Python dictionary but are unsure how to create it. Which approach should you take and why?
- A. Attempt to create the DataFrame directly using 'session.createDataFrame(data)'. Snowpark will automatically pad the shorter lists with 'NULL' values to match the length of the longest list.
- B. DataFrame to a Snowpark DataFrame using 'session.createDataFrame(pandas_df)'. Snowpark does not support creating DataFrames directly from dictionaries with lists of varying lengths. The code will throw an error. So, manually build the logic of combining the lists.
- C. Manually pad all lists in the dictionary with 'None' values until they have the same length. Then, create the DataFrame using 'session.createDataFrame(data)'.
- D. Create a Pandas DataFrame from the dictionary first. Pandas handles lists of unequal lengths by filling the shorter lists with NaN. Then, convert the Pandas
- E. Transform the dictionary into a list of dictionaries or tuples, padding the short lists with 'None' values. Then, define a schema and use 'session.createDataFrame(data, schema=schema)' to create the DataFrame.
正解:C、E
解説:
Options B and E are the most appropriate solutions. Correctness and Rationale: Option B works. The reason is that padding all the lists to the same length will then allow the function to run correctly Correctness and Rationale: Option E also works. The reason is that the transformation to the dictionary to a list or tuple along with the 'session.createDataFrame(data, schema=schemay is also supported. The data types can be forced too to conform to datamodel. Option A is incorrect because it doesn't state an error. Option C, though technically functional by leveraging Pandas, is less efficient than creating Pandas DataFrame since Pandas creates another layer on top of Snowpark Option D is incorrect because Snowpark does support this scenario provided all lists are of equal length, with padding applied.
質問 # 137
You are building a Snowpark application that processes a large number of PDF files stored in a Snowflake stage. You need to extract text from each PDF file using a Python UDF and store the extracted text in a Snowflake table. You are considering different approaches for loading the PDF files into the UDE Which of the following approaches would provide the BEST performance and scalability, while minimizing network traffic and memory usage?
- A. Use the 'GET_OBJECT Snowflake SQL command to retrieve each file's contents and then pass the results as arguments into the UDF for processing. This allows use of pure SQL statements to access the files.
- B. Load the PDF files into a pandas DataFrame within the Snowpark application, then pass the DataFrame to the UDF. This way the PDF can be available to all workers in the dataframe.
- C. Use the 'snowflake.snowpark.functions.read' function in Python to read the PDF files directly from the stage within the UDF. This loads the file contents into a variable available for processing.
- D. Download all PDF files from the Snowflake stage to a local directory on the machine running the Snowpark application, then load the files from the local directory into the UDF.
- E. Pass the file path of each PDF file in the Snowflake stage to the UDF as a string. Within the UDF, use the 'snowflake.snowpark.files.SnowflakeFile' class to open and read the file. This will allow efficient access to the file directly from the stage.
正解:E
解説:
Option C is the most efficient approach. 'snowflake.snowpark.files.SnowflakeFile' allows the UDF to directly access the PDF files stored in the Snowflake stage without transferring the entire file to the client. This minimizes network traffic and memory usage. Option A requires loading all PDF files into a pandas DataFrame, which can consume a significant amount of memory. Option B has issues relating to the file size and content restrictions and isn't suitable for many files. Option D involves downloading all files to a local directory, which is not scalable and introduces unnecessary overhead. Option E using 'GET OBJECT is outside the scope of the python api.
質問 # 138
......
ここ数年、SPS-C01復習教材は、無数の受験者がSPS-C01試験に合格するのに役立ちました。SPS-C01認定資格証明書を取得した後、仕事機会が増え、偉大な企業家になり、専門家になった人もいました。SPS-C01復習教材は多くのいい評価をもらいました。良い評判で、SPS-C01復習教材を選択する人がますます増えています。
SPS-C01テスト難易度: https://www.jpntest.com/shiken/SPS-C01-mondaishu
- 実際的なSPS-C01試験関連情報一回合格-ハイパスレートのSPS-C01テスト難易度 🕟 ウェブサイト▷ jp.fast2test.com ◁を開き、⏩ SPS-C01 ⏪を検索して無料でダウンロードしてくださいSPS-C01受験対策
- SPS-C01試験の準備方法|高品質なSPS-C01試験関連情報試験|便利なSnowflake Certified SnowPro Specialty - Snowparkテスト難易度 🈺 ⏩ www.goshiken.com ⏪を開き、“ SPS-C01 ”を入力して、無料でダウンロードしてくださいSPS-C01最新試験
- 一番優秀なSPS-C01試験関連情報一回合格-権威のあるSPS-C01テスト難易度 🤖 ⇛ www.shikenpass.com ⇚を入力して➤ SPS-C01 ⮘を検索し、無料でダウンロードしてくださいSPS-C01日本語版対策ガイド
- SPS-C01練習問題 📫 SPS-C01日本語試験対策 🕑 SPS-C01日本語版対策ガイド 💍 ⮆ SPS-C01 ⮄を無料でダウンロード《 www.goshiken.com 》ウェブサイトを入力するだけSPS-C01最新な問題集
- ユニークSnowflake SPS-C01|100%合格率のSPS-C01試験関連情報試験|試験の準備方法Snowflake Certified SnowPro Specialty - Snowparkテスト難易度 💿 ➽ SPS-C01 🢪の試験問題は▷ www.xhs1991.com ◁で無料配信中SPS-C01最新テスト
- SPS-C01受験内容 🛳 SPS-C01受験対策 🤜 SPS-C01英語版 🚈 《 www.goshiken.com 》を入力して➡ SPS-C01 ️⬅️を検索し、無料でダウンロードしてくださいSPS-C01英語版
- SPS-C01資格復習テキスト 👡 SPS-C01最新日本語版参考書 ⬜ SPS-C01練習問題 🐽 検索するだけで⇛ www.goshiken.com ⇚から「 SPS-C01 」を無料でダウンロードSPS-C01無料過去問
- SPS-C01試験の準備方法|高品質なSPS-C01試験関連情報試験|便利なSnowflake Certified SnowPro Specialty - Snowparkテスト難易度 🈵 URL 【 www.goshiken.com 】をコピーして開き、【 SPS-C01 】を検索して無料でダウンロードしてくださいSPS-C01英語版
- SPS-C01資料的中率 🥋 SPS-C01資格復習テキスト ❤️ SPS-C01英語版 ⛄ 今すぐ☀ jp.fast2test.com ️☀️で⮆ SPS-C01 ⮄を検索し、無料でダウンロードしてくださいSPS-C01最新な問題集
- SPS-C01無料問題 🕣 SPS-C01テスト難易度 🍱 SPS-C01最新な問題集 😽 検索するだけで▷ www.goshiken.com ◁から( SPS-C01 )を無料でダウンロードSPS-C01練習問題
- SPS-C01試験の準備方法|正確的なSPS-C01試験関連情報試験|効果的なSnowflake Certified SnowPro Specialty - Snowparkテスト難易度 🎪 ➡ www.jpexam.com ️⬅️で( SPS-C01 )を検索して、無料で簡単にダウンロードできますSPS-C01最新テスト
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
2026年JPNTestの最新SPS-C01 PDFダンプおよびSPS-C01試験エンジンの無料共有:https://drive.google.com/open?id=11NX8jn0-MeEi5aFs1KAzdR87JD4DmTYN