Databricks Databricks-Certified-Data-Engineer-Professional対策学習 & Databricks-Certified-Data-Engineer-Professional専門知識訓練

ちなみに、Japancert Databricks-Certified-Data-Engineer-Professionalの一部をクラウドストレージからダウンロードできます:https://drive.google.com/open?id=1awmjRaisTzrXxZlSfyJCzT3LtrM11kFz
従来の見解では、練習資料は、実際の試験に現れる有用な知識を蓄積するために、それらに多くの時間を割く必要があります。 Japancertただし、Databricks Certified Data Engineer Professional Examの学習に関する質問はDatabricksその方法ではありません。 以前のDatabricks-Certified-Data-Engineer-Professional試験受験者のデータによると、合格率は最大98〜100%です。 最小限の時間と費用で試験に合格するのに役立つ十分なコンテンツがあります。Databricks Certified Data Engineer Professional Exam Databricks-Certified-Data-Engineer-Professional準備資料の最新コンテンツで学習できるように、当社の専門家が毎日更新状況を確認し、彼らの勤勉な仕事と専門的な態度が練習資料に高品質をもたらします。 Databricks Certified Data Engineer Professional Examトレーニングエンジンの初心者である場合は、疑わしいかもしれませんが、参照用に無料のデモが提供されています。
Databricks Databricks-Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Objectives |
|---|
| Topic 1: Delta Lake and Data Management | - Time travel and versioning
- Schema evolution and enforcement
- Delta Lake transactions and ACID properties
|
| Topic 2: Data Ingestion and Processing | - Batch and streaming ingestion with Auto Loader
- ETL pipeline design patterns
- Structured Streaming fundamentals
|
| Topic 3: Databricks Lakehouse Platform Architecture | - Workspace and cluster architecture
- Medallion architecture (Bronze, Silver, Gold)
- Data governance concepts (Unity Catalog basics)
|
| Topic 4: Production Pipelines and Orchestration | - Job scheduling and monitoring
- Databricks Workflows
- Error handling and recovery strategies
|
| Topic 5: Data Modeling and Transformation | - Performance optimization techniques
- Spark SQL transformations
- Dimensional modeling concepts
|
>> Databricks Databricks-Certified-Data-Engineer-Professional対策学習 <<
素敵なDatabricks-Certified-Data-Engineer-Professional対策学習試験-試験の準備方法-100%合格率のDatabricks-Certified-Data-Engineer-Professional専門知識訓練
JapancertのDatabricksのDatabricks-Certified-Data-Engineer-Professional試験トレーニング資料は試験問題と解答を含まれて、豊富な経験を持っているIT業種の専門家が長年の研究を通じて作成したものです。その権威性は言うまでもありません。うちのDatabricksのDatabricks-Certified-Data-Engineer-Professional試験トレーニング資料を購入する前に、Japancertのサイトで、一部分のフリーな試験問題と解答をダンロードでき、試用してみます。君がうちの学習教材を購入した後、私たちは一年間で無料更新サービスを提供することができます。
Databricks Certified Data Engineer Professional Exam 認定 Databricks-Certified-Data-Engineer-Professional 試験問題 (Q213-Q218):
質問 # 213
In order to prevent accidental commits to production data, a senior data engineer has instituted a policy that all development work will reference clones of Delta Lake tables. After testing both deep and shallow clone, development tables are created using shallow clone. A few weeks after initial table creation, the cloned versions of several tables implemented as Type 1 Slowly Changing Dimension (SCD) stop working. The transaction logs for the source tables show that vacuum was run the day before.
Why are the cloned tables no longer working?
- A. Running vacuum automatically invalidates any shallow clones of a table; deep clone should always be used when a cloned table will be repeatedly queried.
- B. The metadata created by the clone operation is referencing data files that were purged as invalid by the vacuum command
- C. The data files compacted by vacuum are not tracked by the cloned metadata; running refresh on the cloned table will pull in recent changes.
- D. Because Type 1 changes overwrite existing records, Delta Lake cannot guarantee data consistency for cloned tables.
- E. Tables created with SHALLOW CLONE are automatically deleted after their default retention threshold of 7 days.
正解:B
解説:
In Delta Lake, a shallow clone creates a new table by copying the metadata of the source table without duplicating the data files. When the vacuum command is run on the source table, it removes old data files that are no longer needed to maintain the transactional log's integrity, potentially including files referenced by the shallow clone's metadata. If these files are purged, the shallow cloned tables will reference non-existent data files, causing them to stop working properly. This highlights the dependency of shallow clones on the source table's data files and the impact of data management operations like vacuum on these clones.
質問 # 214
A data engineer wants to reflector the following DLT code, which includes multiple definition with very similar code:
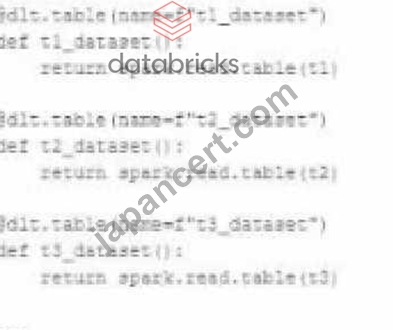
In an attempt to programmatically create these tables using a parameterized table definition, the data engineer writes the following code.
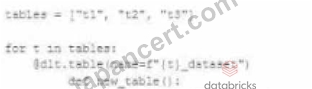
The pipeline runs an update with this refactored code, but generates a different DAG showing incorrect configuration values for tables.
How can the data engineer fix this?
- A. Wrap the loop inside another table definition, using generalized names and properties to replace with those from the inner table
- B. Load the configuration values for these tables from a separate file, located at a path provided by a pipeline parameter.
- C. Convert the list of configuration values to a dictionary of table settings, using table names as keys.
- D. Convert the list of configuration values to a dictionary of table settings, using different input the for loop.
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from
正解:C
解説:
The issue with the refactored code is that it tries to use string interpolation to dynamically create table names within the dlc.table decorator, which will not correctly interpret the table names.
Instead, by using a dictionary with table names as keys and their configurations as values, the data engineer can iterate over the dictionary items and use the keys (table names) to properly configure the table settings. This way, the decorator can correctly recognize each table name, and the corresponding configuration settings can be applied appropriately.
質問 # 215
A small company based in the United States has recently contracted a consulting firm in India to implement several new data engineering pipelines to power artificial intelligence applications. All the company's data is stored in regional cloud storage in the United States.
The workspace administrator at the company is uncertain about where the Databricks workspace used by the contractors should be deployed.
Assuming that all data governance considerations are accounted for, which statement accurately informs this decision?
- A. Databricks notebooks send all executable code from the user's browser to virtual machines over the open internet; whenever possible, choosing a workspace region near the end users is the most secure.
- B. Databricks leverages user workstations as the driver during interactive development; as such, users should always use a workspace deployed in a region they are physically near.
- C. Databricks workspaces do not rely on any regional infrastructure; as such, the decision should be made based upon what is most convenient for the workspace administrator.
- D. Databricks runs HDFS on cloud volume storage; as such, cloud virtual machines must be deployed in the region where the data is stored.
- E. Cross-region reads and writes can incur significant costs and latency; whenever possible, compute should be deployed in the same region the data is stored.
正解:E
解説:
This is the correct answer because it accurately informs this decision. The decision is about where the Databricks workspace used by the contractors should be deployed. The contractors are based in India, while all the company's data is stored in regional cloud storage in the United States. When choosing a region for deploying a Databricks workspace, one of the important factors to consider is the proximity to the data sources and sinks. Cross-region reads and writes can incur significant costs and latency due to network bandwidth and data transfer fees.
Therefore, whenever possible, compute should be deployed in the same region the data is stored to optimize performance and reduce costs.
質問 # 216
A data engineer is implementing a job to download multiple PDF files from a third-party provided REST API endpoint by specifying different report types. The REST API is time-consuming and encounters intermittent errors, so the engineer wants to track each download activity to know when it fails and to retry partially, while providing scalable throughput. The engineer needs to download ten report types, and the list can be changed over time. How should the data engineer achieve this?
- A. Use a foreach task with a list of report types as its inputs.
- B. Define a list variable within a Notebook to loop through the report types to download them, and print the download results. Execute it as a Notebook tasks.
- C. Use a Delta Lake table to track each report download status as 10 rows, and use it as a source table to execute the download function as a Pandas UDF.
- D. Define ten Notebook tasks to clearly track which report download failed.
正解:A
解説:
A foreach task allows the job to dynamically iterate over a configurable list of report types, execute downloads in parallel, and track the success or failure of each item independently. This enables scalable throughput, partial retries for failed downloads, and easy updates when the list of report types changes, without hardcoding tasks or introducing unnecessary complexity.
質問 # 217
A junior data engineer seeks to leverage Delta Lake's Change Data Feed functionality to create a Type 1 table representing all of the values that have ever been valid for all rows in a bronze table created with the property delta.enableChangeDataFeed = true. They plan to execute the following code as a daily job:
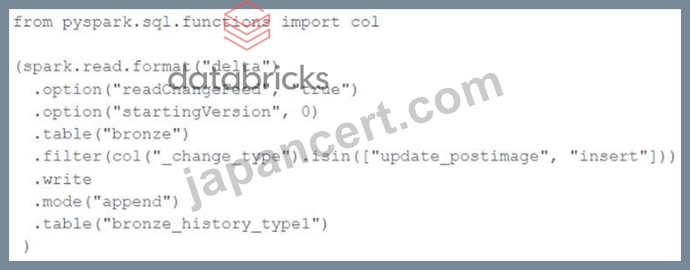
Which statement describes the execution and results of running the above query multiple times?
- A. Each time the job is executed, newly updated records will be merged into the target table, overwriting previous values with the same primary keys.
- B. Each time the job is executed, the differences between the original and current versions are calculated; this may result in duplicate entries for some records.
- C. Each time the job is executed, only those records that have been inserted or updated since the last execution will be appended to the target table giving the desired result.
- D. Each time the job is executed, the target table will be overwritten using the entire history of inserted or updated records, giving the desired result.
- E. Each time the job is executed, the entire available history of inserted or updated records will be appended to the target table, resulting in many duplicate entries.
正解:E
解説:
Reading table's changes, captured by CDF, using spark.read means that you are reading them as a static source. So, each time you run the query, all table's changes (starting from the specified startingVersion) will be read.
質問 # 218
......
今日、知識は精神労働よりも多くの富を生み出すことができるため、知識能力と精神労働は肉体労働よりも価値があります。ある分野で専門知識の能力を高めれば、多くの価値を生み出し、高収入で良い仕事を得ることができます。 Databricks-Certified-Data-Engineer-Professional認定試験に合格すると、その達成に役立ちます。Databricks-Certified-Data-Engineer-Professionalトレーニング資料は、Databricks-Certified-Data-Engineer-Professionalテストの準備に最適な学習資料です。 Databricks-Certified-Data-Engineer-Professionalガイド資料では、重要な情報を組み合わせて、クライアントが基盤を固め、時代とともに前進するのを支援します。
Databricks-Certified-Data-Engineer-Professional専門知識訓練: https://www.japancert.com/Databricks-Certified-Data-Engineer-Professional.html
- Databricks-Certified-Data-Engineer-Professional学習指導 🕦 Databricks-Certified-Data-Engineer-Professional日本語対策 🔯 Databricks-Certified-Data-Engineer-Professional試験関連赤本 💜 ウェブサイト➤ www.xhs1991.com ⮘から▶ Databricks-Certified-Data-Engineer-Professional ◀を開いて検索し、無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional認定試験
- Databricks-Certified-Data-Engineer-Professional試験の準備方法 | 検証するDatabricks-Certified-Data-Engineer-Professional対策学習試験 | 実際的なDatabricks Certified Data Engineer Professional Exam専門知識訓練 👡 { www.goshiken.com }サイトにて▶ Databricks-Certified-Data-Engineer-Professional ◀問題集を無料で使おうDatabricks-Certified-Data-Engineer-Professional受験準備
- ユニークなDatabricks-Certified-Data-Engineer-Professional対策学習 - 合格スムーズDatabricks-Certified-Data-Engineer-Professional専門知識訓練 | 有難いDatabricks-Certified-Data-Engineer-Professional認定内容 💙 ⇛ www.it-passports.com ⇚に移動し、[ Databricks-Certified-Data-Engineer-Professional ]を検索して、無料でダウンロード可能な試験資料を探しますDatabricks-Certified-Data-Engineer-Professional資格関連題
- ユニークなDatabricks-Certified-Data-Engineer-Professional対策学習 - 合格スムーズDatabricks-Certified-Data-Engineer-Professional専門知識訓練 | 有難いDatabricks-Certified-Data-Engineer-Professional認定内容 🥇 ▶ www.goshiken.com ◀サイトで➥ Databricks-Certified-Data-Engineer-Professional 🡄の最新問題が使えるDatabricks-Certified-Data-Engineer-Professional認定資格試験問題集
- ユニークなDatabricks-Certified-Data-Engineer-Professional対策学習 - 合格スムーズDatabricks-Certified-Data-Engineer-Professional専門知識訓練 | 有難いDatabricks-Certified-Data-Engineer-Professional認定内容 🐝 ➠ www.passtest.jp 🠰に移動し、( Databricks-Certified-Data-Engineer-Professional )を検索して、無料でダウンロード可能な試験資料を探しますDatabricks-Certified-Data-Engineer-Professional試験関連赤本
- Databricks Databricks-Certified-Data-Engineer-Professional対策学習: Databricks Certified Data Engineer Professional Exam - 最新のDatabricks 認定トレーリング 💚 “ www.goshiken.com ”で➡ Databricks-Certified-Data-Engineer-Professional ️⬅️を検索し、無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professionalテスト資料
- Databricks-Certified-Data-Engineer-Professional認定資格試験問題集 🤽 Databricks-Certified-Data-Engineer-Professional学習指導 🚎 Databricks-Certified-Data-Engineer-Professional合格体験談 ☣ ⏩ www.passtest.jp ⏪を開き、▶ Databricks-Certified-Data-Engineer-Professional ◀を入力して、無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional日本語対策
- Databricks-Certified-Data-Engineer-Professional資格取得 🍍 Databricks-Certified-Data-Engineer-Professional受験対策 🚣 Databricks-Certified-Data-Engineer-Professional認証資格 💃 ➥ www.goshiken.com 🡄に移動し、《 Databricks-Certified-Data-Engineer-Professional 》を検索して無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional復習攻略問題
- ユニークなDatabricks-Certified-Data-Engineer-Professional対策学習 - 合格スムーズDatabricks-Certified-Data-Engineer-Professional専門知識訓練 | 有難いDatabricks-Certified-Data-Engineer-Professional認定内容 🐣 サイト☀ www.japancert.com ️☀️で▶ Databricks-Certified-Data-Engineer-Professional ◀問題集をダウンロードDatabricks-Certified-Data-Engineer-Professional受験準備
- Databricks-Certified-Data-Engineer-Professional勉強の資料 📷 Databricks-Certified-Data-Engineer-Professional復習攻略問題 🚎 Databricks-Certified-Data-Engineer-Professionalファンデーション 🦕 ➥ Databricks-Certified-Data-Engineer-Professional 🡄を無料でダウンロード⮆ www.goshiken.com ⮄ウェブサイトを入力するだけDatabricks-Certified-Data-Engineer-Professional必殺問題集
- 実用的なDatabricks-Certified-Data-Engineer-Professional対策学習 - 合格スムーズDatabricks-Certified-Data-Engineer-Professional専門知識訓練 | 一生懸命にDatabricks-Certified-Data-Engineer-Professional認定内容 🐈 ▷ www.topexam.jp ◁サイトにて最新➤ Databricks-Certified-Data-Engineer-Professional ⮘問題集をダウンロードDatabricks-Certified-Data-Engineer-Professionalファンデーション
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.twosapp.com, www.stes.tyc.edu.tw, Disposable vapes
無料でクラウドストレージから最新のJapancert Databricks-Certified-Data-Engineer-Professional PDFダンプをダウンロードする:https://drive.google.com/open?id=1awmjRaisTzrXxZlSfyJCzT3LtrM11kFz