How You Can Ace Your Exam Preparation With BraindumpStudy NCA-GENM Exam Questions?

BONUS!!! Download part of BraindumpStudy NCA-GENM dumps for free: https://drive.google.com/open?id=1qLsrsrhHMMYW2OaTz3VlKe6Wlg5mzA8d
BraindumpStudy experts have also developed NVIDIA Generative AI Multimodal (NCA-GENM) test simulation software for you to assess and improve yourself. This is especially useful for intensive preparation and revision. It will provide you with an NVIDIA Generative AI Multimodal (NCA-GENM) exam environment and will give you real exam NVIDIA NCA-GENM questions.
| Section | Weight | Objectives |
|---|
| Topic 1: Trustworthy AI | 5% | - Reliability, fairness, and safety in generative systems
- Ethical considerations and responsible use
- Robustness and error mitigation
|
| Topic 2: Performance Optimization | 10% | - Scalability and deployment considerations
- Model efficiency and inference optimization
- Hardware acceleration with NVIDIA platforms
|
| Topic 3: Data Analysis and Visualization | 10% | - Interpretation of generative AI outputs
- Analyzing multimodal datasets and outputs
- Visualization techniques for model behavior and results
|
| Topic 4: Core Machine Learning and AI Knowledge | 20% | - Generative AI principles and techniques
- Fundamental concepts of machine learning and deep learning
- Neural network architectures relevant to multimodal systems
|
| Topic 5: Multimodal Data | 15% | - Multimodal model architectures and integration
- Data preprocessing, fusion, and representation
- Characteristics of text, image, and audio data
|
| Topic 6: Software Development and Engineering | 15% | - Development workflows for generative AI applications
- Libraries, frameworks, and tools for multimodal AI
- Best practices for building and maintaining systems
|
| Topic 7: Experimentation | 25% | - Model training, fine-tuning, and evaluation
- Metrics and validation strategies for generative models
- Experiment design and methodology
|
>> NCA-GENM Updated Testkings <<
NVIDIA NCA-GENM Updated Testkings: NVIDIA Generative AI Multimodal - BraindumpStudy Help you Prepare Exam Easily
If you want to through the NVIDIA NCA-GENM certification exam to make a stronger position in today's competitive IT industry, then you need the strong expertise knowledge and the accumulated efforts. And pass the NVIDIA NCA-GENM exam is not easy. Perhaps through NVIDIA NCA-GENM exam you can promote yourself to the IT industry. But it is not necessary to spend a lot of time and effort to learn the expertise. You can choose BraindumpStudy's NVIDIA NCA-GENM Exam Training materials. This is training product that specifically made for IT exam. With it you can pass the difficult NVIDIA NCA-GENM exam effortlessly.
NVIDIA Generative AI Multimodal Sample Questions (Q36-Q41):
NEW QUESTION # 36
You are working on a generative A1 model that creates descriptions of images. During experimentation, you notice the model consistently generates descriptions that are factually incorrect about objects in the image, despite the image quality being high. For example, it might describe a 'cat' as a 'dog'. What is the MOST critical step to address this issue?
- A. Use a more complex model architecture.
- B. Apply image sharpening filters to the input images.
- C. Fine-tune the model using a smaller learning rate.
- D. Implement a mechanism to verify the generated descriptions against an external knowledge base or object recognition system.
- E. Increase the training data size with more diverse images.
Answer: D
Explanation:
Factually incorrect descriptions indicate a lack of grounding in real-world knowledge. Verifying against an external knowledge base (B) directly addresses this issue. Increasing data size (A) might help, but it's not guaranteed. Fine-tuning (C) and increasing model complexity (D) might not solve the grounding problem. Image sharpening (E) is irrelevant to factual accuracy.
NEW QUESTION # 37
Consider the following code snippet used in training a multimodal model:
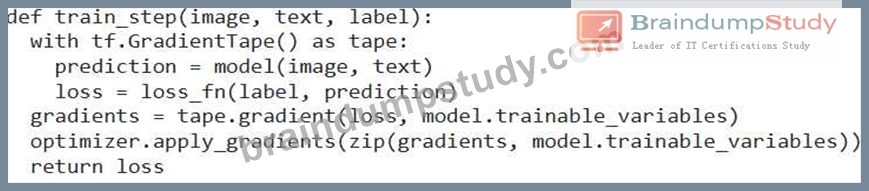
During experimentation, you discover that the image modality contributes negligibly to the final prediction. How would you modify the training loop to dynamically adjust the importance of each modality?
- A. Implement a separate loss function for the image modality and adjust its weight based on validation performance.
- B. Compute modality-specific gradients and apply a scaling factor to the image gradients based on their magnitude relative to the text gradients.
- C. Apply a fixed weight to the image features before feeding them into the model.
- D. Use a curriculum learning approach where the model is initially trained only on the text modality, and the image modality is gradually introduced.
- E. Introduce a modality dropout mechanism that randomly drops either the image or text modality during each training iteration.
Answer: B
Explanation:
Dynamically scaling gradients based on their magnitude allows the model to automatically adjust the importance of each modality during training. If the image gradients are small compared to the text gradients, the scaling factor will increase their influence, encouraging the model to learn from the image modality. Modality dropout is helpful, however gradient scaling provides finer control.
NEW QUESTION # 38
You have trained a multimodal model to generate descriptions for recipes, using images of the finished dish as one modality and a list of ingredients as another. When evaluating the generated descriptions, you notice the descriptions are factually correct in terms of ingredients but often fail to capture the stylistic nuances or tone of professionally written recipes. Which evaluation strategy would provide the most insightful feedback on this aspect of the model's performance?
- A. Conduct a human evaluation where individuals rate the generated descriptions based on factors such as informativeness, clarity, and stylistic appropriateness.
- B. Calculate the BLEU score between the generated descriptions and a set of reference recipes.
- C. Use a pre-trained language model to assess the fluency and coherence of the generated descriptions.
- D. Compute the ROUGE score between the generated descriptions and a set of reference recipes.
- E. Measure the perplexity of the generated descriptions using a language model trained on a corpus of recipe books.
Answer: A
Explanation:
Human evaluation is the most reliable way to assess subjective aspects of the generated text, such as stylistic appropriateness. While automated metrics like BLEU, ROUGE, and perplexity can provide insights into factual accuracy and fluency, they do not capture the nuances of style and tone as effectively as human judgment. Therefore, the correct answer is (D).
NEW QUESTION # 39
You're training a multimodal model for generating stories from images and audio. You use a Transformer architecture. During training, you notice that the model struggles to maintain long-range dependencies in the generated stories, leading to incoherent narratives. Which of the following techniques would be MOST effective in addressing this issue within the Transformer architecture?
- A. Using only audio as input.
- B. Removing the self-attention mechanism.
- C. Using a smaller embedding dimension.
- D. Incorporating positional encodings and increasing the attention window size.
- E. Reducing the number of layers in the Transformer.
Answer: D
Explanation:
Positional encodings help the Transformer understand the order of words in the sequence, which is crucial for maintaining coherence. Increasing the attention window size allows the model to attend to a larger context when generating each word, enabling it to capture longer-range dependencies. Reducing layers or embedding dimension would likely worsen the problem. Removing self-attention would defeat the purpose of using a Transformer. Positional encodings and attention window size are key to transformer performance with respect to long range dependencies.
NEW QUESTION # 40
Consider a scenario where you are building a multimodal model to generate realistic indoor scenes. You have access to text descriptions of the scene, 3D models of furniture, and ambient sound recordings. Which of the following loss functions would be most appropriate to ensure coherence and realism in the generated scenes?
- A. Cosine similarity loss between the generated image and the input 3D models.
- B. Cross-entropy loss for classifying different object categories in the scene.
- C. A combination of adversarial loss (GAN) to ensure realism, a perceptual loss to match high-level features, and a semantic consistency loss to align the generated image with the input text description.
- D. KL Divergence loss between the generated sound and the input text.
- E. Mean Squared Error (MSE) between the generated image and a reference image.
Answer: C
Explanation:
A combination of adversarial loss, perceptual loss, and semantic consistency loss provides the best approach. Adversarial loss enhances realism, perceptual loss focuses on high-level feature matching, and semantic consistency loss aligns the generated image with the input text, ensuring a coherent and realistic scene.
NEW QUESTION # 41
......
From BraindumpStudy website you can free download part of BraindumpStudy's latest NVIDIA certification NCA-GENM exam practice questions and answers as a free try, and it will not let you down. BraindumpStudy latest NVIDIA certification NCA-GENM exam practice questions and answers and real exam questions is very close. You may have also seen on other sites related training materials, but will find their Source BraindumpStudy of you carefully compare. The BraindumpStudy provide more comprehensive information, including the current exam questions, with their wealth of experience and knowledge by BraindumpStudy team of experts to come up against NVIDIA Certification NCA-GENM Exam.
NCA-GENM Training Tools: https://www.braindumpstudy.com/NCA-GENM_braindumps.html
- 100% Pass 2026 NVIDIA Newest NCA-GENM: NVIDIA Generative AI Multimodal Updated Testkings 🐹 Open 「 www.exam4labs.com 」 enter ⏩ NCA-GENM ⏪ and obtain a free download 🔖Exam NCA-GENM Cram Review
- Exam NCA-GENM Cram Review 📝 NCA-GENM Related Certifications 👘 NCA-GENM Related Certifications 🤽 Enter ➽ www.pdfvce.com 🢪 and search for ⏩ NCA-GENM ⏪ to download for free 📞NCA-GENM Sample Questions Pdf
- NCA-GENM Related Certifications 🔵 Valid Exam NCA-GENM Braindumps 🤵 NCA-GENM Reliable Test Online 🧙 Search for 【 NCA-GENM 】 and obtain a free download on “ www.pdfdumps.com ” 💰NCA-GENM Practice Test Engine
- Quiz 2026 NCA-GENM: Professional NVIDIA Generative AI Multimodal Updated Testkings 🏞 Search on 《 www.pdfvce.com 》 for ▛ NCA-GENM ▟ to obtain exam materials for free download 👖Valid Exam NCA-GENM Braindumps
- NCA-GENM Testking Learning Materials 🐞 NCA-GENM Sample Questions Pdf 🌋 NCA-GENM Printable PDF 🏎 Download 【 NCA-GENM 】 for free by simply searching on ⮆ www.prepawayete.com ⮄ 🏵NCA-GENM Sample Questions Pdf
- Precise NCA-GENM Updated Testkings Offers you high-effective Actual NVIDIA NVIDIA Generative AI Multimodal Exam Products 🌵 The page for free download of ▛ NCA-GENM ▟ on ☀ www.pdfvce.com ️☀️ will open immediately 🥨NCA-GENM Valid Vce Dumps
- NCA-GENM Authorized Exam Dumps 🏐 NCA-GENM Practice Test Engine 🍬 NCA-GENM Sample Questions Pdf 🎇 Search for { NCA-GENM } and download it for free on { www.dumpsquestion.com } website 😹Exam NCA-GENM Answers
- Practical NCA-GENM Question Dumps is Very Convenient for You - Pdfvce 🗽 Search on ➽ www.pdfvce.com 🢪 for ⏩ NCA-GENM ⏪ to obtain exam materials for free download 📎Reliable Test NCA-GENM Test
- NVIDIA NCA-GENM Questions: Fosters Your Exam Passing Abilities [2026] 🦟 Open ⮆ www.vce4dumps.com ⮄ and search for 【 NCA-GENM 】 to download exam materials for free 🚕NCA-GENM New Braindumps Questions
- NCA-GENM Quiz Studying Materials: NVIDIA Generative AI Multimodal - NCA-GENM Test Torrent - NCA-GENM Test Bootcamp 🦯 The page for free download of ⇛ NCA-GENM ⇚ on ▷ www.pdfvce.com ◁ will open immediately 🦂NCA-GENM Testking Learning Materials
- NVIDIA NCA-GENM Questions: Fosters Your Exam Passing Abilities [2026] 🦯 Search for 【 NCA-GENM 】 and download exam materials for free through ✔ www.torrentvce.com ️✔️ 🎪NCA-GENM Reliable Test Online
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
What's more, part of that BraindumpStudy NCA-GENM dumps now are free: https://drive.google.com/open?id=1qLsrsrhHMMYW2OaTz3VlKe6Wlg5mzA8d