Our AI-500 study materials can have such a high pass rate, and it is the result of step by step that all members uphold the concept of customer first. If you use a trial version of AI-500 training prep, you can find that our study materials have such a high passing rate and so many users support it. After using the trial version, we believe that you will be willing to choose AI-500 Exam Questions.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Architect multi-agent solutions | 15–20% | - Design workflow and tool integration
|
| Topic 2: Evaluate, optimize, and monitor multi-agent solutions | 20–25% | - Assess performance and reliability
|
| Topic 3: Secure, govern, and deploy multi-agent solutions | 20–25% | - Apply security and compliance
|
| Topic 4: Develop multi-agent solutions in Azure | 30–35% | - Manage state and memory
|
>> Valid AI-500 Exam Papers <<
If you have a strong desire to get the Microsoft certificate, our AI-500 study materials are the best choice for you. At present, the certificate has gained wide popularity. So the official test syllabus of the AI-500 exam begins to become complicated. So you must accept professional guidance. After all, lots of people are striving to compete with many candidates. Powerful competitiveness is crucial to pass the AI-500 Exam. Maybe you think that our AI-500 study materials cannot make a difference. But you must know that if you do not have a try, your life will never be improved. It is useless that you speak boast yourself but never act. Please muster up all your courage. No one will laugh at a hardworking person. Our AI-500 study materials are your good study partner.
NEW QUESTION # 51
You have a Microsoft Foundry multi-agent customer support solution that retrieves grounding data from a shared vector index. The indexed corpus contains product runbooks in Markdown and support articles in HTML Both document types use a consistent hierarchical markup.
You discover that current fixed-size token chunking creates chunks that cross section boundaries.
You need to recommend a chunking approach for the ingestion pipeline. The solution must preserve existing document structure boundaries and minimize custom chunking code.
What should you recommend?
Answer: A
Explanation:
The corpus already contains reliable document hierarchy in Markdown and HTML, so the ingestion pipeline should preserve those author-defined boundaries rather than infer new ones from token counts or topic shifts.
Format-specific header splitters can divide Markdown by heading levels and HTML by structural headers, producing chunks that align with meaningful sections. This directly solves the current problem of fixed-size token chunks crossing section boundaries and requires less custom logic than building a semantic topic-shift chunker. Recursive character splitting can be configured with structure-aware separators, but it remains a more generic fallback when format-specific structure is already available. Microsoft Azure AI Search guidance recommends exploiting document structure such as headings when chunking. Therefore B is the most direct and maintainable approach. In production, add telemetry and regression tests around this behavior so changes to prompts, models, tools, or orchestration do not silently alter the intended contract. The selected approach is the one that best matches the platform ' s native execution semantics.
Official Microsoft reference: Azure AI Search - structure-aware chunking and Markdown indexing
NEW QUESTION # 52
You have a Microsoft Foundry multi-agent customer support solution. The solution includes an orchestrator that starts a single conversation trace when a user request arrives and can invoke two agents named Agent1 and Agent2 concurrently. Each agent can invoke Model Context Protocol (MCP)-hosted tools and dependent REST APIs.
The solution uses OpenTelemetry SDKs to emit logs, metrics, and traces via OTLP to an OpenTelemetry Collector. The solution emits the conversation ID, trace ID, and span ID for agent invocations, tool invocations, and external API calls.
You have a monitoring dashboard that includes:
* Latency
* Throughput
* Reliability
* Token usage
* Content safety triggers
* Time to First Token (TTFT)
Alert rules are configured for latency anomalies and tool invocation failures.
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.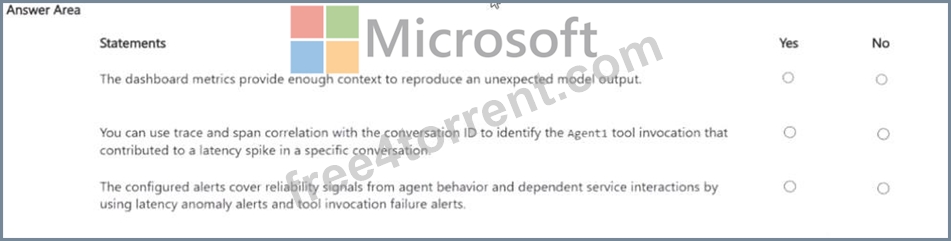
Answer:
Explanation: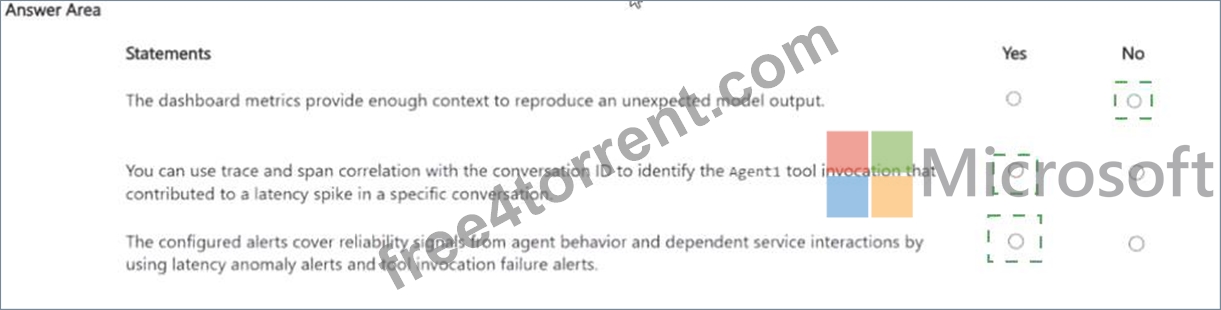
Explanation:
No / Yes / Yes
Aggregate dashboard metrics do not provide enough execution context to reproduce a specific unexpected model output, so the first statement is false. Reproduction normally requires detailed trace data such as model inputs/outputs, ordered agent spans, tool calls, and dependency results. The second statement is true because the solution emits conversation, trace, and span identifiers across agent, MCP tool, and REST API calls.
OpenTelemetry correlation can therefore isolate the Agent1 tool span that contributed to a latency spike in one conversation. The third statement is also true: latency-anomaly alerts and tool-invocation failure alerts cover important reliability signals from both agent execution and dependent service interactions. They are not the entire observability strategy, but they do address the reliability conditions described. The correct sequence is No, Yes, Yes. The evaluation should also preserve correlation identifiers and version information where possible so a failed score can be traced back to the exact agent, model, tool call, or retrieval step that produced it. This turns the metric into an actionable diagnostic rather than only a dashboard number.
Official Microsoft reference: Microsoft Foundry - agent tracing concepts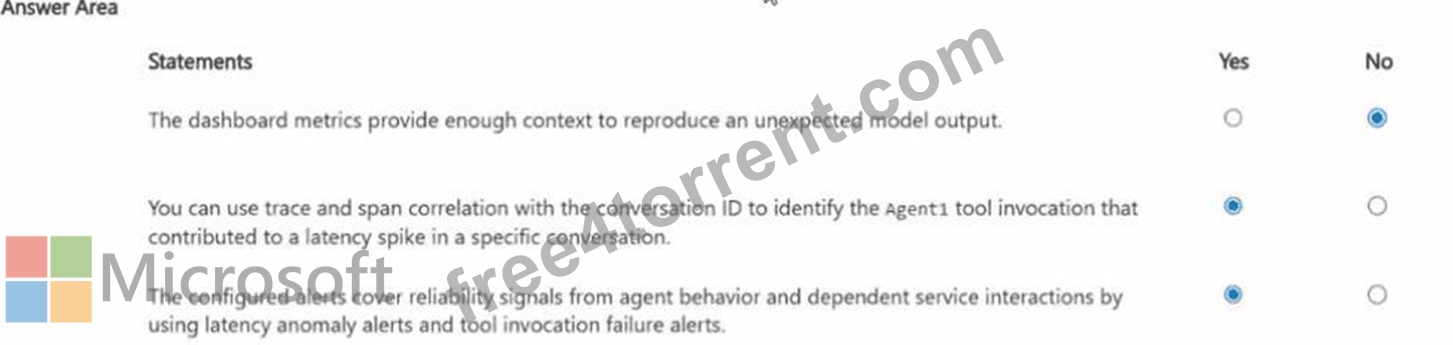
NEW QUESTION # 53
You have a multi-agent solution in a Microsoft Foundry project. The project connects to an Azure Storage account named stgaudit.
You plan to enable a storage-backed tool for the agent The tool will read and write blobs to stgaudit.
You need to create a role assignment for the agent. The solution must follow the principle of least privilege.
Which role should you use?
Answer: A
NEW QUESTION # 54
You have a LangGraph workflow in Microsoft Foundry that is compiled as app by using a checkpointer. Each request includes a value named ticket_id.
You need to instrument the workflow so that each streamed run sends OpenTelemetry traces to Observability in Foundry. The solution must meet the following requirements:
* Correlate graph steps and tool calls for each request by the supplied ticket__id.
* Use the Azure Al OpenTelemetry tracer with the LangGraph invocation.
How should you complete the code? To answer, select the appropriate options in the answer area NOTE: Each correct selection is worth one point.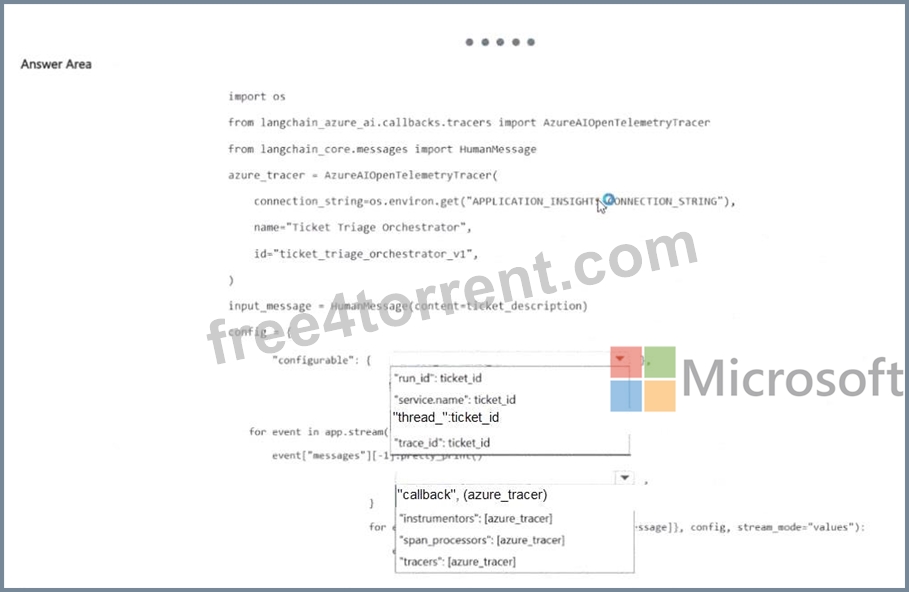
Answer:
Explanation: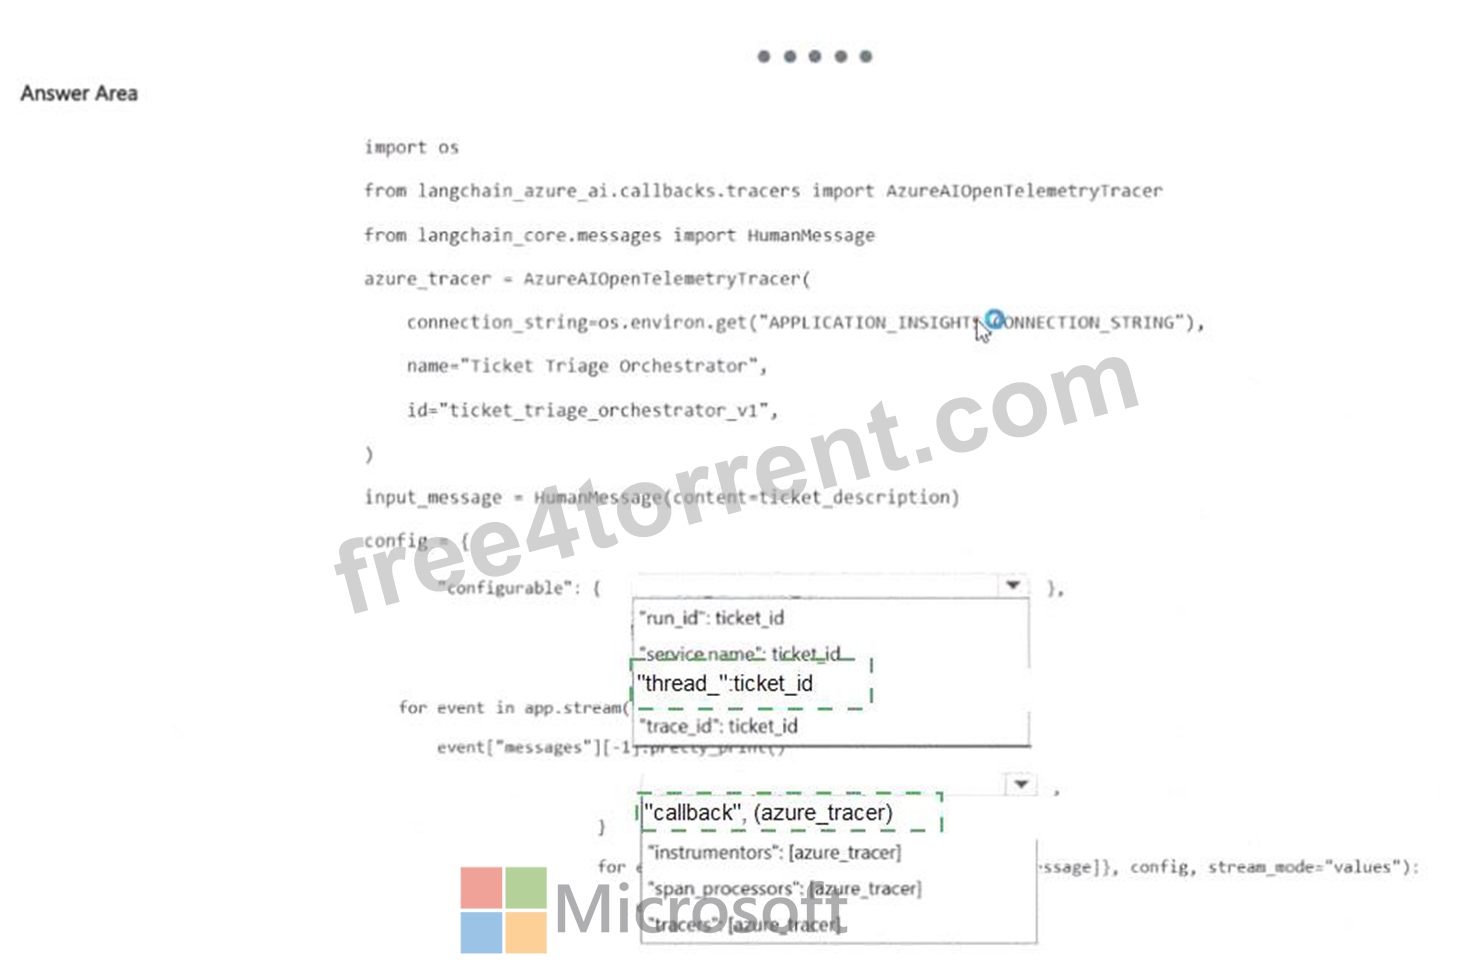
Explanation:
` " thread_id " : ticket_id` and ` " callbacks " : [azure_tracer]`.
LangGraph checkpointers use a stable `thread_id` under the configurable invocation context to associate execution and persisted state with the same logical request or conversation. Setting that value to the supplied
`ticket_id` allows graph steps and tool calls to be correlated to the ticket across a streamed run. Microsoft Foundry ' s LangGraph integration also uses `AzureAIOpenTelemetryTracer` through LangChain/LangGraph callbacks. Adding the tracer in the `callbacks` list causes agent, model, and tool spans to be emitted through OpenTelemetry and become visible in Foundry/Application Insights. A random run ID would not provide the stable checkpointer identity needed for state continuity, and fields such as `span_processors` are configured at a different instrumentation layer. Therefore the two code completions shown in the answer are correct. A robust evaluation program separates process metrics from final-response metrics. The selected answer measures the layer where the stated failure actually occurs, which is essential for deciding whether to change retrieval, orchestration, prompt behavior, or the final generator.
Official Microsoft reference: Microsoft Foundry - develop LangChain/LangGraph agents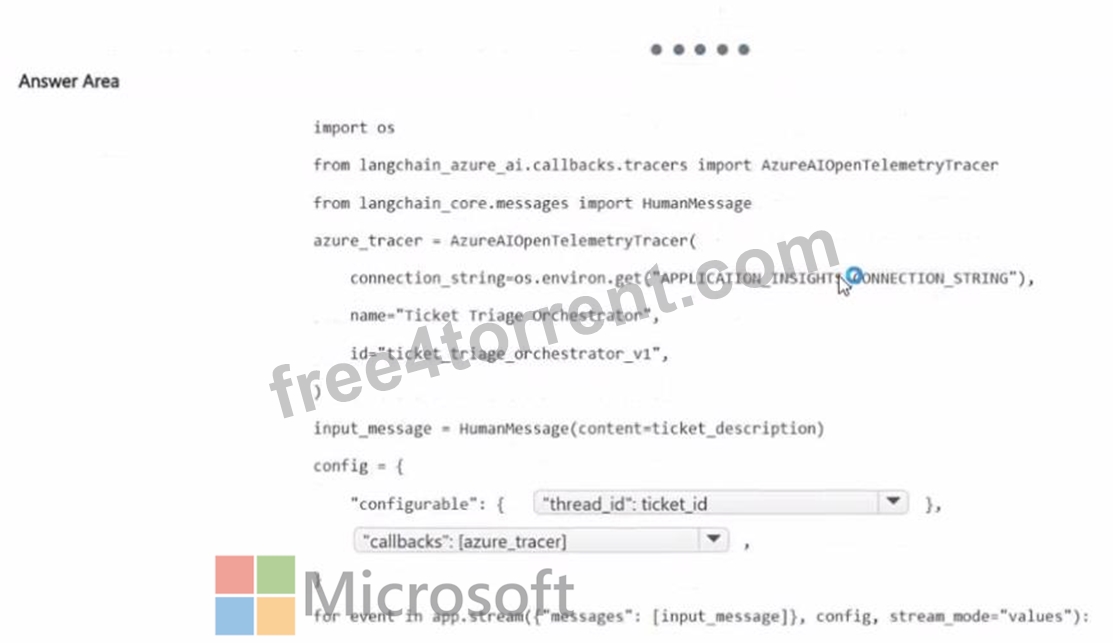
NEW QUESTION # 55
You have a multi-agent Retrieval-Augmented Generation (RAG) solution that uses a Foundry IQ knowledge base. The solution includes a support agent and a policy agent.
You have an evaluation dataset that contains the following for each user query
* The expected source IDs
* Retrieved chunks in rank order
* The final agent response
You discover that an embedding model change and a custom analyzer change cause the failed traces shown in the following table.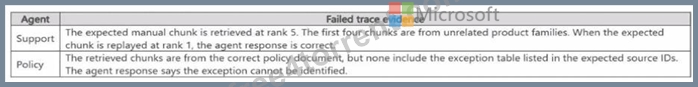
You need to isolate the failing parts of the RAG pipeline.
Which evaluator should you use for each agent? To answer, drag the appropriate evaluators to the correct agents. Each evaluator may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content NOTE: Each correct selection is worth one point.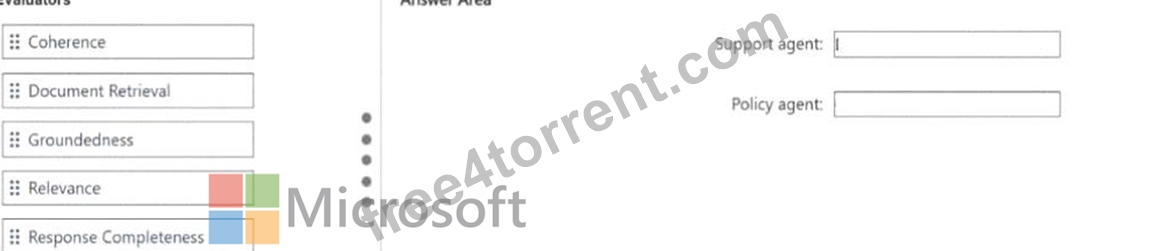
Answer:
Explanation: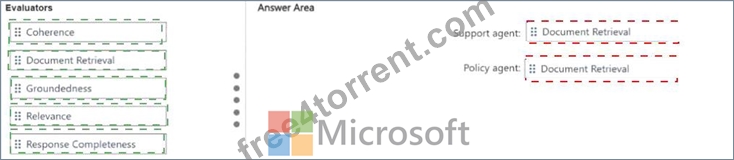
Explanation:
Support agent: Document Retrieval; Policy agent: Document Retrieval.
Both failures are retrieval failures and should therefore be diagnosed with the Document Retrieval evaluator.
The dataset includes expected source IDs and ranked retrieved chunks, which provides the retrieval ground truth required by that evaluator. For the support agent, the expected source appears too low in the ranking after unrelated chunks. For the policy agent, the required exception-table source is missing entirely.
Groundedness would evaluate whether the final response is supported by the context it actually received; it could therefore pass even when the retrieval stage failed to fetch a required source. Microsoft Foundry ' s Document Retrieval evaluator compares retrieved documents against labeled ground truth and reports ranking
/search metrics such as NDCG and Fidelity. The corrected answer is Document Retrieval for both agents. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry - RAG evaluators
NEW QUESTION # 56
......
The Microsoft AI-500 practice tests have customizable time and AI-500 exam questions feature so that the students can set the time and AI-500 exam questions according to their needs. The Microsoft AI-500 practice test questions are getting updated on the daily basis and there are also up to 1 year of free updates. Earning the Microsoft AI-500 Certification Exam is the way to grow in the modern era with high-paying jobs. The 24/7 support system is available for the customers so that they can get the solution to every problem they face and pass Designing and Implementing Multi-Agent AI Solutions (AI-500) exam. You can also evaluate the AI-500 prep material with a free demo.
Frenquent AI-500 Update: https://www.free4torrent.com/AI-500-braindumps-torrent.html