Kostenlos MLA-C01 Dumps Torrent & MLA-C01 exams4sure pdf & Amazon MLA-C01 pdf vce

P.S. Kostenlose 2026 Amazon MLA-C01 Prüfungsfragen sind auf Google Drive freigegeben von EchteFrage verfügbar: https://drive.google.com/open?id=1s_5Wnh-p-7NXRVDtckXIFAU4vvyDnbHC
Wenn Sie Online-Service für die Lerntipps zur Amazon MLA-C01 Zertifizierungsprüfung kaufen wollen, ist unser EchteFrage einer der anführenden Websites. Wir bieten die neuesten Schulungsunterlagen von bester Qualität. Alle Lernmaterialien und Schulungsunterlagen zur Amazon MLA-C01 Zertifizierungsprüfung auf unserer Website entsprechen ihren Kosten. Sie genießen einen einjährigen kostenlosen Update-Service. Wenn alle unseren Produkte Ihnen nicht zum Bestehen der Amazon MLA-C01 Zertifizierungsprüfung Prüfung verhilft, erstatten wir Ihnen die gesammte Summe zurück.
Amazon MLA-C01 Prüfungsplan:
| Thema | Einzelheiten |
|---|
| Thema 1 | - Data Preparation for Machine Learning (ML): This section of the exam measures skills of Forensic Data Analysts and covers collecting, storing, and preparing data for machine learning. It focuses on understanding different data formats, ingestion methods, and AWS tools used to process and transform data. Candidates are expected to clean and engineer features, ensure data integrity, and address biases or compliance issues, which are crucial for preparing high-quality datasets in fraud analysis contexts.
|
| Thema 2 | - Deployment and Orchestration of ML Workflows: This section of the exam measures skills of Forensic Data Analysts and focuses on deploying machine learning models into production environments. It covers choosing the right infrastructure, managing containers, automating scaling, and orchestrating workflows through CI
- CD pipelines. Candidates must be able to build and script environments that support consistent deployment and efficient retraining cycles in real-world fraud detection systems.
|
| Thema 3 | - ML Solution Monitoring, Maintenance, and Security: This section of the exam measures skills of Fraud Examiners and assesses the ability to monitor machine learning models, manage infrastructure costs, and apply security best practices. It includes setting up model performance tracking, detecting drift, and using AWS tools for logging and alerts. Candidates are also tested on configuring access controls, auditing environments, and maintaining compliance in sensitive data environments like financial fraud detection.
|
| Thema 4 | - ML Model Development: This section of the exam measures skills of Fraud Examiners and covers choosing and training machine learning models to solve business problems such as fraud detection. It includes selecting algorithms, using built-in or custom models, tuning parameters, and evaluating performance with standard metrics. The domain emphasizes refining models to avoid overfitting and maintaining version control to support ongoing investigations and audit trails.
|
>> MLA-C01 Prüfungsvorbereitung <<
Die seit kurzem aktuellsten Amazon MLA-C01 Prüfungsinformationen, 100% Garantie für Ihen Erfolg in der Prüfungen!
Seit Jahren gilt EchteFrage als der beste Partner für die IT-Prüfungsteilnehmer. Sie bietet reichliche Ressourcen der Prüfungsunterlagen. Die Bestehensquote der Kunden, die Amazon MLA-C01 Prüfungssoftware benutzt haben, erreicht eine Höhe von fast 100%. Diese befriedigte Feedbacks geben wir mehr Motivation, die zuverlässige Qualität von Amazon MLA-C01 weiter zu versichern. Wir wünschen Ihnen, durch das Bestehen der Amazon MLA-C01 das Gefühl des Erfolgs empfinden, weil es uns auch das Gefühl des Erfolges mitbringt.
Amazon AWS Certified Machine Learning Engineer - Associate MLA-C01 Prüfungsfragen mit Lösungen (Q172-Q177):
172. Frage
An ML engineer trained an ML model on Amazon SageMaker to detect automobile accidents from dosed- circuit TV footage. The ML engineer used SageMaker Data Wrangler to create a training dataset of images of accidents and non-accidents.
The model performed well during training and validation. However, the model is underperforming in production because of variations in the quality of the images from various cameras.
Which solution will improve the model's accuracy in the LEAST amount of time?
- A. Recreate the training dataset by using the Data Wrangler corrupt image transform. Specify the impulse noise option.
- B. Recreate the training dataset by using the Data Wrangler resize image transform. Crop all images to the same size.
- C. Collect more images from all the cameras. Use Data Wrangler to prepare a new training dataset.
- D. Recreate the training dataset by using the Data Wrangler enhance image contrast transform. Specify the Gamma contrast option.
Antwort: A
Begründung:
The model is underperforming in production due to variations in image quality from different cameras. Using the corrupt image transform with the impulse noise option in SageMaker Data Wrangler simulates real-world noise and variations in the training dataset. This approach helps the model become more robust to inconsistencies in image quality, improving its accuracy in production without the need to collect and process new data, thereby saving time.
173. Frage
A company wants to use Amazon SageMaker AI to host an ML model that runs on CPU for real-time predictions. The model has intermittent traffic during business hours and periods of no traffic after business hours.
Which hosting option will serve inference requests in the MOST cost-effective manner?
- A. Deploy the model to a real-time endpoint with scheduled auto scaling.
- B. Deploy the model to an asynchronous inference endpoint with auto scaling to zero.
- C. Deploy the model to a real-time endpoint and activate it only during business hours using AWS Lambda.
- D. Deploy the model to a SageMaker AI Serverless Inference endpoint with provisioned concurrency during business hours.
Antwort: D
Begründung:
AWS recommends SageMaker Serverless Inference for workloads with intermittent or unpredictable traffic.
Serverless inference automatically scales compute resources to zero when idle, eliminating costs during periods with no traffic.
For business-hour traffic spikes, provisioned concurrency ensures low-latency responses while still avoiding the cost of continuously running instances. This model is especially cost-effective for CPU-based inference workloads.
Real-time endpoints incur costs even when idle, and asynchronous inference is designed for long-running jobs rather than low-latency predictions.
AWS documentation explicitly states that Serverless Inference is the most cost-effective option for intermittent real-time workloads.
Therefore, Option B is the correct choice.
174. Frage
A company uses Amazon Athena to query a dataset in Amazon S3. The dataset has a target variable that the company wants to predict.
The company needs to use the dataset in a solution to determine if a model can predict the target variable.
Which solution will provide this information with the LEAST development effort?
- A. Configure Amazon Macie to analyze the dataset and to create a model. Report the model's achieved performance.
- B. Select a model from Amazon Bedrock. Tune the model with the data. Report the model's achieved performance.
- C. Implement custom scripts to perform data pre-processing, multiple linear regression, and performance evaluation. Run the scripts on Amazon EC2 instances.
- D. Create a new model by using Amazon SageMaker Autopilot. Report the model's achieved performance.
Antwort: D
175. Frage
An ML engineer has deployed an Amazon SageMaker model to a serverless endpoint in production. The model is invoked by the InvokeEndpoint API operation.
The model's latency in production is higher than the baseline latency in the test environment. The ML engineer thinks that the increase in latency is because of model startup time.
What should the ML engineer do to confirm or deny this hypothesis?
- A. Schedule a SageMaker Model Monitor job with Amazon CloudWatch metrics enabled.
- B. Enable Amazon CloudWatch metrics. Observe the ModelLoadingWaitTime metric in the SageMaker namespace.
- C. Schedule a SageMaker Model Monitor job. Observe metrics about model quality.
- D. Enable Amazon CloudWatch metrics. Observe the ModelSetupTime metric in the SageMaker namespace.
Antwort: B
176. Frage
A company stores historical data in .csv files in Amazon S3. Only some of the rows and columns in the .csv files are populated. The columns are not labeled. An ML engineer needs to prepare and store the data so that the company can use the data to train ML models.
Select and order the correct steps from the following list to perform this task. Each step should be selected one time or not at all. (Select and order three.)
* Create an Amazon SageMaker batch transform job for data cleaning and feature engineering.
* Store the resulting data back in Amazon S3.
* Use Amazon Athena to infer the schemas and available columns.
* Use AWS Glue crawlers to infer the schemas and available columns.
* Use AWS Glue DataBrew for data cleaning and feature engineering.
Antwort:
Begründung:
Explanation:
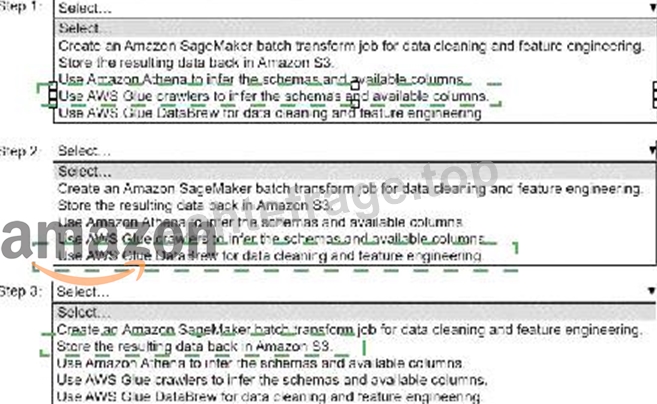
Step 1: Use AWS Glue crawlers to infer the schemas and available columns.
Step 2: Use AWS Glue DataBrew for data cleaning and feature engineering.
Step 3: Store the resulting data back in Amazon S3.
Step 1: Use AWS Glue Crawlers to Infer Schemas and Available Columns
Why? The data is stored in .csv files with unlabeled columns, and Glue Crawlers can scan the raw data in Amazon S3 to automatically infer the schema, including available columns, data types, and any missing or incomplete entries.
How? Configure AWS Glue Crawlers to point to the S3 bucket containing the .csv files, and run the crawler to extract metadata. The crawler creates a schema in the AWS Glue Data Catalog, which can then be used for subsequent transformations.
Step 2: Use AWS Glue DataBrew for Data Cleaning and Feature Engineering Why? Glue DataBrew is a visual data preparation tool that allows for comprehensive cleaning and transformation of data. It supports imputation of missing values, renaming columns, feature engineering, and more without requiring extensive coding.
How? Use Glue DataBrew to connect to the inferred schema from Step 1 and perform data cleaning and feature engineering tasks like filling in missing rows/columns, renaming unlabeled columns, and creating derived features.
Step 3: Store the Resulting Data Back in Amazon S3
Why? After cleaning and preparing the data, it needs to be saved back to Amazon S3 so that it can be used for training machine learning models.
How? Configure Glue DataBrew to export the cleaned data to a specific S3 bucket location. This ensures the processed data is readily accessible for ML workflows.
Order Summary:
Use AWS Glue crawlers to infer schemas and available columns.
Use AWS Glue DataBrew for data cleaning and feature engineering.
Store the resulting data back in Amazon S3.
This workflow ensures that the data is prepared efficiently for ML model training while leveraging AWS services for automation and scalability.
177. Frage
......
Nun bieten viele Ausbildungsinstitute Ihnen die Schulungsunterlagen zur Amazon MLA-C01 Zertifizierungsprüfung. Meistens bekommen die Kandidaten per diese Websites keine ausführlichen Materialien. Denn ihre Materialien zur Amazon MLA-C01 Zertifizierungsprüfung sind breit gefächert und nicht zielgerichtet. So können sie keine Aufmerksamkeit der Kandidaten gewinnen.
MLA-C01 Zertifizierungsfragen: https://www.echtefrage.top/MLA-C01-deutsch-pruefungen.html
- MLA-C01 Prüfungsfragen 🥿 MLA-C01 Zertifikatsfragen 📠 MLA-C01 Testantworten 🍲 Suchen Sie auf ☀ www.itzert.com ️☀️ nach ✔ MLA-C01 ️✔️ und erhalten Sie den kostenlosen Download mühelos 🐨MLA-C01 Zertifizierungsprüfung
- MLA-C01 Dumps Deutsch 🌌 MLA-C01 Prüfungsinformationen 🦘 MLA-C01 Exam Fragen 🟨 ➡ www.itzert.com ️⬅️ ist die beste Webseite um den kostenlosen Download von ☀ MLA-C01 ️☀️ zu erhalten 💈MLA-C01 Zertifikatsfragen
- MLA-C01 Buch 🛰 MLA-C01 Buch 🌸 MLA-C01 Prüfungsfragen 🔣 Suchen Sie auf ⇛ www.examfragen.de ⇚ nach kostenlosem Download von ⮆ MLA-C01 ⮄ 🌑MLA-C01 Prüfungsinformationen
- Valid MLA-C01 exam materials offer you accurate preparation dumps 🕵 Geben Sie ⏩ www.itzert.com ⏪ ein und suchen Sie nach kostenloser Download von [ MLA-C01 ] ⚫MLA-C01 Testengine
- MLA-C01 Dumps Deutsch ⛽ MLA-C01 Testengine 🍰 MLA-C01 Dumps Deutsch 🧾 Suchen Sie auf der Webseite ➥ www.zertpruefung.ch 🡄 nach ( MLA-C01 ) und laden Sie es kostenlos herunter 🦳MLA-C01 Simulationsfragen
- MLA-C01 Zertifizierungsprüfung 🎻 MLA-C01 Deutsch Prüfung 🧯 MLA-C01 Prüfungsinformationen 🤫 URL kopieren ✔ www.itzert.com ️✔️ Öffnen und suchen Sie { MLA-C01 } Kostenloser Download 👫MLA-C01 Deutsche Prüfungsfragen
- MLA-C01 Pass Dumps - PassGuide MLA-C01 Prüfung - MLA-C01 Guide 👔 Suchen Sie jetzt auf ⮆ www.deutschpruefung.com ⮄ nach ⇛ MLA-C01 ⇚ und laden Sie es kostenlos herunter 🔷MLA-C01 Fragenpool
- Echte und neueste MLA-C01 Fragen und Antworten der Amazon MLA-C01 Zertifizierungsprüfung 💎 Suchen Sie jetzt auf 【 www.itzert.com 】 nach ✔ MLA-C01 ️✔️ um den kostenlosen Download zu erhalten 👏MLA-C01 Testantworten
- Die anspruchsvolle MLA-C01 echte Prüfungsfragen von uns garantiert Ihre bessere Berufsaussichten! 😠 Öffnen Sie die Webseite ➽ www.zertsoft.com 🢪 und suchen Sie nach kostenloser Download von ( MLA-C01 ) 🐤MLA-C01 Deutsche Prüfungsfragen
- MLA-C01 Dumps Deutsch 😽 MLA-C01 Prüfungsinformationen 🍋 MLA-C01 Zertifikatsfragen 📅 Öffnen Sie die Website ➽ www.itzert.com 🢪 Suchen Sie ➠ MLA-C01 🠰 Kostenloser Download 🛃MLA-C01 Testengine
- MLA-C01 Deutsche Prüfungsfragen 🚰 MLA-C01 Fragenpool 🪂 MLA-C01 Exam Fragen 📭 Suchen Sie auf { www.zertpruefung.ch } nach ➥ MLA-C01 🡄 und erhalten Sie den kostenlosen Download mühelos 🌍MLA-C01 Prüfungsfragen
- www.ted.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, blogfreely.net, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, justpaste.me, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, network.crcna.org, Disposable vapes
Laden Sie die neuesten EchteFrage MLA-C01 PDF-Versionen von Prüfungsfragen kostenlos von Google Drive herunter: https://drive.google.com/open?id=1s_5Wnh-p-7NXRVDtckXIFAU4vvyDnbHC