P.S. Free 2026 Databricks Databricks-Generative-AI-Engineer-Associate dumps are available on Google Drive shared by ExamDumpsVCE: https://drive.google.com/open?id=1z7-DhVOmGZVsIJAGvSknLyZTm3iK7ilG
As a worldwide leader in offering the best Databricks-Generative-AI-Engineer-Associate test torrent, we are committed to providing comprehensive service to the majority of consumers and strive for constructing an integrated service. What's more, we have achieved breakthroughs in Databricks-Generative-AI-Engineer-Associate certification training application as well as interactive sharing and after-sales service. As a matter of fact, our company takes account of every client's difficulties with fitting solutions. As long as you need help, we will offer instant support to deal with any of your problems about our Databricks-Generative-AI-Engineer-Associate Guide Torrent to help you pass the Databricks-Generative-AI-Engineer-Associate exam.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Generative AI Engineer Associate |
| Exam Number: | Databricks-Generative-AI-Engineer-Associate |
| Certificate Validity Period: | 2 years |
| Available Languages: | English |
| Related Certifications: | Databricks Certified Machine Learning Associate Databricks Certified Data Engineer Associate |
| Exam Price: | USD 200 |
| Real Exam Qty: | 45-60 |
| Exam Format: | Multiple select, Multiple choice |
| Exam Duration: | 90 minutes |
| Recommended Training: | Mosaic AI Documentation Databricks Academy - Generative AI Courses |
| Exam Registration: | Databricks Certification Portal |
| Sample Questions: | Databricks Databricks-Generative-AI-Engineer-Associate Sample Questions |
| Exam Way: | Online proctored exam |
| Pre Condition: | No strict prerequisites, but experience with Python, machine learning fundamentals, and Databricks platform is recommended. |
| Official Syllabus URL: | https://www.databricks.com/learn/certification |
>> Databricks-Generative-AI-Engineer-Associate Latest Test Discount <<
How can you pass your exam and get your certificate in a short time? Our Databricks-Generative-AI-Engineer-Associate exam torrent will be your best choice to help you achieve your aim. According to customers' needs, our product was revised by a lot of experts; the most functions of our Databricks-Generative-AI-Engineer-Associate exam dumps are to help customers save more time, and make customers relaxed. If you choose to use our Databricks-Generative-AI-Engineer-Associate Test Quiz, you will find it is very easy for you to pass your Databricks-Generative-AI-Engineer-Associate exam in a short time. You just need to spend 20-30 hours on studying with our Databricks-Generative-AI-Engineer-Associate exam questions; you will have more free time to do other things.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
NEW QUESTION # 54
A Generative AI Engineer is evaluating a customer-support agent in Databricks. The team needs to score each response on a domain-specific policy: the answer must cite an approved refund rule and must not mention unsupported escalation paths. Built-in evaluation metrics do not capture this logic. The team wants the metric to run during agent evaluation in Databricks and return a repeatable, structured score for each trace.
Which approach should the engineer use?
Answer: D
Explanation:
MLflow supports custom scorers for application-specific evaluation requirements that built-in metrics do not address. The engineer can define a scorer that examines the generated answer and, when necessary, the complete execution trace. It can verify references against an approved refund-rule list and check whether escalation statements violate the policy. The scorer returns structured feedback, such as a Boolean result, numerical score, or Feedback object, and is supplied to mlflow.genai.evaluate(). Deterministic checks are appropriate when repeatability is essential; semantic checks may require a carefully specified judge. Latency and token counts measure operational behavior rather than policy compliance. Reviewing traces manually does not create an automated metric, and the generating model's self-assessment is not an independent compliance evaluation. Databricks documentation
NEW QUESTION # 55
A Generative AI Engineer is designing a RAG application for answering user questions on technical regulations as they learn a new sport.
What are the steps needed to build this RAG application and deploy it?
Answer: D
Explanation:
The Generative AI Engineer needs to follow a methodical pipeline to build and deploy a Retrieval- Augmented Generation (RAG) application. The steps outlined in option B accurately reflect this process:
* Ingest documents from a source : This is the first step, where the engineer collects documents (e.g., technical regulations) that will be used for retrieval when the application answers user questions.
* Index the documents and save to Vector Search : Once the documents are ingested, they need to be embedded using a technique like embeddings (e.g., with a pre-trained model like BERT) and stored in a vector database (such as Pinecone or FAISS). This enables fast retrieval based on user queries.
* User submits queries against an LLM : Users interact with the application by submitting their queries. These queries will be passed to the LLM.
* LLM retrieves relevant documents : The LLM works with the vector store to retrieve the most relevant documents based on their vector representations.
* LLM generates a response : Using the retrieved documents, the LLM generates a response that is tailored to the user ' s question.
* Evaluate model : After generating responses, the system must be evaluated to ensure the retrieved documents are relevant and the generated response is accurate. Metrics such as accuracy, relevance, and user satisfaction can be used for evaluation.
* Deploy it using Model Serving : Once the RAG pipeline is ready and evaluated, it is deployed using a model-serving platform such as Databricks Model Serving. This enables real-time inference and response generation for users.
By following these steps, the Generative AI Engineer ensures that the RAG application is both efficient and effective for the task of answering technical regulation questions.
NEW QUESTION # 56
A Generative AI Engineer I using the code below to test setting up a vector store: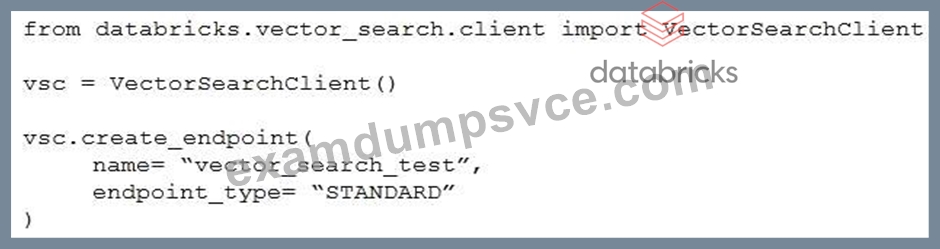
Assuming they intend to use Databricks managed embeddings with the default embedding model, what should be the next logical function call?
Answer: C
Explanation:
Context: The Generative AI Engineer is setting up a vector store using Databricks' VectorSearchClient. This is typically done to enable fast and efficient retrieval of vectorized data for tasks like similarity searches.
Explanation of Options:
* Option A: vsc.get_index(): This function would be used to retrieve an existing index, not create one, so it would not be the logical next step immediately after creating an endpoint.
* Option B: vsc.create_delta_sync_index(): After setting up a vector store endpoint, creating an index is necessary to start populating and organizing the data. The create_delta_sync_index() function specifically creates an index that synchronizes with a Delta table, allowing automatic updates as the data changes. This is likely the most appropriate choice if the engineer plans to use dynamic data that is updated over time.
* Option C: vsc.create_direct_access_index(): This function would create an index that directly accesses the data without synchronization. While also a valid approach, it's less likely to be the next logical step if the default setup (typically accommodating changes) is intended.
* Option D: vsc.similarity_search(): This function would be used to perform searches on an existing index; however, an index needs to be created and populated with data before any search can be conducted.
Given the typical workflow in setting up a vector store, the next step after creating an endpoint is to establish an index, particularly one that synchronizes with ongoing data updates, henceOption B.
NEW QUESTION # 57
A Generative AI Engineer is managing prompt templates using MLflow v3.x for a document summarization pipeline. A regulatory audit requires the team to demonstrate exactly which prompt version was used to generate outputs on a specific date three months ago, including the exact prompt text and any variables used at that time.
Which combination of MLflow v3.x capabilities allows the engineer to satisfy this audit requirement?
Answer: C
Explanation:
The Prompt Registry preserves identifiable prompt versions, allowing the team to recover the exact template associated with a historical execution. Linking inference activity to the prompt's name and version establishes which registered template the application actually used. MLflow also supports lineage between prompt versions, application versions, and execution traces. However, satisfying the entire audit requires retaining the actual runtime variable values or the fully rendered prompt in the relevant execution records. Registry history alone preserves the template, not every value substituted into it. Therefore, D is the best option, provided the logging captures those inputs. Model webhooks, experiment tags, or table history alone do not provide the same explicit prompt-version lineage and complete historical reconstruction. Databricks documentation
NEW QUESTION # 58
A Generative Al Engineer has already trained an LLM on Databricks and it is now ready to be deployed.
Which of the following steps correctly outlines the easiest process for deploying a model on Databricks?
Answer: A
NEW QUESTION # 59
......
Exam Databricks-Generative-AI-Engineer-Associate Tutorial: https://www.examdumpsvce.com/Databricks-Generative-AI-Engineer-Associate-valid-exam-dumps.html
BTW, DOWNLOAD part of ExamDumpsVCE Databricks-Generative-AI-Engineer-Associate dumps from Cloud Storage: https://drive.google.com/open?id=1z7-DhVOmGZVsIJAGvSknLyZTm3iK7ilG