SPS-C01 Valid Test Topics | New SPS-C01 Test Vce Free
What's more, part of that DumpsTests SPS-C01 dumps now are free: https://drive.google.com/open?id=1SKQb8cmZriN2sz5gRLxxZmREbj07f_4d
You can enjoy 365 days free update after purchase of our SPS-C01 exam torrent. About the updated Snowflake study material, our system will send the latest one to your payment email automatically as soon as the SPS-C01 updated. So you can study with the latest SPS-C01 Study Material. In addition, DumpsTests offer you the best valid SPS-C01 training pdf, which can ensure you 100% pass. Try our SPS-C01 free demo before you buy, you will be surprised by our high quality SPS-C01 pdf vce.
| Section | Objectives |
|---|
| Topic 1: Snowpark Fundamentals | - Snowpark architecture and concepts
- 1. Snowflake execution model overview
- 2. Snowpark APIs and supported languages
|
| Topic 2: Testing, Debugging, and Deployment | - Production readiness
- 1. Debugging Snowpark applications
- 2. Deployment strategies
|
| Topic 3: User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
- 1. Stored procedures in Snowpark
- 2. Python UDFs
|
| Topic 4: Data Engineering with Snowpark | - Pipeline development
- 1. Integration with Snowflake data pipelines
- 2. Batch processing workflows
|
| Topic 5: DataFrame Operations and Data Processing | - Data transformation workflows
- 1. Filtering, selecting, and aggregations
- 2. Joins and window functions
|
| Topic 6: Performance Optimization and Best Practices | - Efficient Snowpark execution
- 1. Pushdown optimization concepts
- 2. Resource utilization tuning
|
>> SPS-C01 Valid Test Topics <<
New SPS-C01 Test Vce Free, Dumps SPS-C01 Questions
Different with other similar education platforms on the internet, the Snowflake Certified SnowPro Specialty - Snowpark guide torrent has a high hit rate, in the past, according to data from the students' learning to use the SPS-C01 test torrent, 99% of these students can pass the qualification test and acquire the qualification of their yearning, this powerfully shows that the information provided by the SPS-C01 Study Tool suit every key points perfectly, targeted training students a series of patterns and problem solving related routines, and let students answer up to similar topic.
Snowflake Certified SnowPro Specialty - Snowpark Sample Questions (Q348-Q353):
NEW QUESTION # 348
You are developing a Snowpark Python application that connects to Snowflake using key pair authentication. You have the private key stored securely in an environment variable named 'SNOWFLAKE PRIVATE KEY. Which of the following code snippets correctly establishes a Snowpark session using this method, assuming all other necessary connection parameters (account, user, database, schema, warehouse) are also set as environment variables?
Answer: B
Explanation:
Option D is correct because it properly retrieves the private key from the environment variable, decodes the PEM format, and passes it to the connection parameters after converting the key object to a string. It uses the cryptography library to handle the private key securely, which is required for key pair authentication. The code snippet decodes the private key using cryptography library and creates a string, which then is passed to the connection parameters to create a session. Option A fails to use the cryptography library and just passes the private key directly. Option B is incorrect because it doesn't use the 'configs' method, which is the correct way to pass all connection parameters at once. Option C doesn't encode the private key properly, and does not convert to string after decoding using cryptography. Option E does convert to string, but is not secure as the private key is directly passed without decoding it using the cryptography library.
NEW QUESTION # 349
You have written a Snowpark Python function that performs a complex calculation involving user-defined functions (UDFs). When running this function on a large dataset, you encounter a 'PicklingError: Can't pickle ': it's not the same object as main.my function'. What is the MOST likely cause of this error, and how can you resolve it?
- A. The UDF is defined within a local scope or closure, and Snowpark cannot serialize it. Move the UDF definition to the global scope or use 'cloudpickle' explicitly.
- B. The UDF's return type is not correctly specified. Use 'udf(func, to explicitly define the return type.
- C. The Snowpark session is not properly initialized. Ensure that the connection parameters are correct.
- D. The UDF contains unsupported Python libraries. Ensure that all dependencies are available on the Snowflake worker nodes.
- E. The dataset is too large to be processed in memory. Use 'df.cache()' to persist the intermediate results to disk.
Answer: A
Explanation:
Pickling errors in Snowpark often arise when UDFs are defined within local scopes because the serialization process needs to transmit the function to the Snowflake worker nodes. Moving the UDF to the global scope or using 'cloudpickle' allows the function to be correctly serialized. Option B addresses memory issues, C handles dependency problems, D addresses connection issues, and E addresses return type issues, but these are not the MOST likely cause of a PicklingError related to function scope.
NEW QUESTION # 350
Consider the following Snowpark Python code snippet designed to perform a join operation between two large tables: 'transactions' and 'customers'. The 'transactions' table contains billions of rows and the 'customers' table contains millions of rows. You are experiencing performance bottlenecks during the join operation. The 'transactions' table has a 'customer id' column that references the 'customers' table's primary key 'id'. Which optimization techniques would be MOST effective in improving the join performance within a Snowpark- optimized warehouse?
- A. Ensure that the 'customer_id' column in the 'transactions' table and the 'id' column in the 'customers' table have appropriate indexes defined in Snowflake before performing the join.
- B. Explicitly specify the join type as a broadcast join using a hint: 'df_transactions.join(df_customers, df_transactions['customer_id'] == df_customers['id'],
- C. Broadcast the smaller DataFrame (customers') to all nodes in the warehouse before performing the join. Use: 'from snowflake.snowpark.functions import broadcast; df_transactions.join(broadcast(df_customers), df_transactions['customer_id']
- D. Repartition the 'transactions DataFrame by the 'customer_id' column and the 'customers' DataFrame by the 'id' column before performing the join using 'df_transactions.repartition('customer_id').join(df_customers.repartition('id'), df_transactions['customer_id'] == df_customers['id'])'.
- E. Increase the size of the Snowpark-optimized warehouse to provide more memory and CPU resources for the join operation.
Answer: C
Explanation:
Broadcasting the smaller table (customers) to all nodes allows for a more efficient join by avoiding the need to shuffle large amounts of data. Snowflake automatically handles index management and optimization; explicitly defining indexes is not necessary. While repartitioning can sometimes improve join performance, in this scenario broadcasting the smaller table is generally more effective. Increasing the warehouse size might help, but it's less targeted than broadcasting. 'how='broadcastr is not a valid parameter in Snowpark's 'join()' function.
NEW QUESTION # 351
Consider the following Snowpark Python code snippet that defines and applies a UDF:
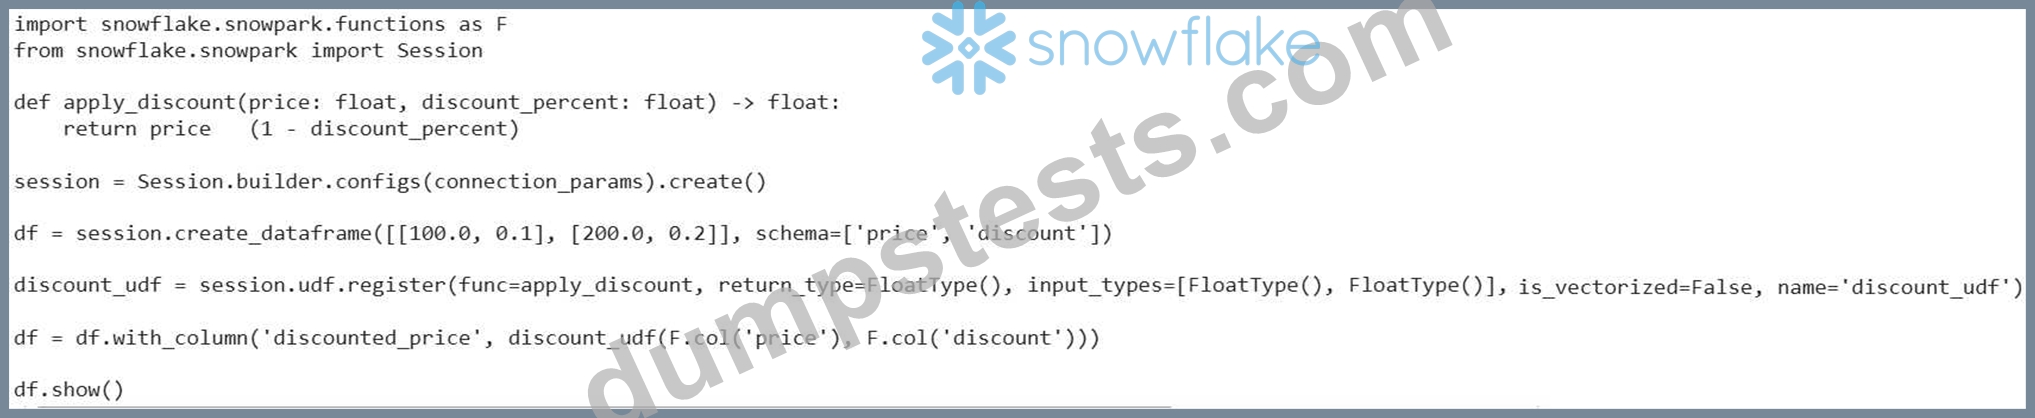
Which of the following modifications would MOST likely improve the performance of this code, assuming the DataFrame 'df contains a large number of rows?
- A. Remove the 'input_types' argument from 'session.udf.register' . Snowflake can automatically infer the input types.
- B. Change to in the "session.udf.register' call, ensuring the function is updated to handle batches of data.
- C. Specify a different warehouse size when creating the Snowpark session using 'session = Session.builder.config('warehouse', 'XLARGE').configs(connection_params).create()'.
- D. Use and F.lit(0.2Y instead of 0.1 and 0.2 while creating the dataframe.
- E. Rewrite the 'apply_discount' function to use NumPy arrays internally for vectorized calculations, ensuring compatibility with vectorized UDF execution. The function signature will also need to accept arrays.
Answer: B,E
Explanation:
Setting tells Snowpark to treat the UDF as a vectorized UDE However, simply setting the flag is not sufficient. E is also required because Vectorized UDF requires functions that accept and process arrays as inputs, not single scalar values. The function needs to be modified to handle arrays using NumPy or similar libraries. The code also need to be rewritten to work with arrays. B has nothing to do with performance. Increasing Warehouse size might help but not on the scale of vectorization.
NEW QUESTION # 352
You have a Snowpark DataFrame representing customer transactions. This DataFrame is used in multiple downstream operations within your Snowpark application. Which of the following strategies would be MOST effective for optimizing the performance of these downstream operations by materializing the results of the 'df DataFrame, and what considerations should be made regarding resource usage?
- A. Using a local variable to store the DataFrame. This method is most suitable for materializing the results of the DataFrame.
- B. Write the DataFrame to a persistent Snowflake table using and then read it back into a new DataFrame. This ensures data persistence but may introduce overhead due to data serialization and deserialization. Only use this method if persistence is required beyond the session.
- C. Use to materialize the DataFrame in memory. This is the most efficient approach as it minimizes disk I/O. Consider the size of the DataFrame relative to available memory to avoid memory pressure.
- D. Create a temporary table using 'df.write.save_as_table('temp_transactions', temporary-True)'. This persists the DataFrame to Snowflake storage, reducing the need for repeated computations. Monitor the size of the temporary table and its impact on storage costs.
- E. Use 'df.checkpoint()' to truncate the DataFrame lineage. This will prevent re-computation in any downstream operations. Monitor the impact on storage costs.
Answer: C,D
Explanation:
Using materializes the DataFrame in memory, which is faster for repeated access but requires sufficient memory. Creating a temporary table using temporary=TrueV persists the DataFrame to Snowflake storage, reducing recomputation at the cost of storage 1/0. Choosing between these options depends on the DataFrame's size, available memory, and the frequency of access. Writing to a persistent table adds unnecessary overhead unless persistence is required. Using a local variable will only persist the result within the scope of that variable, not across multiple Snowpark operations. Checkpointing is used for lineage truncation not caching.
NEW QUESTION # 353
......
Snowflake SPS-C01 exam is an popular examination of the IT industry, and it is also very important. We prepare the best study guide and the best online service specifically for IT professionals to provide a shortcut. DumpsTests Snowflake SPS-C01 Exam covers all the content of the examination and answers you need to know. Tried Exams ot DumpsTests, you know this is something you do everything possible to want, and it is really perfect for the exam preparation.
New SPS-C01 Test Vce Free: https://www.dumpstests.com/SPS-C01-latest-test-dumps.html
- Valid SPS-C01 Exam Discount 👩 Valid SPS-C01 Exam Discount ☎ SPS-C01 Exam Brain Dumps 🎒 Go to website ➡ www.vce4dumps.com ️⬅️ open and search for ( SPS-C01 ) to download for free 🍎SPS-C01 Latest Test Discount
- SPS-C01 actual test - SPS-C01 pass for sure - SPS-C01 test guide 📄 Search for ▷ SPS-C01 ◁ and download exam materials for free through ➡ www.pdfvce.com ️⬅️ 🥄SPS-C01 Test Guide Online
- Efficient SPS-C01 Valid Test Topics - Trusted - Pass-Sure SPS-C01 Materials Free Download for Snowflake SPS-C01 Exam 😠 Search for ➡ SPS-C01 ️⬅️ and download it for free immediately on ➡ www.practicevce.com ️⬅️ 🗳Valid Dumps SPS-C01 Pdf
- SPS-C01 Minimum Pass Score 😏 SPS-C01 Latest Test Discount 🆗 SPS-C01 Exam Flashcards 🚉 Download ➥ SPS-C01 🡄 for free by simply entering ➥ www.pdfvce.com 🡄 website 🗼SPS-C01 Pdf Format
- SPS-C01 Latest Dumps Ebook 📠 Unlimited SPS-C01 Exam Practice 🔚 SPS-C01 Exam Brain Dumps 🌍 Search for [ SPS-C01 ] on ⇛ www.troytecdumps.com ⇚ immediately to obtain a free download 💄SPS-C01 Exam Brain Dumps
- Pass Guaranteed Marvelous Snowflake SPS-C01 Valid Test Topics 🧦 Enter ⮆ www.pdfvce.com ⮄ and search for “ SPS-C01 ” to download for free 🔱SPS-C01 Exam Assessment
- 100% Pass Quiz 2026 Snowflake SPS-C01 Authoritative Valid Test Topics 🚒 Open website [ www.testkingpass.com ] and search for ⮆ SPS-C01 ⮄ for free download 👲SPS-C01 Exam Assessment
- Complete SPS-C01 Exam Dumps 🍻 Downloadable SPS-C01 PDF 🚎 Complete SPS-C01 Exam Dumps 🚞 Open website { www.pdfvce.com } and search for { SPS-C01 } for free download 😇New SPS-C01 Exam Online
- Downloadable SPS-C01 PDF ⛹ SPS-C01 Demo Test 🔳 Book SPS-C01 Free 😧 Search for ( SPS-C01 ) and obtain a free download on ⇛ www.examdiscuss.com ⇚ 🌍New SPS-C01 Exam Book
- 100% Pass Quiz 2026 Snowflake SPS-C01 Authoritative Valid Test Topics 🤼 Easily obtain ▶ SPS-C01 ◀ for free download through { www.pdfvce.com } ⚖Book SPS-C01 Free
- New SPS-C01 Exam Online 🦁 SPS-C01 Test Guide Online 🌇 Valid SPS-C01 Test Online 🟥 Open 「 www.troytecdumps.com 」 and search for ➽ SPS-C01 🢪 to download exam materials for free 🔸New SPS-C01 Exam Book
- www.blackhatprotools.info, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, epeumhf.mataroa.blog, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, justpaste.me, Disposable vapes
BTW, DOWNLOAD part of DumpsTests SPS-C01 dumps from Cloud Storage: https://drive.google.com/open?id=1SKQb8cmZriN2sz5gRLxxZmREbj07f_4d


