MLA-C01 Real Sheets | Knowledge MLA-C01 Points

2026 Latest Prep4cram MLA-C01 PDF Dumps and MLA-C01 Exam Engine Free Share: https://drive.google.com/open?id=1sbg1moPUtCmvT5QFvR5XMHYWMqs5bXmk
To be the best global supplier of electronic MLA-C01 study materials for our customers through innovation and enhancement of our customers' satisfaction has always been our common pursuit. The advantages of our MLA-C01 study guide are more than you can count. As the most important factor that our worthy customers will consider-the pass rate, we are proud to tell you that we have a pass rate high as 98% to 100% on our MLA-C01 training engine, which is also unique in the market. And our price of the MLA-C01 practice guide is also reasonable.
| Topic | Details |
|---|
| Topic 1 | - Data Preparation for Machine Learning (ML): This section of the exam measures skills of Forensic Data Analysts and covers collecting, storing, and preparing data for machine learning. It focuses on understanding different data formats, ingestion methods, and AWS tools used to process and transform data. Candidates are expected to clean and engineer features, ensure data integrity, and address biases or compliance issues, which are crucial for preparing high-quality datasets in fraud analysis contexts.
|
| Topic 2 | - ML Solution Monitoring, Maintenance, and Security: This section of the exam measures skills of Fraud Examiners and assesses the ability to monitor machine learning models, manage infrastructure costs, and apply security best practices. It includes setting up model performance tracking, detecting drift, and using AWS tools for logging and alerts. Candidates are also tested on configuring access controls, auditing environments, and maintaining compliance in sensitive data environments like financial fraud detection.
|
| Topic 3 | - Deployment and Orchestration of ML Workflows: This section of the exam measures skills of Forensic Data Analysts and focuses on deploying machine learning models into production environments. It covers choosing the right infrastructure, managing containers, automating scaling, and orchestrating workflows through CI
- CD pipelines. Candidates must be able to build and script environments that support consistent deployment and efficient retraining cycles in real-world fraud detection systems.
|
| Topic 4 | - ML Model Development: This section of the exam measures skills of Fraud Examiners and covers choosing and training machine learning models to solve business problems such as fraud detection. It includes selecting algorithms, using built-in or custom models, tuning parameters, and evaluating performance with standard metrics. The domain emphasizes refining models to avoid overfitting and maintaining version control to support ongoing investigations and audit trails.
|
>> MLA-C01 Real Sheets <<
[2026] Amazon MLA-C01 Questions: Fosters Your Exam Passing Skills
If you are really intended to pass and become Amazon MLA-C01 exam certified then enrolled in our preparation program today and avail the intelligently designed actual questions. Prep4cram is the best platform, which offers braindumps for MLA-C01 Certification exam duly prepared by experts. Our MLA-C01 Exam Material is good to MLA-C01 pass exam in a week. Now you can become MLA-C01certified professional with Dumps preparation material. Our MLA-C01 exam dumps are efficient, which our dedicated team keeps up-to-date.
Amazon AWS Certified Machine Learning Engineer - Associate Sample Questions (Q110-Q115):
NEW QUESTION # 110
A company wants to improve its customer retention ML model. The current model has 85% accuracy and a new model shows 87% accuracy in testing. The company wants to validate the new model's performance in production.
Which solution will meet these requirements?
- A. Run A/B testing on both models for 4 weeks. Route 20% of traffic to the new model. Monitor customer retention rates across both variants.
- B. Deploy the new model for 4 weeks across all production traffic. Monitor performance metrics and validate improvements.
- C. Run both models in parallel for 4 weeks. Analyze offline predictions weekly by using historical customer data analysis.
- D. Implement alternating deployments for 4 weeks between the current model and the new model. Track performance metrics for comparison.
Answer: A
Explanation:
AWS ML best practices recommend A/B testing to validate model improvements in production while minimizing risk. By routing a controlled portion of live traffic (for example, 20%) to the new model and keeping the majority of traffic on the existing model, the company can directly compare real-world performance using the same data distribution.
This approach allows statistically meaningful comparison of business metrics such as customer retention, rather than relying solely on offline accuracy. It also limits potential negative impact if the new model underperforms in production.
Deploying the new model to 100% of traffic (Option A) introduces unnecessary risk. Offline analysis (Option C) does not reflect live user behavior. Alternating deployments (Option D) introduces confounding factors such as time-based effects.
Therefore, A/B testing is the correct solution.
NEW QUESTION # 111
A customer call center uses Amazon Transcribe to convert hundreds of audio recordings of conversations between customers and support agents to text files. The call center wants to use the text files to train an ML model. To comply with industry regulations, the call center must remove customer names, addresses, and phone numbers from the training text files.
Which solution will meet these requirements with the LEAST development effort?
- A. Store the text files in Amazon S3 buckets. Use S3 Object Lambda functions to redact personal information.
- B. Use the AWS Glue Detect PII transform to remove personal information from the text files.
- C. Configure an Amazon SageMaker Data Wrangler custom transformation to remove personal information from the text files.
- D. Use Amazon Bedrock Guardrails to process and redact personal information from the text files.
Answer: B
Explanation:
Option B is correct because AWS Glue provides a built-in Detect PII transform that can detect, mask, or remove personally identifiable information with minimal custom development. AWS documentation says the Detect PII transform can process predefined AWS-managed PII entity types and supports actions such as removing or masking values. The examples in AWS docs explicitly mention sensitive entities such as phone numbers and addresses, which directly match the problem statement.
The question specifically asks for the least development effort. That wording makes AWS Glue Detect PII the strongest answer because it is a native transformation capability rather than a custom code-heavy workflow.
AWS also documents fine-grained sensitive data detection features that let you apply actions per entity type, improving usability and reducing the need to build custom parsing and redaction logic yourself. This is much easier than creating Lambda-based transformation code or custom text-cleaning logic inside another ML preprocessing tool.
The other options are less suitable. Amazon Bedrock Guardrails is not the standard AWS service documented for bulk ETL-style redaction of training text files in this context. S3 Object Lambda would require more custom engineering to inspect and redact each object. SageMaker Data Wrangler custom transformation would also involve extra implementation work compared with using a purpose-built Glue transform. Because the call center already has text output and simply needs regulated fields like names, addresses, and phone numbers removed before training, the AWS-native low-effort solution is AWS Glue Detect PII. Therefore, the best verified answer is B.
NEW QUESTION # 112
An ML engineer is using a training job to fine-tune a deep learning model in Amazon SageMaker Studio. The ML engineer previously used the same pre-trained model with a similar dataset. The ML engineer expects vanishing gradient, underutilized GPU, and overfitting problems.
The ML engineer needs to implement a solution to detect these issues and to react in predefined ways when the issues occur. The solution also must provide comprehensive real-time metrics during the training.
Which solution will meet these requirements with the LEAST operational overhead?
- A. Use Amazon CloudWatch default metrics to gain insights about the training job. Use the metrics to invoke an AWS Lambda function to initiate the predefined actions.
- B. Use TensorBoard to monitor the training job. Publish the findings to an Amazon Simple Notification Service (Amazon SNS) topic. Create an AWS Lambda function to consume the findings and to initiate the predefined actions.
- C. Expand the metrics in Amazon CloudWatch to include the gradients in each training step. Use the metrics to invoke an AWS Lambda function to initiate the predefined actions.
- D. Use SageMaker Debugger built-in rules to monitor the training job. Configure the rules to initiate the predefined actions.
Answer: D
Explanation:
SageMaker Debugger provides built-in rules to automatically detect issues like vanishing gradients, underutilized GPU, and overfitting during training jobs. It generates real-time metrics and allows users to define predefined actions that are triggered when specific issues occur. This solution minimizes operational overhead by leveraging the managed monitoring capabilities of SageMaker Debugger without requiring custom setups or extensive manual intervention.
NEW QUESTION # 113
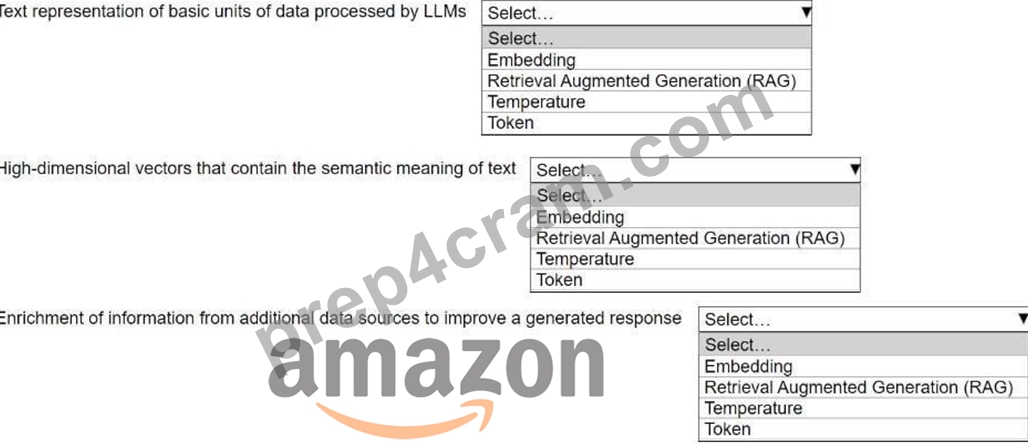
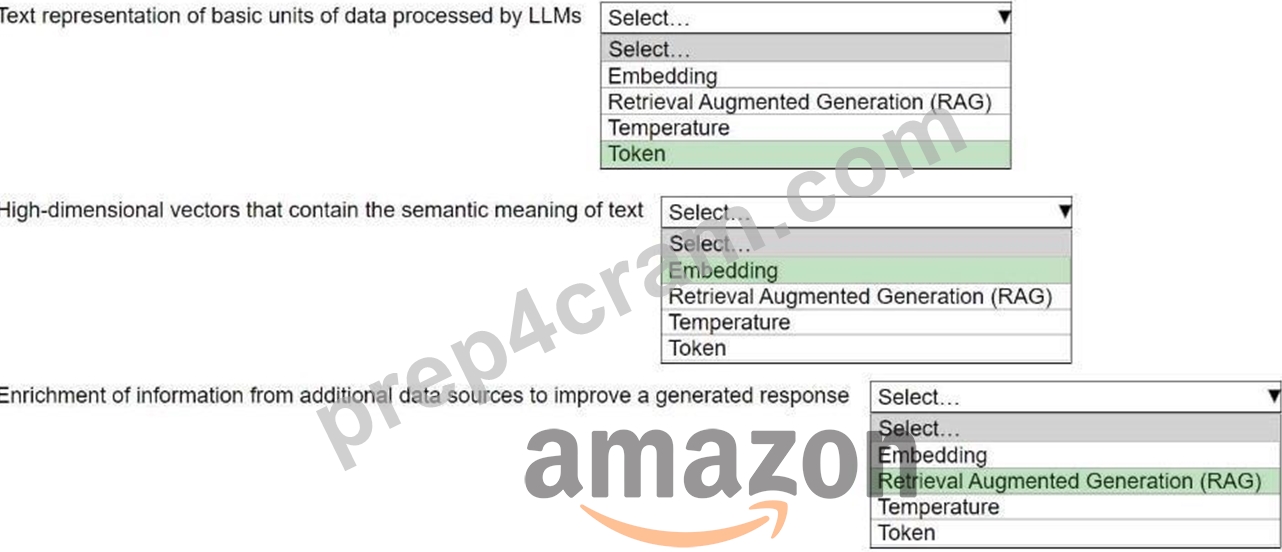
Hotspot Question
An ML engineer is building a generative AI application on Amazon Bedrock by using large language models (LLMs).
Select the correct generative AI term from the following list for each description. Each term should be selected one time or not at all. (Select three.)
- Embedding
- Retrieval Augmented Generation (RAG)
- Temperature
- Token
Answer:
Explanation:
NEW QUESTION # 114
A company uses AWS CodePipeline to orchestrate a continuous integration and continuous delivery (CI/CD) pipeline for ML models and applications.
Select and order the steps from the following list to describe a CI/CD process for a successful deployment.
Select each step one time. (Select and order FIVE.)
. CodePipeline deploys ML models and applications to production.
CodePipeline detects code changes and starts to build automatically.
. Human approval is provided after testing is successful.
. The company builds and deploys ML models and applications to staging servers for testing.
. The company commits code changes or new training datasets to a Git repository.
Answer:
Explanation:
Explanation:
Step 1:
The company commits code changes or new training datasets to a Git repository.
This is the trigger point. A source code or data change initiates the CI/CD pipeline.
Step 2:
CodePipeline detects code changes and starts to build automatically.
CodePipeline monitors the Git repository (for example, AWS CodeCommit, GitHub, or Bitbucket) and automatically triggers the pipeline when changes are detected.
Step 3:
The company builds and deploys ML models and applications to staging servers for testing.
The pipeline runs build, training, and test stages (often using AWS CodeBuild and SageMaker) and deploys artifacts to a staging or test environment for validation.
Step 4:
Human approval is provided after testing is successful.
A manual approval action is a best practice for ML workflows to ensure governance, compliance, and quality checks before production deployment.
Step 5:
CodePipeline deploys ML models and applications to production.
After approval, the pipeline automatically deploys the validated model or application to the production environment.
NEW QUESTION # 115
......
A lot of our new customers don't know how to buy our MLA-C01 exam questions. In fact, it is quite easy. You just need to add your favorite MLA-C01 exam guide into cart. When you finish shopping, you just need to go back to the shopping cart to pay money for our MLA-C01 Study Materials. The whole process is quickly. And you have to remember that we only accept payment by credit card. And you will find that you can receive the MLA-C01 learning prep in a few minutes.
Knowledge MLA-C01 Points: https://www.prep4cram.com/MLA-C01_exam-questions.html
- Get the Right Q-A in Amazon MLA-C01 Exam Questions 🐘 Download ▶ MLA-C01 ◀ for free by simply searching on ➡ www.torrentvce.com ️⬅️ 📈Test MLA-C01 Lab Questions
- Get the Right Q-A in Amazon MLA-C01 Exam Questions 🦎 Search for ⇛ MLA-C01 ⇚ and download it for free on ➡ www.pdfvce.com ️⬅️ website 👴MLA-C01 Test Centres
- 100% Pass Quiz Amazon Latest MLA-C01 Real Sheets 🌋 Enter “ www.testkingpass.com ” and search for ▛ MLA-C01 ▟ to download for free 🤔MLA-C01 Exam Brain Dumps
- Quiz Amazon Marvelous MLA-C01 Real Sheets 🥴 Enter ⮆ www.pdfvce.com ⮄ and search for ➤ MLA-C01 ⮘ to download for free ⏫Valid MLA-C01 Test Labs
- HOT MLA-C01 Real Sheets 100% Pass | Latest Amazon Knowledge AWS Certified Machine Learning Engineer - Associate Points Pass for sure ♣ Simply search for [ MLA-C01 ] for free download on 《 www.troytecdumps.com 》 🔖MLA-C01 Latest Test Online
- MLA-C01 Study Dumps 🐀 Test MLA-C01 Lab Questions 💈 Valid MLA-C01 Braindumps 🦚 Search on ➤ www.pdfvce.com ⮘ for ➠ MLA-C01 🠰 to obtain exam materials for free download 💏MLA-C01 Top Exam Dumps
- 100% Pass Quiz Amazon Latest MLA-C01 Real Sheets 🍦 Enter ➡ www.prep4away.com ️⬅️ and search for 《 MLA-C01 》 to download for free 📈Valid MLA-C01 Test Labs
- Test MLA-C01 Dumps Demo ⚽ MLA-C01 Reliable Test Sims 👳 MLA-C01 Test Collection Pdf ➖ Search for { MLA-C01 } and obtain a free download on [ www.pdfvce.com ] 🌲MLA-C01 Exam Brain Dumps
- HOT MLA-C01 Real Sheets 100% Pass | Latest Amazon Knowledge AWS Certified Machine Learning Engineer - Associate Points Pass for sure 😰 Go to website “ www.troytecdumps.com ” open and search for ⮆ MLA-C01 ⮄ to download for free 🕊MLA-C01 Valid Exam Experience
- MLA-C01 Latest Test Online 🍾 MLA-C01 Test Collection Pdf 🗾 MLA-C01 Exam Brain Dumps 🔟 Open ⏩ www.pdfvce.com ⏪ enter ⮆ MLA-C01 ⮄ and obtain a free download 🐍MLA-C01 Reliable Test Sims
- Get the Right Q-A in Amazon MLA-C01 Exam Questions 🏀 Search for ( MLA-C01 ) and easily obtain a free download on ⇛ www.testkingpass.com ⇚ 🚪MLA-C01 Test Centres
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
What's more, part of that Prep4cram MLA-C01 dumps now are free: https://drive.google.com/open?id=1sbg1moPUtCmvT5QFvR5XMHYWMqs5bXmk