Test Databricks-Certified-Professional-Data-Engineer Pass4sure, Valid Databricks-Certified-Professional-Data-Engineer Guide Files

For added reassurance, we also provide you with up to 1 year of free Databricks Dumps updates and a free demo version of the actual product so that you can verify its validity before purchasing. The key to passing the Databricks Databricks-Certified-Professional-Data-Engineer exam on the first try is vigorous Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) practice. And that's exactly what you'll get when you prepare from our Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) practice material. Each format of our Databricks-Certified-Professional-Data-Engineer study material excels in its own way and serves to improve your skills and gives you an inside-out understanding of each exam topic.
Databricks Certified Professional Data Engineer (Databricks-Certified-Professional-Data-Engineer) exam is a certification program designed to validate the skills and expertise of data engineers in developing and managing big data pipelines using Databricks. Databricks-Certified-Professional-Data-Engineer Exam is ideal for data engineers, ETL developers, and data architects who work with Databricks and want to showcase their skills and proficiency.
Databricks Databricks-Certified-Professional-Data-Engineer Exam Syllabus Topics:
| Topic | Details |
|---|
| Topic 1 | - Databricks Tooling: The Databricks Tooling topic encompasses the various features and functionalities of Delta Lake. This includes understanding the transaction log, Optimistic Concurrency Control, Delta clone, indexing optimizations, and strategies for partitioning data for optimal performance in the Databricks SQL service.
|
| Topic 2 | - Data Processing: The topic covers understanding partition hints, partitioning data effectively, controlling part-file sizes, updating records, leveraging Structured Streaming and Delta Lake, implementing stream-static joins and deduplication. Additionally, it delves into utilizing Change Data Capture and addressing performance issues related to small files.
|
| Topic 3 | - Security & Governance: It discusses creating Dynamic views to accomplishing data masking and using dynamic views to control access to rows and columns.
|
| Topic 4 | - Data Modeling: It focuses on understanding the objectives of data transformations, using Change Data Feed, applying Delta Lake cloning, designing multiplex bronze tables. Lastly it discusses implementing incremental processing and data quality enforcement, implementing lookup tables, and implementing Slowly Changing Dimension tables, and implementing SCD Type 0, 1, and 2 tables.
|
>> Test Databricks-Certified-Professional-Data-Engineer Pass4sure <<
2026 Test Databricks-Certified-Professional-Data-Engineer Pass4sure - Databricks Databricks Certified Professional Data Engineer Exam - Trustable Valid Databricks-Certified-Professional-Data-Engineer Guide Files
With years of experience in the field, Free4Torrent are always striving hard to provide customers with genuine Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) exam dumps so that they crack their Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) exam in less time. Free4Torrent also offer the best self-assessment software so besides memorizing Databricks-Certified-Professional-Data-Engineer Exam Questions, applicants put their learning to the test and reduce their chances of failure in the real Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) examination.
Databricks Certified Professional Data Engineer Exam Sample Questions (Q140-Q145):
NEW QUESTION # 140
A table named user_ltv is being used to create a view that will be used by data analysis on various teams.
Users in the workspace are configured into groups, which are used for setting up data access using ACLs.
The user_ltv table has the following schema:
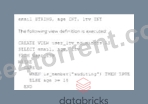
An analyze who is not a member of the auditing group executing the following query:
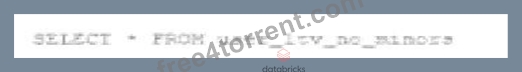
Which result will be returned by this query?
- A. All records from all columns will be displayed with the values in user_ltv.
- B. All columns will be displayed normally for those records that have an age greater than 17; records not meeting this condition will be omitted.
- C. All columns will be displayed normally for those records that have an age greater than 18; records not meeting this condition will be omitted.
- D. All age values less than 18 will be returned as null values all other columns will be returned with the values in user_ltv.
Answer: C
Explanation:
Given the CASE statement in the view definition, the result set for a user not in the auditing group would be constrained by the ELSE condition, which filters out records based on age. Therefore, the view will return all columns normally for records with an age greater than 18, as users who are not in the auditing group will not satisfy the is_member('auditing') condition. Records not meeting the age > 18 condition will not be displayed.
NEW QUESTION # 141
The downstream consumers of a Delta Lake table have been complaining about data quality issues impacting performance in their applications. Specifically, they have complained that invalid latitude and longitude values in the activity_details table have been breaking their ability to use other geolocation processes.
A junior engineer has written the following code to add CHECK constraints to the Delta Lake table:
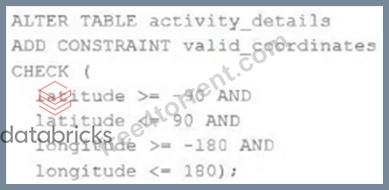
A senior engineer has confirmed the above logic is correct and the valid ranges for latitude and longitude are provided, but the code fails when executed.
Which statement explains the cause of this failure?
- A. The activity details table already exists; CHECK constraints can only be added during initial table creation.
- B. Because another team uses this table to support a frequently running application, two-phase locking is preventing the operation from committing.
- C. The activity details table already contains records; CHECK constraints can only be added prior to inserting values into a table.
- D. The current table schema does not contain the field valid coordinates; schema evolution will need to be enabled before altering the table to add a constraint.
- E. The activity details table already contains records that violate the constraints; all existing data must pass CHECK constraints in order to add them to an existing table.
Answer: E
Explanation:
The failure is that the code to add CHECK constraints to the Delta Lake table fails when executed. The code uses ALTER TABLE ADD CONSTRAINT commands to add two CHECK constraints to a table named activity_details. The first constraint checks if the latitude value is between -90 and 90, and the second constraint checks if the longitude value is between -180 and 180. The cause of this failure is that the activity_details table already contains records that violate these constraints, meaning that they have invalid latitude or longitude values outside of these ranges. When adding CHECK constraints to an existing table, Delta Lake verifies that all existing data satisfies the constraints before adding them to the table. If any record violates the constraints, Delta Lake throws an exception and aborts the operation. Verified Reference: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Add a CHECK constraint to an existing table" section.
https://docs.databricks.com/en/sql/language-manual/sql-ref-syntax-ddl-alter-table.html#add-constraint
NEW QUESTION # 142
An hourly batch job is configured to ingest data files from a cloud object storage container where each batch represent all records produced by the source system in a given hour. The batch job to process these records into the Lakehouse is sufficiently delayed to ensure no late-arriving data is missed. Theuser_idfield represents a unique key for the data, which has the following schema:
user_id BIGINT, username STRING, user_utc STRING, user_region STRING, last_login BIGINT, auto_pay BOOLEAN, last_updated BIGINT New records are all ingested into a table namedaccount_historywhich maintains a full record of all data in the same schema as the source. The next table in the system is namedaccount_currentand is implemented as a Type 1 table representing the most recent value for each uniqueuser_id.
Assuming there are millions of user accounts and tens of thousands of records processed hourly, which implementation can be used to efficiently update the describedaccount_currenttable as part of each hourly batch job?
- A. Use Delta Lake version history to get the difference between the latest version of account history and one version prior, then write these records to account current.
- B. Filter records in account history using the last updated field and the most recent hour processed, as well as the max last iogin by user id write a merge statement to update or insert the most recent value for each user id.
- C. Filter records in account history using the last updated field and the most recent hour processed, making sure to deduplicate on username; write a merge statement to update or insert the most recent value for each username.
- D. Use Auto Loader to subscribe to new files in the account history directory; configure a Structured Streaminq trigger once job to batch update newly detected files into the account current table.
- E. Overwrite the account current table with each batch using the results of a query against the account history table grouping by user id and filtering for the max value of last updated.
Answer: B
Explanation:
This is the correct answer because it efficiently updates the account current table with only the most recent value for each user id. The code filters records in account history using the last updated field and the most recent hour processed, which means it will only process the latest batch of data. It also filters by the max last login by user id, which means it will only keep the most recent record for each user id within that batch. Then, it writes a merge statement to update or insert the most recent value for each user id into account current, which means it will perform an upsert operation based on the user id column. Verified References:
[Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Upsert into a table using merge" section.
NEW QUESTION # 143
Which statement describes the default execution mode for Databricks Auto Loader?
- A. New files are identified by listing the input directory; the target table is materialized by directory querying all valid files in the source directory.
- B. New files are identified by listing the input directory; new files are incrementally and idempotently loaded into the target Delta Lake table.
- C. Cloud vendor-specific queue storage and notification services are configured to track newly arriving files; new files are incrementally and impotently into the target Delta Lake table.
- D. Webhook trigger Databricks job to run anytime new data arrives in a source directory; new data automatically merged into target tables using rules inferred from the data.
Answer: B
Explanation:
Databricks Auto Loader simplifies and automates the process of loading data into Delta Lake. The default execution mode of the Auto Loader identifies new files by listing the input directory. It incrementally and idempotently loads these new files into the target Delta Lake table. This approach ensures that files are not missed and are processed exactly once, avoiding data duplication. The other options describe different mechanisms or integrations that are not part of the default behavior of the Auto Loader.
:
Databricks Auto Loader Documentation: Auto Loader Guide
Delta Lake and Auto Loader: Delta Lake Integration
NEW QUESTION # 144
A data engineer, while designing a Pandas UDF to process financial time-series data with complex calculations that require maintaining state across rows within each stock symbol group, must ensure the function is efficient and scalable. Which approach will solve the problem with minimum overhead while preserving data integrity?
- A. Use applyInPandas on a Spark DataFrame so that each stock symbol group is received as a pandas DataFrame, allowing processing within each group while maintaining state variables local to each group's processing function.
- B. Use a scalar_iter Pandas UDF with iterator-based processing, implementing state management through persistent storage (Delta tables) that gets updated after each batch to maintain continuity across iterator chunks.
- C. Use a grouped-aggregate Pandas UDF that processes each stock symbol group independently, maintaining state through intermediate aggregation results that get passed between successive UDF calls via broadcast variables.
- D. Use a scalar Pandas UDF that processes the entire dataset at once, implementing custom partitioning logic within the UDF to group by stock symbol and maintain state using global variables shared across all executor processes.
Answer: A
Explanation:
applyInPandas is the documented grouped Pandas API for processing each group as a pandas DataFrame.
Spark passes all columns for each group together, which allows per-group state to be maintained naturally inside the function. By contrast, scalar Pandas UDFs are batch-oriented Series-to-Series operations, not group- state processing tools. ( Apache Spark ) This is why option C is the intended best answer among the listed choices. Option A adds unnecessary external persistence overhead, option B relies on unsupported global executor state, and option D misuses grouped aggregation semantics for row-by-row stateful logic. Spark also documents applyInPandas specifically as a grouped operation, while scalar Pandas UDFs process row batches and concatenate results rather than preserving grouped state semantics. ( Apache Spark )
======
NEW QUESTION # 145
......
In addition to the Databricks-Certified-Professional-Data-Engineer study materials, our company also focuses on the preparation and production of other learning materials. If you choose our Databricks-Certified-Professional-Data-Engineer study materials this time, I believe you will find our products unique and powerful. Then you don't have to spend extra time searching for information when you're facing other exams later, just choose us again. As long as you face problems with the exam, our company is confident to help you solve. Give our Databricks-Certified-Professional-Data-Engineer Study Materials a choice is to give you a chance to succeed.
Valid Databricks-Certified-Professional-Data-Engineer Guide Files: https://www.free4torrent.com/Databricks-Certified-Professional-Data-Engineer-braindumps-torrent.html
- Quiz 2026 Marvelous Databricks Test Databricks-Certified-Professional-Data-Engineer Pass4sure 🍿 Enter ⇛ www.exam4labs.com ⇚ and search for ➡ Databricks-Certified-Professional-Data-Engineer ️⬅️ to download for free 🥊Databricks-Certified-Professional-Data-Engineer Latest Exam Cram
- Free PDF Fantastic Databricks-Certified-Professional-Data-Engineer - Test Databricks Certified Professional Data Engineer Exam Pass4sure 📃 Search for [ Databricks-Certified-Professional-Data-Engineer ] on 《 www.pdfvce.com 》 immediately to obtain a free download 😠Databricks-Certified-Professional-Data-Engineer New Dumps Ppt
- Databricks-Certified-Professional-Data-Engineer New Dumps Ppt 🔕 Databricks-Certified-Professional-Data-Engineer Exam Introduction 🦙 Test Databricks-Certified-Professional-Data-Engineer Collection Pdf 🚾 Immediately open ➤ www.practicevce.com ⮘ and search for ☀ Databricks-Certified-Professional-Data-Engineer ️☀️ to obtain a free download ⏮Exam Vce Databricks-Certified-Professional-Data-Engineer Free
- Valid Exam Databricks-Certified-Professional-Data-Engineer Practice ⛲ Valid Databricks-Certified-Professional-Data-Engineer Practice Materials ⏰ Test Databricks-Certified-Professional-Data-Engineer Collection Pdf 💺 The page for free download of 【 Databricks-Certified-Professional-Data-Engineer 】 on ▶ www.pdfvce.com ◀ will open immediately 🦔Best Databricks-Certified-Professional-Data-Engineer Practice
- Best Databricks-Certified-Professional-Data-Engineer Practice 🧊 Databricks-Certified-Professional-Data-Engineer Valid Exam Cost 🤍 Test Databricks-Certified-Professional-Data-Engineer Prep 😇 Search for 【 Databricks-Certified-Professional-Data-Engineer 】 and easily obtain a free download on [ www.prepawaypdf.com ] 🍟Latest Databricks-Certified-Professional-Data-Engineer Mock Test
- Valid Exam Databricks-Certified-Professional-Data-Engineer Practice ⤵ Databricks-Certified-Professional-Data-Engineer Valid Exam Cost 💡 Latest Databricks-Certified-Professional-Data-Engineer Mock Test 🙆 Easily obtain 【 Databricks-Certified-Professional-Data-Engineer 】 for free download through ▶ www.pdfvce.com ◀ 🎨New Databricks-Certified-Professional-Data-Engineer Exam Price
- Perfect Test Databricks-Certified-Professional-Data-Engineer Pass4sure by www.prepawayete.com 🦚 Immediately open ➤ www.prepawayete.com ⮘ and search for ⮆ Databricks-Certified-Professional-Data-Engineer ⮄ to obtain a free download 📻Reliable Databricks-Certified-Professional-Data-Engineer Braindumps Book
- Complete Test Databricks-Certified-Professional-Data-Engineer Pass4sure | Easy To Study and Pass Exam at first attempt - Correct Databricks-Certified-Professional-Data-Engineer: Databricks Certified Professional Data Engineer Exam 👉 Simply search for ⇛ Databricks-Certified-Professional-Data-Engineer ⇚ for free download on ▶ www.pdfvce.com ◀ ⚠Reliable Databricks-Certified-Professional-Data-Engineer Exam Practice
- Databricks-Certified-Professional-Data-Engineer New Dumps Ppt 🐰 Valid Exam Databricks-Certified-Professional-Data-Engineer Practice 🧵 Training Databricks-Certified-Professional-Data-Engineer Online 😇 Easily obtain free download of { Databricks-Certified-Professional-Data-Engineer } by searching on ▶ www.exam4labs.com ◀ ✈Latest Databricks-Certified-Professional-Data-Engineer Mock Test
- Test Databricks-Certified-Professional-Data-Engineer Prep ⚾ Databricks-Certified-Professional-Data-Engineer Latest Exam Cram ⚒ New Databricks-Certified-Professional-Data-Engineer Exam Price 🚻 Easily obtain { Databricks-Certified-Professional-Data-Engineer } for free download through “ www.pdfvce.com ” 🌽Databricks-Certified-Professional-Data-Engineer Exam Introduction
- Latest Databricks-Certified-Professional-Data-Engineer Mock Test 🌺 Databricks-Certified-Professional-Data-Engineer Latest Exam Cram 🍹 Best Databricks-Certified-Professional-Data-Engineer Practice 🚗 Copy URL ⏩ www.practicevce.com ⏪ open and search for ⮆ Databricks-Certified-Professional-Data-Engineer ⮄ to download for free 🦧Valid Databricks-Certified-Professional-Data-Engineer Practice Materials
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes