P.S. Free & New DP-800 dumps are available on Google Drive shared by PDFVCE: https://drive.google.com/open?id=1ylKHJQyXIvcDKNIIyZh5IPGQnbWI3w8z
We have always taken care to provide our customers with the very best. So we provide numerous benefits along with our Developing AI-Enabled Database Solutions exam study material. We provide our customers with the demo version of the Microsoft DP-800 Exam Questions to eradicate any doubts that may be in your mind regarding the validity and accuracy. You can test the product before you buy it.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
PDFVCE team of professionals made this product after working day and night so that users can prepare from it for the Microsoft DP-800 certification test successfully. PDFVCE even guarantees that you will pass the Developing AI-Enabled Database Solutions (DP-800) test on the first try by preparing with real questions. If you fail to pass the certification exam, despite all your efforts, you could get a full refund from PDFVCE according to terms and conditions.
NEW QUESTION # 70
You have a database named DB1. The schema is stored in a GitHub repository as an SDK style SQL database project.
You use a feature branch workflow to deploy changes to DB1
You need to update the local feature branch with the latest changes to main, and then create a pull request to merge the feature branch into main for review.
How should you complete the GitHub CLI script? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.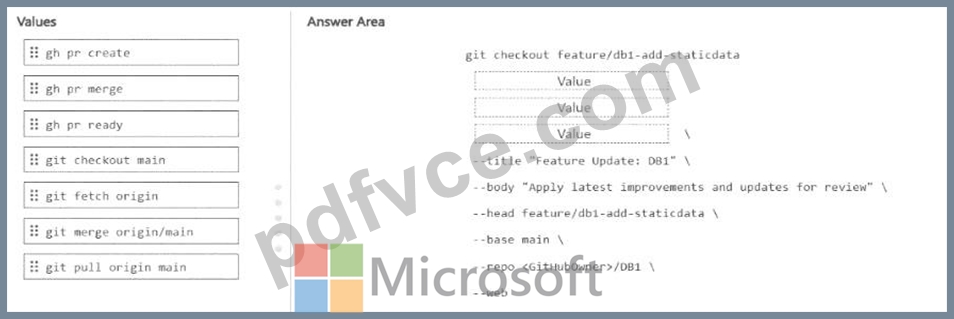
Answer:
Explanation: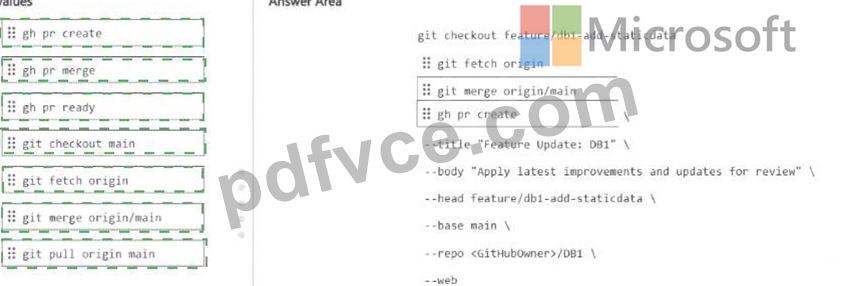
Explanation: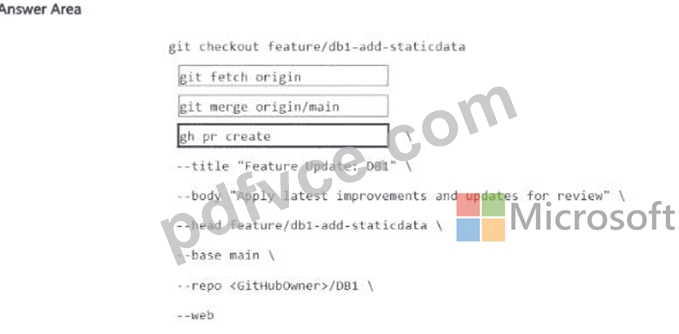
The correct sequence is:
* git fetch origin
* git merge origin/main
* gh pr create
This is the right workflow because the script starts on the local feature branch:
git checkout feature/db1-add-staticdata
To update that local feature branch with the latest changes from main, you first fetch the latest remote refs with git fetch origin , then merge the updated remote main branch into the current feature branch with git merge origin/main . After the feature branch is up to date, the correct GitHub CLI command to open the pull request is gh pr create . GitHub's CLI documentation shows that gh pr create is the command used to create a pull request, and supports flags such as --title, --body, --head, --base, --repo, and --web, which match the script shown in the question.
The other commands are not the best fit here:
* git checkout main would move you off the feature branch, which is not what you want before merging main into the feature branch.
* git pull origin main could update from remote main, but the script pattern here clearly separates fetching and then merging.
* gh pr merge merges an existing pull request, not create one.
* gh pr ready marks a draft PR as ready for review, but does not create the PR.
NEW QUESTION # 71
You have an Azure SQL database that contains a table named dbo.ManualChunks. dbo.HonualChunks contains product manuals A retrieval query already returns the top five matching chunks as nvarchar(max) text.
You need to call an Azure OpenAI REST endpomt for chat completions. The request body must include both the user question and theretiieved chunks.
You write the following Transact-SQL code.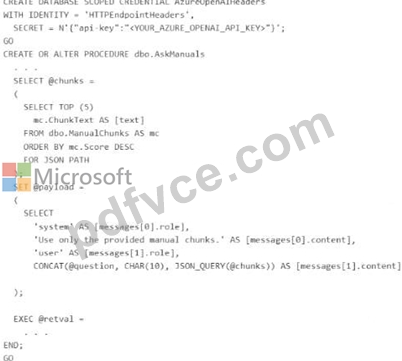
What should you insert at line 22?
Answer: C
Explanation:
The correct insertion at line 22 is FOR JSON PATH, WITHOUT_ARRAY_WRAPPER .
The request body for the Azure OpenAI chat completions call must be a single JSON object containing the messages array with both the system/user content and the retrieved chunks. Microsoft documents that FOR JSON PATH is the preferred way to shape JSON output, especially when you want precise control over nested property names like messages[0].role and messages[1] .content.
The key detail is WITHOUT_ARRAY_WRAPPER . By default, FOR JSON returns results enclosed in square brackets as a JSON array. Microsoft documents that WITHOUT_ARRAY_WRAPPER removes those brackets so a single JSON object is produced instead. That is exactly what is needed here for @payload, because the stored procedure is building one request body, not an array of request bodies.
NEW QUESTION # 72
Which component handles security in Azure SQL?
Answer: C
Explanation:
Azure Key Vault securely stores secrets and keys.
NEW QUESTION # 73
Case Study 1 - Contoso
Existing Environment
Azure Environment
Contoso has an Azure subscription in North Europe that contains the corporate infrastructure.
The current infrastructure contains a Microsoft SQL Server 2017 database. The database contains the following tables.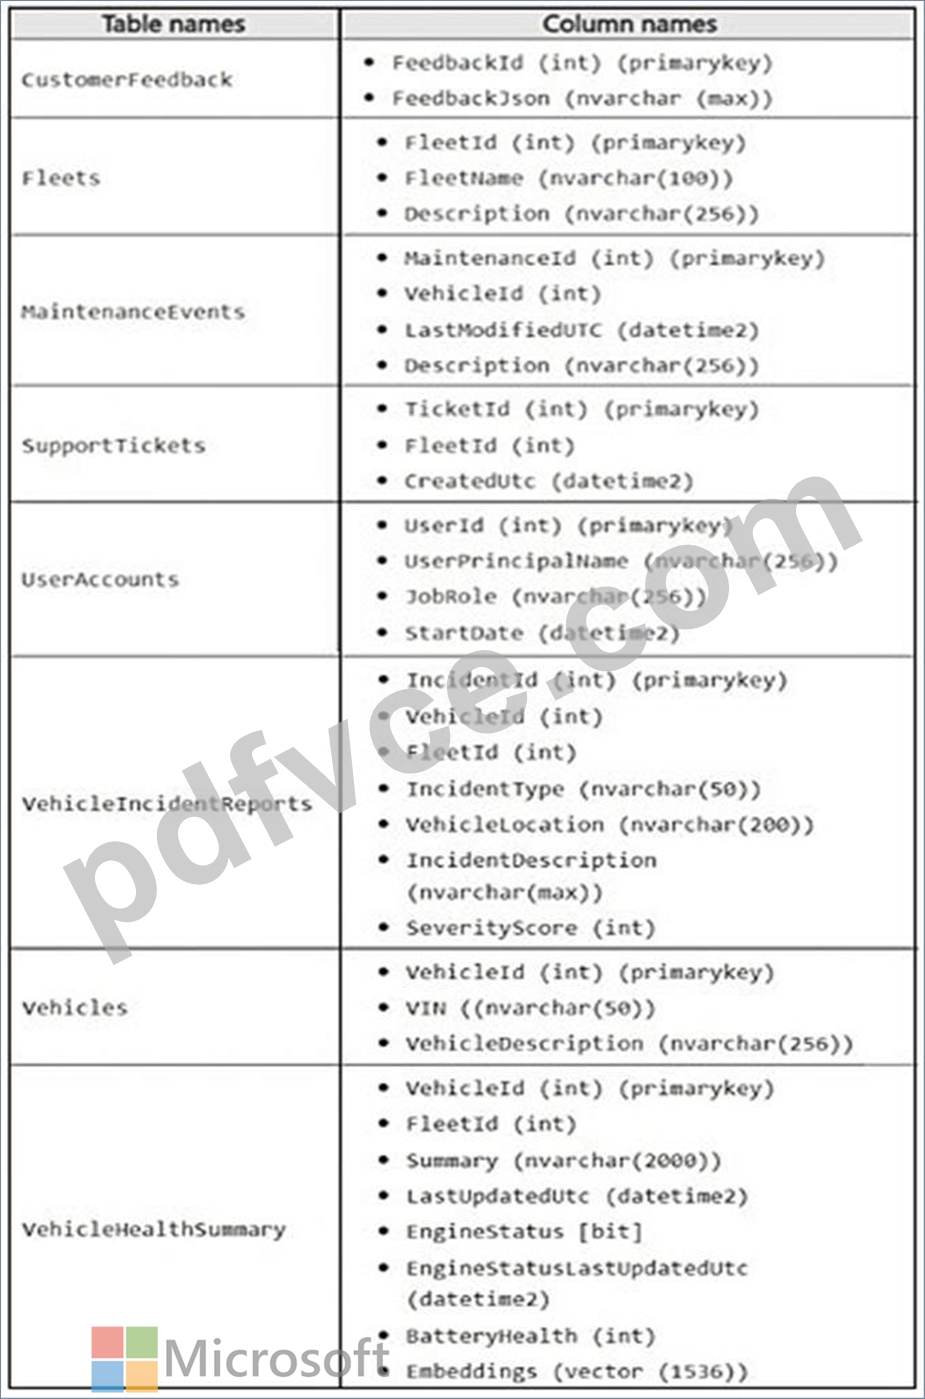
The FeedbackJsoncolumn has a full-text index and stores JSON documents in the following format.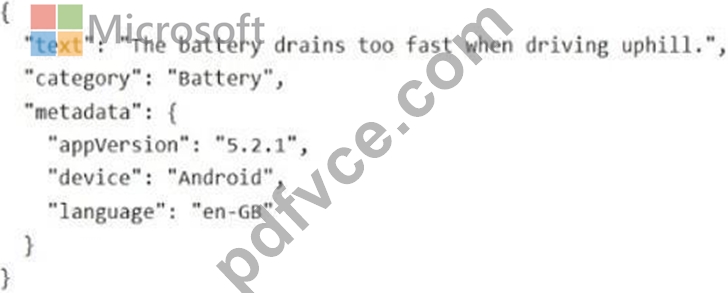
The support staff at Contoso never has the UNMASKpermission.
Problem Statements
Contoso is deploying a new Azure SQL database that will become the authoritative data store for the following:
* AI workloads
* Vector search
* Modernized API access
* Retrieval Augmented Generation (RAG) pipelines
Sometimes the ingestion pipeline fails due to malformed JSON and duplicate payloads.
The engineers at Contoso report that the following dashboard query runs slowly.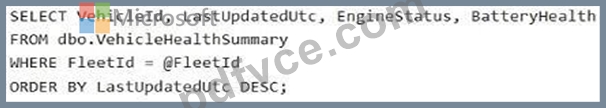
You review the execution plan and discover that the plan shows a clustered index scan.
VehicleIncidentReportsoften contains details about the weather, traffic conditions, and location. Analysts report that it is difficult to find similar incidents based on these details.
Requirements
Planned Changes
Contoso wants to modernize Fleet Intelligence Platform to support AI-powered semantic search over incident reports.
Security Requirements
Contoso identifies the following security requirements:
* Restrict the support staff from viewing Personally Identifiable Information (PII) data, which is full email addresses and phone numbers.
* Enforce row-level filtering so that analysts see only incidents for the fleets to which they are assigned. The analysts can be assigned to multiple fleets.
Database Performance and Requirements
Contoso identifies the following telemetry requirements:
* Telemetry data must be stored in a partitioned table.
* Telemetry data must provide predictable performance for ingestion and retention operations.
* latitude, longitude, and accuracyJSON properties must be filtered by using an index seek.
Contoso identifies the following maintenance data requirements:
* Ensure that any changes to a row in the MaintenanceEventstable updates the corresponding value in the LastModifiedUtccolumn to the time of the change.
* Avoid recursive updates.
AI Search, Embeddings, and Vector Indexing
Contoso plans to implement semantic search over incident data to meet the following requirements:
* Embeddings must be stored in dedicated Azure SQL Database tables.
* Embeddings must be generated from rich natural language fields.
* Chunking must preserve semantic coherence.
* Hybrid search must combine the following:
- Vector similarity
- Keyword filtering or boosting
Development Requirements
The development team at Contoso will use Microsoft Visual Studio Code and GitHub Copilot and will retrieve live metadata from the databases.
Contoso identifies the following requirements for querying data in the FeedbackJsoncolumn of the CustomerFeedbacktable:
* Extract the customer feedback text from the JSON document.
* Filter rows where the JSON text contains a keyword.
* Calculate a fuzzy similarity score between the feedback text and a known issue description.
* Order the results by similarity score, with the highest score first.
You need to recommend a solution that will resolve the ingestion pipeline failure issues.
Which two actions should you recommend? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: A,D
Explanation:
Scenario: Sometimes the ingestion pipeline fails due to malformed JSON and duplicate payloads.
Adding a CHECK constraint with ISJSON and creating a unique index on a computed hash of the payload are effective measures in Azure SQL Database to handle malformed JSON and duplicate payloads.
[E]
JSON Validation with a CHECK Constraint
You can use a CHECK constraint in conjunction with the built-in ISJSON function to ensure that only valid JSON text is stored in a VARCHAR or NVARCHAR column. The constraint automatically rejects any insert or update operation that contains malformed JSON data, preventing pipeline failures due to invalid formatting at the database level.
[D]
Deduplication with a Unique Index on a Hashed Payload
To prevent duplicate payloads, you can create a unique index on a computed column that stores a hash of the entire JSON payload or relevant business keys within the JSON.
Reference:
https://www.shaped.ai/blog/10-best-practices-in-data-ingestion
NEW QUESTION # 74
Drag and Drop Question
You have a Microsoft SQL Server 2025 database that contains a table named dbo.CustomerMessages. dbo.CustomerMessages contains two columns named MessageID (int) and MessageRaw (nvarchar(max)).
MessageRaw can contain a phone number in multiple formats, and some rows do NOT contain a phone number.
You need to write a single SELECT query that meets the following requirements:
- The query must return MessageID, RawNumber, DigitsOnly, and
PhoneStatus.
- RawNumber must contain the first substring that matches a phone-
number pattern, or NULL if no match exists.
- DigitsOnly must remove all non-digit characters from RawNumber, or
return NULL.
- PhoneStatus must return valid when a phone number exists in
MessageRaw, otherwise return Missing.
How should you complete the Transact-SQL query? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.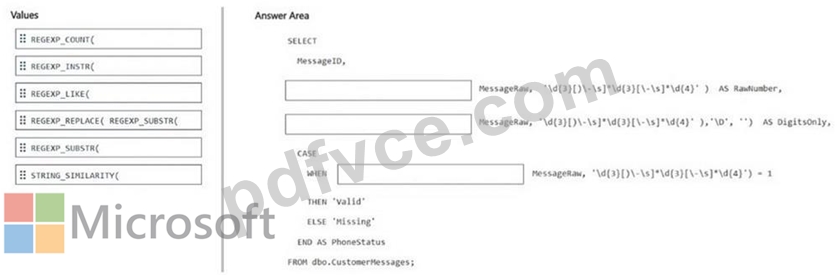
Answer:
Explanation: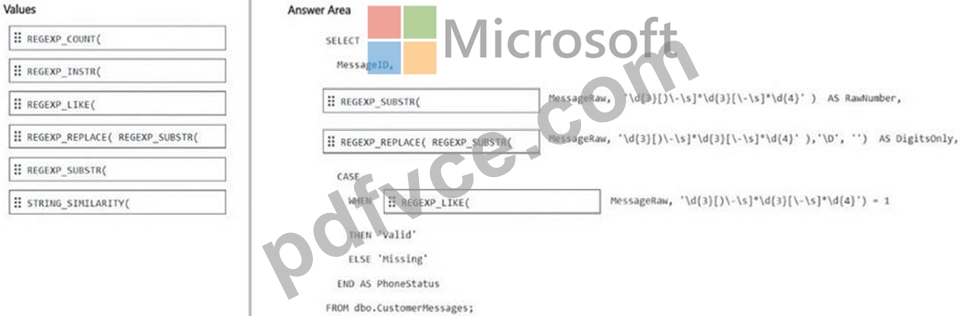
NEW QUESTION # 75
......
A Developing AI-Enabled Database Solutions (DP-800) practice questions is a helpful, proven strategy to crack the Developing AI-Enabled Database Solutions (DP-800) exam successfully. It helps candidates to know their weaknesses and overall performance. PDFVCE software has hundreds of Developing AI-Enabled Database Solutions (DP-800) exam dumps that are useful to practice in real-time.
Valid DP-800 Learning Materials: https://www.pdfvce.com/Microsoft/DP-800-exam-pdf-dumps.html
P.S. Free 2026 Microsoft DP-800 dumps are available on Google Drive shared by PDFVCE: https://drive.google.com/open?id=1ylKHJQyXIvcDKNIIyZh5IPGQnbWI3w8z