Databricks Databricks-Certified-Data-Engineer-Professional考試指南 - Databricks-Certified-Data-Engineer-Professional考試證照綜述

2026 NewDumps最新的Databricks-Certified-Data-Engineer-Professional PDF版考試題庫和Databricks-Certified-Data-Engineer-Professional考試問題和答案免費分享:https://drive.google.com/open?id=1RlDwyWCuX90hXA8pRCjxPhd1edCGcDHQ
隨著21世紀資訊時代的洪流到來,人們不斷提高自己的知識來適應這個時代,但遠遠不夠,就IT行業來說,Databricks的Databricks-Certified-Data-Engineer-Professional考試認證是IT行業必不可少的認證,想要通過這項考試培訓是必須的,因為這項考試是有所困難的,通過了它,就可以受到國際的認可及接受,你將有一個美好的前程及拿著受人矚目的高薪,NewDumps網站有全世界最可靠的IT認證培訓資料,有了它你就可以實現你美好的計畫,我們保證你100%通過認證,參加Databricks的Databricks-Certified-Data-Engineer-Professional考試認證的考生們,你們還在猶豫什麼呢,趕緊行動吧!
Databricks Databricks-Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|
| Databricks Lakehouse Platform | 24% | - Delta Lake
- Lakehouse Architecture
- Unity Catalog
- Data Management
|
| Monitoring and Troubleshooting | 16% | - Performance Optimization
- Monitoring
- Troubleshooting
|
| Data Modeling and Storage | 20% | - File Formats
- Storage Optimization
- Data Modeling
|
| Data Quality and Governance | 12% | - Data Quality
- Governance
- Data Lineage
|
| Data Processing | 28% | - Structured Streaming
- ETL Pipelines
- Spark SQL
- Data Transformation
|
>> Databricks Databricks-Certified-Data-Engineer-Professional考試指南 <<
Databricks-Certified-Data-Engineer-Professional考試證照綜述,Databricks-Certified-Data-Engineer-Professional證照指南
一般考 Databricks Databricks-Certified-Data-Engineer-Professional 認證兩個目的:一來是學習產品知識;二來通過認證,得到一個可以證明自己能力的東西。如何讓自己一次性通過考試呢?下面向您推薦 NewDumps 考古題。如果你正在準備 Databricks 的 Databricks-Certified-Data-Engineer-Professional 考試,為認證做最後衝刺,又苦於沒有絕對權威的考試真題模擬,Databricks-Certified-Data-Engineer-Professional 題庫能助你成功通過考試,獲取認證!
最新的 Databricks Certification Databricks-Certified-Data-Engineer-Professional 免費考試真題 (Q93-Q98):
問題 #93
A junior data engineer is working to implement logic for a Lakehouse table named silver_device_recordings. The source data contains 100 unique fields in a highly nested JSON structure.
The silver_device_recordings table will be used downstream for highly selective joins on a number of fields, and will also be leveraged by the machine learning team to filter on a handful of relevant fields, in total, 15 fields have been identified that will often be used for filter and join logic.
The data engineer is trying to determine the best approach for dealing with these nested fields before declaring the table schema.
Which of the following accurately presents information about Delta Lake and Databricks that may Impact their decision-making process?
- A. Schema inference and evolution on Databricks ensure that inferred types will always accurately match the data types used by downstream systems.
- B. By default Delta Lake collects statistics on the first 32 columns in a table; these statistics are leveraged for data skipping when executing selective queries.
- C. Because Delta Lake uses Parquet for data storage, Dremel encoding information for nesting can be directly referenced by the Delta transaction log.
- D. Tungsten encoding used by Databricks is optimized for storing string data: newly-added native support for querying JSON strings means that string types are always most efficient.
答案:B
解題說明:
Delta Lake, built on top of Parquet, enhances query performance through data skipping, which is based on the statistics collected for each file in a table. For tables with a large number of columns, Delta Lake by default collects and stores statistics only for the first 32 columns. These statistics include min/max values and null counts, which are used to optimize query execution by skipping irrelevant data files. When dealing with highly nested JSON structures, understanding this behavior is crucial for schema design, especially when determining which fields should be flattened or prioritized in the table structure to leverage data skipping efficiently for performance optimization.
問題 #94
Which method can be used to determine the total wall-clock time it took to execute a query?
- A. Open the Query Profiler associated with that query and use the Total wall-clock duration metric.
- B. Open the Query Profiler associated with that query and use the Aggregated task time metric.
- C. In the Spark UI, take the job duration of the longest-running job associated with that query.
- D. In the Spark UI, take the sum of all task durations that ran across all stages for all jobs associated with that query.
答案:A
解題說明:
The Query Profiler in Databricks SQL and notebooks provides a detailed breakdown of query performance metrics. The "Total wall-clock duration" metric directly represents the total elapsed time from query start to completion, including all execution, planning, and waiting stages. In contrast, "Aggregated task time" reflects the cumulative duration across all parallel tasks, which does not equal the total elapsed wall time since tasks often run concurrently. Using job duration from Spark UI can underestimate or overestimate runtime when queries span multiple jobs.
Therefore, the Query Profiler's total wall-clock duration is the officially documented method to determine actual query execution time.
問題 #95
A user wants to use DLT expectations to validate that a derived table report contains all records from the source, included in the table validation_copy.
The user attempts and fails to accomplish this by adding an expectation to the report table definition.
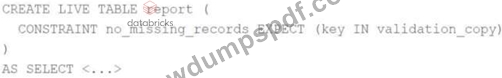
Which approach would allow using DLT expectations to validate all expected records are present in this table?
- A. Define a view that performs a left outer join on validation_copy and report, and reference this view in DLT expectations for the report table
- B. Define a function that performs a left outer join on validation_copy and report and report, and check against the result in a DLT expectation for the report table
- C. Define a temporary table that perform a left outer join on validation_copy and report, and define an expectation that no report key values are null
- D. Define a SQL UDF that performs a left outer join on two tables, and check if this returns null values for report key values in a DLT expectation for the report table.
答案:A
解題說明:
To validate that all records from the source are included in the derived table, creating a view that performs a left outer join between the validation_copy table and the report table is effective. The view can highlight any discrepancies, such as null values in the report table's key columns, indicating missing records. This view can then be referenced in DLT (Delta Live Tables) expectations for the report table to ensure data integrity. This approach allows for a comprehensive comparison between the source and the derived table.
問題 #96
A data engineer is evaluating tools to build a production-grade data pipeline. The team must process change data from cloud object storage, filter out or isolate invalid records, and ensure the timely delivery of clean data to downstream consumers. The team is small, under tight deadlines, and wants to minimize operational overhead while keeping pipelines auditable and maintainable.
Which approach should the data engineer implement?
- A. Use LDP to build declarative pipelines with Streaming Tables and Materialized Views, leveraging built-in support for data expectations and incremental processing.
- B. Implement ingestion using Auto Loader with Structured Streaming, and manage invalid data handling and table updates using checkpointing and merge logic.
- C. Use a hybrid approach: Ingest with Auto Loader into Bronze tables, then process using SQL queries in Databricks Workflows to generate cleaned Silver and Gold tables on a schedule.
- D. Ingest data directly into Delta tables via Spark jobs, apply data quality filters using UDFs, and use LDP for creating Materialized Views.
答案:A
解題說明:
LDP provides a declarative framework for building production-grade pipelines with minimal operational overhead. Streaming Tables and Materialized Views handle incremental processing automatically, while built-in data expectations allow invalid records to be filtered or isolated in a consistent and auditable way. This approach is well suited for small teams under tight deadlines, as it simplifies maintenance, improves reliability, and ensures timely delivery of clean data to downstream consumers.
問題 #97
The data engineer team has been tasked with configured connections to an external database that does not have a supported native connector with Databricks. The external database already has data security configured by group membership. These groups map directly to user group already created in Databricks that represent various teams within the company. A new login credential has been created for each group in the external database. The Databricks Utilities Secrets module will be used to make these credentials available to Databricks users. Assuming that all the credentials are configured correctly on the external database and group membership is properly configured on Databricks, which statement describes how teams can be granted the minimum necessary access to using these credentials?
- A. "Manage" permission should be set on a secret scope containing only those credentials that will be used by a given team.
- B. "Read" permissions should be set on a secret scope containing only those credentials that will be used by a given team.
- C. No additional configuration is necessary as long as all users are configured as administrators in the workspace where secrets have been added.
- D. "Read'' permissions should be set on a secret key mapped to those credentials that will be used by a given team.
答案:B
解題說明:
In Databricks, using the Secrets module allows for secure management of sensitive information such as database credentials. Granting 'Read' permissions on a secret key that maps to database credentials for a specific team ensures that only members of that team can access these credentials. This approach aligns with the principle of least privilege, granting users the minimum level of access required to perform their jobs, thus enhancing security.
問題 #98
......
誰想要獲得Databricks Databricks-Certified-Data-Engineer-Professional認證?我們所知道的該考試是非常具有挑戰性的,隨著最新的Databricks-Certified-Data-Engineer-Professional考古題上線,您將更方便快捷的獲得認證。如果您不相信我們,可以先下載我們的免費PDF試用版的Databricks-Certified-Data-Engineer-Professional問題和答案,我們將保證您100%成功。對于擁有高品質的Databricks Databricks-Certified-Data-Engineer-Professional題庫是絕對值得信賴的,為了配合當真正的考試,我們的專家在不斷的更新我們的問題和答案。如果使用我們的Databricks-Certified-Data-Engineer-Professional考古題沒有通過考試,我們將無條件的退款。
Databricks-Certified-Data-Engineer-Professional考試證照綜述: https://www.newdumpspdf.com/Databricks-Certified-Data-Engineer-Professional-exam-new-dumps.html
- 利用Databricks-Certified-Data-Engineer-Professional考試指南資料,快速通過Databricks Certified Data Engineer Professional Exam ↙ 在【 www.pdfexamdumps.com 】網站下載免費【 Databricks-Certified-Data-Engineer-Professional 】題庫收集Databricks-Certified-Data-Engineer-Professional認證考試解析
- Databricks-Certified-Data-Engineer-Professional考題寶典 📄 Databricks-Certified-Data-Engineer-Professional題庫更新資訊 🦺 Databricks-Certified-Data-Engineer-Professional PDF題庫 👧 ( www.newdumpspdf.com )是獲取➽ Databricks-Certified-Data-Engineer-Professional 🢪免費下載的最佳網站Databricks-Certified-Data-Engineer-Professional題庫更新資訊
- 專業的Databricks Databricks-Certified-Data-Engineer-Professional考試指南是行業領先材料&授權的Databricks-Certified-Data-Engineer-Professional考試證照綜述 🍣 在✔ www.newdumpspdf.com ️✔️網站上免費搜索( Databricks-Certified-Data-Engineer-Professional )題庫Databricks-Certified-Data-Engineer-Professional通過考試
- 專業的Databricks Databricks-Certified-Data-Engineer-Professional考試指南是行業領先材料&授權的Databricks-Certified-Data-Engineer-Professional考試證照綜述 🌗 透過【 www.newdumpspdf.com 】搜索➤ Databricks-Certified-Data-Engineer-Professional ⮘免費下載考試資料Databricks-Certified-Data-Engineer-Professional考試重點
- 最新Databricks-Certified-Data-Engineer-Professional考證 🔰 Databricks-Certified-Data-Engineer-Professional題庫最新資訊 🌳 Databricks-Certified-Data-Engineer-Professional考古題 📤 立即在「 www.newdumpspdf.com 」上搜尋《 Databricks-Certified-Data-Engineer-Professional 》並免費下載Databricks-Certified-Data-Engineer-Professional學習資料
- 值得信賴的Databricks-Certified-Data-Engineer-Professional考試指南和最新的Databricks認證培訓 - 保證通過的Databricks Databricks Certified Data Engineer Professional Exam 📚 免費下載{ Databricks-Certified-Data-Engineer-Professional }只需在▶ www.newdumpspdf.com ◀上搜索Databricks-Certified-Data-Engineer-Professional考試資訊
- Databricks-Certified-Data-Engineer-Professional考古题推薦 🦦 Databricks-Certified-Data-Engineer-Professional題庫更新資訊 🐰 Databricks-Certified-Data-Engineer-Professional PDF題庫 ⛅ 打開網站▶ www.kaoguti.com ◀搜索✔ Databricks-Certified-Data-Engineer-Professional ️✔️免費下載Databricks-Certified-Data-Engineer-Professional考試重點
- 高水平的Databricks-Certified-Data-Engineer-Professional考試指南,最新的考試指南幫助妳輕松通過Databricks-Certified-Data-Engineer-Professional考試 🐍 在➽ www.newdumpspdf.com 🢪上搜索「 Databricks-Certified-Data-Engineer-Professional 」並獲取免費下載最新Databricks-Certified-Data-Engineer-Professional考證
- 專業的Databricks Databricks-Certified-Data-Engineer-Professional考試指南是行業領先材料&授權的Databricks-Certified-Data-Engineer-Professional考試證照綜述 📎 複製網址《 tw.fast2test.com 》打開並搜索☀ Databricks-Certified-Data-Engineer-Professional ️☀️免費下載Databricks-Certified-Data-Engineer-Professional考古题推薦
- 高水平的Databricks-Certified-Data-Engineer-Professional考試指南,最新的考試指南幫助妳輕松通過Databricks-Certified-Data-Engineer-Professional考試 🌭 請在✔ www.newdumpspdf.com ️✔️網站上免費下載☀ Databricks-Certified-Data-Engineer-Professional ️☀️題庫Databricks-Certified-Data-Engineer-Professional題庫最新資訊
- 值得信賴的Databricks-Certified-Data-Engineer-Professional考試指南和最新的Databricks認證培訓 - 保證通過的Databricks Databricks Certified Data Engineer Professional Exam 😃 ⮆ www.kaoguti.com ⮄上搜索[ Databricks-Certified-Data-Engineer-Professional ]輕鬆獲取免費下載Databricks-Certified-Data-Engineer-Professional證照考試
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes
P.S. NewDumps在Google Drive上分享了免費的2026 Databricks Databricks-Certified-Data-Engineer-Professional考試題庫:https://drive.google.com/open?id=1RlDwyWCuX90hXA8pRCjxPhd1edCGcDHQ