2026 Latest ITPassLeader DP-750 PDF Dumps and DP-750 Exam Engine Free Share: https://drive.google.com/open?id=1H7VjLhce5soOc5iV6JcNPh-qA8ZMxF2k
ITPassLeader will provide you with a standard, classified, and authentic study material for all the IT candidates. Our experts are trying their best to supply you with the high quality DP-750 training pdf which contains the important knowledge required by the actual test. The high quality and valid DP-750 study torrent will make you more confidence in the real test. Additionally, you will get the updated Microsoft vce dumps within one year after payment. With the updated DP-750 study material, you can successfully pass at first try.
| Section | Weight | Objectives |
|---|---|---|
| Configure and manage Azure Databricks environments | 15-20% | - Security and authentication setup
|
| Prepare and process data | 30-35% | - Data quality and validation
|
| Deploy and manage data pipelines and workloads | 30-35% | - Lakehouse architecture operations
|
| Secure and govern data using Unity Catalog | 15-20% | - Access control and policies
|
>> Valid DP-750 Test Blueprint <<
ITPassLeader's DP-750 exam training materials evoke great repercussions in the examinees, and has established a very good reputation, which means that choosing ITPassLeader DP-750 exam training materials is to choose success. After you buy our DP-750 VCE Dumps, if you fail to pass the certification exam or there are any problems of learning materials, we will give a full refund. What's more, after you buy our DP-750 exam, we will provide one year free renewal service.
NEW QUESTION # 45
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that writes records to a Delta table named Table1 by using a data quality rule named rule1 You need to meet the following requirements:
* Records that violate rule! must NOT be written to Table1. but the pipeline must continue processing valid records.
* Data engineers must be able to review expectation metrics by using minimal development effort.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
Two things are needed here:
For the rule enforcement: use @dlt.expect_or_drop. This drops any record that violates rule1 before it reaches Table1, while the pipeline continues processing all valid records. The table only ever receives clean data.
For reviewing metrics: the Lakeflow SDP Pipeline UI is the right tool - zero development effort required.
The pipeline graph shows expectation pass/fail counts directly on each table node, and the event log provides a detailed per-batch breakdown of how many records were dropped and why. Data engineers can inspect this at any time without writing additional monitoring queries or connecting external dashboards.
This combination is one of the strongest arguments for SDP over hand-coded Structured Streaming:
expectation observability is built in, not bolted on.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta-live-tables/expectations
NEW QUESTION # 46
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a catalog named finance, finance contains two schemas named default and procurement.
You need to create a table named assets in the procurement schema, assets must contain the following columns:
* asset.id
* asset, type
* asset_name
How should you complete the SQL statement? To answer, drag the appropriate values to the correct targets.
Each value may be used once, more than once, or not at all You may need to drag the split bar between panes or scroll to view content NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
The correct SQL statement uses the full three-part namespace finance.procurement.assets with the three specified columns.
In Unity Catalog, every object lives in a three-tier hierarchy: catalog # schema # table. Using the full path finance.procurement.assets guarantees the table lands in the right schema regardless of the session's current catalog or schema context. Omitting the catalog or schema name relies on the session default, which may not be finance.procurement - a silent mistake that's hard to catch.
The column names asset_id, asset_type, and asset_name must match the spec exactly. Unity Catalog applies access controls, lineage tracking, and tagging at the column level, so the names are meaningful beyond just the schema. Once created, any GRANT statements can target specific columns for fine-grained access control.
Reference: https://learn.microsoft.com/en-us/azure/databricks/sql/language-manual/sql-ref-syntax-ddl-create- table-using
NEW QUESTION # 47
You have an Azure Databricks workspace that contains a Delta table named Table1.
Table1 has accumulated obsolete files.
You need to reduce storage costs. The solution must preserve 30 days of time travel history.
Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: C,D
Explanation:
To diminish storage costs while preserving 60 days of time travel history, you must perform the following two actions: Set the delta.deletedFileRetentionDuration table property to 60 days and Run the vacuum command on the table.
Set the delta.deletedFileRetentionDuration table property to 30 days
This property controls how long data files must be deleted before they become eligible for removal by a cleanup process. By default, it is set to 7 days. Increasing it to 60 days ensures that Delta Lake preserves the underlying parquet files required to query any historical snapshot within your 30-day time travel window.
Run the vacuum command on the tableChanging the retention property alone does not delete files or reduce costs. You must explicitly execute the VACUUM command. The command scans the table and permanently deletes uncommitted or deleted data files that are older than the 60- day threshold defined by your retention duration, thereby freeing up storage space.
Incorrect:
[Not C]
Set the delta.logRetentionDuration table property to 30 days
This property controls how long the transaction log (_delta_log) history is kept, which defaults to
30 days. While the transaction log is required for time travel, modifying this property alone does not delete the heavy data files causing high storage costs. Furthermore, it governs the logs rather than the actual deleted data files.
Reference:
https://www.cloudmatter.io/post/data-audit-with-databricks-delta-time-travel
NEW QUESTION # 48
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have a complex job named Job1 that contains eight tasks. Job1 takes multiple hours to complete.
During the last job run, the final task fails due to a transient issue.
You need to retry the last task without rerunning tasks that have already completed.
What should you do?
Answer: A
Explanation:
Repairing the current job run allows Lakeflow Jobs to rerun the failed task while preserving the successful status of tasks that already completed. This prevents several hours of successful processing from being repeated and reduces both recovery time and compute consumption. If downstream tasks had been skipped because of the failure, they can also be included in the repair operation as appropriate. Updating job parameters changes configuration but does not retry the failed task in the existing run. Restarting Job1 creates a new run and ordinarily executes the workflow again from its beginning. Disabling and reenabling the schedule only changes whether future scheduled runs can start; it does not repair the failed execution. Repair Run is specifically designed for recovering selected failed or skipped tasks in a multi-task workflow.
NEW QUESTION # 49
You have an Azure Databricks workspace that uses Databricks SQL.
You have a table named sales_goals_source that contains the following columns:
* Salesperson
* Item
* 2019
* 2020
* 2021
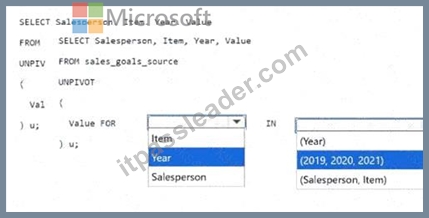
You need to transform the year columns into rows and return the columns Salesperson, Item, Year, and Value.
How should you complete the SQL statement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
SELECT Salesperson, Item, Year, Value
FROM sales_goals_source
UNPIVOT
(
Value FOR [first dropdown] IN [second dropdown]
);
Answer:
Explanation: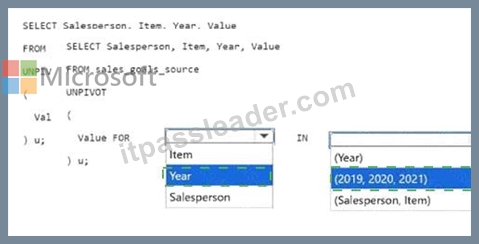
Explanation:
First dropdown: Year
Second dropdown: (2019, 2020, 2021)
The UNPIVOT operator converts the separate 2019, 2020, and 2021 columns into rows. Value becomes the output column containing the values previously stored in those year columns. Year becomes the output name column that identifies the original column from which each value came. Therefore, the expression must use Value FOR Year IN (2019, 2020, 2021). The Salesperson and Item columns are not included in the IN list because they remain identifier columns and are repeated for every resulting year row. A single source row consequently produces three output rows-one for each listed year. Selecting (Year) would reference an output name rather than the source columns that must be rotated.
NEW QUESTION # 50
......
If you just free download the demos of our DP-750 exam questions, then you will find that every detail of our DP-750 study braindumps is perfect. Not only the content of the DP-750 learning guide is the latest and accurate, but also the displays can cater to all needs of the candidates. It is all due to the efforts of the professionals. These professionals have full understanding of the candidates’ problems and requirements hence our DP-750 training engine can cater to your needs beyond your expectations.
DP-750 Vce Torrent: https://www.itpassleader.com/Microsoft/DP-750-dumps-pass-exam.html
DOWNLOAD the newest ITPassLeader DP-750 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1H7VjLhce5soOc5iV6JcNPh-qA8ZMxF2k