If you still have a trace of enterprise, you really want to start working hard! AI-200 exam questions are the most effective helpers on your path. By using AI-200 study engine, your abilities will improve and your mindset will change. Who does not want to be a positive person? This is all supported by strength! In any case, a lot of people have improved their strength through AI-200 Exam simulating. They now have the opportunity they want. Whether to join the camp of the successful ones, purchase AI-200 study engine, you decide for yourself!
| Section | Weight | Objectives |
|---|---|---|
| Integrate backend services and build event-driven architectures | 25% | - Implement messaging and event systems
|
| Develop AI solutions using Azure data services | 30% | - Implement vector-enabled databases
|
| Develop containerized AI solutions on Azure | 25% | - Implement container hosting environments
|
| Secure, monitor, and optimize AI solutions | 20% | - Manage security and configuration
|
Microsoft AI-200 learning materials help you to easily acquire the Developing AI Cloud Solutions on Azure AI-200 certification even if you have never touched the relative knowledge before. With our AI-200 Exam Questions, you will easily get the favor of executives and successfully enter the gates of famous companies.
NEW QUESTION # 132
You are deploying a model in Azure AI Foundry and must ensure the endpoint can handle unpredictable bursts of traffic while keeping cost low during idle periods.
Which deployment type should you choose?
Answer: B
Explanation:
Choose a Standard pay-as-you-go deployment . Microsoft Foundry documentation identifies Standard deployments as appropriate for low-to-medium volume workloads with high burstiness . Standard uses pay-per-token billing , so charges are based on actual inference consumption rather than continuously reserved model capacity. This makes it well suited to workloads whose traffic varies significantly and may have long idle periods.
By contrast, Provisioned Throughput Units (PTUs) reserve model-processing capacity and are designed for sustained, predictable high-throughput workloads where consistent latency is important. Microsoft states that PTUs are billed based on deployed capacity even when that capacity is not actively serving requests.
Consequently, PTU deployments can be economically inefficient when the endpoint is frequently idle or traffic is highly variable.
A Batch deployment is optimized for asynchronous, non-latency-sensitive processing and is not appropriate for an interactive endpoint receiving unpredictable live traffic. Dedicated managed compute with fixed capacity introduces continuously allocated infrastructure and therefore does not align with the requirement to minimize idle-period cost.
Microsoft also recommends Standard or Global Standard for variable, bursty traffic , while provisioned types are recommended for consistent high-volume workloads.
Study Guide references: Microsoft Foundry Models # Standard deployments; pay-per-token billing; bursty workloads; provisioned throughput; batch processing.
NEW QUESTION # 133
A RAG application ' s retrieval step is returning documents that are topically related but not precisely relevant to the user ' s question.
You need to improve retrieval precision without retraining any model.
What should you do?
Answer: A
Explanation:
Enable semantic ranking in Azure AI Search . Semantic ranking is a query-time secondary re-ranking stage that evaluates the initial candidate results using Microsoft language-understanding models and promotes documents that are more semantically aligned with the user ' s actual query intent. It can operate over BM25 results, hybrid results, and the textual content associated with vector-search results.
This directly addresses the stated problem. Vector similarity retrieval often has strong recall but can return passages that are broadly related rather than specifically useful for answering the question. Microsoft ' s RAG guidance explains that reranking improves precision by taking the retrieved candidate set and reordering it so that the most query-relevant chunks are placed first. This reduces irrelevant context passed to the generation model and improves grounding quality without retraining either the embedding model or the LLM.
Increasing embedding dimensionality alone does not guarantee better relevance. Disabling vector search sacrifices semantic retrieval capability, while reducing the index size arbitrarily removes potentially useful content rather than improving ranking quality.
Therefore, semantic re-ranking is the correct precision-improvement mechanism .
Study Guide references: Azure AI Search # semantic ranker; RAG information retrieval; hybrid/vector search; secondary ranking; relevance optimization.
NEW QUESTION # 134
You are developing several microservices to run on Azure Container Apps.
The microservices must allow HTTPS access by using a custom domain.
You need to configure the custom domain in Azure Container Apps.
In which order should you perform the actions? To answer, move all actions from the list of actions to the answer area and arrange them in the correct order.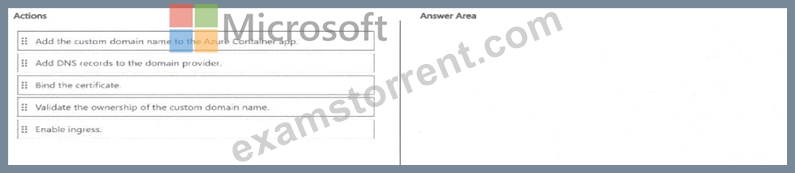
Answer:
Explanation:
Explanation:
Verified answer: 1) Enable ingress; 2) add the required DNS records; 3) validate ownership of the custom domain; 4) add the custom domain to the Container App; 5) bind the certificate.
Detailed Explanation: A custom HTTPS hostname requires an ingress endpoint, DNS proof that the requester controls the hostname, the hostname association itself, and a TLS certificate bound to that hostname.
DNS records must exist before ownership validation can succeed. Once ownership is validated, the domain can be associated with the Container App and the certificate can be bound to provide HTTPS. Skipping ingress or DNS validation would prevent the hostname from being correctly routed and secured.
Study Guide Alignment: Containerized Azure workloads: registry builds, App Service containers, Container Apps revision/scaling behavior, and AKS deployment choices.
Official Microsoft Learn References: AI-200 Study Guide | Custom domains and certificates in Container Apps
Topic 1, Proseware Inc. Case Study
Background
Proseware Inc. develops AI-powered knowledge management solutions for enterprise customers. The company is modernizing its platform to support semantic search, intelligent document retrieval, and real-time partner integrations.
The engineering team uses Python and Azure SDKs. The architecture is being redesigned to support containerized microservices, vector search workloads, and serverless backend processing.
Planned Application Architecture
Microservices are containerized by using Docker.
Code for containerized microservices and Azure Function apps is developed locally but stored in a GitHub repository.
Custom images for containerized microservices are stored in Azure Container Registry (ACR).
Base images are stored in Docker Hub. Custom images must be rebuilt automatically whenever their base images are updated.
Azure Cosmos DB for NoSQL stores documents, metadata, and vector embeddings.
Azure Functions generate vector embeddings of Azure Cosmos DB for NoSQL-hosted documents and send messages to Service Bus to trigger search index updates.
Azure Container Apps (ACA) apps host backend API services that provide semantic search across Azure Cosmos DB for NoSQL documents. API services process Service Bus messages and update search indexes.
Azure Kubernetes Service (AKS) processes batch vector embedding regeneration for existing Azure Cosmos DB for NoSQL documents (whenever the embedding model is changed).
An extranet-facing containerized webhook allows business partners to submit documents to be processed by internal AI workflows for semantic search and retrieval.
Monitoring:
* Telemetry generated by Azure resources is sent to Azure Monitor.
* A Log Analytics workspace is used to collect ACA apps logs, AKS container logs, and Azure Functions apps logs.
* Monitoring of Azure Functions is currently implemented by using Azure Application Insights SDK instrumentation.
Business Requirements
Embeddings for new or updated Azure Cosmos DB for NoSQL-hosted documents must be automatically generated.
Backend API services must scale automatically during business hours.
Cold start delay of backend APIs must be minimized.
Secrets must be stored outside of container images.
Developers must be able to correlate telemetry across Azure Functions hosts and apps.
All tracing must be implemented by using OpenTelemetry SDK instrumentation.
Development efforts must be minimized.
Technical Requirements
Container images must be built automatically and validated before code updates are merged into the main branch.
Image build automation must run inside the Azure Container Registry, eliminating dependency on local developer machines and external build services.
Dependency of image builds on local developer machines must be eliminated.
Event-driven scaling in ACA must occur based on the number of pending messages in the Azure Service Bus queue.
Azure Cosmos DB for NoSQL RU consumption must be minimized.
Vector similarity search must use embeddings stored in Azure Cosmos DB for NoSQL.
The partner-facing containerized webhook service must run on Azure App Service.
Secrets must NOT be stored in container images, source control, or application configuration directly. They must be accessed securely at runtime.
All secrets must be stored centrally in Azure Key Vault and accessed at runtime through a managed identity.
Azure App Service must supply secrets at runtime without relying on external services.
Resources and workloads must be deployed by using Bicep templates through an automated, version- controlled pipeline. Local and command-line deployments must be eliminated to ensure repeatable, auditable deployments.
Known issues
RU consumption spikes during vector similarity queries.
NEW QUESTION # 135
An Azure Storage Blob upload must trigger backend processing.
The solution must:
- Avoid polling.
- Minimize latency.
- Trigger automatically when the upload occurs.
You need to ensure that processing starts as soon as a file is uploaded.
Which trigger should you implement?
Answer: C
Explanation:
Azure Event Grid is the best trigger type to use because it pushes real-time event notifications with minimal latency and completely avoids polling.
Push-based model: Sends events instantly as blobs are created.
Lowest latency: Delivers notifications in milliseconds.
No polling overhead: Saves resources compared to timer or queue polling.
How It Works
A user uploads a file to Azure Blob Storage.Blob Storage fires an Microsoft.Storage.BlobCreated event.
Event Grid pushes this event directly to your backend endpoint (such as an Azure Function or Webhook).Processing starts right away.
Reference:
https://damle-amit075.medium.com/azure-databricks-auto-loader-plugging-the-gap-for-batch-loads-72585b0f158e
NEW QUESTION # 136
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a global retail analytics company that provides AI-driven demand forecasting and product recommendation services to online retailers. The company is modernizing its solution to run entirely on Microsoft Azure.
The platform ingests transaction data, generates embeddings for semantic retrieval, performs vector similarity search, and returns product recommendations through containerized microservices. Developers use Python and Azure SDKs. Operations teams manage container orchestration, scaling, monitoring, and security.
The solution must meet strict performance, scalability, and security requirements.
Current environment
Application architecture
The Recommendation engine is a customer-facing HTTP API running as a containerized Python application. The engine is deployed to Azure Container Apps (ACA).
Embeddings are stored in Azure Database for PostgreSQL by using pgvector.
Semantic retrieval uses metadata filtering combined with vector similarity search.
Azure Managed Redis is used as a caching layer.
Front-end and API workloads are deployed to Azure Container Apps (ACA).
Batch model retraining workloads run in Azure Kubernetes Service (AKS).
Container and CI/CD
Container images are stored in Azure Container Registry (ACR).
CI/CD uses ACR Tasks to build images on commit.
ACA environments support revision management.
AKS workloads are deployed by using Kubernetes manifest files stored in Git.
Monitoring
Logs are collected in Azure Monitor.
Teams inspect container logs and Kubernetes events when troubleshooting.
Developers write KQL queries to analyze latency spikes.
Business requirements
Customer experience: Maintain a seamless, low-latency recommendation experience for end- users, even during unpredictable seasonal traffic spikes.
Operational cost efficiency: Minimize compute expenditures by deallocating resources during periods of inactivity and by preventing runaway scaling costs.
Data integrity and freshness: Ensure that product recommendations always reflect the most current catalog metadata and pricing to prevent customer dissatisfaction.
Security and compliance: Adhere to a Zero Trust security model by eliminating long-lived credentials and centralizing the management of all sensitive secrets.
Global scalability: Support the rapid ingestion of millions of new product embeddings daily without degrading query performance for existing retailers.
Technical requirements
Performance: Semantic search latency must remain under 200 milliseconds at peak load.
Database optimization: Use pgvector for embeddings and implement metadata filtering to reduce compute overhead. Configure compute and memory appropriately for vector workloads to ensure high-dimensional index residency in RAM and efficient mathematical throughput. Vector similarity calculations must be performed only against products that satisfy mandatory metadata constraints.
Database performance: Database connections must support high concurrency with minimal latency through the implementation of connection optimization.
Data load strategy: To ensure maximum ingestion throughput, secondary indexes must be applied only after bulk loading of embeddings is complete.
Caching: Redis cache entries must expire automatically after 10 minutes. Implement a reactive mechanism to invalidate cache entries upon metadata updates.
Identity: Use managed identities for all service-to-service and service-to-database authentication.
Plain-text credentials in configuration files are strictly prohibited.
Secret management: All secrets must be stored centrally. Secrets must be rotated automatically by using a centralized lifecycle policy.
Scaling: Use Kubernetes event-driven autoscaling (KEDA) for event-driven scaling. The Recommendation API must scale based on HTTP traffic, while batch jobs must scale based on queue length and support scale-to-zero.
CI/CD: All images must be stored in Azure Container Registry. Use ACR Tasks to automate image builds triggered by source code commits.
Monitoring: Use KQL to analyze performance telemetry and troubleshoot microservice connectivity failures. Inspect logs and events when troubleshooting AKS and ACA.
You need to implement a secret management solution for the Recommendation API to satisfy the security and identity requirements of Fabrikam Inc.
Which service should you use?
Answer: B
Explanation:
Scenario, technical requirements: Secret management: All secrets must be stored centrally.
Secrets must be rotated automatically by using a centralized lifecycle policy.
Azure Key Vault is the correct and recommended service to store secrets in this scenario. It fulfills all the requirements for centralized management, Python SDK integration, and automated rotation.
Reference:
https://www.cloudthat.com/resources/blog/securing-sensitive-information-with-azure-key-vault
NEW QUESTION # 137
......
ExamsTorrent Developing AI Cloud Solutions on Azure (AI-200) exam questions are consistently updated to make sure they are according to the Microsoft latest exam syllabus. If you choose ExamsTorrent, you can be sure that you'll always get the updated and real AI-200 exam questions, which are essential to go through the AI-200 test in one go. In addition, we also offer up to 1 year of free Microsoft AI-200 certification exam question updates. These free updates ensure that candidates get access to the latest Microsoft exam questions even after they have made their initial purchase.
AI-200 Valid Dumps Files: https://www.examstorrent.com/AI-200-exam-dumps-torrent.html