참고: Pass4Test에서 Google Drive로 공유하는 무료, 최신 Professional-Machine-Learning-Engineer 시험 문제집이 있습니다: https://drive.google.com/open?id=1XF8389YZn_YUnV3Rto2pSsfPiV9zmeEH
만약Pass4Test를 선택하였다면 여러분은 반은 성공한 것입니다. 여러분은 아주 빠르게 안전하게 또 쉽게Google Professional-Machine-Learning-Engineer인증시험 자격증을 취득하실 수 있습니다. 우리Pass4Test에서 제공되는 모든 덤프들은 모두 100%보장 도를 자랑하며 그리고 우리는 일년무료 업데이트를 제공합니다.
| Section | Objectives |
|---|---|
| Topic 1: Monitoring ML solutions | - Performance monitoring and drift detection - Model retraining strategies - Logging and alerting (Cloud Monitoring) |
| Topic 2: Automating and orchestrating ML pipelines | - Vertex AI Pipelines (Kubeflow Pipelines) - Triggering and scheduling pipelines - CI/CD for ML systems |
| Topic 3: Serving and scaling models | - Hardware accelerators (GPU/TPU) in serving - Online prediction (Vertex AI Prediction) - Model optimization (Quantization, Distillation) - Batch prediction |
| Topic 4: Scaling prototypes into ML models | - Frameworks (TensorFlow, PyTorch, JAX, Scikit-learn) - Hyperparameter tuning - Training at scale (Distributed training, TPUs) |
| Topic 5: Architecting low-code ML solutions | - AutoML capabilities and implementation - Implementing BigQuery ML for basic models - Leveraging pre-built ML models as a service (e.g., Vision AI, Speech-to-Text, Recommendations AI) |
| Topic 6: Collaborating within and across teams to manage data and models | - Data management and governance - Version control and reproducibility (e.g., DVC, MLOps) - Collaboration between Data Scientists, Data Engineers, and ML Engineers |
>> Professional-Machine-Learning-Engineer인기자격증 인증시험덤프 <<
Google인증사에서 주췌하는 Professional-Machine-Learning-Engineer시험은 IT업계에 종사하는 분이시라면 모두 패스하여 자격증을 취득하고 싶으리라 믿습니다. Pass4Test에서는 여러분이 IT인증자격증을 편하게 취득할수 있게 도와드리는 IT자격증시험대비시험자료를 제공해드리는 전문 사이트입니다. Pass4Test덤프로 자격증취득의 꿈을 이루세요.
질문 # 185
You work for a magazine distributor and need to build a model that predicts which customers will renew their subscriptions for the upcoming year. Using your company's historical data as your training set, you created a TensorFlow model and deployed it to AI Platform. You need to determine which customer attribute has the most predictive power for each prediction served by the model. What should you do?
정답:D
설명:
* Option A is incorrect because using AI Platform notebooks to perform a Lasso regression analysis on your model, which will eliminate features that do not provide a strong signal, is not a suitable way to determine which customer attribute has the most predictive power for each prediction served by the model. Lasso regression is a method of feature selection that applies a penalty to the coefficients of the linear model, and shrinks them to zero for irrelevant features1. However, this method assumes that the model is linear and additive, which may not be the case for a TensorFlow model. Moreover, this method does not provide feature attributions for each prediction, but rather for the entire dataset.
* Option B is incorrect because streaming prediction results to BigQuery, and using BigQuery's CORR(X1, X2) function to calculate the Pearson correlation coefficient between each feature and the target variable, is not a valid way to determine which customer attribute has the most predictive power for each prediction served by the model. The Pearson correlation coefficient is a measure of the linear relationship between two variables, ranging from -1 to 12. However, this method does not account for the interactions between features or the non-linearity of the model. Moreover, this method does not provide feature attributions for each prediction, but rather for the entire dataset.
* Option C is correct because using the AI Explanations feature on AI Platform, and submitting each prediction request with the 'explain' keyword to retrieve feature attributions using the sampled Shapley method, is the best way to determine which customer attribute has the most predictive power for each prediction served by the model. AI Explanations is a service that allows you to get feature attributions for your deployed models on AI Platform3. Feature attributions are values that indicate how much each feature contributed to the prediction for a given instance4. The sampled Shapley method is a technique that uses the Shapley value, a game-theoretic concept, to measure the contribution of each feature to the prediction5. By using AI Explanations, you can get feature attributions for each prediction request, and identify the most important features for each customer.
* Option D is incorrect because using the What-If tool in Google Cloud to determine how your model will perform when individual features are excluded, and ranking the feature importance in order of those that caused the most significant performance drop when removed from the model, is not a practical way to determine which customer attribute has the most predictive power for each prediction served by the model. The What-If tool is a tool that allows you to visualize and analyze your ML models and datasets.
However, this method requires manually editing or removing features for each instance, and observing
* the change in the prediction. This method is not scalable or efficient, and may not capture the interactions between features or the non-linearity of the model.
References:
* Lasso regression
* Pearson correlation coefficient
* AI Explanations overview
* Feature attributions
* Sampled Shapley method
* [What-If tool overview]
질문 # 186
You work for a bank. You have created a custom model to predict whether a loan application should be flagged for human review. The input features are stored in a BigQuery table. The model is performing well and you plan to deploy it to production. Due to compliance requirements the model must provide explanations for each prediction. You want to add this functionality to your model code with minimal effort and provide explanations that are as accurate as possible What should you do?
정답:A
설명:
The best option for adding explanations to your model code with minimal effort and providing explanations that are as accurate as possible is to upload the custom model to Vertex AI Model Registry and configure feature-based attribution by using sampled Shapley with input baselines. This option allows you to leverage the power and simplicity of Vertex Explainable AI to generate feature attributions for each prediction, and understand how each feature contributes to the model output. Vertex Explainable AI is a service that can help you understand and interpret predictions made by your machine learning models, natively integrated with a number of Google's products and services. Vertex Explainable AI can provide feature-based and example-based explanations to provide better understanding of model decision making. Feature-based explanations are explanations that show how much each feature in the input influenced the prediction. Feature-based explanations can help you debug and improve model performance, build confidence in the predictions, and understand when and why things go wrong. Vertex Explainable AI supports various feature attribution methods, such as sampled Shapley, integrated gradients, and XRAI. Sampled Shapley is a feature attribution method that is based on the Shapley value, which is a concept from game theory that measures how much each player in a cooperative game contributes to the total payoff. Sampled Shapley approximates the Shapley value for each feature by sampling different subsets of features, and computing the marginal contribution of each feature to the prediction. Sampled Shapley can provide accurate and consistent feature attributions, but it can also be computationally expensive. To reduce the computation cost, you can use input baselines, which are reference inputs that are used to compare with the actual inputs. Input baselines can help you define the starting point or the default state of the features, and calculate the feature attributions relative to the input baselines. By uploading the custom model to Vertex AI Model Registry and configuring feature-based attribution by using sampled Shapley with input baselines, you can add explanations to your model code with minimal effort and provide explanations that are as accurate as possible1.
The other options are not as good as option C, for the following reasons:
Option A: Creating an AutoML tabular model by using the BigQuery data with integrated Vertex Explainable AI would require more skills and steps than uploading the custom model to Vertex AI Model Registry and configuring feature-based attribution by using sampled Shapley with input baselines. AutoML tabular is a service that can automatically build and train machine learning models for structured or tabular data. AutoML tabular can use BigQuery as the data source, and provide feature-based explanations by using integrated gradients as the feature attribution method. However, creating an AutoML tabular model by using the BigQuery data with integrated Vertex Explainable AI would require more skills and steps than uploading the custom model to Vertex AI Model Registry and configuring feature-based attribution by using sampled Shapley with input baselines. You would need to create a new AutoML tabular model, import the BigQuery data, configure the model settings, train and evaluate the model, and deploy the model. Moreover, this option would not use your existing custom model, which is already performing well, but create a new model, which may not have the same performance or behavior as your custom model2.
Option B: Creating a BigQuery ML deep neural network model, and using the ML.EXPLAIN_PREDICT method with the num_integral_steps parameter would not allow you to deploy the model to production, and could provide less accurate explanations than using sampled Shapley with input baselines. BigQuery ML is a service that can create and train machine learning models by using SQL queries on BigQuery. BigQuery ML can create a deep neural network model, which is a type of machine learning model that consists of multiple layers of neurons, and can learn complex patterns and relationships from the data. BigQuery ML can also provide feature-based explanations by using the ML.EXPLAIN_PREDICT method, which is a SQL function that returns the feature attributions for each prediction. The ML.EXPLAIN_PREDICT method uses integrated gradients as the feature attribution method, which is a method that calculates the average gradient of the prediction output with respect to the feature values along the path from the input baseline to the input. The num_integral_steps parameter is a parameter that determines the number of steps along the path from the input baseline to the input. However, creating a BigQuery ML deep neural network model, and using the ML.EXPLAIN_PREDICT method with the num_integral_steps parameter would not allow you to deploy the model to production, and could provide less accurate explanations than using sampled Shapley with input baselines. BigQuery ML does not support deploying the model to Vertex AI Endpoints, which is a service that can provide low-latency predictions for individual instances. BigQuery ML only supports batch prediction, which is a service that can provide high-throughput predictions for a large batch of instances. Moreover, integrated gradients can provide less accurate and consistent explanations than sampled Shapley, as integrated gradients can be sensitive to the choice of the input baseline and the num_integral_steps parameter3.
Option D: Updating the custom serving container to include sampled Shapley-based explanations in the prediction outputs would require more skills and steps than uploading the custom model to Vertex AI Model Registry and configuring feature-based attribution by using sampled Shapley with input baselines. A custom serving container is a container image that contains the model, the dependencies, and a web server. A custom serving container can help you customize the prediction behavior of your model, and handle complex or non-standard data formats. However, updating the custom serving container to include sampled Shapley-based explanations in the prediction outputs would require more skills and steps than uploading the custom model to Vertex AI Model Registry and configuring feature-based attribution by using sampled Shapley with input baselines. You would need to write code, implement the sampled Shapley algorithm, build and test the container image, and upload and deploy the container image. Moreover, this option would not leverage the power and simplicity of Vertex Explainable AI, which can provide feature-based explanations natively integrated with Vertex AI services4.
Reference:
Preparing for Google Cloud Certification: Machine Learning Engineer, Course 3: Production ML Systems, Week 4: Evaluation Google Cloud Professional Machine Learning Engineer Exam Guide, Section 3: Scaling ML models in production, 3.3 Monitoring ML models in production Official Google Cloud Certified Professional Machine Learning Engineer Study Guide, Chapter 6: Production ML Systems, Section 6.3: Monitoring ML Models Vertex Explainable AI AutoML Tables BigQuery ML Using custom containers for prediction
질문 # 187
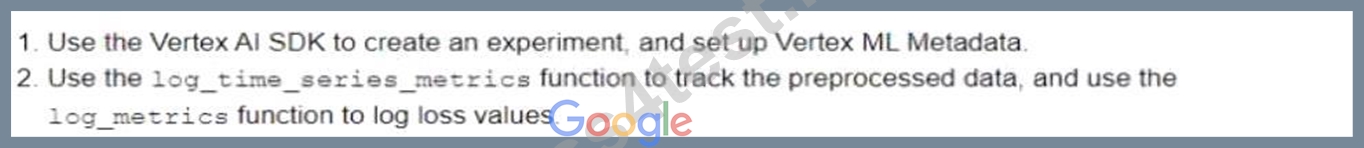
You are developing a model to predict whether a failure will occur in a critical machine part. You have a dataset consisting of a multivariate time series and labels indicating whether the machine part failed You recently started experimenting with a few different preprocessing and modeling approaches in a Vertex Al Workbench notebook. You want to log data and track artifacts from each run. How should you set up your experiments?


정답:C
설명:
The option A is the most suitable solution for logging data and tracking artifacts from each run of a model development experiment in a Vertex AI Workbench notebook. Vertex AI Workbench is a service that allows you to create and run interactive notebooks on Google Cloud. You can use Vertex AI Workbench to experiment with different preprocessing and modeling approaches for your time series prediction problem.
You can also use the Vertex AI TensorBoard instance and the Vertex AI SDK to create an experiment and associate the TensorBoard instance. TensorBoard is a tool that allows you to visualize and monitor the metrics and artifacts of your ML experiments. You can use the Vertex AI SDK to create an experiment object, which is a logical grouping of runs that share a common objective. You can also use the Vertex AI SDK to associate the experiment object with a TensorBoard instance, which is a managed service that hosts a TensorBoard web app. By using the Vertex AI TensorBoard instance and the Vertex AI SDK, you can easily set up and manage your experiments, and access the TensorBoard web app from the Vertex AI console. You can also use the log_time_series_metrics function and the log_metrics function to log data and track artifacts from each run.
The log_time_series_metrics function is a function that allows you to log the time series data, such as the multivariate time series and the labels, to the TensorBoard instance. The log_metrics function is a function that allows you to log the scalar metrics, such as the loss values, to the TensorBoard instance. By using these functions, you can record the data and artifacts from each run of your experiment, and compare them in the TensorBoard web app. You can also use the TensorBoard web app to visualize the data and artifacts, such as the time series plots, the scalar charts, the histograms, and the distributions. By using the Vertex AI TensorBoard instance, the Vertex AI SDK, and the log functions, you can log data and track artifacts from each run of your experiment in a Vertex AI Workbench notebook. References :
* Vertex AI Workbench documentation
* Vertex AI TensorBoard documentation
* Vertex AI SDK documentation
* log_time_series_metrics function documentation
* log_metrics function documentation
* [Preparing for Google Cloud Certification: Machine Learning Engineer Professional Certificate]
질문 # 188
You have created a Vertex Al pipeline that includes two steps. The first step preprocesses 10 TB data completes in about 1 hour, and saves the result in a Cloud Storage bucket The second step uses the processed data to train a model You need to update the model's code to allow you to test different algorithms You want to reduce pipeline execution time and cost, while also minimizing pipeline changes What should you do?
정답:A
질문 # 189
You have created a Vertex Al pipeline that automates custom model training You want to add a pipeline component that enables your team to most easily collaborate when running different executions and comparing metrics both visually and programmatically. What should you do?
정답:C
설명:
Vertex AI Experiments is a managed service that allows you to track, compare, and manage experiments with Vertex AI. You can use Vertex AI Experiments to record the parameters, metrics, and artifacts of each pipeline run, and compare them in a graphical interface. Vertex AI TensorBoard is a tool that lets you visualize the metrics of your models, such as accuracy, loss, and learning curves. By logging metrics to Vertex ML Metadata and using Vertex AI Experiments and TensorBoard, you can easily collaborate with your team and find the best model configuration for your problem. Reference: Vertex AI Pipelines: Metrics visualization and run comparison using the KFP SDK, Track, compare, manage experiments with Vertex AI Experiments, Vertex AI Pipelines
질문 # 190
......
Professional-Machine-Learning-Engineer인증시험은Google인증시험중의 하나입니다.그리고 또한 비중이 아주 큰 인증시험입니다. 그리고Google Professional-Machine-Learning-Engineer인증시험 패스는 진짜 어렵다고 합니다. 우리Pass4Test에서는 여러분이Professional-Machine-Learning-Engineer인증시험을 편리하게 응시하도록 전문적이 연구팀에서 만들어낸 최고의Professional-Machine-Learning-Engineer덤프를 제공합니다, Pass4Test와 만남으로 여러분은 아주 간편하게 어려운 시험을 패스하실 수 있습니다,
Professional-Machine-Learning-Engineer덤프문제모음: https://www.pass4test.net/Professional-Machine-Learning-Engineer.html
BONUS!!! Pass4Test Professional-Machine-Learning-Engineer 시험 문제집 전체 버전을 무료로 다운로드하세요: https://drive.google.com/open?id=1XF8389YZn_YUnV3Rto2pSsfPiV9zmeEH