BTW, DOWNLOAD part of Test4Sure Professional-Machine-Learning-Engineer dumps from Cloud Storage: https://drive.google.com/open?id=1oLbpsvzqBTyQtqJ71AHEvz0AKwD3_MGu
There are a lot of excellent experts and professors in our company. The high quality of the Professional-Machine-Learning-Engineer reference guide from our company resulted from their constant practice, hard work and their strong team spirit. After a long period of research and development, our Professional-Machine-Learning-Engineer test questions have been the leader study materials in the field. We have taken our customers’ suggestions of the Professional-Machine-Learning-Engineer Exam Prep seriously, and according to these useful suggestions, we have tried our best to perfect the Professional-Machine-Learning-Engineer reference guide from our company just in order to meet the need of these customers well. So stop hesitation and buy our study materials.
| Section | Objectives |
|---|---|
| Deployment and operations | - Model deployment
|
| ML model development | - Model training and tuning
|
| Designing ML solutions | - Framing ML problems
|
| Data preparation and processing | - Data ingestion and pipelines
|
| ML pipeline automation and orchestration | - Pipeline design
|
>> Professional-Machine-Learning-Engineer Training Tools <<
It is impossible to pass Professional-Machine-Learning-Engineer exam without efforts and time, but our Test4Sure team will try our best to reduce your burden when you are preparing for Professional-Machine-Learning-Engineer exam. The normal model test and understandable answer analysis will make you secretly master the exam skills to pass Professional-Machine-Learning-Engineer exam. In order to reduce more stress for you, we promise you if you fail the exam, what you need to do is to send your scanned unqualified transcripts to our email box. After confirmation, we will immediately refund all the money that you purchased the Professional-Machine-Learning-Engineer Exam Materials. Test4Sure is worthy your trust.
NEW QUESTION # 29
Your team is working on an NLP research project to predict political affiliation of authors based on articles they have written. You have a large training dataset that is structured like this: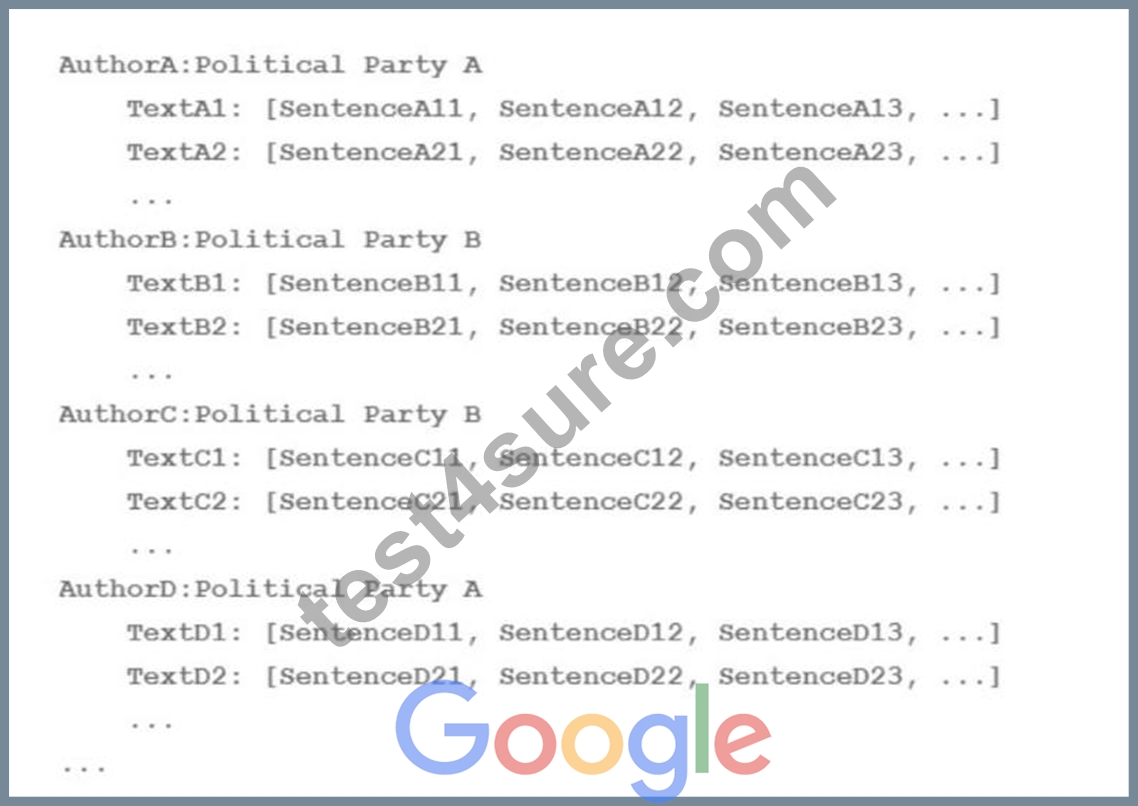
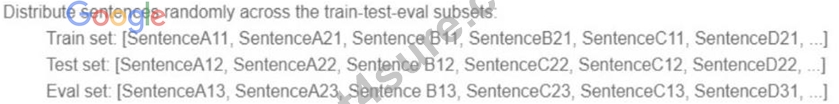
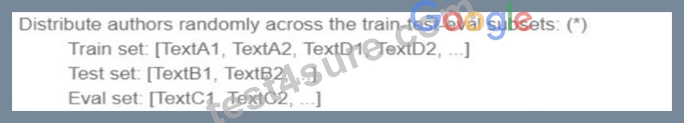
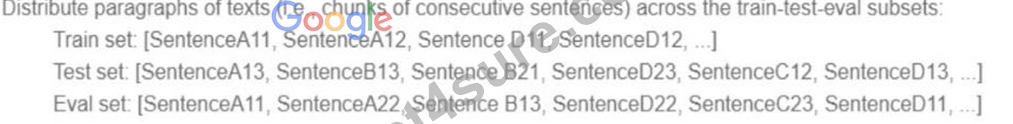
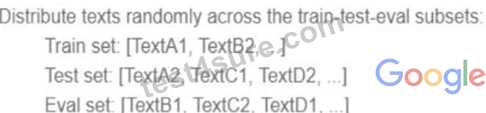
You followed the standard 80%-10%-10% data distribution across the training, testing, and evaluation subsets. How should you distribute the training examples across the train-test-eval subsets while maintaining the 80-10-10 proportion?
Answer: B
Explanation:
If we just put inside the Training set , Validation set and Test set , randomly Text, Paragraph or sentences the model will have the ability to learn specific qualities about The Author's use of language beyond just his own articles. Therefore the model will mixed up different opinions. Rather if we divided things up a the author level, so that given authors were only on the training data, or only in the test data or only in the validation data. The model will find more difficult to get a high accuracy on the test validation (What is correct and have more sense!). Because it will need to really focus in author by author articles rather than get a single political affiliation based on a bunch of mixed articles from different authors. https://developers.google.com/machine-learning/crash-course/18th-century-literature For example, suppose you are training a model with purchase data from a number of stores. You know, however, that the model will be used primarily to make predictions for stores that are not in the training data. To ensure that the model can generalize to unseen stores, you should segregate your data sets by stores. In other words, your test set should include only stores different from the evaluation set, and the evaluation set should include only stores different from the training set. https://cloud.google.com/automl-tables/docs/prepare#ml-use
NEW QUESTION # 30
You have trained a deep neural network model on Google Cloud. The model has low loss on the training data, but is performing worse on the validation dat a. You want the model to be resilient to overfitting. Which strategy should you use when retraining the model?
Answer: B
Explanation:
https://machinelearningmastery.com/introduction-to-regularization-to-reduce-overfitting-and-improve-generalization-error/
NEW QUESTION # 31
You work for a company that is developing a new video streaming platform. You have been asked to create a recommendation system that will suggest the next video for a user to watch.
After a review by an AI Ethics team, you are approved to start development. Each video asset in your company's catalog has useful metadata (e.g., content type, release date, country), but you do not have any historical user event data. How should you build the recommendation system for the first version of the product?
Answer: C
Explanation:
https://developers.google.com/machine-learning/guides/rules-of-ml
NEW QUESTION # 32
You built and manage a production system that is responsible for predicting sales numbers. Model accuracy is crucial, because the production model is required to keep up with market changes. Since being deployed to production, the model hasn't changed; however the accuracy of the model has steadily deteriorated. What issue is most likely causing the steady decline in model accuracy?
Answer: C
Explanation:
Model retraining is the process of updating an existing machine learning model with new data and parameters to improve its performance and accuracy. Model retraining is essential for maintaining the relevance and validity of the model, especially when the data or the environment changes over time. Model retraining can help to avoid or reduce the effects of model degradation, which is the phenomenon of the model's predictive performance decreasing as it is tested on new datasets within rapidly evolving environments1.
For the use case of predicting sales numbers, model accuracy is crucial, because the production model is required to keep up with market changes. Market changes can affect the demand, supply, price, and preference of the products, and thus influence the sales numbers. If the model is not retrained with new data that reflects the market changes, it may become outdated and inaccurate, and fail to capture the patterns and trends of the sales numbers. Therefore, the most likely issue that is causing the steady decline in model accuracy is the lack of model retraining.
The other options are not as likely as option B, because they are not directly related to the model's ability to adapt to market changes. Option A, poor data quality, may affect the model's accuracy, but it is not a specific cause of model degradation over time. Option C, too few layers in the model for capturing information, may affect the model's complexity and expressiveness, but it is not a specific cause of model degradation over time. Option D, incorrect data split ratio during model training, evaluation, validation, and test, may affect the model's generalization and validation, but it is not a specific cause of model degradation over time. Therefore, option B, lack of model retraining, is the best answer for this question.
Reference:
Beware Steep Decline: Understanding Model Degradation In Machine Learning Models
NEW QUESTION # 33
You are working on a system log anomaly detection model for a cybersecurity organization. You have developed the model using TensorFlow, and you plan to use it for real-time prediction. You need to create a Dataflow pipeline to ingest data via Pub/Sub and write the results to BigQuery. You want to minimize the serving latency as much as possible. What should you do?
Answer: C
Explanation:
The best option for creating a Dataflow pipeline for real-time anomaly detection is to load the model directly into the Dataflow job as a dependency, and use it for prediction. This option has the following advantages:
It minimizes the serving latency, as the model prediction logic is executed within the same Dataflow pipeline that ingests and processes the data. There is no need to invoke external services or containers, which can introduce network overhead and latency.
It simplifies the deployment and management of the model, as the model is packaged with the Dataflow job and does not require a separate service or container. The model can be updated by redeploying the Dataflow job with a new model version.
It leverages the scalability and reliability of Dataflow, as the model prediction logic can scale up or down with the data volume and handle failures and retries automatically.
The other options are less optimal for the following reasons:
Option A: Containerizing the model prediction logic in Cloud Run, which is invoked by Dataflow, introduces additional latency and complexity. Cloud Run is a serverless platform that runs stateless containers, which means that the model prediction logic needs to be initialized and loaded every time a request is made. This can increase the cold start latency and reduce the throughput. Moreover, Cloud Run has a limit on the number of concurrent requests per container, which can affect the scalability of the model prediction logic. Additionally, this option requires managing two separate services: the Dataflow pipeline and the Cloud Run container.
Option C: Deploying the model to a Vertex AI endpoint, and invoking this endpoint in the Dataflow job, also introduces additional latency and complexity. Vertex AI is a managed service that provides various tools and features for machine learning, such as training, tuning, serving, and monitoring. However, invoking a Vertex AI endpoint from a Dataflow job requires making an HTTP request, which can incur network overhead and latency. Moreover, this option requires managing two separate services: the Dataflow pipeline and the Vertex AI endpoint.
Option D: Deploying the model in a TFServing container on Google Kubernetes Engine, and invoking it in the Dataflow job, also introduces additional latency and complexity. TFServing is a high-performance serving system for TensorFlow models, which can handle multiple versions and variants of a model. However, invoking a TFServing container from a Dataflow job requires making a gRPC or REST request, which can incur network overhead and latency. Moreover, this option requires managing two separate services: the Dataflow pipeline and the Google Kubernetes Engine cluster.
Reference:
[Dataflow documentation]
[TensorFlow documentation]
[Cloud Run documentation]
[Vertex AI documentation]
[TFServing documentation]
NEW QUESTION # 34
......
As everybody knows, the most crucial matter is the quality of Google Professional Machine Learning Engineer study question for learners. We have been doing this professional thing for many years. Let the professionals handle professional issues. So as for us, we have enough confidence to provide you with the best Professional-Machine-Learning-Engineer exam questions for your study to pass it. With many years work experience, we have fast reaction speed to market change and need. In this way, we have the Latest Professional-Machine-Learning-Engineer Test Guide. You don’t worry about that how to keep up with the market trend, just follow us. In addition to the industry trends, the Professional-Machine-Learning-Engineer test guide is written by lots of past materials’ rigorous analyses. Only with strict study, we write the latest and the specialized study materials. We can say that our Professional-Machine-Learning-Engineer exam questions are the most suitable for examinee to pass the exam.
Reliable Professional-Machine-Learning-Engineer Test Forum: https://www.test4sure.com/Professional-Machine-Learning-Engineer-pass4sure-vce.html
DOWNLOAD the newest Test4Sure Professional-Machine-Learning-Engineer PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1oLbpsvzqBTyQtqJ71AHEvz0AKwD3_MGu