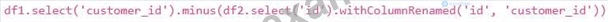SPS-C01試験復習赤本 & SPS-C01試験攻略

P.S. TopexamがGoogle Driveで共有している無料かつ新しいSPS-C01ダンプ:https://drive.google.com/open?id=18JLK1Y7AA-WsMSIejYwWOIRWuVWfeuLh
高賃金の仕事には、優れた労働能力と深い知識が必要です。 SPS-C01試験に合格すると、夢の仕事を見つけるのに役立ちます。最高のSPS-C01質問トレントをクライアントに提供します。Snowflake受験者がSPS-C01試験に簡単に合格できることを目指しています。私たちが提供するSPS-C01学習教材は合格率とヒット率を高めるためのものです。準備と確認に少し時間をかけるだけで、SPS-C01試験に合格できます。時間と労力はほとんどかかりません。ソフトウェアを無料でダウンロードして、購入する前に試用できます。
Snowflake SPS-C01 Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|
| Performance Optimization and Best Practices | 20% | - Minimizing data transfer
- Caching strategies
- Vectorized UDFs
- Query pushdown and optimization
- Debugging and explain plans
- Warehouse sizing for Snowpark
|
| Snowpark Concepts | 15% | - Snowpark DataFrames and query plans
- Stored procedures and conditional logic
- Transformations vs. Actions
- Snowpark Sessions and connection management
- Client-side vs. Server-side execution
- Snowpark architecture and core concepts
|
| Snowpark API for Python | 30% | - Working with Semi-structured data
- Establishing connections and session management
- DataFrame creation and manipulation
- Reading and writing data
- User-Defined Functions (UDFs) and Stored Procedures
|
| Data Transformations and DataFrame Operations | 35% | - Window functions
- Using built-in functions
- Complex data pipelines
- Persisting transformed data
- Filtering, Aggregating, and Joining DataFrames
|
>> SPS-C01試験復習赤本 <<
試験の準備方法-真実的なSPS-C01試験復習赤本試験-効果的なSPS-C01試験攻略
SPS-C01のSnowflake試験問題の高い合格率は98%〜100%であるため、正確かつ最新のSPS-C01試験トレントで市場に並ぶものがないと誇らしげに主張できます。 成功をもたらす当社の強みと、取得する意図のある認定を疑うことはありません。 SPS-C01実践教材を使用して、候補者の勝利をますます証明しています。Topexam あなたは彼らのような勝者の一人になると信じています。 Snowflake Certified SnowPro Specialty - SnowparkのSPS-C01学習教材を購入するだけで、より明るい未来を手にすることができます。
Snowflake Certified SnowPro Specialty - Snowpark 認定 SPS-C01 試験問題 (Q278-Q283):
質問 # 278
You have a Snowpark DataFrame 'df with a column 'transaction_date' of STRING type, containing dates in 'YYYY-MM-DD' format, and a 'transaction_amount' column of STRING type, containing currency values like '$1 ,234.56'. You need to create a new DataFrame 'df_transformed' that contains the 'transaction_date' as a DATE type and 'transaction_amount' as a DOUBLE type. What Snowpark Python code snippet will accomplish this transformation most efficiently and handle potential errors during the cast?
- A. ...python from snowflake.snowpark.functions import try_to_date, try_to_double df_transformed = df.with_column('transaction_date', try_to_date(col('transaction_date'))).with_column('transaction_amount', try_to_double(regexp_replace(col('transaction_amount'), '[$,]', ")))
- B. ...python df_transformed = df.select(to_date(col('transaction_date')).alias('transaction_date'), to_double(col('transaction_amount')).alias('transaction_amount'))
- C. ...python import snowflake.snowpark.functions as sf df_transformed = df.with_column('transaction_date', sf.to_date(sf.col('transaction_date'), format='YYYY- MM-DD')).with_column('transaction_amount', sf.to_double(sf.regexp_replace(sf.col('transaction_amount'), '[$,]', ")
- D. ...python df_transformed = df.with_column('transaction_date', to_date(col('transaction_date'))).with_column('transaction_amount', to_double(col('transaction_amount').replace('$',").replace(',',")))
- E. ...python df_transformed = df.with_column('transaction_date', to_date(col('transaction_date') YYYY-MM-DD')).with_column('transaction_amount', col('transaction_amount').cast(DoubleType()))
正解:A
解説:
Option C is the most robust because it uses and , which handle potential conversion errors by returning NULL instead of throwing exceptions. It also correctly uses 'regexp_replace' to remove both '$ and ',' from the 'transaction_amount' string before casting. Option A doesn't handle the format string for 'to_date' or special characters in amount. Option B doesnt remove special charcaters from transaction amount.Option D will not return other existing Columns, and also it doesn't handle the format string for 'to_date' or special characters in amount. Option E will not handle errors gracefully and redundantly imports 'snowflake.snowpark.functions as sf, and it also requires providing a format string for 'to_date' .
質問 # 279
You have two Snowpark DataFrames, 'dfl' and 'df2 , both containing customer data, but with slightly different schemas. 'dfl' has columns 'customer_id', 'name', and 'email'. 'df2' has columns 'id', 'customer name', and 'email_address'. You want to perform a set- based operation to find all unique customer IDs present in 'dfl but NOT in 'df2' , considering that 'customer_id' in 'dfl corresponds to 'id' in 'df2. Which of the following code snippets will achieve this, ensuring that column names are correctly aligned before the operation?
正解:D
解説:
Option D is the correct solution. First, 'customer_id')' renames the 'id' column in 'df2 to 'customer_id', aligning it with the 'customer_id' column in 'dfl Then, 'cifl performs the set difference operation, returning only the 'customer_id' values present in 'dfl& but not in the modified 'df2. 'exceptAll' (Option A) will include duplicates. Option B uses 'minus' which does not exist on Snowpark DataFrame. Options C uses 'subtract which also does not exist. Option E will cause unexpected results because the column name of dfl and df2 would be different.
質問 # 280
You need to create a Snowpark DataFrame using a SQL query. The query requires a user-defined variable (e.g., a date for filtering records). What are the correct and recommended ways to safely pass this variable into the SQL query when creating the DataFrame using 'session.sql()' to prevent SQL injection vulnerabilities?
正解:C、E
解説:
Options C and E are the safest and recommended approaches. Option C, if supported by your Snowpark version, uses parameterized SQL queries, which are the best way to prevent SQL injection. Option E avoids injecting the variable into the SQL string at all by filtering in Snowpark after the DataFrame is created. Options A and B are highly vulnerable to SQL injection. Option D is better than A and B, but still less secure and more complex than using parameterized queries or filtering with the DataFrame API.
質問 # 281
You are using VS Code with the Snowflake extension to develop a Snowpark application. You have successfully connected to your Snowflake account and are writing a script that creates a stage and then loads data from a local file into a Snowflake table using Snowpark. However, you're encountering issues with file paths and permission errors. Which of the following strategies would best address these challenges and ensure your Snowpark application can reliably load data from local files?
- A. Use VS Code's remote development feature to run your Snowpark code directly on the Snowflake compute nodes. This will eliminate file path issues.
- B. Utilize Snowpark's 'session.file.put' to upload the local file to an internal or external stage. Then, use 'session.table.copy_into' to load data from the stage into the target table.
- C. Leverage a network share and mount it as a drive in both your local development environment and the Snowflake environment. Then, use relative file paths in your Snowpark code.
- D. Modify the Snowflake account-level parameters to allow direct access to the local file system. Use relative file paths to access the local file.
- E. Use absolute file paths in your Snowpark code when referring to local files. Ensure the Snowflake service account has read access to the local file system.
正解:B
解説:
Option B is the most secure and recommended approach. Snowflake's security model restricts direct access to local file systems. Using 'session.file.put' uploads the file to a Snowflake-managed stage (either internal or external), ensuring data is transferred securely and access is controlled within the Snowflake environment. Then, 'copy_into' safely loads the staged data into the table. The other options are problematic for these reasons: Option A is incorrect because Snowflake does not directly access the local file system for security reasons. Option C is overly complex and introduces external dependencies that can be difficult to manage and secure. Option D is incorrect as Snowflake does not allow modifications to account-level parameters to grant direct local file system access. This would be a major security risk. Option E is incorrect. VS Code's remote development is for connecting to remote servers; it cannot run code on Snowflake compute nodes.
質問 # 282
You are developing a Snowpark application to ingest a large dataset into Snowflake. You have a DataFrame with a schema that matches the target table 'TARGET TABLE. Due to network constraints, you need to optimize the insertion process to minimize the number of API calls. Which of the following approaches would provide the MOST efficient way to insert the data?
- A. Directly use the method, without any intermediate transformations.
- B. Stage 'data_df to an internal stage, then load the data from stage to the table using COPY INTO command.
- C. Load the DataFrame into chunks of 1000 records into target table by using insert_into() function iteratively
- D. Iterate through the rows of 'data_df , constructing and executing a separate INSERT statement for each row using 'session.sql()'.
- E. Convert 'data_df to a Pandas DataFrame using and then use to insert the data.
正解:A
解説:
The most efficient approach is option C: 'data_df.insert_into('TARGET_TABLE')'. This method leverages Snowpark's optimized data transfer mechanisms and performs bulk insertion using the underlying Snowflake engine which minimizes api calls and faster to insert the data. Option A is highly inefficient due to the overhead of constructing and executing individual SQL statements. Option B introduces Pandas, which is slower. Option D involves additional staging steps. Option E is manual chunking which is also slower.
質問 # 283
......
私たちのSPS-C01研究ブレーンダンプは、この点でユーザーの需要を満たすのに非常に優れている可能性があり、ユーザーが学習したことを継続的に統合する良い環境で読み書きできるようにします。 SPS-C01準備ガイドは高品質です。当社のウェブサイトのSPS-C01学習クイズバンクおよび教材は、選択したトピックに基づいて最新の質問と回答を検索します。 この選択は、あなたのキャリア全体の突破口となるので、SPS-C01スタディガイドの高い品質と正確性に驚かされるでしょう。
SPS-C01試験攻略: https://www.topexam.jp/SPS-C01_shiken.html
- SPS-C01科目対策 🍇 SPS-C01受験内容 💎 SPS-C01科目対策 ☑ ➥ jp.fast2test.com 🡄を開き、➤ SPS-C01 ⮘を入力して、無料でダウンロードしてくださいSPS-C01合格体験談
- SPS-C01資格トレーニング ❣ SPS-C01試験情報 🤐 SPS-C01無料模擬試験 🔟 Open Webサイト➡ www.goshiken.com ️⬅️検索“ SPS-C01 ”無料ダウンロードSPS-C01資格トレーニング
- SPS-C01模擬解説集 💹 SPS-C01合格内容 🦊 SPS-C01資格認証攻略 🚂 URL 「 www.jpexam.com 」をコピーして開き、⮆ SPS-C01 ⮄を検索して無料でダウンロードしてくださいSPS-C01模擬モード
- SPS-C01試験の準備方法|素敵なSPS-C01試験復習赤本試験|便利なSnowflake Certified SnowPro Specialty - Snowpark試験攻略 🛐 ☀ www.goshiken.com ️☀️の無料ダウンロード▛ SPS-C01 ▟ページが開きますSPS-C01過去問無料
- SPS-C01試験復習赤本を見ると,Snowflake Certified SnowPro Specialty - Snowparkの半分に合格する 🌃 今すぐ▛ www.passtest.jp ▟で【 SPS-C01 】を検索し、無料でダウンロードしてくださいSPS-C01試験内容
- SPS-C01試験の準備方法|高品質なSPS-C01試験復習赤本試験|完璧なSnowflake Certified SnowPro Specialty - Snowpark試験攻略 🍃 ☀ www.goshiken.com ️☀️の無料ダウンロード▶ SPS-C01 ◀ページが開きますSPS-C01合格内容
- 信頼的なSPS-C01試験復習赤本 - 合格スムーズSPS-C01試験攻略 | 最高のSPS-C01日本語対策問題集 📊 今すぐ▷ www.xhs1991.com ◁で➥ SPS-C01 🡄を検索し、無料でダウンロードしてくださいSPS-C01資格トレーニング
- SPS-C01試験の準備方法|素敵なSPS-C01試験復習赤本試験|便利なSnowflake Certified SnowPro Specialty - Snowpark試験攻略 🍰 ウェブサイト【 www.goshiken.com 】から【 SPS-C01 】を開いて検索し、無料でダウンロードしてくださいSPS-C01合格率
- ユニークなSPS-C01試験復習赤本試験-試験の準備方法-素晴らしいSPS-C01試験攻略 ⛴ ⏩ www.jpshiken.com ⏪サイトにて最新⏩ SPS-C01 ⏪問題集をダウンロードSPS-C01試験情報
- 有難いSPS-C01試験復習赤本 - 合格スムーズSPS-C01試験攻略 | 素敵なSPS-C01日本語対策問題集 🪐 ➠ www.goshiken.com 🠰は、➽ SPS-C01 🢪を無料でダウンロードするのに最適なサイトですSPS-C01資格問題集
- Snowflake SPS-C01試験復習赤本: Snowflake Certified SnowPro Specialty - Snowpark - www.goshiken.com テストエンジンシミュレーション 🌠 ▶ www.goshiken.com ◀にて限定無料の☀ SPS-C01 ️☀️問題集をダウンロードせよSPS-C01資格認証攻略
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
P.S.TopexamがGoogle Driveで共有している無料の2026 Snowflake SPS-C01ダンプ:https://drive.google.com/open?id=18JLK1Y7AA-WsMSIejYwWOIRWuVWfeuLh