NewDumps的AI-500資料不僅能讓你通過考試,還可以讓你學到關於AI-500考試的很多知識。NewDumps的考古題把你應該要掌握的技能全都包含在試題中,這樣你就可以很好地提高自己的能力,並且在工作中更好地應用它們。NewDumps的AI-500考古題絕對是你準備考試並提高自己技能的最好的選擇。你要相信NewDumps可以給你一個美好的未來。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Architect multi-agent solutions | 15-20% | - Design logical architecture for multi-agent solutions
|
| Topic 2: Secure, govern, and deploy multi-agent solutions | 20-25% | - Design and implement guardrails
|
| Topic 3: Develop multi-agent solutions in Azure | 30-35% | - Build and integrate tool ecosystems
|
| Topic 4: Evaluate, optimize, and monitor multi-agent solutions | 20-25% | - Evaluate solution quality
|
在這個網路盛行的時代,有很多的方式方法以備你的Microsoft的AI-500認證考試,NewDumps提供了最可靠的培訓的試題及答案,以備你順利通過Microsoft的AI-500認證考試,我們NewDumps的Microsoft的AI-500考試認證有很多種,我們將滿足你所有有關IT認證。
問題 #34
You have a Microsoft Foundry multi-agent solution. The agents contain the CI/CD evaluation gates shown in the following table.
You call one of the agents by using the request context in the evaluation process as shown in the following table.
The agent receives the following results for the tool.
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.
答案:
解題說明:
Explanation:
SchemaGate: Yes; RelevanceGate: Yes; CompletenessGate: No.
The supplied tool result satisfies the structural requirements of SchemaGate: it includes a valid-looking UUID result identifier, a string sourceTool value, an items array, and the required fields on the item. RelevanceGate also passes because the request category is VPN, the returned item category is VPN, and its confidence value of 0.87 is above the required 0.80 threshold. CompletenessGate fails because the rule requires at least two items while the response contains only one. This is a deterministic gate evaluation rather than an LLM-judge interpretation, so the values should be checked directly against the declared criteria. Microsoft Foundry evaluation datasets and CI/CD quality gates are designed to make exactly these regression checks repeatable before release. Therefore the correct sequence is Yes, Yes, No. The evaluation should also preserve correlation identifiers and version information where possible so a failed score can be traced back to the exact agent, model, tool call, or retrieval step that produced it. This turns the metric into an actionable diagnostic rather than only a dashboard number.
Official Microsoft reference: Microsoft Foundry - evaluation datasets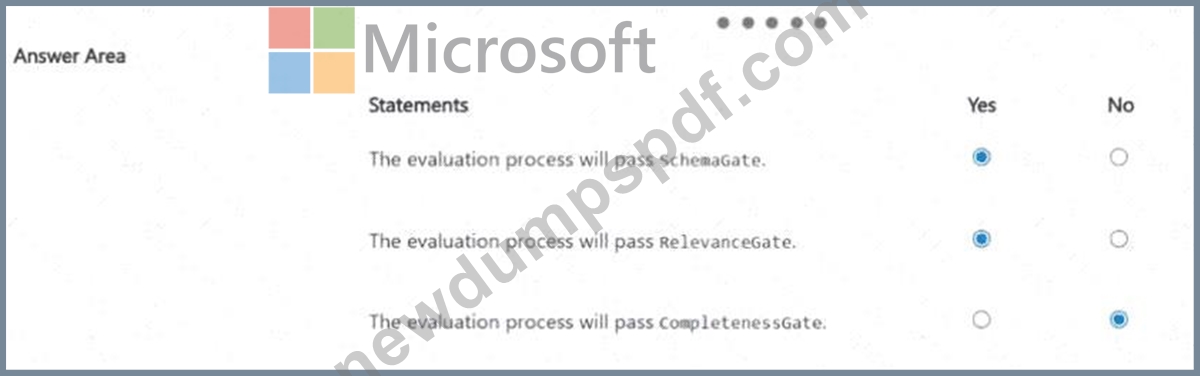
問題 #35
You have a Microsoft Foundry project that contains a multi-agent customer support solution. The solution includes a final response agent.
You need to provide reviewers with the ability to assess agent responses in the preview web app and record a completion score for each agent response. The solution must follow the principle of least privilege.
Which roles should you assign to the reviewers?
答案:D
解題說明:
Microsoft ' s human-evaluation guidance for the Foundry preview web app requires reviewers to have Foundry User permissions on the project plus Reader access on the Foundry account/resource. That combination gives the reviewer enough project-level access to open the agent experience and record evaluation feedback while avoiding project-management or account-management privileges. Application Insights Reader alone only grants telemetry visibility and does not provide the Foundry interaction permissions needed to score responses. Foundry User alone does not satisfy the documented account-level visibility requirement for this preview experience. Foundry Project Manager would be broader than necessary and violate the least-privilege objective. Therefore C is the documented reviewer role combination. The same configuration should be paired with auditable identity, trace, and evaluation data so reviewers can prove which principal acted, which policy was applied, and why a request was allowed or blocked. That is particularly important for production multi-agent systems with external tools. Least privilege remains the governing principle: grant only the identity, data, tool, or deployment access required for the specific operation. The selected answer preserves that boundary while still allowing the workflow to satisfy its functional requirement.
Official Microsoft reference: Microsoft Foundry - Human evaluation
問題 #36
Solution: Use separate a managed identity for each agent and environment Assign Azure roles at the resource level. Does this meet the goal?
答案:B
解題說明:
Separate managed identities for each agent and environment remove the need to store application secrets and create independent authorization boundaries. Assigning Azure roles at the resource level further limits each identity to only the Storage resource it requires. This sharply reduces lateral movement compared with a shared application principal or subscription-wide role. Microsoft Foundry and Azure identity guidance consistently recommend identity-based authentication, distinct identities when permissions differ, and the narrowest practical RBAC scope. In current Foundry deployments, the exact identity object may be represented through Microsoft Entra agent identity or a federated managed identity relationship, but the architectural principle in the option is correct. Therefore the solution meets both stated goals and the answer is A, Yes. From a security and governance perspective, the control should be enforced at the narrowest platform boundary that can deterministically block or constrain the action. Relying only on prompt text is weaker because the model can still be induced to behave unexpectedly.
Official Microsoft reference: Microsoft Foundry agent identity
問題 #37
You are validating the outcome of the consultant proposal for the Patient Intake agent.
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.
答案:
解題說明:
Explanation:
No / No / No
All three consultant-proposal statements should be rejected. Applying the highest sensitivity to every guardrail control is not automatically safer because it can increase false positives and unnecessarily block legitimate clinical interactions; controls should be tuned to the actual risk and tested. Telling the model in a system prompt to ignore hate speech is not equivalent to enabling the platform content-safety controls required for public-facing agents. Finally, repeatedly prompting patients to verify symptoms does not address long-context growth and can worsen token usage and latency. Microsoft guidance separates deterministic safety controls, evaluation, and context-management mechanisms from ordinary prompt instructions. The proposal also hardcodes medical behavior in prompts, contrary to the requirement to avoid embedding new clinical logic in the core prompt. A robust design would use appropriate content-safety/guardrail controls, validated intervention points, and a deliberate memory/compaction strategy rather than relying on increasingly restrictive or repetitive prompt text. The same configuration should be paired with auditable identity, trace, and evaluation data so reviewers can prove which principal acted, which policy was applied, and why a request was allowed or blocked. That is particularly important for production multi-agent systems with external tools.
Official Microsoft reference: AI-500 Study Guide - guardrails, context management, and evaluation
問題 #38
You have a Microsoft Agent Framework multi-agent workflow. The workflow includes a context provider that injects a condensed memory summary into each agent invocation. Requirements and acceptance criteria are stored in GitHub issues.
During a long-running workflow, the acceptance criteria changes. Later agents sometimes apply the earlier criteria. Token telemetry shows condensed summaries grow across handoffs. causing older content to be truncated.
You need to ensure that the later agents use the current requirements. The solution must limit context window growth.
What should you do?
答案:C
解題說明:
GitHub issues are the authoritative source for current requirements, and those requirements can change while a long-running workflow is still executing. Each handoff should therefore reconstruct context from the current issue state and discard memory that has been invalidated by newer requirements. Keeping an accumulated summary allows obsolete criteria to remain present and also causes the prompt to grow until older content is truncated. Persisting the transcript in Cosmos DB preserves history but does not make that history current.
Giving subagents a GitHub lookup tool while continuing to inject the stale summary can expose the model to conflicting versions of the same requirement. Microsoft Agent Framework context providers are intended to inject current external context at invocation time, making C the approach that simultaneously preserves freshness and bounds context growth. In production, add telemetry and regression tests around this behavior so changes to prompts, models, tools, or orchestration do not silently alter the intended contract. The selected approach is the one that best matches the platform ' s native execution semantics.
Official Microsoft reference: Microsoft Agent Framework - Context providers
問題 #39
......
通過 Microsoft的AI-500的考試認證不僅僅是驗證你的技能,但也證明你的專業知識和你的證書,你的老闆沒有白白雇傭你,目前的IT行業需要一個可靠的 Microsoft的AI-500的考試的來源,NewDumps是個很好的選擇,AI-500的考試縮短在最短的時間內,這樣不會浪費你的錢和精力。還會讓你又一個美好的前程。
最新AI-500題庫: https://www.newdumpspdf.com/AI-500-exam-new-dumps.html