Pass Guaranteed Databricks-Certified-Data-Engineer-Professional - Fantastic Databricks Certified Data Engineer Professional Exam Answers Free

We would like to provide our customers with different kinds of Databricks-Certified-Data-Engineer-Professional practice guide to learn, and help them accumulate knowledge and enhance their ability. Besides, we guarantee that the Databricks-Certified-Data-Engineer-Professional exam questions of all our users can be answered by professional personal in the shortest time with our Databricks-Certified-Data-Engineer-Professional Study Dumps. One more to mention, we can help you make full use of your sporadic time to absorb knowledge and information.
| Section | Weight | Objectives |
|---|
| Data Governance | 7% | - Manage data assets and metadata
- Enforce data policies and standards
- Use Unity Catalog for governance
|
| Data Modelling | 6% | - Optimize table design and partitioning
- Design Medallion Architecture
- Implement dimensional and relational models
|
| Data Ingestion & Acquisition | 7% | - Use Auto Loader and structured streaming
- Ingest data from diverse sources
- Handle incremental and batch data loads
|
| Ensuring Data Security and Compliance | 10% | - Ensure data privacy and compliance
- Implement access control and permissions
- Secure data at rest and in transit
|
| Monitoring and Alerting | 10% | - Set up alerts and notifications
- Monitor pipeline performance and health
- Track data lineage and metrics
|
| Debugging and Deploying | 10% | - Deploy using Asset Bundles, CLI, and APIs
- Implement CI/CD and DevOps practices
- Troubleshoot and debug pipelines
|
| Cost & Performance Optimisation | 13% | - Apply cost management best practices
- Improve query and pipeline performance
- Optimize compute and storage resources
|
| Data Sharing and Federation | 5% | - Manage cross-platform data access
- Implement Lakehouse Federation
- Use Delta Sharing for secure data sharing
|
| Developing Code for Data Processing using Python and SQL | 22% | - Write efficient and maintainable code
- Implement complex data processing logic
- Use Databricks-specific libraries and APIs
|
| Data Transformation, Cleansing, and Quality | 10% | - Implement schema evolution and management
- Apply data cleansing and validation rules
- Enforce data quality standards
|
>> Databricks-Certified-Data-Engineer-Professional Answers Free <<
Exam Databricks Databricks-Certified-Data-Engineer-Professional Cram, Databricks-Certified-Data-Engineer-Professional Latest Exam Question
So for this reason, our Databricks Databricks-Certified-Data-Engineer-Professional are very similar to the actual exam. With a vast knowledge in this field, Lead2PassExam always tries to provide candidates with the actual questions so that when they appear in their real Databricks Databricks-Certified-Data-Engineer-Professional Exam they do not feel any difference. The Desktop Databricks Databricks-Certified-Data-Engineer-Professional Practice Exam Software of Lead2PassExam arranges a mock exam for the one who wants to evaluate and improve preparation.
Databricks Certified Data Engineer Professional Exam Sample Questions (Q22-Q27):
NEW QUESTION # 22
Each configuration below is identical to the extent that each cluster has 400 GB total of RAM, 160 total cores and only one Executor per VM.
Given a job with at least one wide transformation, which of the following cluster configurations will result in maximum performance?
- A. Total VMs: 1
400 GB per Executor
160 Cores / Executor - B. Total VMs: 8
50 GB per Executor
20 Cores / Executor - C. Total VMs: 4
100 GB per Executor
40 Cores/Executor - D. Total VMs: 2
200 GB per Executor
80 Cores / Executor
Answer: A
Explanation:
https://docs.databricks.com/en/clusters/cluster-config-best-practices.html
NEW QUESTION # 23
The downstream consumers of a Delta Lake table have been complaining about data quality issues impacting performance in their applications. Specifically, they have complained that invalid latitude and longitude values in the activity_details table have been breaking their ability to use other geolocation processes.
A junior engineer has written the following code to add CHECK constraints to the Delta Lake table:
A senior engineer has confirmed the above logic is correct and the valid ranges for latitude and longitude are provided, but the code fails when executed.
Which statement explains the cause of this failure?
- A. The activity details table already contains records; CHECK constraints can only be added prior to inserting values into a table.
- B. Because another team uses this table to support a frequently running application, two-phase locking is preventing the operation from committing.
- C. The current table schema does not contain the field valid coordinates; schema evolution will need to be enabled before altering the table to add a constraint.
- D. The activity details table already contains records that violate the constraints; all existing data must pass CHECK constraints in order to add them to an existing table.
- E. The activity details table already exists; CHECK constraints can only be added during initial table creation.
Answer: D
Explanation:
The failure is that the code to add CHECK constraints to the Delta Lake table fails when executed. The code uses ALTER TABLE ADD CONSTRAINT commands to add two CHECK constraints to a table named activity_details. The first constraint checks if the latitude value is between -90 and 90, and the second constraint checks if the longitude value is between -180 and
180. The cause of this failure is that the activity_details table already contains records that violate these constraints, meaning that they have invalid latitude or longitude values outside of these ranges. When adding CHECK constraints to an existing table, Delta Lake verifies that all existing data satisfies the constraints before adding them to the table. If any record violates the constraints, Delta Lake throws an exception and aborts the operation.
NEW QUESTION # 24
A CHECK constraint has been successfully added to the Delta table named activity_details using the following logic:
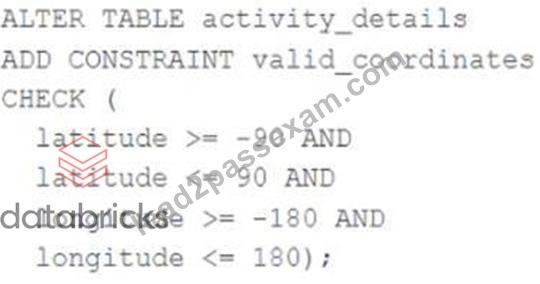
A batch job is attempting to insert new records to the table, including a record where latitude =
45.50 and longitude = 212.67.
Which statement describes the outcome of this batch insert?
- A. The write will fail completely because of the constraint violation and no records will be inserted into the target table.
- B. The write will insert all records except those that violate the table constraints; the violating records will be recorded to a quarantine table.
- C. The write will include all records in the target table; any violations will be indicated in the boolean column named valid_coordinates.
- D. The write will fail when the violating record is reached; any records previously processed will be recorded to the target table.
- E. The write will insert all records except those that violate the table constraints; the violating records will be reported in a warning log.
Answer: A
Explanation:
The CHECK constraint is used to ensure that the data inserted into the table meets the specified conditions. In this case, the CHECK constraint is used to ensure that the latitude and longitude values are within the specified range. If the data does not meet the specified conditions, the write operation will fail completely and no records will be inserted into the target table. This is because Delta Lake supports ACID transactions, which means that either all the data is written or none of it is written. Therefore, the batch insert will fail when it encounters a record that violates the constraint, and the target table will not be updated.
NEW QUESTION # 25
A security analytics pipeline must enrich billions of raw connection logs with geolocation data.
The join hinges on finding which IPv4 range each event's address falls into.
Table 1: network_events ( 5 billion rows)
event_id ip_int
42 3232235777
Table 2: ip_ranges ( 2 million rows)
start_ip_int end_ip_int country
3232235520 3232236031 US
The query is currently very slow:
SELECT n.event_id, n.ip_int, r.country
FROM network_events n
JOIN ip_ranges r
ON n.ip_int BETWEEN r.start_ip_int AND r.end_ip_int;
Which change will most dramatically accelerate the query while preserving its logic?
- A. Force a sort-merge join with /*+ MERGE(r) */.
- B. Add a range-join hint /*+ RANGE_JOIN(r, 65536) */.
- C. Increase spark.sql.shuffle.partitions from 200 to 10000.
- D. Add a broadcast hint: /*+ BROADCAST(r) */ for ip_ranges.
Answer: B
Explanation:
The query joins billions of rows (network_events) with millions of rows (ip_ranges) using a range predicate (BETWEEN). Unlike equality joins (=), range joins are not efficiently handled by broadcast or sort-merge joins because:
Broadcast Join (D): Effective for small tables but only for equality joins. Since this query uses a range condition, broadcast will not reduce the complexity of scanning billions of records across non-equality conditions.
Sort-Merge Join (C): Works for ordered joins but is inefficient on range conditions. Sorting billions of records adds excessive overhead and will not resolve the bottleneck.
Increasing Shuffle Partitions (A): Only spreads out shuffle work but does not address the fundamental inefficiency of range-based lookups at scale.
Range Joins in Spark (RANGE_JOIN hint):
Databricks provides range join optimizations specifically for conditions such as BETWEEN. By applying a RANGE_JOIN hint, Spark can build optimized data structures (such as interval indexes or partition pruning strategies) that map billions of input rows to ranges much faster. This avoids brute- force scans and unnecessary shuffle costs.
Thus, Option B is the correct solution because:
It leverages range-join optimization, which is purpose-built for queries joining massive event logs to smaller lookup tables with IP ranges.
This ensures Spark can evaluate billions of rows against millions of ranges with optimized matching logic, drastically improving query performance while preserving correctness.
NEW QUESTION # 26
A data engineer is tasked with ensuring that a Delta table in Databricks continuously retains deleted files for 15 days (instead of the default 7 days), in order to permanently comply with the organization's data retention policy. Which code snippet correctly sets this retention period for deleted files?
- A. spark.sql("ALTER TABLE my_table SET TBLPROPERTIES
('delta.deletedFileRetentionDuration' = 'interval 15 days')") - B. spark.conf.set("spark.databricks.delta.deletedFileRetentionDuration", "15 days")
- C. from delta.tables import *
deltaTable = DeltaTable.forPath(spark, "/mnt/data/my_table")
deltaTable.deletedFileRetentionDuration = "interval 15 days" - D. spark.sql("VACUUM my_table RETAIN 15 HOURS")
Answer: A
Explanation:
The deleted file retention period in Delta Lake is controlled by the table property delta.deletedFileRetentionDuration. Setting this property via ALTER TABLE ensures the retention policy is persistently enforced at the table level, extending deleted file retention to 15 days in compliance with organizational requirements.
NEW QUESTION # 27
......
For years our team has built a top-ranking brand with mighty and main which bears a high reputation both at home and abroad. The sales volume of the Databricks-Certified-Data-Engineer-Professional Study Materials we sell has far exceeded the same industry and favorable rate about our products is approximate to 100%. Why the clients speak highly of our Databricks-Certified-Data-Engineer-Professional study materials? Our dedicated service, high quality and passing rate and diversified functions contribute greatly to the high prestige of our products. We provide free trial service before the purchase, the consultation service online after the sale, free update service and the refund service in case the clients fail in the test.
Exam Databricks-Certified-Data-Engineer-Professional Cram: https://www.lead2passexam.com/Databricks/valid-Databricks-Certified-Data-Engineer-Professional-exam-dumps.html
- 100% Pass Quiz Databricks - Databricks-Certified-Data-Engineer-Professional - Authoritative Databricks Certified Data Engineer Professional Exam Answers Free 🕊 Search for ✔ Databricks-Certified-Data-Engineer-Professional ️✔️ on { www.examcollectionpass.com } immediately to obtain a free download 🧯Study Databricks-Certified-Data-Engineer-Professional Demo
- Databricks-Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional Exam Accurate Answers Free 💹 Download 《 Databricks-Certified-Data-Engineer-Professional 》 for free by simply entering ▶ www.pdfvce.com ◀ website 🐾Databricks-Certified-Data-Engineer-Professional Exam Price
- Databricks-Certified-Data-Engineer-Professional Answers Free | Latest Databricks Exam Databricks-Certified-Data-Engineer-Professional Cram: Databricks Certified Data Engineer Professional Exam 💥 Open website 《 www.prepawaypdf.com 》 and search for ⇛ Databricks-Certified-Data-Engineer-Professional ⇚ for free download 🌆New Databricks-Certified-Data-Engineer-Professional Exam Simulator
- Test Databricks-Certified-Data-Engineer-Professional Book 🧺 New Soft Databricks-Certified-Data-Engineer-Professional Simulations 🌉 Exam Databricks-Certified-Data-Engineer-Professional Registration 🙌 Search for ☀ Databricks-Certified-Data-Engineer-Professional ️☀️ and download exam materials for free through ( www.pdfvce.com ) 🔥Databricks-Certified-Data-Engineer-Professional Updated Test Cram
- Databricks-Certified-Data-Engineer-Professional Intereactive Testing Engine 🛢 Valid Databricks-Certified-Data-Engineer-Professional Study Notes 🧗 Exam Databricks-Certified-Data-Engineer-Professional Registration 🎤 Search for ⏩ Databricks-Certified-Data-Engineer-Professional ⏪ and easily obtain a free download on ⏩ www.prepawaypdf.com ⏪ ☂Exam Databricks-Certified-Data-Engineer-Professional Torrent
- New Databricks-Certified-Data-Engineer-Professional Exam Simulator 🙉 Databricks-Certified-Data-Engineer-Professional Reliable Exam Simulations 🐥 Exam Databricks-Certified-Data-Engineer-Professional Torrent 👓 The page for free download of ▷ Databricks-Certified-Data-Engineer-Professional ◁ on ➽ www.pdfvce.com 🢪 will open immediately 🟣Valid Databricks-Certified-Data-Engineer-Professional Study Notes
- Databricks-Certified-Data-Engineer-Professional Test Book 🖕 Databricks-Certified-Data-Engineer-Professional Intereactive Testing Engine ↔ Valid Databricks-Certified-Data-Engineer-Professional Study Notes 🛫 Download ➤ Databricks-Certified-Data-Engineer-Professional ⮘ for free by simply entering ▷ www.vceengine.com ◁ website 🛴New Soft Databricks-Certified-Data-Engineer-Professional Simulations
- 100% Pass Quiz 2026 Databricks Databricks-Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Exam Latest Answers Free 🍸 Open ▶ www.pdfvce.com ◀ enter [ Databricks-Certified-Data-Engineer-Professional ] and obtain a free download 🥰Standard Databricks-Certified-Data-Engineer-Professional Answers
- Valid Databricks-Certified-Data-Engineer-Professional Study Notes 🧎 New Databricks-Certified-Data-Engineer-Professional Braindumps Ebook 🔆 Latest Databricks-Certified-Data-Engineer-Professional Exam Fee 🧾 Copy URL { www.practicevce.com } open and search for 《 Databricks-Certified-Data-Engineer-Professional 》 to download for free 🟩Valid Databricks-Certified-Data-Engineer-Professional Study Notes
- Databricks-Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional Exam Accurate Answers Free 🧖 Go to website ➡ www.pdfvce.com ️⬅️ open and search for 《 Databricks-Certified-Data-Engineer-Professional 》 to download for free 🥂Exam Databricks-Certified-Data-Engineer-Professional Tutorial
- Latest Databricks-Certified-Data-Engineer-Professional Exam Fee 📱 Databricks-Certified-Data-Engineer-Professional Test Book 🧮 Databricks-Certified-Data-Engineer-Professional New Braindumps 😻 Simply search for ⏩ Databricks-Certified-Data-Engineer-Professional ⏪ for free download on ▷ www.exam4labs.com ◁ 📺Databricks-Certified-Data-Engineer-Professional Test Book
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes