2026 Latest DumpsActual DP-600 PDF Dumps and DP-600 Exam Engine Free Share: https://drive.google.com/open?id=18tcw0hMT4UnCjeRuj0Yo7kWDiKmZUtcM
In this high-speed world, a waste of time is equal to a waste of money. As an electronic product, our DP-600 real study dumps have the distinct advantage of fast delivery. Once our customers pay successfully, we will check about your email address and other information to avoid any error, and send you the DP-600 Prep Guide in 5-10 minutes, so you can get our DP-600 exam questions at first time. And then you can start your study after downloading the DP-600 exam questions in the email attachments.
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Implementing Analytics Solutions Using Microsoft Fabric |
| Exam Number: | DP-600 |
| Exam Price: | $165 USD (varies by country) |
| Exam Duration: | 120 minutes |
| Passing Score: | 700 (out of 1000) |
| Certificate Validity Period: | 1 year (renewable via Microsoft certification renewal) |
| Real Exam Qty: | 40-60 |
| Exam Format: | Drag and drop, Case studies, Multiple choice, Scenario-based questions |
| Related Certifications: | DP-900 PL-300 DP-203 |
| Available Languages: | Portuguese (Brazil), Korean, French, English, Japanese, Spanish, German, Simplified Chinese |
| Recommended Training: | DP-600 Learning Path (Microsoft Learn) Microsoft Fabric Documentation |
| Exam Registration: | Pearson VUE Microsoft Exams Microsoft Certification Dashboard |
| Sample Questions: | Microsoft DP-600 Sample Questions |
| Exam Way: | Online proctored exam or in-person at Pearson VUE test centers |
| Pre Condition: | No formal prerequisites required, but familiarity with data analytics, Power BI, and Azure data services is recommended. |
| Official Syllabus URL: | https://learn.microsoft.com/credentials/certifications/fabric-analytics-engineer/ |
It is known to us that passing the DP-600 exam is very difficult for a lot of people. Choosing the correct study materials is so important that all people have to pay more attention to the study materials. If you have any difficulty in choosing the correct DP-600 study braindumps, here comes a piece of good news for you. The DP-600 prep guide designed by a lot of experts and professors from company are very useful for all people to pass the practice exam and help them get the Microsoft certification in the shortest time. If you are preparing for the practice exam, we can make sure that the DP-600 Test Practice files from our company will be the best choice for you, and you cannot find the better study materials than our company’.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
NEW QUESTION # 97
You need to implement the date dimension in the data store. The solution must meet the technical requirements.
What are two ways to achieve the goal? Each correct answer presents a complete solution.
NOTE: Each correct selection is worth one point.
Answer: A,C
Explanation:
Both a dataflow (A) and a Stored procedure activity in a pipeline (B) are capable of creating and populating a date dimension table. A dataflow can perform the transformation needed to create the date dimension, and it aligns with the preference for using low-code tools for data ingestion when possible. A Stored procedure could be written to generate the necessary date dimension data and executed within a pipeline, which also adheres to the technical requirements for the PoC.
Topic 1, Litware. Inc. Case Study
Overview
Litware. Inc. is a manufacturing company that has offices throughout North America. The analytics team at Litware contains data engineers, analytics engineers, data analysts, and data scientists.
Existing Environment
litware has been using a Microsoft Power Bl tenant for three years. Litware has NOT enabled any Fabric capacities and features.
Fabric Environment
Litware has data that must be analyzed as shown in the following table.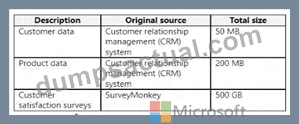
The Product data contains a single table and the following columns.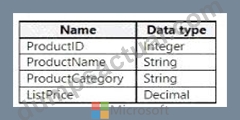
The customer satisfaction data contains the following tables:
* Survey
* Question
* Response
For each survey submitted, the following occurs:
* One row is added to the Survey table.
* One row is added to the Response table for each question in the survey.
The Question table contains the text of each survey question. The third question in each survey response is an overall satisfaction score. Customers can submit a survey after each purchase.
User Problems
The analytics team has large volumes of data, some of which is semi-structured. The team wants to use Fabric to create a new data store.
Product data is often classified into three pricing groups: high, medium, and low. This logic is implemented in several databases and semantic models, but the logic does NOT always match across implementations.
Planned Changes
Litware plans to enable Fabric features in the existing tenant. The analytics team will create a new data store as a proof of concept (PoC). The remaining Litware users will only get access to the Fabric features once the PoC is complete. The PoC will be completed by using a Fabric trial capacity.
The following three workspaces will be created:
* AnalyticsPOC: Will contain the data store, semantic models, reports, pipelines, dataflows, and notebooks used to populate the data store
* DataEngPOC: Will contain all the pipelines, dataflows, and notebooks used to populate Onelake
* DataSciPOC: Will contain all the notebooks and reports created by the data scientists The following will be created in the AnalyticsPOC workspace:
* A data store (type to be decided)
* A custom semantic model
* A default semantic model
* Interactive reports
The data engineers will create data pipelines to load data to OneLake either hourly or daily depending on the data source. The analytics engineers will create processes to ingest transform, and load the data to the data store in the AnalyticsPOC workspace daily. Whenever possible, the data engineers will use low-code tools for data ingestion. The choice of which data cleansing and transformation tools to use will be at the data engineers ' discretion.
All the semantic models and reports in the Analytics POC workspace will use the data store as the sole data source.
Technical Requirements
The data store must support the following:
* Read access by using T-SQL or Python
* Semi-structured and unstructured data
* Row-level security (RLS) for users executing T-SQL queries
Files loaded by the data engineers to OneLake will be stored in the Parquet format and will meet Delta Lake specifications.
Data will be loaded without transformation in one area of the AnalyticsPOC data store. The data will then be cleansed, merged, and transformed into a dimensional model.
The data load process must ensure that the raw and cleansed data is updated completely before populating the dimensional model.
The dimensional model must contain a date dimension. There is no existing data source for the date dimension. The Litware fiscal year matches the calendar year. The date dimension must always contain dates from 2010 through the end of the current year.
The product pricing group logic must be maintained by the analytics engineers in a single location. The pricing group data must be made available in the data store for T-SQL queries and in the default semantic model. The following logic must be used:
* List prices that are less than or equal to 50 are in the low pricing group.
* List prices that are greater than 50 and less than or equal to 1,000 are in the medium pricing group.
* List pnces that are greater than 1,000 are in the high pricing group.
Security Requirements
Only Fabric administrators and the analytics team must be able to see the Fabric items created as part of the PoC. Litware identifies the following security requirements for the Fabric items in the AnalyticsPOC workspace:
* Fabric administrators will be the workspace administrators.
* The data engineers must be able to read from and write to the data store. No access must be granted to datasets or reports.
* The analytics engineers must be able to read from, write to, and create schemas in the data store. They also must be able to create and share semantic models with the data analysts and view and modify all reports in the workspace.
* The data scientists must be able to read from the data store, but not write to it. They will access the data by using a Spark notebook.
* The data analysts must have read access to only the dimensional model objects in the data store. They also must have access to create Power Bl reports by using the semantic models created by the analytics engineers.
* The date dimension must be available to all users of the data store.
* The principle of least privilege must be followed.
Both the default and custom semantic models must include only tables or views from the dimensional model in the data store. Litware already has the following Microsoft Entra security groups:
* FabricAdmins: Fabric administrators
* AnalyticsTeam: All the members of the analytics team
* DataAnalysts: The data analysts on the analytics team
* DataScientists: The data scientists on the analytics team
* Data Engineers: The data engineers on the analytics team
* Analytics Engineers: The analytics engineers on the analytics team
Report Requirements
The data analysis must create a customer satisfaction report that meets the following requirements:
* Enables a user to select a product to filter customer survey responses to only those who have purchased that product
* Displays the average overall satisfaction score of all the surveys submitted during the last 12 months up to a selected date
* Shows data as soon as the data is updated in the data store
* Ensures that the report and the semantic model only contain data from the current and previous year
* Ensures that the report respects any table-level security specified in the source data store
* Minimizes the execution time of report queries
NEW QUESTION # 98
You have a Fabric tenant that contains a lakehouse named LH1 and a notebook.
You have a Parquet file named invoice1 that contains a column named InvoiceDateKey of the timestamp data type.
You need to create a PySpark script that will import invoice1 and create a table named fact_sale in LH1. The solution must meet the following requirements:
* A new column named Year must be added to fact_sale.
* The values in Year must use the InvoiceDateKey column.
How should you complete the script? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.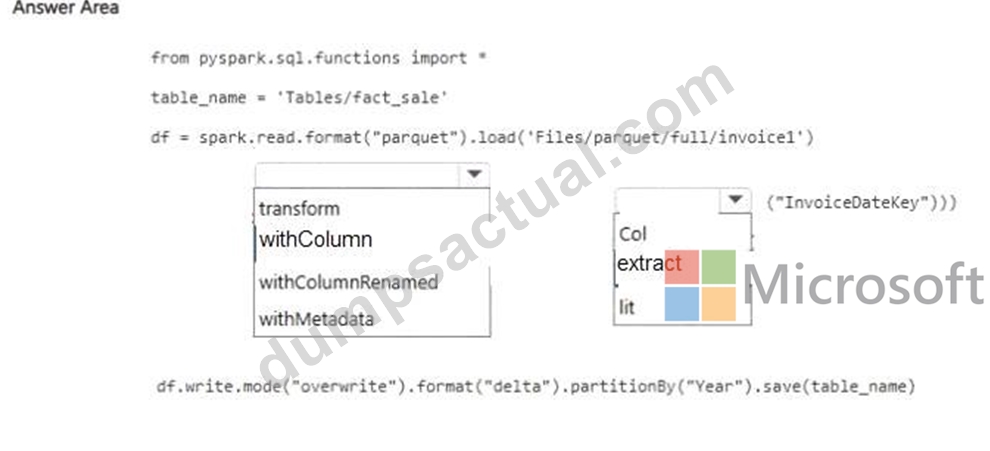
Answer:
Explanation: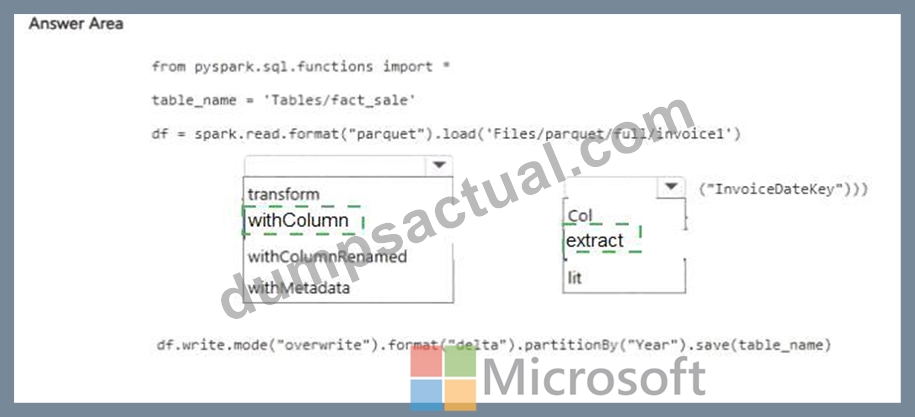
Explanation: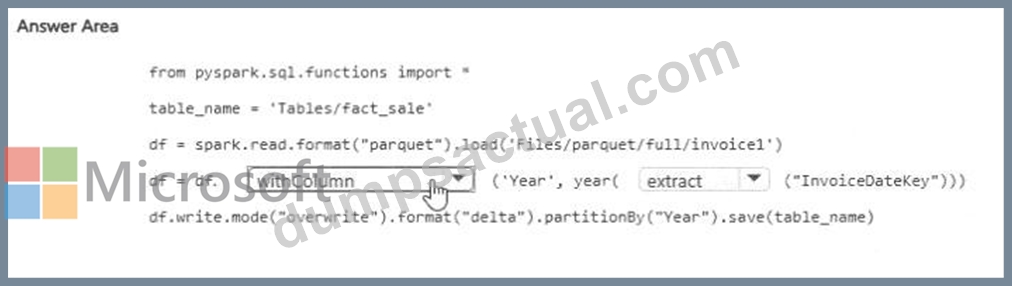
NEW QUESTION # 99
You have a Fabric tenant that contains a semantic model. The model contains data about retail stores.
You need to write a DAX query that will be executed by using the XMLA endpoint. The query must return the total amount of sales from the same period last year.
How should you complete the DAX expression? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.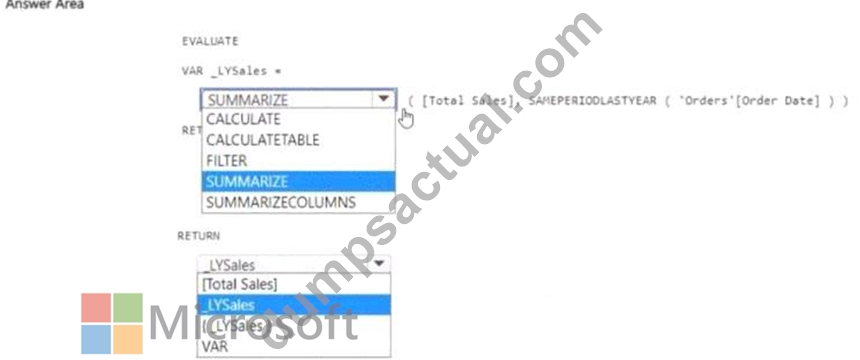
Answer:
Explanation: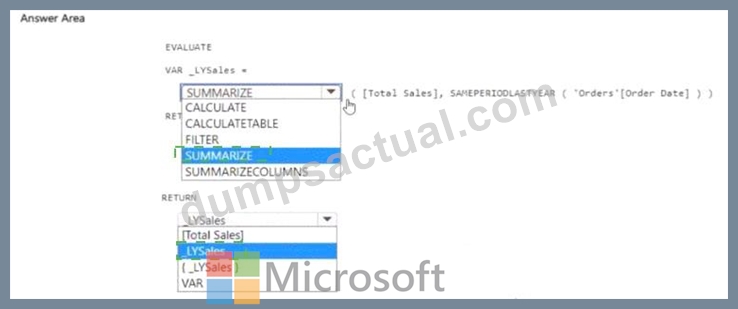
Explanation: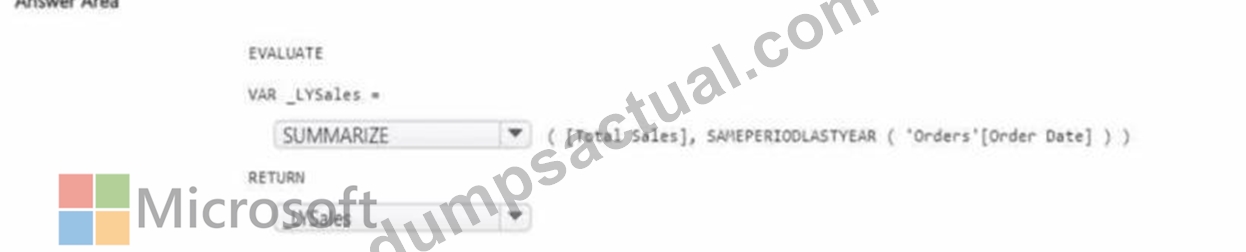
NEW QUESTION # 100
You have a Fabric workspace named Workspace1 and a user named User1.
You need to ensure that User1 can perform the following tasks in Workspace1:
- Create dashboards.
- Publish semantic models.
- Create and publish reports.
The solution must follow the principle of least privilege.
Which workspace role should you assign to User1?
Answer: B
Explanation:
The most appropriate role for this user is the Contributor role.
In Microsoft Fabric, workspace roles are hierarchical. The Contributor role provides the exact balance of creation and publishing permissions without granting the administrative overhead or broad sharing powers found in higher roles.
The Contributor role is specifically designed for data creators. It allows the user to perform all requested tasks while maintaining "least privilege" by restricting administrative control.
Included Permissions
Create and Publish: Users can upload or create semantic models, reports, and dashboards.
Edit Content: They can modify existing items within the workspace they have access to.
Interact with Fabric items: They can create, read, update, and delete items like Data Pipelines, Notebooks, and Lakehouses.
Reference:
https://www.linkedin.com/pulse/practical-guide-choosing-right-role-microsoft-fabric-oussama- haimoud-c8kte
NEW QUESTION # 101
You are implementing two dimension tables named Customers and Products in a Fabric warehouse.
You need to use slowly changing dimension (SCO) to manage the versioning of dat a. The solution must meet the requirements shown in the following table.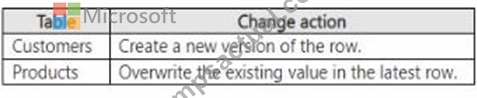
Which type of SCD should you use for each table? To answer, drag the appropriate SCD types to the correct tables. Each SCD type may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.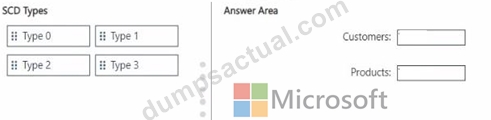
Answer:
Explanation: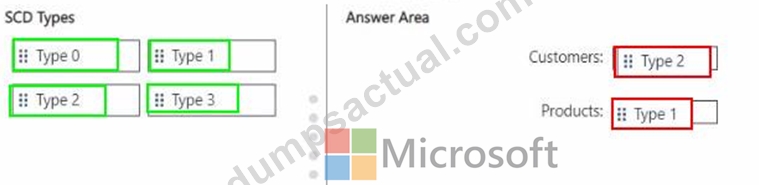
NEW QUESTION # 102
......
DP-600 Regualer Update: https://www.dumpsactual.com/DP-600-actualtests-dumps.html
What's more, part of that DumpsActual DP-600 dumps now are free: https://drive.google.com/open?id=18tcw0hMT4UnCjeRuj0Yo7kWDiKmZUtcM