Our AI-300 exam questions are compiled by experts and approved by authorized personnel and boost varied function so that you can learn AI-300 test torrent conveniently and efficiently. We provide free download and tryout before your purchase. Our AI-300 exam questions just need students to spend 20 to 30 hours practicing on the platform which provides simulation problems, can let them have the confidence to pass the AI-300 Exam, so little time great convenience for some workers. It must be your best tool to pass your AI-300 exam and achieve your target.
| Section | Objectives |
|---|---|
| Topic 1: Design and implement an MLOps infrastructure | - Configure source control, CI/CD pipelines, and automation for ML workflows - Manage environments, data stores, and model registries - Implement security, governance, and compliance for MLOps - Set up Azure Machine Learning workspace and compute targets |
| Topic 2: Design and implement a GenAIOps infrastructure | - Implement RAG (Retrieval-Augmented Generation) pipelines and vector search - Configure prompt orchestration, prompt flows, and agent frameworks - Manage API keys, rate limits, and responsible AI guardrails - Set up Microsoft Foundry and Azure AI services for generative AI workloads |
| Topic 3: Implement machine learning model lifecycle and operations | - Deploy models to real-time and batch endpoints - Retrain, update, and manage model versions in production - Monitor model performance, data drift, and operational health - Train, register, and version models using Azure Machine Learning |
| Topic 4: Optimize generative AI systems and model performance | - Fine-tune and distill models for specific use cases - Optimize inference performance, caching, and throughput - Implement cost management and scaling strategies for GenAI workloads - Tune prompts, system messages, and grounding strategies |
| Topic 5: Implement generative AI quality assurance and observability | - Evaluate generative AI outputs for quality, safety, and grounding - Conduct red teaming, adversarial testing, and content filtering - Monitor latency, token usage, cost, and error rates - Implement logging, tracing, and telemetry for GenAI applications |
>> Latest AI-300 Test Blueprint <<
All contents of AI-300 training guide are being explicit to make you have explicit understanding of this exam. Their contribution is praised for their purview is unlimited. None cryptic contents in AI-300 learning materials you may encounter. And our AI-300 Exam Questions are easy to understand and they are popular to be sold to all over the world. Just look at the comments on the website, then you will know that we have a lot of loyal customers.
NEW QUESTION # 65
Drag and Drop Question
You are fine-tuning an LLM base model by using Microsoft Foundry. You have a labeled dataset of customer emails.
You need to improve task-specific prediction accuracy so that the model can be tested and deployed later.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.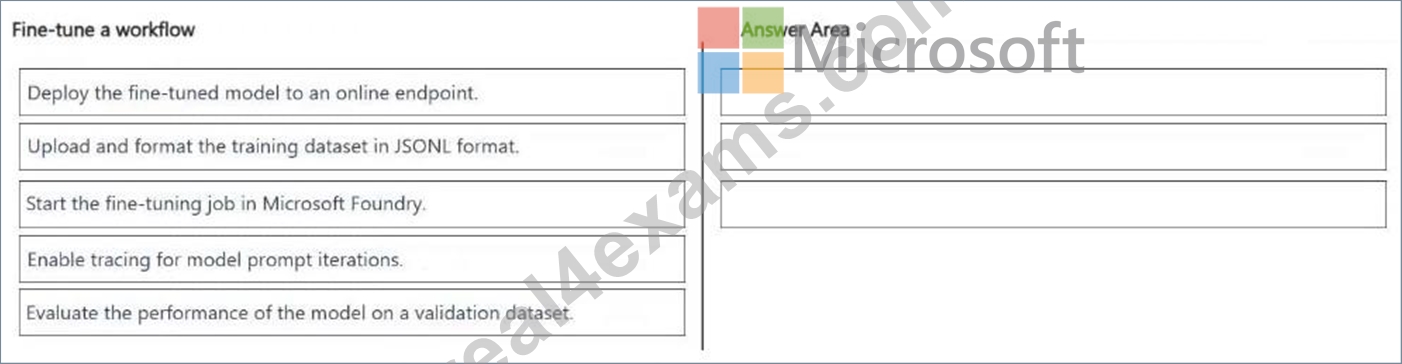
Answer:
Explanation: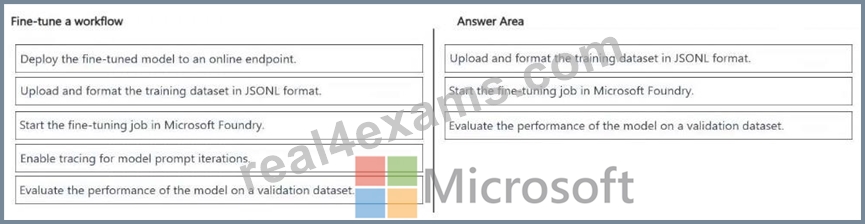
Explanation:
Step 1: Upload and format the training dataset in JSON format.
Upload and Format Training Data (JSONL)
You need to format your labeled emails so the model can learn from them.
Format Requirements: In Microsoft Foundry, training and validation files must be prepared in a JSONL (JSON Lines) format.
Structure: Each line should represent a single conversation or input-output pair. For email tasks (like classification, summarization, or routing), this usually consists of a messages array.
Step 2: Start the fine-tuning jobs in Microsoft Foundry.
Start Supervised Fine-Tuning (SFT) Jobs
Once your data is uploaded to a private Azure storage account or directly through the UI, you will initiate the training process.
Technique: Choose Supervised Fine-Tuning (SFT). SFT is designed for teaching models specific tasks (like specific tone alignment or labeling) on labeled data.
Execution: Through the Azure AI Foundry Model Catalog, select your base model (e.g., GPT-4o- mini or Llama Scout), upload your train/validation JSONL files, and submit the job.
Experimentation: Foundry also supports hyperparameter settings (like learning rates and batch sizes) which you can tweak if needed.
Step 3: Evaluate the performance of the model on a validation dataset.
Evaluate and Deploy
Fine-tuning is an iterative process. Before deploying to a production environment, you must evaluate the model to ensure it meets your specific task accuracy goals.
Evaluation: Use Foundry's built-in evaluation tools and your validation dataset to benchmark the fine-tuned student model against the baseline base model.
Deployment: Once task-specific prediction accuracy is confirmed using validation metrics, you can host and deploy the model directly on Azure AI Foundry for your applications to consume.
Reference:
https://devblogs.microsoft.com/foundry/beyond-the-prompt-why-and-how-to-fine-tune-your-own-models/
NEW QUESTION # 66
A team is deploying machine learning models to a production inference endpoint in Azure Machine Learning.
The team requires a safe way to validate a new model version without disrupting existing users.
You need to recommend a deployment strategy for controlled testing of a new model version.
What should you configure?
Answer: A
Explanation:
The best strategy for controlled testing of a new model version in Azure Machine Learning is Blue-Green Deployment, often referred to as a safe rollout.
This approach allows you to deploy a new model version alongside the current one within the same Managed Online Endpoint without disrupting existing users.
Key Features of Blue-Green Deployment in Azure ML
Simultaneous Versions: Both the current "Blue" and new "Green" models run concurrently on the same endpoint.
*-> Traffic Shifting: You can use the endpoint's load balancer to allocate a specific percentage (e.g., 10%) of live production traffic to the new version.
Mirrored Traffic: For even lower risk, you can test the new model with mirrored traffic, where production requests are copied to the new model for validation without using its responses for the end user.
Instant Rollback: If the new model performs poorly, you can instantly shift 100% of traffic back to the original version.
Deployment Headers: You can bypass general traffic splitting to test the "Green" deployment specifically by adding an azureml-model-deployment header to your HTTP requests.
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-safely-rollout-online-endpoints
NEW QUESTION # 67
A product team is building a customer support assistant that must respond consistently across multiple channels.
Early testing shows that small wording changes in prompts cause large differences in tone and factual accuracy.
The team needs prompts that are reliable, reusable, and adaptable across multiple use cases without retraining the underlying model.
You need to design prompts that improve response quality while remaining flexible for future changes.
Which two actions should you perform? Each correct answer presents part of the solution. (Choose two.)
Answer: A,B
Explanation:
B and C provide the strongest architecture for reusable and predictable prompts. Separating persistent application instructions from dynamic user input establishes a clear instruction hierarchy . The stable portion of the prompt can define application behavior while channel-specific or request-specific content remains variable. This reduces coupling between user wording and the behavioral rules of the assistant and makes the prompt easier to reuse, version, test, and modify.
The system prompt should establish the model ' s role, behavioral boundaries, tone, communication style, response format, and other persistent rules. Microsoft specifically describes system messages as high-priority instructions used to define an assistant ' s role and boundaries and to set tone and communication style.
Fine-tuning for every conversational variation is unnecessarily expensive and contradicts the requirement to remain adaptable without retraining. Increasing temperature increases randomness and therefore works against consistent responses. Although repeating important instructions can sometimes mitigate recency effects, Microsoft treats this as an optional prompt-engineering technique to experiment with, not the primary architectural technique for producing reusable prompts.
Study Guide Reference: Design and implement a GenAIOps infrastructure - design and develop prompts, prompt management, prompt variants, system instructions, and reusable prompt structures.
NEW QUESTION # 68
You have an Azure Machine Learning workspace that includes an AmICompute cluster and a batch endpoint.
You clone a repository that contains an MLflow model to your local computer. You need to ensure that you can deploy the model to the batch endpoint.
Solution: Create a datastore in the workspace.
Does the solution meet the goal?
Answer: A
NEW QUESTION # 69
Your ML pipeline contains independent feature engineering steps that currently execute sequentially, increasing overall runtime. You want to optimize execution without modifying logic.
What is the BEST solution?
Answer: A
Explanation:
Parallel execution allows independent pipeline steps to run simultaneously, reducing total execution time without altering logic. This is more efficient than increasing compute resources, which may raise costs without guaranteeing proportional performance improvements.
NEW QUESTION # 70
......
Most of the brands that offer Microsoft AI-300 study material provide it at high rates. However, Real4exams saves your money by offering Microsoft AI-300 Real Questions at an affordable price. In addition, we offer up to 12 months of free AI-300 exam questions.
AI-300 Guide: https://www.real4exams.com/AI-300_braindumps.html