P.S. Free & New MLA-C01 dumps are available on Google Drive shared by ITCertMagic: https://drive.google.com/open?id=16kD6VdnZIVqIHesrfsy63d6gdAm4il7s
In order to make the exam easier for every candidate, ITCertMagic compiled such a study materials that allows making you test and review history performance, and then you can find your obstacles and overcome them. In addition, once you have used this type of MLA-C01 Exam Question online for one time, next time you can practice in an offline environment. It must be highest efficiently MLA-C01 exam tool to help you pass the exam.
| Certification Vendor: | Amazon Web Services (AWS) |
|---|---|
| Exam Name: | AWS Certified Machine Learning Engineer - Associate |
| Exam Number: | MLA-C01 |
| Exam Duration: | 170 minutes |
| Exam Price: | 150 USD |
| Related Certifications: | AWS Certified Data Engineer - Associate AWS Certified Solutions Architect - Associate AWS Certified Developer - Associate |
| Passing Score: | 1000-2000 scaled score (passing score approximately 720) |
| Available Languages: | Traditional Chinese, Korean, English, Japanese, Simplified Chinese |
| Exam Format: | Multiple choice, Multiple response |
| Certificate Validity Period: | 3 years |
| Real Exam Qty: | 85 |
| Sample Questions: | Amazon MLA-C01 Sample Questions |
| Exam Way: | Online proctored (Pearson VUE) or in-person testing center |
| Pre Condition: | Recommended: 2+ years of ML engineering experience, familiarity with AWS ML services |
| Official Syllabus URL: | https://aws.amazon.com/certification/certified-machine-learning-engineer-associate/ |
The AWS Certified Machine Learning Engineer - Associate certification exam is a valuable asset for beginners and seasonal professionals. If you want to improve your career prospects then MLA-C01 certification is a step in the right direction. Whether you’re just starting your career or looking to advance your career, the MLA-C01 Certification Exam is the right choice. With the MLA-C01 certification you can gain a range of career benefits which include credibility, marketability, validation of skills, and access to new job opportunities.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
NEW QUESTION # 224
An ML engineer is preparing a dataset that contains medical records to train an ML model to predict the likelihood of patients developing diseases.
The dataset contains columns for patient ID, age, medical conditions, test results, and a "Disease" target column.
How should the ML engineer configure the data to train the model?
Answer: C
Explanation:
Patient ID is a unique identifier and does not contain predictive information. Including it can cause the model to overfit by memorizing records rather than learning meaningful patterns.
AWS ML best practices recommend removing identifiers that are not causally related to the target variable.
Age, medical conditions, and test results are clinically relevant features and should be retained. The target column must remain for supervised learning.
Therefore, Option A is the correct and AWS-aligned choice.
NEW QUESTION # 225
A company has multiple models that are hosted on Amazon SageMaker Al. The models need to be re-trained.
The requirements for each model are different, so the company needs to choose different deployment strategies to transfer all requests to a new model.
Select the correct strategy from the following list for each requirement. Select each strategy one time. (Select THREE.)
. Canary traffic shifting
. Linear traffic shifting guardrail
. All at once traffic shifting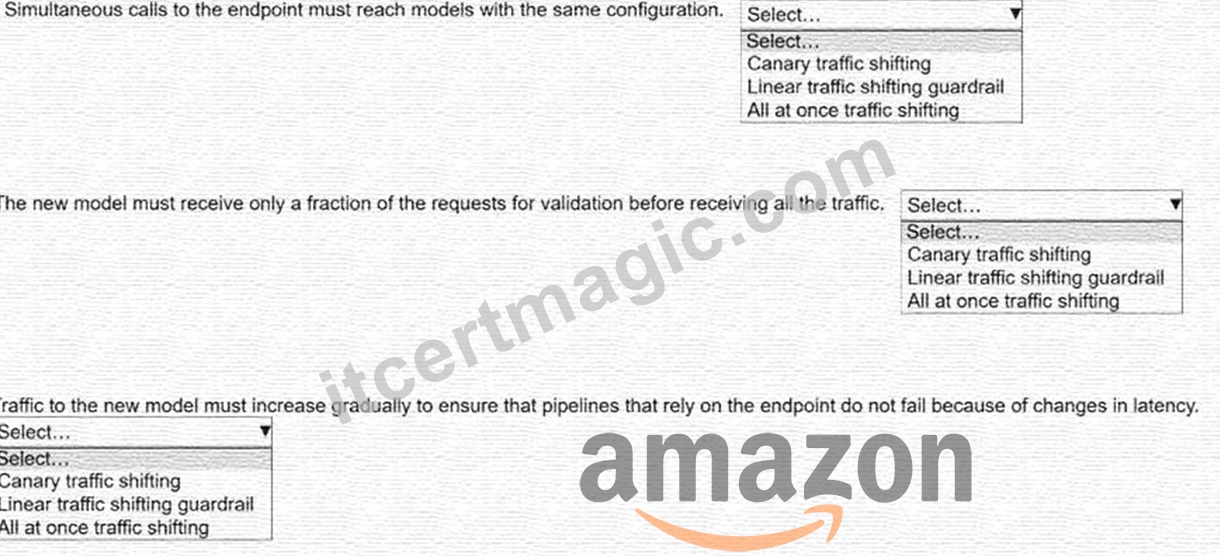
Answer:
Explanation: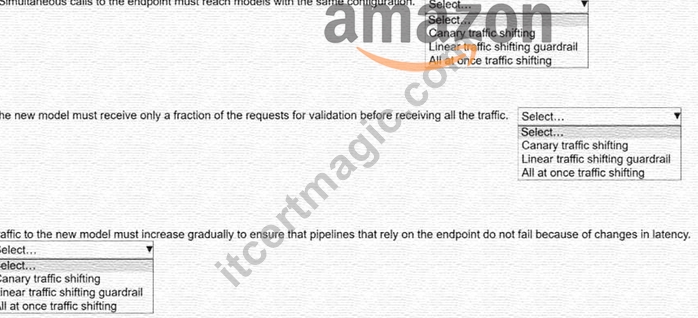
Explanation:
1## Simultaneous calls to the endpoint must reach models with the same configuration Correct strategy: All at once traffic shifting Why:
"All at once" replaces the old model with the new model immediately. After the switch, all concurrent requests hit only the new model configuration, guaranteeing configuration consistency across simultaneous calls.
2## The new model must receive only a fraction of the requests for validation before receiving all the traffic Correct strategy: Canary traffic shifting Why:
Canary deployments route a small percentage of traffic (for example, 5% or 10%) to the new model first. This allows validation of correctness and performance before shifting 100% of traffic.
3## Traffic to the new model must increase gradually to ensure that pipelines that rely on the endpoint do not fail because of changes in latency Correct strategy: Linear traffic shifting guardrail Why:
Linear traffic shifting gradually increases traffic in equal increments over time and includes guardrails (such as CloudWatch alarms) to automatically roll back if latency or errors exceed thresholds.
NEW QUESTION # 226
An ML engineer is analyzing potential biases in a customer dataset before training an ML model. The dataset contains customer age (numeric), product reviews (text), and purchase outcomes (categorical).
Which statistical metrics should the ML engineer use to identify potential biases in the dataset before model training?
Answer: C
Explanation:
Bias detection is a critical step in responsible machine learning and is emphasized in AWS documentation, particularly in Amazon SageMaker Clarify. When analyzing structured datasets that include sensitive or influential attributes such as age, AWS recommends evaluating label distribution fairness and group-based outcome differences before training a model.
The class imbalance metric helps identify whether certain outcomes (for example, purchase vs. no purchase) are overrepresented or underrepresented. Severe imbalance can cause models to favor majority classes, leading to biased predictions. AWS explicitly highlights class imbalance as a key issue to assess during data exploration.
The Difference in Proportions of Labels (DPL) is a fairness metric supported by SageMaker Clarify that measures whether outcome labels are disproportionately distributed across different groups, such as age ranges. DPL compares the proportion of favorable outcomes between groups, making it especially effective for identifying demographic bias in categorical labels.
Options A and D focus on descriptive statistics or correlations, which are useful for data understanding but do not directly measure bias or fairness. Option B partially addresses imbalance and sentiment but sentiment analysis of reviews alone does not quantify demographic bias tied to outcomes.
AWS documentation strongly recommends using group fairness metrics, including DPL, alongside class imbalance checks to identify bias before training. These metrics provide actionable insights into whether a dataset may lead to unfair or skewed model behavior.
Therefore, Option C is the most appropriate and AWS-aligned choice.
NEW QUESTION # 227
A company has built more than 50 models and deployed the models on Amazon SageMaker Al as real-time inference endpoints. The company needs to reduce the costs of the SageMaker Al inference endpoints. The company used the same ML framework to build the models. The company ' s customers require low-latency access to the models.
Select and order the correct steps from the following list to reduce the cost of inference and keep latency low.
Select each
step one time or not at all. (Select and order FIVE.)
Create an endpoint configuration that references a multi-model container.
. Create a SageMaker Al model with multi-model endpoints enabled.
. Deploy a real-time inference endpoint by using the endpoint configuration.
. Deploy a serverless inference endpoint configuration by using the endpoint configuration.
Spread the existing models to multiple different Amazon S3 bucket paths.
. Upload the existing models to the same Amazon S3 bucket path.
. Update the models to use the new endpoint ID. Pass the model IDs to the new endpoint.
Answer:
Explanation:
Explanation:
Step 1
Upload the existing models to the same Amazon S3 bucket path.
Multi-model endpoints require all models to be stored under a single S3 prefix so SageMaker can dynamically load them on demand.
Step 2
Create a SageMaker AI model with multi-model endpoints enabled.
This creates a SageMaker model resource that uses a multi-model-capable container (for example, XGBoost, PyTorch, or TensorFlow MME-compatible containers).
Step 3
Create an endpoint configuration that references a multi-model container.
The endpoint configuration defines:
Instance type
Initial instance count
The multi-model container reference
Step 4
Deploy a real-time inference endpoint by using the endpoint configuration.
Real-time endpoints ensure low-latency inference, which is a strict customer requirement.
Step 5
Update the models to use the new endpoint ID. Pass the model IDs to the new endpoint.
Each inference request specifies a model ID so SageMaker knows which model to load from S3.
NEW QUESTION # 228
An ML engineer is training a simple neural network model. The ML engineer tracks the performance of the model over time on a validation dataset. The model's performance improves substantially at first and then degrades after a specific number of epochs.
Which solutions will mitigate this problem? (Choose two.)
Answer: A,E
Explanation:
Early stopping halts training once the performance on the validation dataset stops improving. This prevents the model from overfitting, which is likely the cause of performance degradation after a certain number of epochs.
Dropout is a regularization technique that randomly deactivates neurons during training, reducing overfitting by forcing the model to generalize better. Increasing dropout can help mitigate the problem of performance degradation due to overfitting.
NEW QUESTION # 229
......
MLA-C01 Reliable Test Topics: https://www.itcertmagic.com/Amazon/real-MLA-C01-exam-prep-dumps.html
BTW, DOWNLOAD part of ITCertMagic MLA-C01 dumps from Cloud Storage: https://drive.google.com/open?id=16kD6VdnZIVqIHesrfsy63d6gdAm4il7s