Our Designing and Implementing Multi-Agent AI Solutions exam question has been widely praised by all of our customers in many countries and our company has become the leader in this field. Our product boost varied functions and they include the self-learning and the self-assessment functions, the timing function and the function to stimulate the exam to make you learn efficiently and easily. There are many advantages of our AI-500 Study Tool.
| Section | Weight | Objectives |
|---|---|---|
| Secure, govern, and deploy multi-agent solutions | 20-25% | - Design and implement guardrails
|
| Evaluate, optimize, and monitor multi-agent solutions | 20-25% | - Optimize operational performance
|
| Develop multi-agent solutions in Azure | 30-35% | - Build and integrate tool ecosystems
|
| Architect multi-agent solutions | 15-20% | - Design logical architecture for multi-agent solutions
|
>> AI-500 Interactive Questions <<
Each product has a trial version and our products are without exception, literally means that our AI-500 guide torrent can provide you with a free demo when you browse our website of AI-500 prep guide, and we believe it is a good way for our customers to have a better understanding about our products in advance. Moreover if you have a taste ahead of schedule, you can consider whether our AI-500 Exam Torrent is suitable to you or not, thus making the best choice.
NEW QUESTION # 30
You are designing Microsoft Foundry multi-agent solution. The agents will use Agent-to-Agent (A2A) delegation and access separate Azure Storage containers within a lesource group named RG1.
You need to recommend identity components for the design. The solution must meet the following requirements:
* Eliminate stored application secrets.
* Limit the impact of a compromised agent or deployment.
Solution: Use a shared single-tenant application registration for the agents Assign Azure roles at the subscription scope. Does this meet the goal?
Answer: B
Explanation:
A shared single-tenant application registration combined with subscription-wide role assignments creates an excessively broad trust and authorization boundary. It also does not, by itself, guarantee elimination of stored credentials because an app registration can still authenticate with a client secret or certificate unless federation is configured. More importantly, compromise of any agent using the shared identity could expose resources well beyond that agent ' s assigned Storage container. Microsoft guidance favors distinct workload/agent identities and the narrowest practical Azure RBAC scope, ideally at the resource or data-resource level required by each agent. Because the proposed design uses both a shared identity and subscription-level access, it fails the blast-radius requirement and least-privilege principle. Therefore B, No, is correct. Least privilege remains the governing principle: grant only the identity, data, tool, or deployment access required for the specific operation. The selected answer preserves that boundary while still allowing the workflow to satisfy its functional requirement.
Official Microsoft reference: Microsoft Foundry agent identity
NEW QUESTION # 31
You have a Microsoft Foundry agent that answers questions about products. You evaluate the agent responses and discover the following issues:
* Questions about a product named product1 make up 40 percent of user traffic, and responses are returned in inconsistent formats.
* Questions about a product named product2 appear infrequently in the existing logs but have high escalation rates.
The available chat logs include customer names and contact details, and the labeling budget enables subject matter experts (SMEs) to review only a limited subset of training examples.
You need to design a dataset preparation plan to fine-tune the agent. The solution must meet the following requirements:
* Match usage patterns for the product1 questions.
* Cover the product2 questions.
* Meet General Data Protection Regulation < GDPR) and Health Insurance Portability and Accountability Act (HIPAA) privacy requirements for names and contact details.
* Minimize SME review efforts during labeling.
What should you include in the design? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.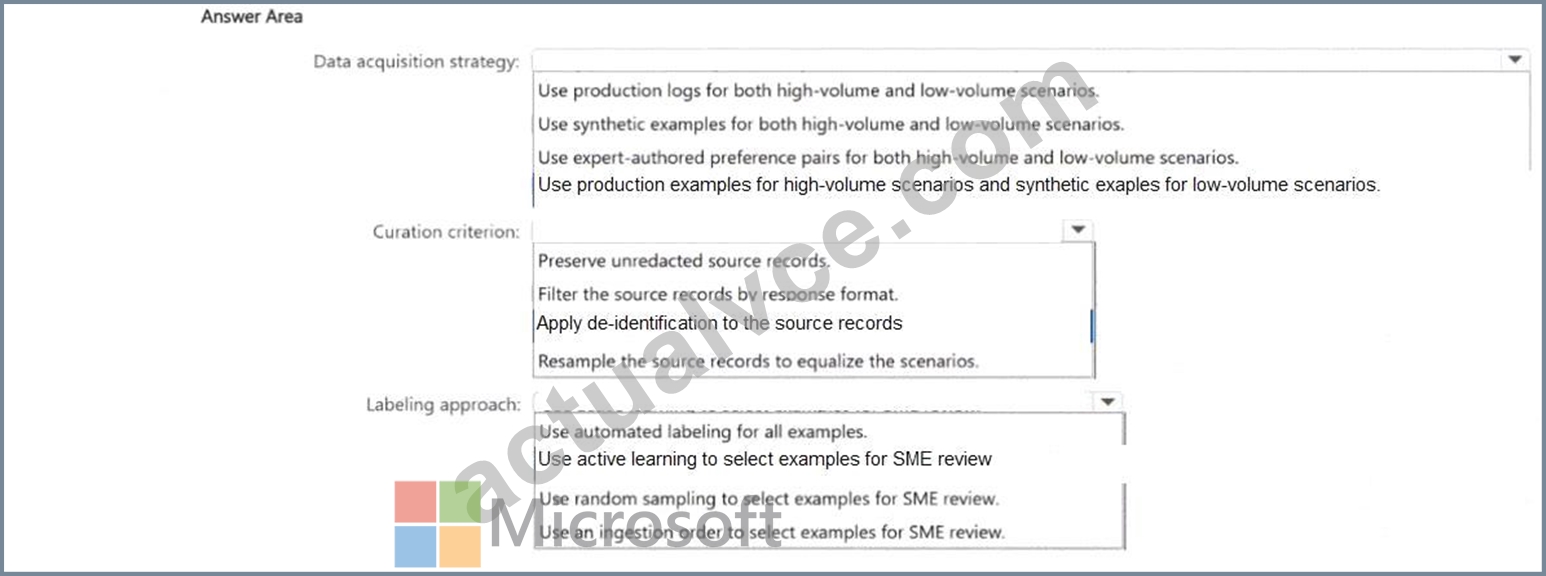
Answer:
Explanation: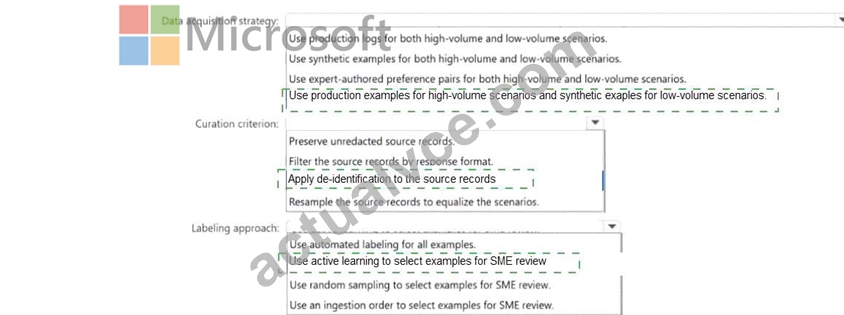
Explanation:
Data acquisition: Production examples for high-volume product1 and synthetic examples for sparse product2; Curation: De-identify source records; Labeling: Use active learning to prioritize SME review.
Product1 represents a large share of real traffic, so production examples best preserve its true usage distribution. Product2 appears infrequently but has high escalation impact, making synthetic generation appropriate for filling the coverage gap without waiting for more production traffic. Because the available logs contain names and contact information, those records should be de-identified before they are reused for training or labeling. Finally, the SME budget is limited, so active learning should prioritize the examples where expert labels are most informative instead of reviewing a uniform random sample. Microsoft Foundry guidance supports synthetic fine-tuning data when real examples are sparse, and Microsoft healthcare/privacy tooling supports de-identification of sensitive identifiers. This design balances representativeness, rare-case coverage, privacy, and labeling efficiency. At implementation time, the same rule should be expressed through the framework or service configuration rather than left only as a natural-language convention. That makes the behavior repeatable across runs, easier to test, and less sensitive to model variability.
Official Microsoft reference: Microsoft Foundry - synthetic fine-tuning data generation
NEW QUESTION # 32
You have a multi-agent Retrieval-Augmented Generation (RAG) solution that uses a Foundry IQ knowledge base. The solution includes a support agent and a policy agent.
You have an evaluation dataset that contains the following for each user query
* The expected source IDs
* Retrieved chunks in rank order
* The final agent response
You discover that an embedding model change and a custom analyzer change cause the failed traces shown in the following table.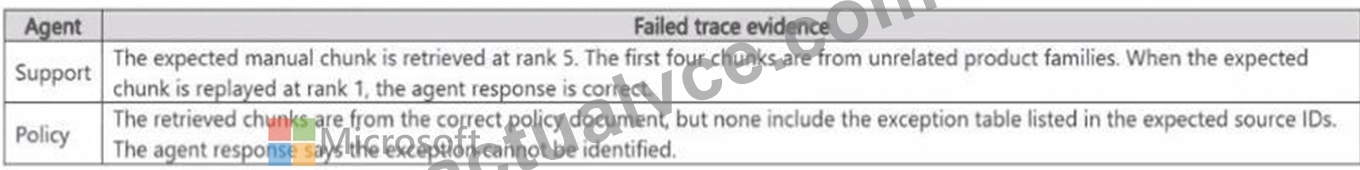
You need to isolate the failing parts of the RAG pipeline.
Which evaluator should you use for each agent? To answer, drag the appropriate evaluators to the correct agents. Each evaluator may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content NOTE: Each correct selection is worth one point.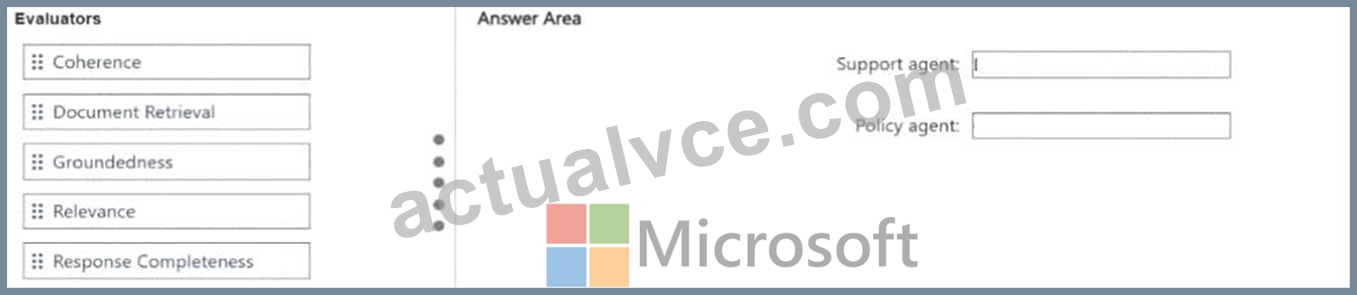
Answer:
Explanation:
Explanation:
Support agent: Document Retrieval; Policy agent: Document Retrieval.
Both failures are retrieval failures and should therefore be diagnosed with the Document Retrieval evaluator.
The dataset includes expected source IDs and ranked retrieved chunks, which provides the retrieval ground truth required by that evaluator. For the support agent, the expected source appears too low in the ranking after unrelated chunks. For the policy agent, the required exception-table source is missing entirely.
Groundedness would evaluate whether the final response is supported by the context it actually received; it could therefore pass even when the retrieval stage failed to fetch a required source. Microsoft Foundry ' s Document Retrieval evaluator compares retrieved documents against labeled ground truth and reports ranking
/search metrics such as NDCG and Fidelity. The corrected answer is Document Retrieval for both agents. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry - RAG evaluators
NEW QUESTION # 33
You have a Microsoft Foundry multi-agent assistant that uses a Retrieval-Augmented Generation (RAG)- enabled workflow. A retrieval agent returns document chunks to an answer agent, and the answer agent produces the final response.
You have a dataset that contains query, context, and response without document relevance labels.
You need to implement built-in RAG evaluators that meet the following requirements:
* Identify final responses that include content that is NOT supported by the retrieved context.
* Assess whether the retrieved context chunks and final responses support the user query.
Which evaluator should you use for each requirement? To answer, drag the appropriate evaluators to the correct requirements. Each evaluator may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.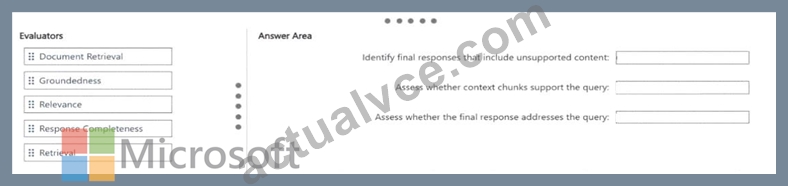
Answer:
Explanation: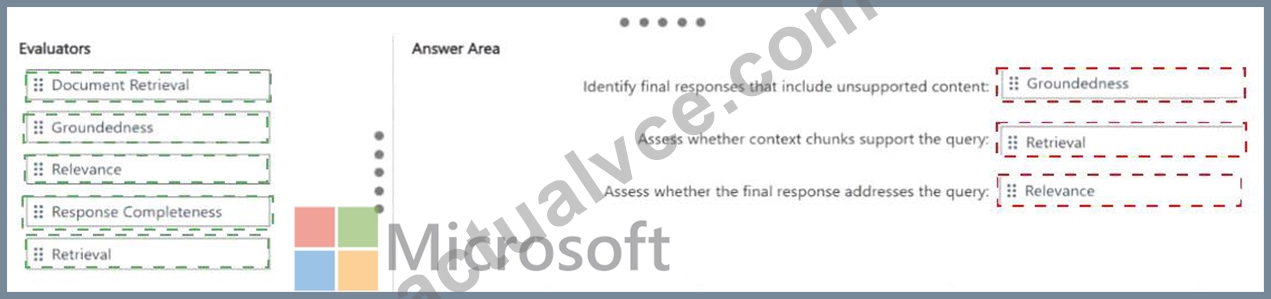
Explanation:
Unsupported final-response content: Groundedness; Context support for the query: Retrieval; Final- response support for the query: Relevance.
Groundedness detects whether the generated response contains claims that are not supported by the retrieved context, which directly matches the first requirement. Retrieval evaluates how relevant the provided context chunks are to the query when no document relevance ground truth is available. Relevance evaluates whether the final response directly and adequately answers the query. Microsoft Foundry separates these metrics so teams can diagnose whether a poor RAG result originated in retrieval or generation. Document Retrieval would require labeled retrieval ground truth, which the question explicitly says is absent. Response Completeness likewise depends on expected/ground-truth information. The supplied Groundedness, Retrieval, and Relevance mapping therefore matches the documented evaluator inputs and purposes. A robust evaluation program separates process metrics from final-response metrics. The selected answer measures the layer where the stated failure actually occurs, which is essential for deciding whether to change retrieval, orchestration, prompt behavior, or the final generator. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry - RAG evaluators
NEW QUESTION # 34
You have a Microsoft Agent Framework solution for customer support that includes the following agents:
* A triage agent
* A refund specialist agent that runs in the same process as the triage agent
* A compliance review agent that is exposed by a partner team as a remote service You need to identify which integration components the triage agent will use to coordinate interactions with the other agents.
What should you identify for each agent? To answer, drag the appropriate components to the correct agents Each component may be used once, more than once, or not at all You may need to drag the split bar between panes or scroll to view content NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
Refund specialist agent: Agent-as-tools; Compliance review agent: Agent-to-Agent (A2A) protocol.
The refund specialist runs in the same process as the triage agent, so exposing it as an agent-as-tool is the lightweight composition pattern. The outer triage agent can decide when to invoke the specialist while retaining overall task ownership. The compliance reviewer is different: it is a remote service owned by a partner team. Agent-to-Agent (A2A) is the interoperable protocol intended for independently hosted agents that may use a different runtime or framework. It supports capability discovery and remote task interaction without coupling the caller to the partner ' s implementation. Using A2A for the in-process specialist would add unnecessary network/protocol complexity, while treating the partner agent as an in-process tool would not match the deployment boundary. The two selections therefore reflect Microsoft ' s distinction between local agent composition and remote agent interoperability. The implementation should also preserve clear inputs and outputs around this step so that later agents receive only the information they require. This improves debuggability and keeps token, permission, and state growth under control as the workflow becomes more complex.
Official Microsoft reference: Microsoft Agent Framework - agents as tools and A2A
NEW QUESTION # 35
......
The high quality of our AI-500 preparation materials is mainly reflected in the high pass rate, because we deeply know that the pass rate is the most important. As is well known to us, our passing rate has been high; 99% of people who used our AI-500 real test has passed their tests and get the certificates. I dare to make a bet that you will not be exceptional. Your test pass rate is going to reach more than 99% if you are willing to use our AI-500 Study Materials with a high quality. So it is necessary for you to know well about our AI-500 test prep.
Valid Real AI-500 Exam: https://www.actualvce.com/Microsoft/AI-500-valid-vce-dumps.html