Unparalleled Certified-Data-Engineer-Professional Latest Exam Pdf, Ensure to pass the Certified-Data-Engineer-Professional Exam

After you pay for our Certified-Data-Engineer-Professional exam material online, you will get the link to download it in only 5 to 10 minutes. You don't need to worry about safety in buying our Certified-Data-Engineer-Professional exam materials. Our products are free from computer virus and we will protect your private information. You won't get any telephone harassment or receiving junk E-mails after purchasing our Certified-Data-Engineer-Professional Study Guide. If we have a new version of your study material, we will send an E-mail to you. Whenever you have questions about our Certified-Data-Engineer-Professional study material, you are welcome to contact us via E-mail.
| Section | Objectives |
|---|
| Topic 1: Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 2. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- 3. Develop User-Defined Functions using Pandas/Python UDF
- Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 2. Create pipeline components using control flow operators such as if/else and foreach
- 3. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 4. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 5. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 6. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 7. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 8. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
|
| Topic 2: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
- 2. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
|
| Topic 3: Data Sharing and Federation | - Share and federate data
- 1. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 2. Configure Lakehouse Federation with appropriate governance across supported source systems
- 3. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
|
| Topic 4: Cost & Performance Optimization | - Optimize cost and performance
- 1. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 2. Apply Change Data Feed to address streaming table limitations and improve latency
- 3. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 4. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 5. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
|
| Topic 5: Data Governance | - Govern enterprise data
- 1. Demonstrate understanding of the Unity Catalog permission inheritance model
- 2. Create and add descriptions and metadata to enterprise data to improve discoverability
|
| Topic 6: Debugging and Deploying | - Debugging and Troubleshooting
- 1. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- 2. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 3. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- Deploying CI/CD
- 1. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
|
| Topic 7: Data Modeling | - Design and optimize data models
- 1. Design and implement scalable data models using Delta Lake to manage large datasets
- 2. Simplify data layout decisions and optimize query performance using liquid clustering
- 3. Design dimensional models for analytical workloads with efficient querying and aggregation
- 4. Identify the benefits of liquid clustering over partitioning and Z-Ordering
|
| Topic 8: Ensuring Data Security and Compliance | - Applying Data Security Mechanisms
- 1. Use ACLs to secure workspace objects and enforce the principle of least privilege
- 2. Use row filters and column masks to protect sensitive table data
- 3. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- Ensuring Compliance
- 1. Implement compliant batch and streaming pipelines that detect and mask PII
- 2. Develop data purging solutions that comply with data retention policies
|
| Topic 9: Monitoring and Alerting | - Alerting
- 1. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- 2. Use SQL Alerts to monitor data quality
- Monitoring
- 1. Use Query Profile and Spark UI to monitor workloads
- 2. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 3. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 4. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
|
| Topic 10: Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
- 2. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
|
>> Certified-Data-Engineer-Professional Latest Exam Pdf <<
Certified-Data-Engineer-Professional Exam Questions - Certified-Data-Engineer-Professional Test Torrent & Certified-Data-Engineer-Professional Latest Exam Torrents
It is human nature to pursue wealth and success. No one wants to be a common person. In order to become a successful person, you must sharpen your horizons and deepen your thoughts. Our Certified-Data-Engineer-Professional practice guide can help you update yourself in the shortest time. And according to the data of our loyal customers, we can claim that if you study with our Certified-Data-Engineer-Professional Exam Questions for 20 to 30 hours, then you can pass the exam with ease. And the price of our Certified-Data-Engineer-Professional study materials is quite favourable.
Databricks Certified Data Engineer Professional Sample Questions (Q167-Q172):
NEW QUESTION # 167
A security team wants to enforce data protection for a customer table containing customer PII data. To comply with local policies, sales team members should only see customers from their region, while non-admin users should have email addresses masked. Which implementation approach should be used when using Unity Catalog row filters and column masks?
- A. Implement row filters with SQL UDFs based on user region only since column masks cannot be combined with row filters on the same table, then apply them be recreating the table with DROP TABLE and CREATE TABLE SET ROW FILTER commands.
- B. Create SQL UDFs for row filtering based on user region and column masking based on group membership, then apply them using ALTER TABLE SET ROW FILTER and ALTER COLUMN SET MASK commands.
- C. Create a view with dynamic WHERE clauses for region filtering and use string replacement functions for email masking using ALTER COLUMN SET MASK command.
- D. Use table ACLs to restrict access using tags with GRANT SELECT ON table_name WITH TAG command, and rely on application-level filtering for sensitive data based on user region.
Answer: B
Explanation:
Unity Catalog enforces fine-grained access control by applying SQL UDF-based row filters and column masks directly at the table level. Row filter UDFs can restrict visible rows based on the user's region, while column mask UDFs can dynamically mask sensitive fields like email addresses for non-admin users. Applying them with ALTER TABLE SET ROW FILTER and ALTER COLUMN SET MASK ensures centralized, consistent enforcement of data protection policies across all access paths.
NEW QUESTION # 168
A Delta Lake table was created with the below query:

Realizing that the original query had a typographical error, the below code was executed:
ALTER TABLE prod.sales_by_stor RENAME TO prod.sales_by_store
Which result will occur after running the second command?
- A. All related files and metadata are dropped and recreated in a single ACID transaction.
- B. A new Delta transaction log Is created for the renamed table.
- C. The table name change is recorded in the Delta transaction log.
- D. The table reference in the metastore is updated and no data is changed.
- E. The table reference in the metastore is updated and all data files are moved.
Answer: D
Explanation:
The query uses the CREATE TABLE USING DELTA syntax to create a Delta Lake table from an existing Parquet file stored in DBFS. The query also uses the LOCATION keyword to specify the path to the Parquet file as /mnt/finance_eda_bucket/tx_sales.parquet. By using the LOCATION keyword, the query creates an external table, which is a table that is stored outside of the default warehouse directory and whose metadata is not managed by Databricks. An external table can be created from an existing directory in a cloud storage system, such as DBFS or S3, that contains data files in a supported format, such as Parquet or CSV.
The result that will occur after running the second command is that the table reference in the metastore is updated and no data is changed. The metastore is a service that stores metadata about tables, such as their schema, location, properties, and partitions. The metastore allows users to access tables using SQL commands or Spark APIs without knowing their physical location or format. When renaming an external table using the ALTER TABLE RENAME TO command, only the table reference in the metastore is updated with the new name; no data files or directories are moved or changed in the storage system. The table will still point to the same location and use the same format as before. However, if renaming a managed table, which is a table whose metadata and data are both managed by Databricks, both the table reference in the metastore and the data files in the default warehouse directory are moved and renamed accordingly.
NEW QUESTION # 169
The data engineering team maintains the following code:
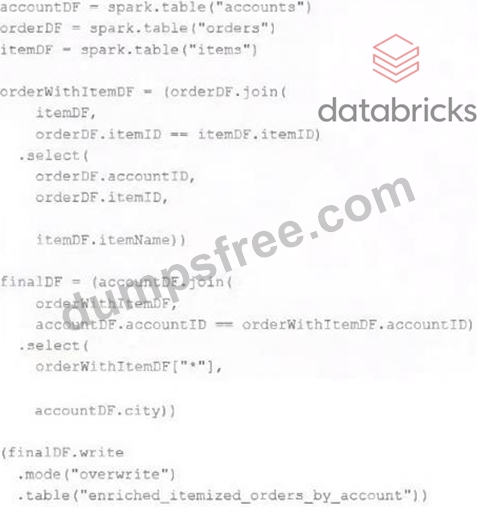
Assuming that this code produces logically correct results and the data in the source tables has been de-duplicated and validated, which statement describes what will occur when this code is executed?
- A. An incremental job will leverage information in the state store to identify unjoined rows in the source tables and write these rows to the enriched_iteinized_orders_by_account table.
- B. The enriched_itemized_orders_by_account table will be overwritten using the current valid version of data in each of the three tables referenced in the join logic.
- C. An incremental job will detect if new rows have been written to any of the source tables; if new rows are detected, all results will be recalculated and used to overwrite the enriched_itemized_orders_by_account table.
- D. No computation will occur until enriched_itemized_orders_by_account is queried; upon query materialization, results will be calculated using the current valid version of data in each of the three tables referenced in the join logic.
- E. A batch job will update the enriched_itemized_orders_by_account table, replacing only those rows that have different values than the current version of the table, using accountID as the primary key.
Answer: B
Explanation:
This is the correct answer because it describes what will occur when this code is executed. The code uses three Delta Lake tables as input sources: accounts, orders, and order_items. These tables are joined together using SQL queries to create a view called new_enriched_itemized_orders_by_account, which contains information about each order item and its associated account details. Then, the code uses write.format("delta").mode("overwrite") to overwrite a target table called enriched_itemized_orders_by_account using the data from the view. This means that every time this code is executed, it will replace all existing data in the target table with new data based on the current valid version of data in each of the three input tables.
NEW QUESTION # 170
A data team is working to optimize an existing large, fast-growing table 'orders' with high cardinality columns, which experiences significant data skew and requires frequent concurrent writes. The team notice that the columns 'user_id', 'event_timestamp' and 'product_id' are heavily used in analytical queries and filters, although those keys may be subject to change in the future due to different business requirements. Which partitioning strategy should the team choose to optimize the table for immediate data skipping, incremental management over time, and flexibility?
- A. Cluster the table with: ALTER TABLE orders CLUSTER BY user_id, product_id, event_timestamp
- B. Partition the table with: ALTER TABLE orders PARTITION BY user_id, product_id, event_timestamp
- C. Use z-order after partitiing the table: OPTIMIZE orders ZORDER BY (user_id, product_id) WHERE event_timestamp = current date () - 1 DAY
- D. Z-order the table with OPTIMIZE orders ZORDER BY (user_id, product_id, event_timestamp)
Answer: D
Explanation:
Z-ordering optimizes data skipping for selective queries on high-cardinality columns without physically repartitioning the table, making it flexible if query patterns change. Using OPTIMIZE ...
ZORDER BY (user_id, product_id, event_timestamp) improves query performance for filters and joins while allowing incremental writes, avoiding the data skew and maintenance overhead that explicit partitioning or clustering could introduce.
NEW QUESTION # 171
The Databricks CLI is use to trigger a run of an existing job by passing the job_id parameter. The response that the job run request has been submitted successfully includes a filed run_id.
Which statement describes what the number alongside this field represents?
- A. The total number of jobs that have been run in the workspace.
- B. The number of times the job definition has been run in the workspace.
- C. The job_id is returned in this field.
- D. The job_id and number of times the job has been are concatenated and returned.
- E. The globally unique ID of the newly triggered run.
Answer: E
Explanation:
When triggering a job run using the Databricks CLI, the run_id field in the response represents a globally unique identifier for that particular run of the job. This run_id is distinct from the job_id.
While the job_id identifies the job definition and is constant across all runs of that job, the run_id is unique to each execution and is used to track and query the status of that specific job run within the Databricks environment. This distinction allows users to manage and reference individual executions of a job directly.
NEW QUESTION # 172
......
The Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) PDF dumps format can be accessed from any smart device such as laptops, tablets, and smartphones. DumpsFree regularly updates the Certified-Data-Engineer-Professional PDF Questions to reflect the latest Databricks Certified-Data-Engineer-Professional exam content. All test questions in the Certified-Data-Engineer-Professional exam PDF format are real and latest.
Certified-Data-Engineer-Professional Valid Study Notes: https://www.dumpsfree.com/Certified-Data-Engineer-Professional-valid-exam.html
- Latest Certified-Data-Engineer-Professional Exam Pattern 👦 Certified-Data-Engineer-Professional Useful Dumps 🔰 Certified-Data-Engineer-Professional Reliable Dumps Ppt 🐕 Search for 「 Certified-Data-Engineer-Professional 」 on ( www.prep4sures.top ) immediately to obtain a free download 🧳Certified-Data-Engineer-Professional Reliable Guide Files
- Free PDF Quiz 2026 Databricks Updated Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Latest Exam Pdf ⏭ Simply search for ▶ Certified-Data-Engineer-Professional ◀ for free download on ✔ www.pdfvce.com ️✔️ 🥦Valid Certified-Data-Engineer-Professional Exam Syllabus
- Start Your Journey to Success with www.validtorrent.com Databricks Certified-Data-Engineer-Professional Practice Material 🤨 Open ➽ www.validtorrent.com 🢪 enter ➤ Certified-Data-Engineer-Professional ⮘ and obtain a free download 🥻Certified-Data-Engineer-Professional Reliable Dumps Ppt
- Certified-Data-Engineer-Professional New Dumps Ebook 🤤 Certified-Data-Engineer-Professional Complete Exam Dumps 🎆 Certified-Data-Engineer-Professional Discount ↔ Search for { Certified-Data-Engineer-Professional } and obtain a free download on ➡ www.pdfvce.com ️⬅️ 😒Mock Certified-Data-Engineer-Professional Exam
- 100% Pass 2026 Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Newest Latest Exam Pdf 🦺 ▶ www.examcollectionpass.com ◀ is best website to obtain 「 Certified-Data-Engineer-Professional 」 for free download 🌞New Certified-Data-Engineer-Professional Study Materials
- Hot Certified-Data-Engineer-Professional Latest Exam Pdf Pass Certify | Professional Certified-Data-Engineer-Professional Valid Study Notes: Databricks Certified Data Engineer Professional 😤 Easily obtain ➠ Certified-Data-Engineer-Professional 🠰 for free download through ( www.pdfvce.com ) 📜Certified-Data-Engineer-Professional Practice Test Pdf
- Reliable Certified-Data-Engineer-Professional Test Tutorial ☝ New Certified-Data-Engineer-Professional Test Questions 💫 Valid Certified-Data-Engineer-Professional Test Practice 🎣 Search for ➡ Certified-Data-Engineer-Professional ️⬅️ and easily obtain a free download on ☀ www.examcollectionpass.com ️☀️ 🦮Certified-Data-Engineer-Professional Demo Test
- Quiz Marvelous Databricks - Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional Latest Exam Pdf 🧾 Search for ⮆ Certified-Data-Engineer-Professional ⮄ and download it for free on ➽ www.pdfvce.com 🢪 website 🤔Certified-Data-Engineer-Professional Reliable Dumps Ppt
- Latest Databricks Certified Data Engineer Professional real exams, Certified-Data-Engineer-Professional vce dumps 🥝 Simply search for ▷ Certified-Data-Engineer-Professional ◁ for free download on ▛ www.vce4dumps.com ▟ 📂Valid Certified-Data-Engineer-Professional Test Practice
- Certified-Data-Engineer-Professional Useful Dumps 📶 Certified-Data-Engineer-Professional Reliable Dumps Ppt 🤩 Certified-Data-Engineer-Professional Discount 🔗 Search for ☀ Certified-Data-Engineer-Professional ️☀️ and easily obtain a free download on ➠ www.pdfvce.com 🠰 🐚Certified-Data-Engineer-Professional Complete Exam Dumps
- Start Your Journey to Success with www.vceengine.com Databricks Certified-Data-Engineer-Professional Practice Material 🦌 Copy URL ☀ www.vceengine.com ️☀️ open and search for 「 Certified-Data-Engineer-Professional 」 to download for free 🙅Cert Certified-Data-Engineer-Professional Guide
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes