Have similar features to the desktop-based exam simulator contains actual Microsoft DP-750 Practice Test that will help you grasp every topic Compatible with every operating system such as Mac, Linus, iOS, Windows, and Android Works properly on Google chrome, Internet explorer, Microsoft Edge, Opera, etc. Does not require any special plugins to operate creates an exam atmosphere making candidates more confident. Keep track of your progress with self-analysis Points out mistakes at the end of every attempt.
| Section | Weight | Objectives |
|---|---|---|
| Configure and manage Azure Databricks environments | 15-20% | - Security and authentication setup
|
| Prepare and process data | 30-35% | - Data quality and validation
|
| Deploy and manage data pipelines and workloads | 30-35% | - Operational reliability
|
| Secure and govern data using Unity Catalog | 15-20% | - Data governance fundamentals
|
>> DP-750 Guaranteed Passing <<
TestSimulate provides updated and valid DP-750 Exam Questions because we are aware of the absolute importance of updates, keeping in mind the dynamic Microsoft DP-750 Exam Syllabus. We provide you update checks for 365 days after purchase for absolutely no cost. We also give a 25% discount on all DP-750 dumps.
NEW QUESTION # 69
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a catalog named CatalogV Catalog1 contains a schema named Schema! and a table named Table1.
You need to ensure that access to the data in Table1 is controlled by using attribute based access control (ABAC).
What should you apply to Table1, and how should you control access for users? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.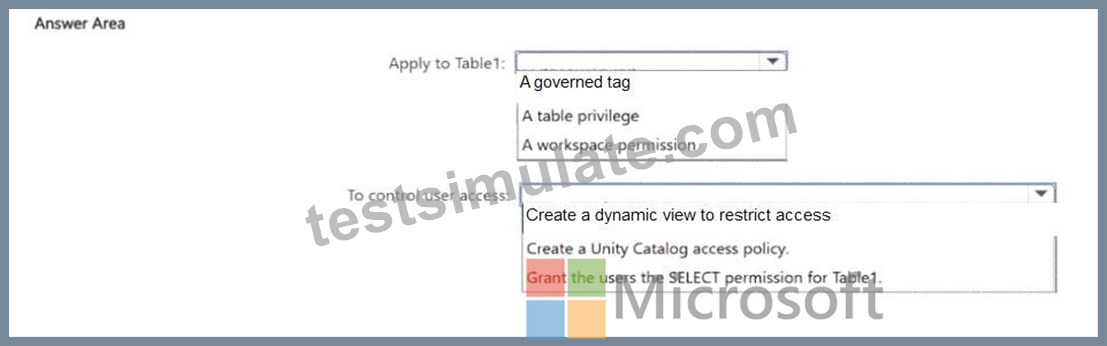
Answer:
Explanation: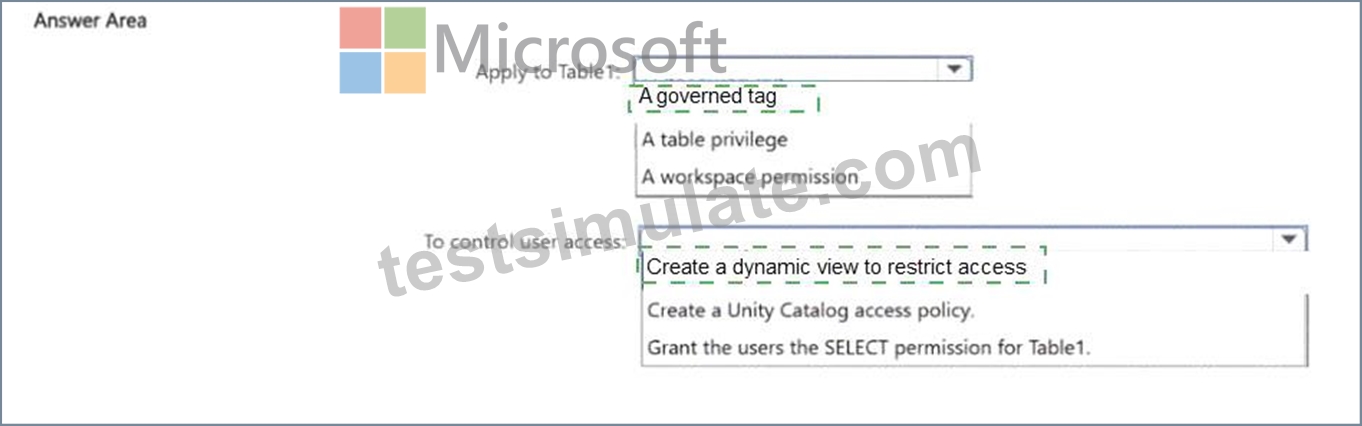
Explanation:
Attribute-based access control (ABAC) in Unity Catalog is implemented through row filters. A row filter is a SQL function registered on a table that evaluates the identity or group membership of the querying user and returns only the rows they're entitled to see.
The key functions are CURRENT_USER() (returns the logged-in user's email) and IS_ACCOUNT_GROUP_MEMBER() (returns true if the user belongs to a specified group). By building filter logic around these, you create access rules that are data-driven - a user in the 'EMEA' group sees EMEA rows, a user in 'APAC' sees APAC rows - without maintaining separate table-level grants per data segment.
This is what distinguishes ABAC from role-based access control: decisions are based on the user's attributes evaluated at query time, not on static grant lists. The filter is transparent to end users - they query the table normally and only receive rows the policy allows.
Reference: https://learn.microsoft.com/en-us/azure/databricks/data-governance/unity-catalog/row-and-column- filters
NEW QUESTION # 70
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to ensure that data lineage is captured and can be reviewed for tables accessed by Databricks notebooks and jobs. The solution must minimize administrative effort.
Which compute configuration should you use to capture the data lineage and what should you use to review the data lineage? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.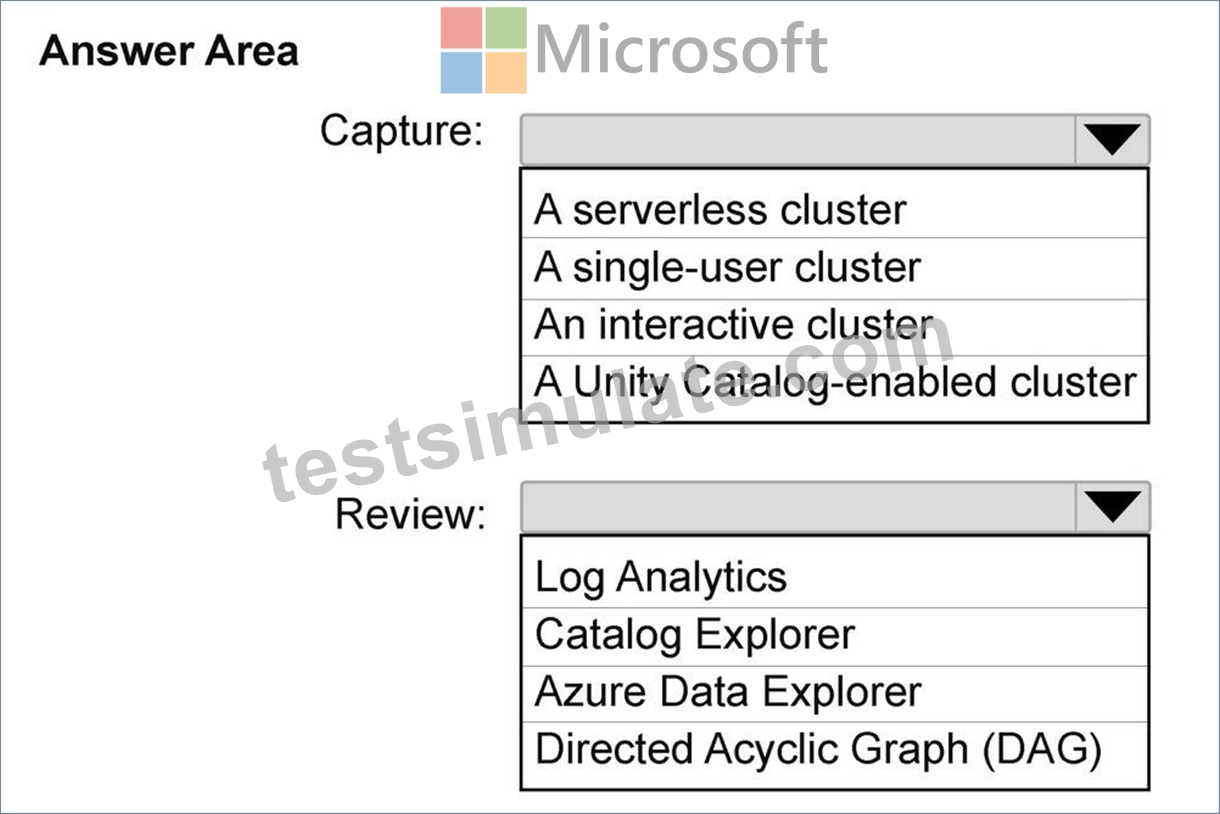
Answer:
Explanation: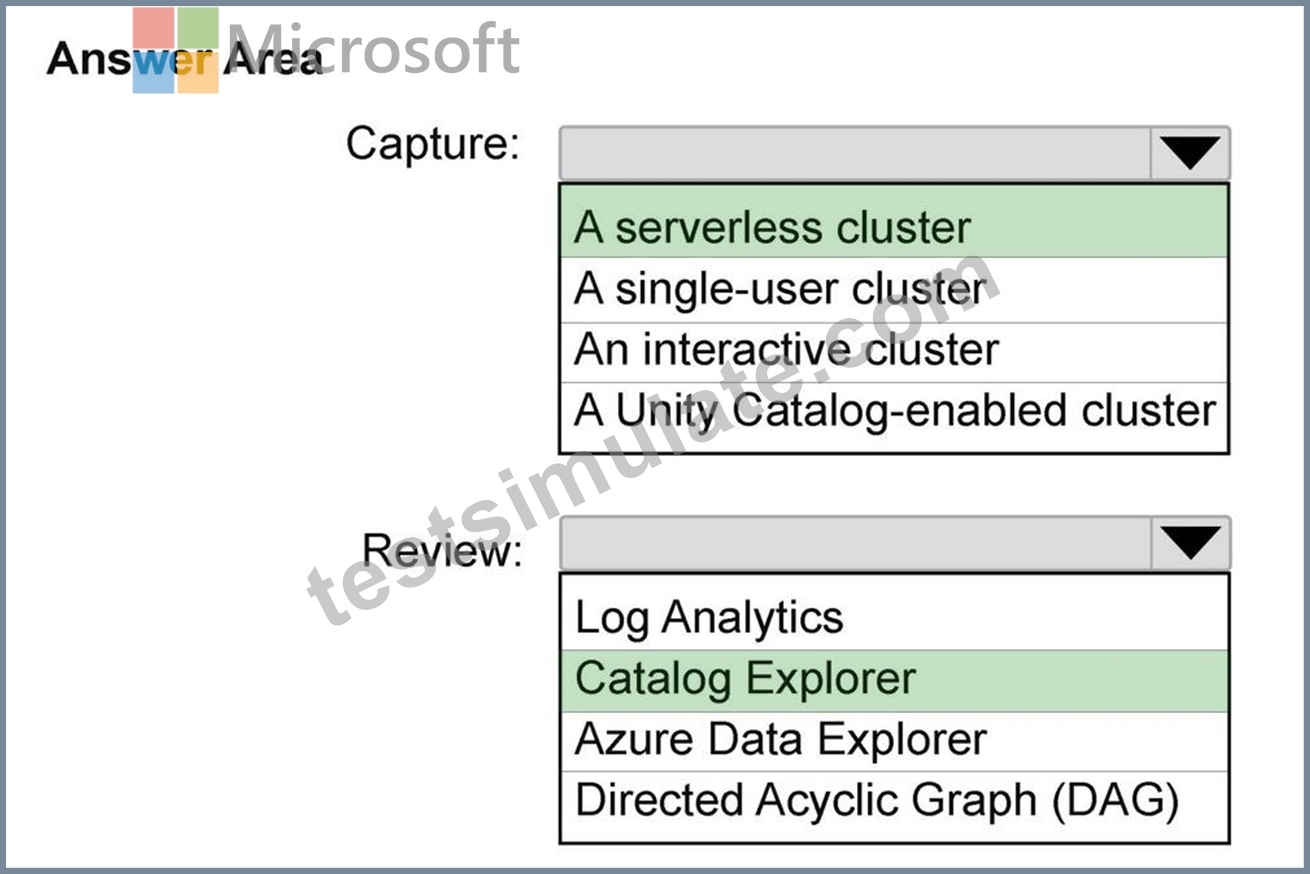
NEW QUESTION # 71
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains two managed Delta tables named sales.schema1.table1 and sales.schema1.table2.
sales.schema1.table1 contains sales data from the current year.
sales.schema1.table2 contains historical data.
You need to load all the rows from sales.schema1.table1 into sales.schema1.table2. The solution must preserve any existing data in sales.schema1.table2 and minimize processing effort.
Which command should you run?
Answer: C
Explanation:
The correct answer is A - INSERT INTO.
INSERT INTO appends all rows from the source to the target. Existing rows in table2 are untouched - the historical data stays intact - and the current year's rows from table1 are added. That is exactly what the requirement asks: 'preserve any existing data and minimise processing effort.' Option B (CREATE TABLE AS SELECT) would fail if table2 already exists, or if used with CREATE OR REPLACE it wipes table2 entirely before writing - historical data gone. Option C (INSERT OVERWRITE) replaces the entire table content with only the table1 rows, also destroying table2's existing data. Option D (CREATE OR REPLACE TABLE AS SELECT) explicitly drops and recreates the table, eliminating all historical records.
INSERT INTO is deliberately the simplest possible command here - one line, no special options, no risk of accidental data loss.
Reference: https://learn.microsoft.com/en-us/azure/databricks/sql/language-manual/delta-insert-into
NEW QUESTION # 72
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1. Job1 contains multiple tasks.
Failures of non-critical tasks must be logged but must NOT trigger notifications. Notifications must be triggered only when critical tasks have failed, and Job1 has completed You need to configure the job alerting behavior.
What should trigger a notification?
Answer: C
NEW QUESTION # 73
Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders.
You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df.fillna(0, subset=['order_amount'])
Does this meet the goal?
Answer: A
Explanation:
Correct:
* You run the following expression.
df.dropna(subset=["order_amount"])
The expression df.dropna(subset=["order_amount"]) is an appropriate and effective way to exclude rows where order_amount is null.
* You run the following expression.
df.filter(df.order_amount.isNotNull())
To exclude rows where the order amount is null, you can use the isNotNull() method or a SQL expression within the filter() or where() functions.Here are the standard, appropriate expressions:
Option 1: Python/PySpark API (Recommended)
pythondf_clean = df.filter(df["order_amount"].isNotNull())
Incorrect:
* You run the following expression.
df.fillna(0, subset=['order_amount'])
* You run the following expression.
df.filter(df.order_amount != None)
Reference:
https://www.geeksforgeeks.org/python/filter-pyspark-dataframe-columns-with-none-or-null-values/
https://learn.microsoft.com/en-us/azure/databricks/pyspark/reference/classes/dataframe/dropna
NEW QUESTION # 74
......
TestSimulate's Microsoft DP-750 exam training material is the best training materials on the Internet. It is the leader in all training materials. It not only can help you to pass the exam, you can also improve your knowledge and skills. Help you in your career in your advantage successfully. As long as you have the Microsoft DP-750 Certification, you will be treated equally by all countries.
DP-750 Latest Practice Materials: https://www.testsimulate.com/DP-750-study-materials.html